KernelGAN: kernel estimation with an internal GAN (NeurIPS 2019)
Optional · paper guide 3 of 11 for DLCV 09A.1 · Blind and Real-World Image Super-Resolution. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- SRMD: one network for many known degradations (CVPR 2018)
- IKC: iterative kernel correction (CVPR 2019)
- KernelGAN: kernel estimation with an internal GAN (NeurIPS 2019)
- DAN: unfolding the alternating optimization (NeurIPS 2020)
- DASR: contrastive degradation representations (CVPR 2021)
- BSRGAN: a practical degradation model (ICCV 2021)
- Real-ESRGAN: high-order degradation with pure synthetic data (ICCVW 2021)
- StableSR: a time-aware encoder for a frozen diffusion prior (IJCV 2024)
- DiffBIR: remove the degradation, then regenerate (ECCV 2024)
- SeeSR: degradation-aware semantic prompts (CVPR 2024)
- SUPIR: scaling up the prior, the data and the text (CVPR 2024)
Deep Learning for Computer Vision
Challenge
Non-blind SR methods that accept a kernel (ZSSR, SRMD) are only useful if the kernel of the specific image is known; it depends on the optics and even on camera shake, so it changes from image to image. Earlier estimation by nearest-neighbor patch search across scales (Michaeli and Irani [11]) failed above and took about 45 minutes per image. Bell-Kligler, Shocher and Irani want an unsupervised, image-specific kernel estimator that needs no training data except the test image [12].
Method
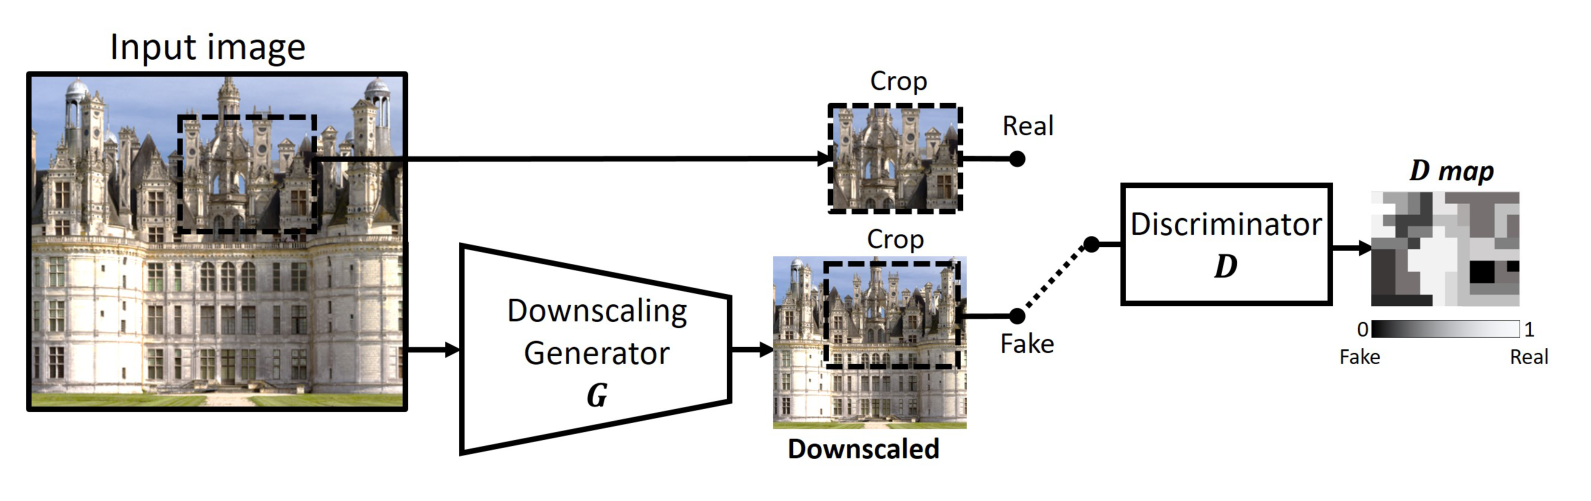
Figure source: [12], Published paper PDF, PDF page 4. Original PDF.
Principle. The correct SR kernel is the downscaling kernel that best preserves the distribution of small patches across scales of the LR image. So generate a downscaled version of the LR image such that its patches are indistinguishable from the patches of the LR image itself: this is distribution matching, a GAN’s job.
Objective. Let and be crops from the input LR image, its learned downscaler, and a patch discriminator. The released code alternates minimization of
The absolute values are averaged over the discriminator’s spatial map, and regularizes the effective kernel . Real crops target label 1, generated crops target 0 when training , and the generator targets 1 when training . Gradients through generated crops are stopped during the discriminator update. The paper’s printed minimax shorthand is not a literal implementation of these alternating losses; the released GANLoss uses mean L1 [73], in the spirit of label-regression adversarial training [74]. Training runs 3,000 alternating updates with Adam [64], learning rate and the published decay schedule, using image crops sampled to favor gradient-rich regions.
Discriminator. Fully convolutional, without pooling or strides: one convolution followed by six convolutions with spectral normalization [36], batch normalization, ReLU and a final sigmoid. Its receptive field is a patch, so it judges each patch separately and outputs a “D-map” of the input’s size; labels are all-ones maps for crops of and all-zeros for crops of ‘s output, with a pixel-wise loss.
Deep linear generator. Downscaling by convolution and subsampling is linear, so has no non-linearities (a non-linear could fool by, for example, tiling valid patches without any downscaling relation). A single strided convolution is expressive enough for the assumed linear downsampler, but the paper observes worse optimization. A deep linear network admits many factorizations of the same effective kernel; the authors propose this overparameterization as an explanation for its better behavior. This is an optimization argument, not a guarantee that the estimated kernel is unique or correct. has five hidden convolution layers with 64 channels; the first three filters are , and and the rest , giving a receptive field and so a kernel. For the first iterations ‘s output is constrained to be close to a bicubic downscaling, as a starting point.
Extracting the kernel. Convolving all filters of in sequence with stride 1 gives the kernel . This extraction is differentiable, so priors on can be imposed during training:
where keeps the kernel normalized, penalizes mass far from the center with a mask that grows exponentially with distance, discourages over-smooth kernels, and penalizes displacement from the chosen center . These are the paper’s stated regularizers. The released implementation uses a scale-aware center, an MSE center penalty and a sparsity exponent of 0.2 rather than the paper’s 0.5, with scheduled coefficients [73]; reproducing its run requires that implementation, not just this symbolic summary.
From to . KernelGAN only learns ; downscaling twice by 2 equals downscaling once by 4 with , where for even and 0 otherwise. This also avoids training on a tiny -downscaled image.
DIV2KRK benchmark. Because the NTIRE 2018 blind data have sub-pixel misalignments that favor blurry outputs, the paper builds DIV2KRK: each of the 100 DIV2K validation images is blurred with its own anisotropic Gaussian (axis lengths , angle ), perturbed by up to 25% uniform multiplicative noise and renormalized, then subsampled.
Results
On DIV2KRK (PSNR / SSIM), KernelGAN + ZSSR reaches 30.363 / 0.8669 at and 26.810 / 0.7316 at . Bicubic-trained networks barely beat interpolation (RCAN+ 29.198 / 0.8223 and 25.659 / 0.6936, interpolation 28.731 / 0.8040 and 25.330 / 0.6795), and the best NTIRE 2018 blind entry reached 26.340 / 0.7190 at . Replacing the KernelGAN kernel by Michaeli and Irani’s kernel costs about 1 dB and 0.73 dB with ZSSR (29.368 and 26.080 dB), and about 4 dB and 2.4 dB with SRMD. With the ground-truth kernel the upper bounds are 32.436 dB () and 27.527 dB () for ZSSR, so a gap remains. KernelGAN + SRMD at (25.711 dB) ranks below the best NTIRE entry in PSNR but above it in SSIM (0.7265). Runtime is 61 s per image on a Tesla V100 (102 s on a K80), independent of image size because a fixed number of crops is used.
Ablations
- Depth of the linear generator. A single-layer generator instead of the deep linear one is worse by 3.8 dB at and 1.6 dB at on DIV2KRK, and its kernels look wrong. Depth matters even without non-linearity.
- Kernel source (Table 1 as a controlled study): with SR method fixed, bicubic kernel < Michaeli–Irani < KernelGAN < ground truth, showing that SR quality tracks kernel accuracy.
- An ablation of the four kernel constraints is reported only on the project website, not in the paper.
Conclusion
An image-specific GAN with a deep linear generator recovers the SR kernel from the test image alone, and plugging it into off-the-shelf non-blind SR gives the best blind results on DIV2KRK at the time.
Problems
- About a minute per image of test-time training, plus the non-blind SR step (DAN measured 415.7 s per image for KernelGAN + ZSSR); feed-forward estimators are much faster (DAN).
- Noise and compression are outside the model: the discriminator compares patches that contain noise and JPEG blocks, and the downscaler cannot represent them.
- Assumes patch recurrence and one spatially uniform kernel; images without repeating structure or with varying blur are hard cases.
- The estimator and the SR network are separate, and a good kernel can still be mismatched to the SR network’s expectations (DAN reports KernelGAN + USRNet at 20.06 dB on DIV2KRK ).
References
- N. Efrat, D. Glasner, A. Apartsin, B. Nadler and A. Levin, “Accurate Blur Models vs. Image Priors in Single Image Super-Resolution,” in Proc. IEEE ICCV, 2013, pp. 2832–2839. doi · CVF
- K. Zhang, W. Zuo and L. Zhang, “Learning a Single Convolutional Super-Resolution Network for Multiple Degradations,” CVPR, 2018. paper
- A. Liu, Y. Liu, J. Gu, Y. Qiao, C. Dong, “Blind Image Super-Resolution: A Survey and Beyond,” IEEE TPAMI (early access), 2022. source
- Honggang Chen, Xiaohai He, Linbo Qing, Yuanyuan Wu, Chao Ren, Ray E. Sheriff, Ce Zhu, “Real-world single image super-resolution: A brief review,” Information Fusion, 2022. source
- B. B. Moser, A. S. Shanbhag, F. Raue, S. Frolov, S. Palacio and A. Dengel, “Diffusion Models, Image Super-Resolution, and Everything: A Survey,” IEEE Transactions on Neural Networks and Learning Systems, vol. 36, no. 7, pp. 11793–11813, 2025. doi · arXiv
- Y. Xu, S. R. Tseng, Y. Tseng, H. Kuo, Y. Tsai, “Unified Dynamic Convolutional Network for Super-Resolution with Variational Degradations,” CVPR, 2020. source
- K. Zhang, L. Van Gool, R. Timofte, “Deep Unfolding Network for Image Super-Resolution,” CVPR, 2020. source
- J. Gu, H. Lu, W. Zuo and C. Dong, “Blind Super-Resolution With Iterative Kernel Correction,” CVPR, 2019. paper
- Z. Luo, Y. Huang, S. Li, L. Wang and T. Tan, “Unfolding the Alternating Optimization for Blind Super Resolution,” NeurIPS, 2020. paper
- Z. Luo, H. Huang, L. Yu, Y. Li, H. Fan and S. Liu, “Deep Constrained Least Squares for Blind Image Super-Resolution,” CVPR, 2022. paper
- T. Michaeli, M. Irani, “Nonparametric Blind Super-resolution,” Proceedings of the IEEE International Conference on Computer Vision, 2013. source
- S. Bell-Kligler, A. Shocher and M. Irani, “Blind Super-Resolution Kernel Estimation using an Internal-GAN,” NeurIPS, 2019. paper
- A. Shocher, N. Cohen and M. Irani, “‘Zero-Shot’ Super-Resolution Using Deep Internal Learning,” in Proc. IEEE/CVF CVPR, 2018, pp. 3118–3126. doi · arXiv
- L. Wang, Y. Wang, X. Dong, Q. Xu, J. Yang, W. An and Y. Guo, “Unsupervised Degradation Representation Learning for Blind Super-Resolution,” CVPR, 2021. paper
- B. Xia, Y. Zhang, Y. Wang, Y. Tian, W. Yang, R. Timofte and L. Van Gool, “Knowledge Distillation Based Degradation Estimation for Blind Super-Resolution,” ICLR, 2023. paper
- K. Zhang, J. Liang, L. Van Gool, R. Timofte, “Designing a Practical Degradation Model for Deep Blind Image Super-Resolution,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- X. Wang, L. Xie, C. Dong, Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution With Pure Synthetic Data,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- J. Liang, H. Zeng, L. Zhang, “Efficient and Degradation-Adaptive Network for Real-World Image Super-Resolution,” ECCV, 2022. source
- J. Cai, H. Zeng, H. Yong, Z. Cao, L. Zhang, “Toward Real-World Single Image Super-Resolution: A New Benchmark and a New Model,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source
- P. Wei, Z. Xie, H. Lu, Z. Zhan, Q. Ye, W. Zuo, L. Lin, “Component Divide-and-Conquer for Real-World Image Super-Resolution,” ECCV, 2020. source
- C. Chen, Z. Xiong, X. Tian, Z. Zha, F. Wu, “Camera Lens Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2019. source
- Y. Yuan, S. Liu, J. Zhang, Y. Zhang, C. Dong, L. Lin, “Unsupervised Image Super-Resolution using Cycle-in-Cycle Generative Adversarial Networks,” CVPR Workshops, 2018. source
- A. Bulat, J. Yang, G. Tzimiropoulos, “To learn image super-resolution, use a GAN to learn how to do image degradation first,” ECCV, 2018. source
- M. Fritsche, S. Gu, R. Timofte, “Frequency Separation for Real-World Super-Resolution,” ICCV Workshops, 2019. source
- X. Ji, Y. Cao, Y. Tai, C. Wang, J. Li, F. Huang, “Real-World Super-Resolution via Kernel Estimation and Noise Injection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2020. source
- J. Wang, Z. Yue, S. Zhou, K. C. K. Chan, C. C. Loy, “Exploiting Diffusion Prior for Real-World Image Super-Resolution,” IJCV, 2024. source
- X. Lin, J. He, Z. Chen, et al., “DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior,” ECCV, 2024. source
- T. Yang, R. Wu, P. Ren, X. Xie, L. Zhang, “Pixel-Aware Stable Diffusion for Realistic Image Super-resolution and Personalized Stylization,” ECCV, 2024. source
- R. Wu, T. Yang, L. Sun, Z. Zhang, S. Li, L. Zhang, “SeeSR: Towards Semantics-Aware Real-World Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source · supplementary experiments
- F. Yu, J. Gu, Z. Li, et al., “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” CVPR, 2024. source
- Z. Yue, J. Wang, C. C. Loy, “ResShift: Efficient Diffusion Model for Image Super-resolution by Residual Shifting,” NeurIPS, 2023. source
- X. Wang, K. Yu, C. Dong, C. C. Loy, “Recovering Realistic Texture in Image Super-Resolution by Deep Spatial Feature Transform,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 2018. source
- K. He, H. Fan, Y. Wu, S. Xie, R. Girshick, “Momentum Contrast for Unsupervised Visual Representation Learning,” CVPR, 2020. source
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018 (Lecture Notes in Computer Science, 2019), pp. 63–79. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” in Proc. MICCAI, 2015, pp. 234–241. doi · arXiv
- T. Miyato, T. Kataoka, M. Koyama, Y. Yoshida, “Spectral Normalization for Generative Adversarial Networks,” ICLR, 2018. source
- J. Liang, H. Zeng, L. Zhang, “Details or Artifacts: A Locally Discriminative Learning Approach to Realistic Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2022. source
- A. Ignatov, N. Kobyshev, R. Timofte, K. Vanhoey, L. Van Gool, “DSLR-Quality Photos on Mobile Devices with Deep Convolutional Networks,” ICCV, 2017. source
- A. Lugmayr, M. Danelljan, R. Timofte, “Unsupervised Learning for Real-World Super-Resolution,” arXiv preprint, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “NTIRE 2020 Challenge on Real-World Image Super-Resolution: Methods and Results,” CVPR Workshops, 2020. source
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. source
- L. Zhang, A. Rao, M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” ICCV, 2023. source
- Y. Ai, X. Zhou, H. Huang, X. Han, Z. Chen, Q. You, H. Yang, “DreamClear: High-Capacity Real-World Image Restoration with Privacy-Safe Dataset Curation,” NeurIPS, 2024. source
- Z. Duan, J. Zhang, X. Jin, et al., “DiT4SR: Taming Diffusion Transformer for Real-World Image Super-Resolution,” ICCV, 2025. source
- R. Wu, L. Sun, Z. Ma, L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” NeurIPS, 2024. source
- Y. Wang, W. Yang, X. Chen, et al., “SinSR: Diffusion-Based Image Super-Resolution in a Single Step,” CVPR, 2024. source
- E. Agustsson and R. Timofte, “NTIRE 2017 Challenge on Single Image Super-Resolution: Dataset and Study,” in Proc. IEEE CVPR Workshops, 2017, pp. 1122–1131. doi · CVF
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- K. Ding, K. Ma, S. Wang, E. P. Simoncelli, “Image Quality Assessment: Unifying Structure and Texture Similarity,” IEEE TPAMI, 2022. source
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a “Completely Blind” Image Quality Analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar, F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” ICCV, 2021. source
- S. Yang, T. Wu, S. Shi, S. Lao, Y. Gong, M. Cao, J. Wang, Y. Yang, “MANIQA: Multi-dimension Attention Network for No-Reference Image Quality Assessment,” CVPR Workshops, 2022. source
- J. Wang, K. C. K. Chan, C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” AAAI, 2023. source
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. source
- R. Timofte, S. Gu, J. Wu, L. Van Gool, “NTIRE 2018 Challenge on Single Image Super-Resolution: Methods and Results,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops, 2018. source
- J. Cai, S. Gu, R. Timofte, L. Zhang, “NTIRE 2019 Challenge on Real Image Super-Resolution: Methods and Results,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “AIM 2019 Challenge on Real-World Image Super-Resolution: Methods and Results,” ICCV Workshops, 2019. source
- P. Wei, H. Lu, R. Timofte, et al., “AIM 2020 Challenge on Real Image Super-Resolution: Methods and Results,” ECCV Workshops, 2020. source
- Z. Chen, K. Liu, J. Gong, J. Wang, L. Sun, Z. Wu, R. Timofte, Y. Zhang et al., “NTIRE 2025 Challenge on Image Super-Resolution (×4): Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2025, pp. 1525–1535. doi · arXiv
- Le Zhang, Ao Li, Qibin Hou, Ce Zhu, Yonina C. Eldar, “Deep-Learning-Empowered Super Resolution: A Comprehensive Survey and Future Prospects,” Proceedings of the IEEE, 2025. source
- W. Ren, R. Goyal, Z. Hu, T. T. Aumentado-Armstrong, I. Mohomed and A. Levinshtein, “Hallucination Score: Towards Mitigating Hallucinations in Generative Image Super-Resolution,” arXiv:2507.14367, 2025. arXiv
- Real-ESRGAN contributors, “Real-ESRGAN model and ×4-plus training configuration,” official source, accessed 2026-11-02. model · configuration
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- M. Bevilacqua, A. Roumy, C. Guillemot and M.-L. Alberi Morel, “Low-Complexity Single-Image Super-Resolution based on Nonnegative Neighbor Embedding,” in Proc. BMVC, 2012, pp. 135.1–135.10. doi
- R. Zeyde, M. Elad and M. Protter, “On Single Image Scale-Up Using Sparse-Representations,” in Curves and Surfaces, Lecture Notes in Computer Science, Springer, 2012, pp. 711–730. doi
- D. Martin, C. Fowlkes, D. Tal and J. Malik, “A Database of Human Segmented Natural Images and Its Application to Evaluating Segmentation Algorithms and Measuring Ecological Statistics,” in Proc. IEEE ICCV, 2001, vol. 2, pp. 416–423. doi
- J.-B. Huang, A. Singh and N. Ahuja, “Single Image Super-Resolution from Transformed Self-Exemplars,” in Proc. IEEE CVPR, 2015, pp. 5197–5206. doi · CVF
- J. Kim, J. K. Lee and K. M. Lee, “Accurate Image Super-Resolution Using Very Deep Convolutional Networks,” in Proc. IEEE CVPR, 2016, pp. 1646–1654. doi · arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017, pp. 105–114. doi · arXiv
- R. Timofte, E. Agustsson, L. Van Gool, M.-H. Yang, L. Zhang et al., “NTIRE 2017 Challenge on Single Image Super-Resolution: Methods and Results,” in Proc. IEEE CVPR Workshops, 2017, pp. 1110–1121. doi · CVF
- Y. Matsui, K. Ito, Y. Aramaki, A. Fujimoto, T. Ogawa, T. Yamasaki and K. Aizawa, “Sketch-Based Manga Retrieval Using Manga109 Dataset,” Multimedia Tools and Applications, vol. 76, no. 20, pp. 21811–21838, 2017. doi
- KernelGAN contributors, “Adversarial losses and kernel constraints,” official source, accessed 2026-11-02. loss definitions · alternating updates
- X. Mao, Q. Li, H. Xie, R. Y. K. Lau, Z. Wang, S. P. Smolley, “Least Squares Generative Adversarial Networks,” ICCV, 2017. source
- DASR contributors, “MoCo logits and contrastive cross-entropy implementation,” official DASR source, commit
51524af8021c94a502ee002e135867a1b75dc7d0, accessed 2026-11-02. encoder · loss - Y. Zhang, K. Li, K. Li, L. Wang, B. Zhong and Y. Fu, “Image Super-Resolution Using Very Deep Residual Channel Attention Networks,” in Proc. ECCV, 2018, pp. 294–310. doi · arXiv
- K. Simonyan and A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” in Proc. ICLR, 2015. arXiv
- Y. Zhang, X. Huang, J. Ma, et al., “Recognize Anything: A Strong Image Tagging Model,” CVPR Workshops, 2024. source
- E. J. Hu, Y. Shen, P. Wallis, Z. Allen-Zhu, Y. Li, S. Wang, L. Wang, W. Chen, “LoRA: Low-Rank Adaptation of Large Language Models,” ICLR, 2022. source
- D. Podell, Z. English, K. Lacey, A. Blattmann, T. Dockhorn, J. Müller, J. Penna, R. Rombach, “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. source
- H. Liu, C. Li, Q. Wu, Y. J. Lee, “Visual Instruction Tuning,” NeurIPS, 2023. source
- T. Karras, M. Aittala, T. Aila, S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. source