BSRGAN: a practical degradation model (ICCV 2021)
Optional · paper guide 6 of 11 for DLCV 09A.1 · Blind and Real-World Image Super-Resolution. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- SRMD: one network for many known degradations (CVPR 2018)
- IKC: iterative kernel correction (CVPR 2019)
- KernelGAN: kernel estimation with an internal GAN (NeurIPS 2019)
- DAN: unfolding the alternating optimization (NeurIPS 2020)
- DASR: contrastive degradation representations (CVPR 2021)
- BSRGAN: a practical degradation model (ICCV 2021)
- Real-ESRGAN: high-order degradation with pure synthetic data (ICCVW 2021)
- StableSR: a time-aware encoder for a frozen diffusion prior (IJCV 2024)
- DiffBIR: remove the degradation, then regenerate (ECCV 2024)
- SeeSR: degradation-aware semantic prompts (CVPR 2024)
- SUPIR: scaling up the prior, the data and the text (CVPR 2024)
Deep Learning for Computer Vision
Challenge
A super-resolution network learns the inverse of the training degradation, not a universal operation called “make sharp.” BSRGAN asks whether an ordinary restoration backbone becomes useful on real photographs when its training inputs cover more realistic damage [16]. This changes the research question: a higher score on bicubic downsampling is not enough if compression, sensor noise and resizing interact differently at deployment.
The contribution is principally a training-data generator. It does not estimate a physically unique history for a particular photograph, and it does not require captured LR–HR pairs. Clean images supply targets; randomized processing supplies aligned degraded observations. Keeping the network familiar makes the effect of changing this observation distribution easier to understand, although the complete training recipe also changes the image collection and losses.
Method
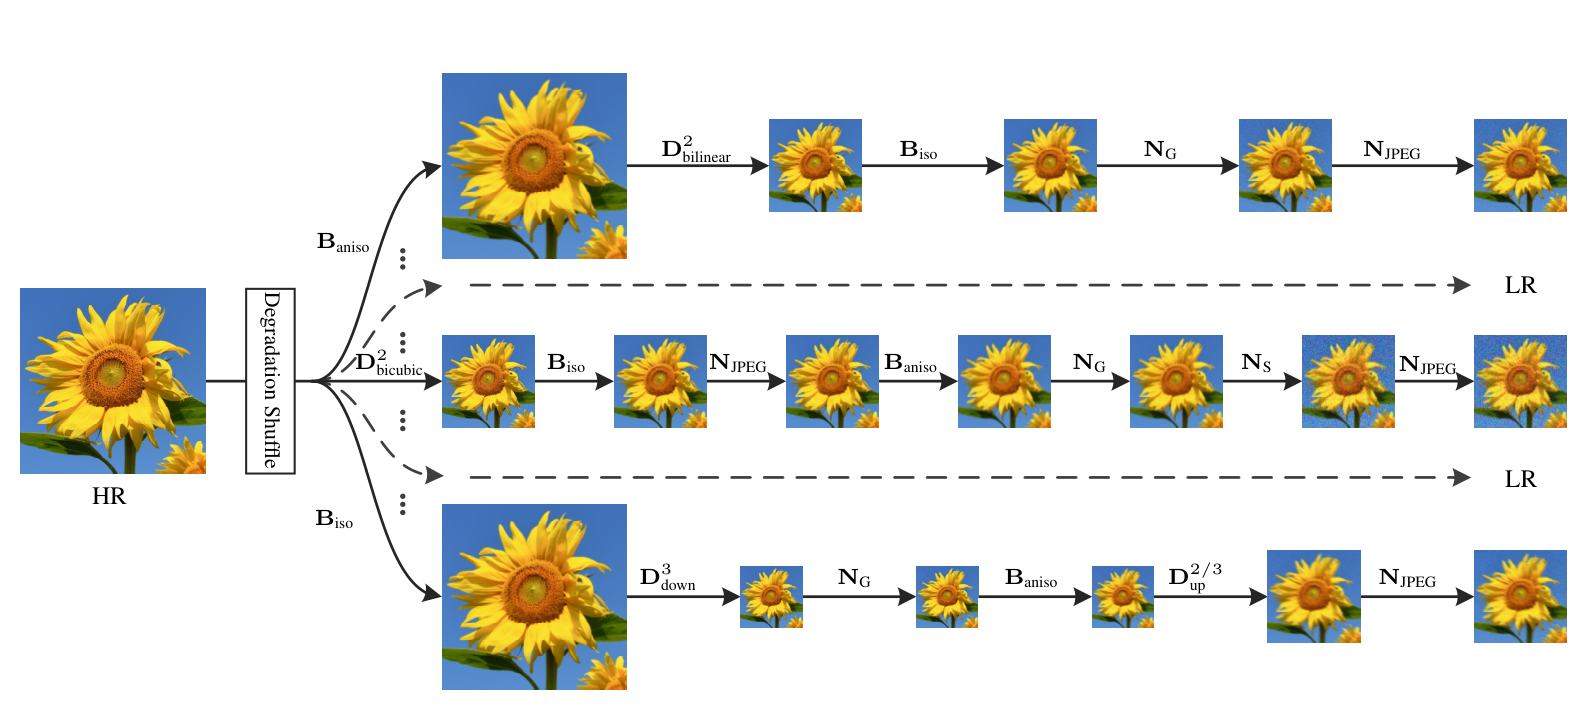
Figure source: [16], arXiv:2103.14006v2, PDF page 5. Original PDF.
Two blurs. The pipeline includes an isotropic Gaussian and an anisotropic Gaussian, rather than choosing just one. Kernel support is sampled from odd sizes 7 through 21. For ×4, isotropic widths range from 0.1 to 2.8; anisotropic axis widths range from 0.5 to 8, with a random orientation. These are widths in the coordinate system where that operation occurs. A blur applied after shrinking therefore has a different HR-equivalent footprint from the same blur applied before it.
Four downsampling choices. The scale reduction uses bilinear, bicubic, nearest-neighbor with a shifted Gaussian prefilter, or a down-up sequence. The prefilter compensates for the nearest-neighbor sampling-grid displacement. In the down-up option, an intermediate enlargement can introduce interpolation blur at LR resolution. Its two operations may be separated by other degradations. These choices model more than uncertainty about a single Gaussian width.
Three noise mechanisms. Gaussian noise can be independent across channels, shared as grayscale noise, or correlated across channels. JPEG creates block and quantization artifacts. Processed sensor noise is synthesized by approximately reversing a camera pipeline, injecting noise in RAW space, then applying forward processing. The camera-pipeline pool comes from five cameras; this branch is used with probability 0.25. Reverse processing is an approximation, not recovery of the original sensor measurement.
Random order. Write the operation list as . A random permutation produces
Here is the HR target, the LR input, the two blurs, the scale change, and Gaussian, JPEG and processed-camera noise operations. The final JPEG operation saves a compressed observation. Order matters because these operators do not commute: downsampling can suppress noise already present, whereas adding noise afterward leaves it visible at the final pixel scale.
Restoration and losses. An ESRGAN-style residual-in-residual dense-block generator [34] is first trained as BSRNet with L1 loss, then fine-tuned as BSRGAN with pixel, perceptual and adversarial objectives. The reported weights are 1, 1 and 0.1. The perceptual feature is taken before activation in the fourth convolution before the fourth pooling layer of VGG-19 [77]. The discriminator uses spectral normalization [36] and a least-squares adversarial objective [74]. These losses encourage different things: pixel alignment, feature similarity and locally plausible appearance. None verifies that a generated texture existed in the scene.
Results
The synthetic DIV2K4D benchmark has four degradation subsets made from 100 DIV2K validation images [47]. In Table 1, the following are Y-channel PSNR values in dB; LPIPS is unitless and lower is better:
| Degradation | BSRNet PSNR / LPIPS | BSRGAN PSNR / LPIPS |
|---|---|---|
| I: bicubic | 29.07 / 0.331 | 27.30 / 0.236 |
| II | 27.76 / 0.397 | 26.26 / 0.284 |
| III | 27.59 / 0.419 | 26.28 / 0.284 |
| IV: proposed pipeline | 25.67 / 0.506 | 24.58 / 0.361 |
The table exposes the expected distinction between pixel fidelity and perceptual reconstruction. It also exposes a limitation of the evaluation: subset IV uses the proposed data model. Generalization to that subset is useful evidence, but not independent proof of coverage of all real cameras.
On 20 real images, Table 2 gives BSRGAN a NIQE of 5.60, worse than the compared methods’ 3.99–4.95. The authors nevertheless prefer its images visually. This disagreement is part of the result; it should not be edited into an across-the-board numerical victory.
Ablations
The paper does not provide a component-by-component quantitative ablation that independently removes every blur, noise source and ordering choice under a fixed budget. Its comparisons establish the usefulness of the full system and show degradation mismatch, but do not identify an isolated causal gain for each operation. The BSRNet/BSRGAN rows above show the effect of the perception-oriented training stage; they do not isolate the shuffling strategy. Real-ESRGAN subsequently supplies controlled first-order/second-order and sinc-filter comparisons [17].
Conclusion
A practical synthetic observation distribution can matter as much as a new restoration backbone. BSRGAN makes operation order, camera processing and degradation diversity explicit parts of the training design.
Problems
The synthetic space can include unlikely processing histories while still omitting real ones. Unaligned compression grids, spatial variation and unfamiliar image-processing software remain difficult. GAN training can create bubble-like textures, and perceptual scores can disagree with inspection. There is also no unique inverse for severe damage: broad training improves robustness, not evidential certainty about the missing scene detail.
References
- N. Efrat, D. Glasner, A. Apartsin, B. Nadler and A. Levin, “Accurate Blur Models vs. Image Priors in Single Image Super-Resolution,” in Proc. IEEE ICCV, 2013, pp. 2832–2839. doi · CVF
- K. Zhang, W. Zuo and L. Zhang, “Learning a Single Convolutional Super-Resolution Network for Multiple Degradations,” CVPR, 2018. paper
- A. Liu, Y. Liu, J. Gu, Y. Qiao, C. Dong, “Blind Image Super-Resolution: A Survey and Beyond,” IEEE TPAMI (early access), 2022. source
- Honggang Chen, Xiaohai He, Linbo Qing, Yuanyuan Wu, Chao Ren, Ray E. Sheriff, Ce Zhu, “Real-world single image super-resolution: A brief review,” Information Fusion, 2022. source
- B. B. Moser, A. S. Shanbhag, F. Raue, S. Frolov, S. Palacio and A. Dengel, “Diffusion Models, Image Super-Resolution, and Everything: A Survey,” IEEE Transactions on Neural Networks and Learning Systems, vol. 36, no. 7, pp. 11793–11813, 2025. doi · arXiv
- Y. Xu, S. R. Tseng, Y. Tseng, H. Kuo, Y. Tsai, “Unified Dynamic Convolutional Network for Super-Resolution with Variational Degradations,” CVPR, 2020. source
- K. Zhang, L. Van Gool, R. Timofte, “Deep Unfolding Network for Image Super-Resolution,” CVPR, 2020. source
- J. Gu, H. Lu, W. Zuo and C. Dong, “Blind Super-Resolution With Iterative Kernel Correction,” CVPR, 2019. paper
- Z. Luo, Y. Huang, S. Li, L. Wang and T. Tan, “Unfolding the Alternating Optimization for Blind Super Resolution,” NeurIPS, 2020. paper
- Z. Luo, H. Huang, L. Yu, Y. Li, H. Fan and S. Liu, “Deep Constrained Least Squares for Blind Image Super-Resolution,” CVPR, 2022. paper
- T. Michaeli, M. Irani, “Nonparametric Blind Super-resolution,” Proceedings of the IEEE International Conference on Computer Vision, 2013. source
- S. Bell-Kligler, A. Shocher and M. Irani, “Blind Super-Resolution Kernel Estimation using an Internal-GAN,” NeurIPS, 2019. paper
- A. Shocher, N. Cohen and M. Irani, “‘Zero-Shot’ Super-Resolution Using Deep Internal Learning,” in Proc. IEEE/CVF CVPR, 2018, pp. 3118–3126. doi · arXiv
- L. Wang, Y. Wang, X. Dong, Q. Xu, J. Yang, W. An and Y. Guo, “Unsupervised Degradation Representation Learning for Blind Super-Resolution,” CVPR, 2021. paper
- B. Xia, Y. Zhang, Y. Wang, Y. Tian, W. Yang, R. Timofte and L. Van Gool, “Knowledge Distillation Based Degradation Estimation for Blind Super-Resolution,” ICLR, 2023. paper
- K. Zhang, J. Liang, L. Van Gool, R. Timofte, “Designing a Practical Degradation Model for Deep Blind Image Super-Resolution,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- X. Wang, L. Xie, C. Dong, Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution With Pure Synthetic Data,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- J. Liang, H. Zeng, L. Zhang, “Efficient and Degradation-Adaptive Network for Real-World Image Super-Resolution,” ECCV, 2022. source
- J. Cai, H. Zeng, H. Yong, Z. Cao, L. Zhang, “Toward Real-World Single Image Super-Resolution: A New Benchmark and a New Model,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source
- P. Wei, Z. Xie, H. Lu, Z. Zhan, Q. Ye, W. Zuo, L. Lin, “Component Divide-and-Conquer for Real-World Image Super-Resolution,” ECCV, 2020. source
- C. Chen, Z. Xiong, X. Tian, Z. Zha, F. Wu, “Camera Lens Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2019. source
- Y. Yuan, S. Liu, J. Zhang, Y. Zhang, C. Dong, L. Lin, “Unsupervised Image Super-Resolution using Cycle-in-Cycle Generative Adversarial Networks,” CVPR Workshops, 2018. source
- A. Bulat, J. Yang, G. Tzimiropoulos, “To learn image super-resolution, use a GAN to learn how to do image degradation first,” ECCV, 2018. source
- M. Fritsche, S. Gu, R. Timofte, “Frequency Separation for Real-World Super-Resolution,” ICCV Workshops, 2019. source
- X. Ji, Y. Cao, Y. Tai, C. Wang, J. Li, F. Huang, “Real-World Super-Resolution via Kernel Estimation and Noise Injection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2020. source
- J. Wang, Z. Yue, S. Zhou, K. C. K. Chan, C. C. Loy, “Exploiting Diffusion Prior for Real-World Image Super-Resolution,” IJCV, 2024. source
- X. Lin, J. He, Z. Chen, et al., “DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior,” ECCV, 2024. source
- T. Yang, R. Wu, P. Ren, X. Xie, L. Zhang, “Pixel-Aware Stable Diffusion for Realistic Image Super-resolution and Personalized Stylization,” ECCV, 2024. source
- R. Wu, T. Yang, L. Sun, Z. Zhang, S. Li, L. Zhang, “SeeSR: Towards Semantics-Aware Real-World Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source · supplementary experiments
- F. Yu, J. Gu, Z. Li, et al., “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” CVPR, 2024. source
- Z. Yue, J. Wang, C. C. Loy, “ResShift: Efficient Diffusion Model for Image Super-resolution by Residual Shifting,” NeurIPS, 2023. source
- X. Wang, K. Yu, C. Dong, C. C. Loy, “Recovering Realistic Texture in Image Super-Resolution by Deep Spatial Feature Transform,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 2018. source
- K. He, H. Fan, Y. Wu, S. Xie, R. Girshick, “Momentum Contrast for Unsupervised Visual Representation Learning,” CVPR, 2020. source
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018 (Lecture Notes in Computer Science, 2019), pp. 63–79. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” in Proc. MICCAI, 2015, pp. 234–241. doi · arXiv
- T. Miyato, T. Kataoka, M. Koyama, Y. Yoshida, “Spectral Normalization for Generative Adversarial Networks,” ICLR, 2018. source
- J. Liang, H. Zeng, L. Zhang, “Details or Artifacts: A Locally Discriminative Learning Approach to Realistic Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2022. source
- A. Ignatov, N. Kobyshev, R. Timofte, K. Vanhoey, L. Van Gool, “DSLR-Quality Photos on Mobile Devices with Deep Convolutional Networks,” ICCV, 2017. source
- A. Lugmayr, M. Danelljan, R. Timofte, “Unsupervised Learning for Real-World Super-Resolution,” arXiv preprint, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “NTIRE 2020 Challenge on Real-World Image Super-Resolution: Methods and Results,” CVPR Workshops, 2020. source
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. source
- L. Zhang, A. Rao, M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” ICCV, 2023. source
- Y. Ai, X. Zhou, H. Huang, X. Han, Z. Chen, Q. You, H. Yang, “DreamClear: High-Capacity Real-World Image Restoration with Privacy-Safe Dataset Curation,” NeurIPS, 2024. source
- Z. Duan, J. Zhang, X. Jin, et al., “DiT4SR: Taming Diffusion Transformer for Real-World Image Super-Resolution,” ICCV, 2025. source
- R. Wu, L. Sun, Z. Ma, L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” NeurIPS, 2024. source
- Y. Wang, W. Yang, X. Chen, et al., “SinSR: Diffusion-Based Image Super-Resolution in a Single Step,” CVPR, 2024. source
- E. Agustsson and R. Timofte, “NTIRE 2017 Challenge on Single Image Super-Resolution: Dataset and Study,” in Proc. IEEE CVPR Workshops, 2017, pp. 1122–1131. doi · CVF
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- K. Ding, K. Ma, S. Wang, E. P. Simoncelli, “Image Quality Assessment: Unifying Structure and Texture Similarity,” IEEE TPAMI, 2022. source
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a “Completely Blind” Image Quality Analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar, F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” ICCV, 2021. source
- S. Yang, T. Wu, S. Shi, S. Lao, Y. Gong, M. Cao, J. Wang, Y. Yang, “MANIQA: Multi-dimension Attention Network for No-Reference Image Quality Assessment,” CVPR Workshops, 2022. source
- J. Wang, K. C. K. Chan, C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” AAAI, 2023. source
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. source
- R. Timofte, S. Gu, J. Wu, L. Van Gool, “NTIRE 2018 Challenge on Single Image Super-Resolution: Methods and Results,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops, 2018. source
- J. Cai, S. Gu, R. Timofte, L. Zhang, “NTIRE 2019 Challenge on Real Image Super-Resolution: Methods and Results,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “AIM 2019 Challenge on Real-World Image Super-Resolution: Methods and Results,” ICCV Workshops, 2019. source
- P. Wei, H. Lu, R. Timofte, et al., “AIM 2020 Challenge on Real Image Super-Resolution: Methods and Results,” ECCV Workshops, 2020. source
- Z. Chen, K. Liu, J. Gong, J. Wang, L. Sun, Z. Wu, R. Timofte, Y. Zhang et al., “NTIRE 2025 Challenge on Image Super-Resolution (×4): Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2025, pp. 1525–1535. doi · arXiv
- Le Zhang, Ao Li, Qibin Hou, Ce Zhu, Yonina C. Eldar, “Deep-Learning-Empowered Super Resolution: A Comprehensive Survey and Future Prospects,” Proceedings of the IEEE, 2025. source
- W. Ren, R. Goyal, Z. Hu, T. T. Aumentado-Armstrong, I. Mohomed and A. Levinshtein, “Hallucination Score: Towards Mitigating Hallucinations in Generative Image Super-Resolution,” arXiv:2507.14367, 2025. arXiv
- Real-ESRGAN contributors, “Real-ESRGAN model and ×4-plus training configuration,” official source, accessed 2026-11-02. model · configuration
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- M. Bevilacqua, A. Roumy, C. Guillemot and M.-L. Alberi Morel, “Low-Complexity Single-Image Super-Resolution based on Nonnegative Neighbor Embedding,” in Proc. BMVC, 2012, pp. 135.1–135.10. doi
- R. Zeyde, M. Elad and M. Protter, “On Single Image Scale-Up Using Sparse-Representations,” in Curves and Surfaces, Lecture Notes in Computer Science, Springer, 2012, pp. 711–730. doi
- D. Martin, C. Fowlkes, D. Tal and J. Malik, “A Database of Human Segmented Natural Images and Its Application to Evaluating Segmentation Algorithms and Measuring Ecological Statistics,” in Proc. IEEE ICCV, 2001, vol. 2, pp. 416–423. doi
- J.-B. Huang, A. Singh and N. Ahuja, “Single Image Super-Resolution from Transformed Self-Exemplars,” in Proc. IEEE CVPR, 2015, pp. 5197–5206. doi · CVF
- J. Kim, J. K. Lee and K. M. Lee, “Accurate Image Super-Resolution Using Very Deep Convolutional Networks,” in Proc. IEEE CVPR, 2016, pp. 1646–1654. doi · arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017, pp. 105–114. doi · arXiv
- R. Timofte, E. Agustsson, L. Van Gool, M.-H. Yang, L. Zhang et al., “NTIRE 2017 Challenge on Single Image Super-Resolution: Methods and Results,” in Proc. IEEE CVPR Workshops, 2017, pp. 1110–1121. doi · CVF
- Y. Matsui, K. Ito, Y. Aramaki, A. Fujimoto, T. Ogawa, T. Yamasaki and K. Aizawa, “Sketch-Based Manga Retrieval Using Manga109 Dataset,” Multimedia Tools and Applications, vol. 76, no. 20, pp. 21811–21838, 2017. doi
- KernelGAN contributors, “Adversarial losses and kernel constraints,” official source, accessed 2026-11-02. loss definitions · alternating updates
- X. Mao, Q. Li, H. Xie, R. Y. K. Lau, Z. Wang, S. P. Smolley, “Least Squares Generative Adversarial Networks,” ICCV, 2017. source
- DASR contributors, “MoCo logits and contrastive cross-entropy implementation,” official DASR source, commit
51524af8021c94a502ee002e135867a1b75dc7d0, accessed 2026-11-02. encoder · loss - Y. Zhang, K. Li, K. Li, L. Wang, B. Zhong and Y. Fu, “Image Super-Resolution Using Very Deep Residual Channel Attention Networks,” in Proc. ECCV, 2018, pp. 294–310. doi · arXiv
- K. Simonyan and A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” in Proc. ICLR, 2015. arXiv
- Y. Zhang, X. Huang, J. Ma, et al., “Recognize Anything: A Strong Image Tagging Model,” CVPR Workshops, 2024. source
- E. J. Hu, Y. Shen, P. Wallis, Z. Allen-Zhu, Y. Li, S. Wang, L. Wang, W. Chen, “LoRA: Low-Rank Adaptation of Large Language Models,” ICLR, 2022. source
- D. Podell, Z. English, K. Lacey, A. Blattmann, T. Dockhorn, J. Müller, J. Penna, R. Rombach, “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. source
- H. Liu, C. Li, Q. Wu, Y. J. Lee, “Visual Instruction Tuning,” NeurIPS, 2023. source
- T. Karras, M. Aittala, T. Aila, S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. source