DLCV 09 · Deep Image Restoration: Low-Level Vision
Needs: DLCV 01 · Deep Learning for Image Processing and Computer Vision, IP 05 · Image Restoration and Reconstruction
Navigate: this page and this track: Navigate: this page and this track
On this page
- What you’ll learn1 min
- The big picture2 min
- What is low-level vision?2 min
- One problem, many faces: the degradation model4 min
- Before deep learning: the era of hand-crafted priors1 min
- The deep learning formulation3 min
- Super-resolution3 min
- Denoising3 min
- Dehazing2 min
- Desnowing1 min
- Deraining1 min
- Low-light enhancement (brief)1 min
- Image fusion (brief)1 min
- Deblurring5 min
- Inpainting (brief)1 min
- Matting (brief)1 min
- General backbones1 min
- All-in-one and universal restoration2 min
- Loss functions1 min
- Evaluation metrics14 min
- NTIRE challenges1 min
- Modern view3 min
- Key takeaways1 min
- Exercises5 min
- Supplementary notes
- Paper guides
- References
- Blind super-resolution: conditioning on and estimating the kernel
- Plug-and-play priors and half-quadratic splitting
- Super-resolution milestones, families and benchmarks
- Classical and learned blind-deblurring methods
- All-in-one methods in more detail
- Human-rated IQA datasets
- PIQE and the Perceptual Index
- How the learned NR assessors work
- CLIP-IQA and Q-Align scores
- Fitting the Bradley–Terry model
- Metric-by-metric summary table
- Restormer: global channel relationships without pixel-wise attention
- AirNet: infer the degradation before conditioning restoration
- TransWeather: learned weather queries for a shared restoration model
- PromptIR: input-conditioned feature prompts, without language instructions
- AdaIR: adaptively separate and exchange frequency information
- DA-CLIP: separate content guidance from degradation guidance
- InstructIR: route image features with a human instruction
- AutoDIR: diagnose degradation, guide diffusion, then correct structure
- AgenticIR: plan, inspect and revise a sequence of restoration tools
- 4KAgent: select restoration experts for a configured fidelity goal
- PromptFix: combine instructions, visual diagnosis and high-frequency preservation
- Deep Image Prior: the network as the prior
- Survey papers in detail
Deep Learning for Computer Vision
Explore this chapter 1 interactive experiment
A blurry observation fits two sharp clean signals. The blurry average has the lowest expected squared error; a sharp guess looks better but is usually farther from the truth.
What you’ll learn
- Describe restoration through an observation model and its unknowns.
- Build paired data and synthetic degradations, then assess the real-world gap.
- Compare task-specific backbones and models conditioned on degradation or instructions.
- Choose losses and distinguish fidelity, perceptual quality and measurement consistency.
- Evaluate results with appropriate datasets, protocols and uncertainty about missing detail.
The big picture
Low-level vision is about the pixels themselves. Before a system can recognize a face, read a sign or detect a car, the image has to be clear enough to look at. Restoration models are the part of the pipeline that takes a damaged photo (too small, noisy, blurred, foggy, rainy, dark) and returns a better estimate of the clean scene.
Why it matters: every phone camera runs denoising, demosaicking and super-resolution before you ever see a picture. Satellite, microscope, medical and surveillance images are restored before they are measured. Video streaming services upscale low-bitrate frames. Self-driving cars need their detectors to work in rain and fog. And from a research point of view, restoration is where many architectural ideas were tested first: residual learning, channel attention, efficient transformers and diffusion priors all have well-known restoration variants.
We assume you know CNNs and backpropagation (DLCV 01) and the classical restoration chapter (IP 05), which covers noise models, Wiener filtering and the degradation model in detail. We link to it rather than repeat it.
Related chapters. Three chapters go deeper into parts of this one: DLCV 09A (single-image super-resolution), DLCV 09A.3 (video super-resolution) and DLCV 09B (generative restoration with GAN and diffusion priors). DLCV 10 covers image fusion. DLCV 01B explains why restoration networks are built from blocks differently than classifiers.
What is low-level vision?
Plain version. High-level vision asks “what is in the picture?” (classification, detection). Low-level vision asks “what does the picture actually look like, pixel by pixel?” One is about understanding, the other about perceiving.
The analogy in the earlier post [1] comes from how people interact with the world: we first sense (light hits the retina and we see edges, colors and contrast) and then interpret (that is a cup). Both are necessary. If the sensing is poor (the cup is blurry), the interpretation suffers. Low-level vision tasks exist to make the sensing good again: when we say an object looks “blurry”, our perception of it is not sharp, and a deblurring task is created to make it “clear”.
Precise version. A low-level vision task maps an image to an image of (usually) the same content:
where the output is a pixel-wise estimate rather than a label. are the input height, width and channels, and those of the output ( for super-resolution by a factor , otherwise usually equal). This has three consequences that shape the whole field:
- Dense, high-resolution outputs. Every pixel matters, so architectures cannot downsample aggressively and must keep fine detail, which makes them expensive at high resolution.
- Supervision is cheap to synthesize. Take a clean image, damage it with a known process, and you have an input–target pair. This is a huge advantage over labeled data for recognition, and also the source of the field’s main weakness (synthetic damage is not real damage).
- “Correct” is ambiguous. Many clean images are consistent with one damaged image. Which one is “best” depends on whether you value fidelity to the truth or natural appearance, as we will see in the evaluation section.
The family of tasks is broad: deblurring, super-resolution, denoising, inpainting, color calibration, infrared–visible fusion and more. Papers with Code used to be the standard place to browse these task lists and leaderboards, but it has shut down and its address now redirects to Hugging Face’s trending-papers page, so its per-task leaderboards are no longer available. A reliable way to follow progress today is the yearly NTIRE challenge reports (New Trends in Image Restoration and Enhancement, a CVPR workshop), which we discuss near the end [2], [3].
One problem, many faces: the degradation model
Plain version. Every task in this tutorial can be written as “the camera saw a clean scene , something damaged it, and we got .” Only the damage changes. If you can write the damage down, you can name the task.
The unified view
where is the unknown clean image, is a (possibly nonlinear, possibly unknown) degradation operator, is noise, and is what we observe. Restoration means estimating from . Here are the specific forms used in the post [1] and in the rest of this tutorial. Figure 1 shows each one applied to the same photo.
Blur (the textbook model). As in IP 05,
where is the sharp image, the point spread function (blur kernel), 2-D convolution, additive noise and the observed image, all indexed by pixel coordinates . Denoising is the special case (a unit impulse, so no blur).
Super-resolution. The low-resolution image is a blurred, subsampled and noisy version of the high-resolution one:
where is a blur (anti-aliasing) kernel, keeps every -th pixel in each direction, and is the scale factor (2, 3, 4, …). The classic “bicubic” benchmark setting replaces all of this with MATLAB-style bicubic downsampling and no noise.
Compression. , where is the quality factor. JPEG quantizes DCT coefficients (see IP 08), producing blocking and ringing. It is not additive and not linear, so it is usually just added to the pipeline as a black box.
Haze (the atmospheric scattering model).
where is a pixel, the hazy image, the haze-free scene radiance, the global atmospheric light (the color of the haze), the transmission, the scattering coefficient and the scene depth. The first term is the attenuated scene; the second is “airlight” scattered toward the camera. Far objects (large ) get small and fade into .
Rain. For rain streaks the common model is additive,
where is the rain-free background and the rain layer. Raindrops stuck on a lens or windshield behave differently: they block and refract the background, so a popular model is , where is a binary raindrop mask, the element-wise product and the light passing through the drops [39].
Low light (Retinex). Retinex theory [5] separates an image into reflectance and illumination:
where is the observed image, the reflectance (the intrinsic color and texture of surfaces, what we want), the illumination and the element-wise product. A dark photo has small ; enhancement estimates and brightens it, while noise that was hidden in the dark gets amplified.
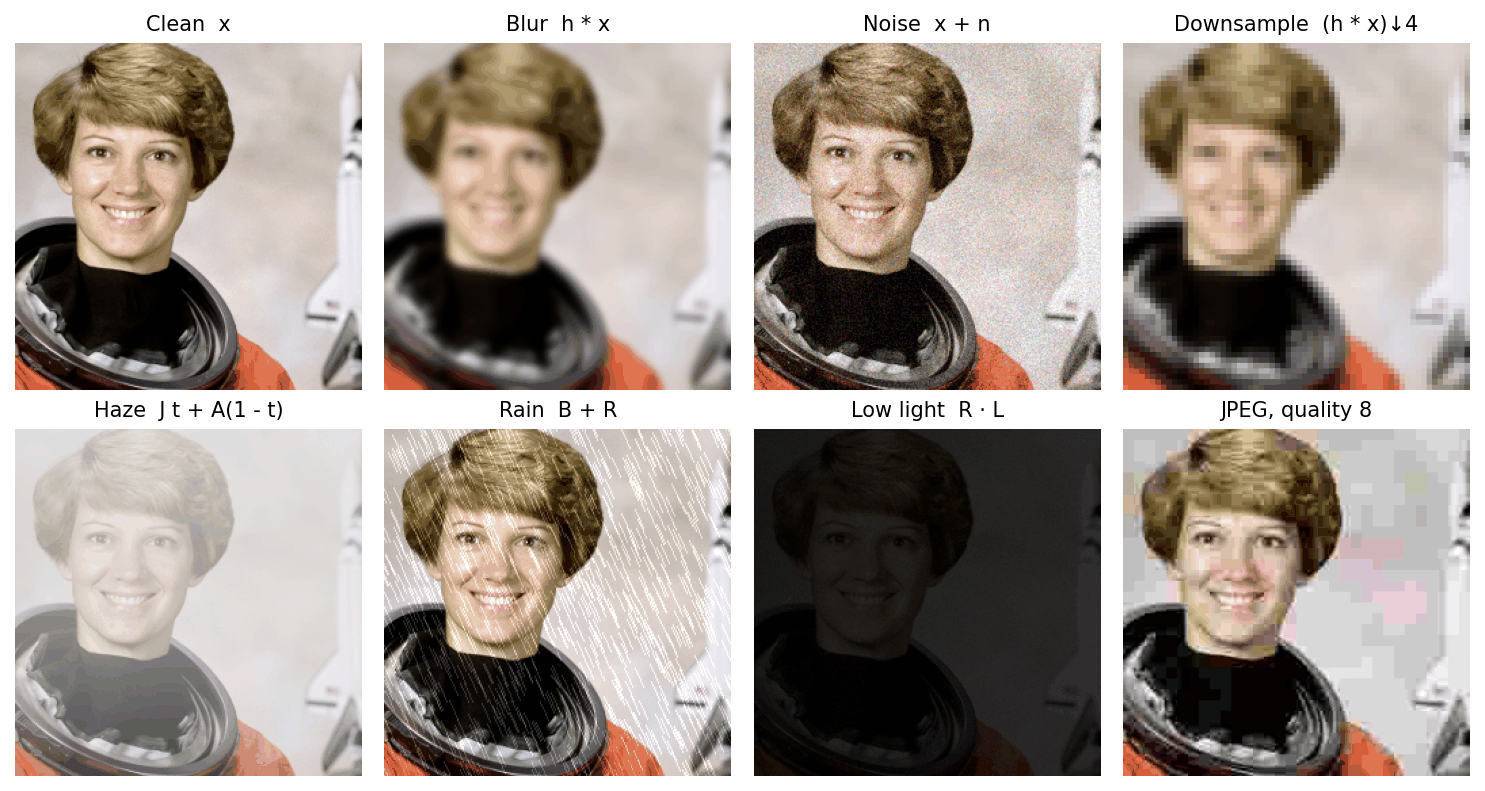
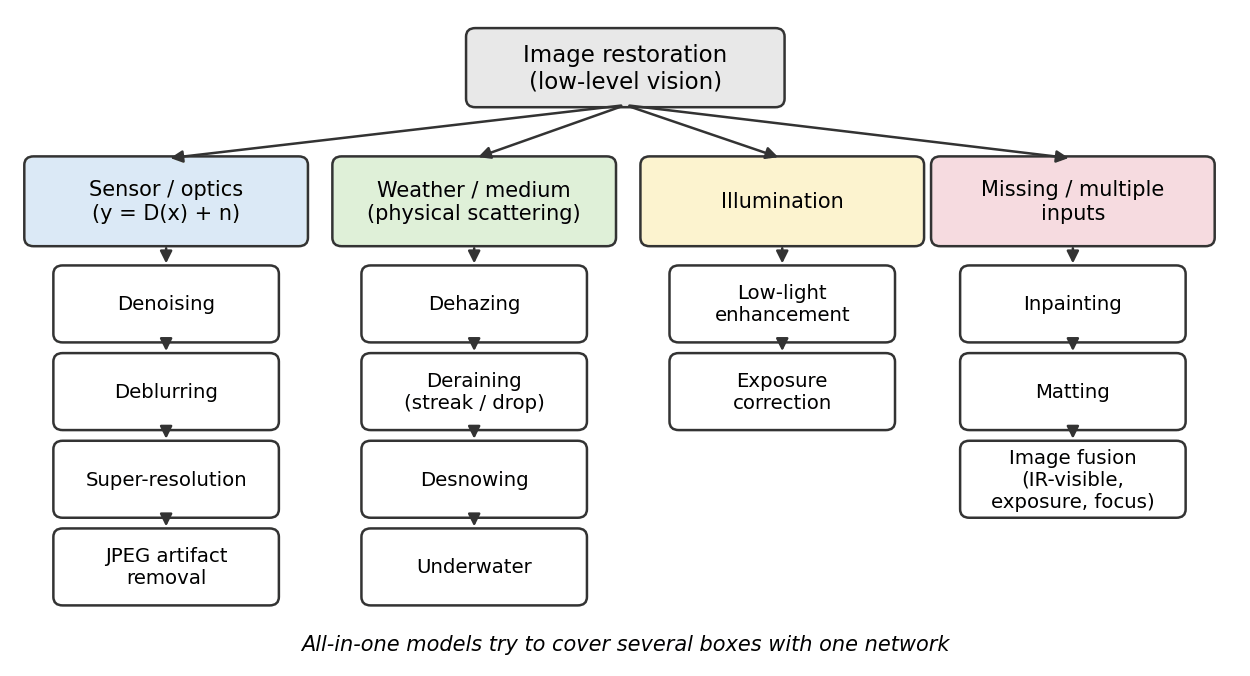
Although none of these models is exact, they all have the same shape: a clean image goes in, an operator plus noise comes out. That is the post’s central point [1]: seen through the degradation model, these are all the same kind of problem, and the same tools (and often the same networks) apply to all of them. Figure 2 organizes them by where the damage comes from.
Why the problem is hard: ill-posedness
For almost every above, many different produce the same . Downsampling by 4 throws away 15 of every 16 pixels; blur suppresses high frequencies to near zero; haze with erases distant objects. The inverse problem is ill-posed, and we need a prior on what clean images look like. In the Bayesian (MAP) form,
where the first term (data fidelity) says ” must explain the observation”, is a regularizer encoding the prior (small for natural-looking images), and balances the two. The whole history of the field is a history of better priors .
Before deep learning: the era of hand-crafted priors
Before deep learning, each task had its own carefully reasoned prior, and success depended on having enough physical or statistical knowledge of the problem. Denoising used local smoothness, non-local self-similarity and sparsity; deblurring used Wiener and constrained least-squares filters plus heavy-tailed gradient priors; dehazing used the dark channel prior [25]; super-resolution used interpolation and example-based dictionaries; low-light enhancement used histogram equalization and Retinex decompositions. IP 05 covers the core of this toolbox (noise models, mean/median/adaptive filters, inverse, Wiener and CLS filtering) and ends with a short history of the move to learned denoisers. The view in [1] is that once deep learning surpassed what these models could do, the decisive factor stopped being a strong theoretical prior for each task and became a strong learning mechanism and feature extractor. The degradation model did not disappear: it moved from the solver into the data generator.
The deep learning formulation
Plain version. Make lots of (damaged, clean) pairs, and train a network to map damaged to clean. Most of the hard work is in making the damage realistic.
Supervised training on pairs
Given a dataset of clean images and a degradation sampler, we build pairs with , and fit
where is the restoration network with parameters , the number of training pairs and a loss (L1, L2, perceptual, adversarial, …; see the losses section). Training is done on random crops (“patches”, e.g. to ) with flips and rotations, because convolutional and windowed-attention networks are translation-equivariant and full-resolution images do not fit in GPU memory.
A useful fact explains a lot of what follows: with the L2 loss, the optimal network outputs the posterior mean . When many sharp images are consistent with , their average is blurry. This is why MSE-trained super-resolution looks smooth, and why GANs and diffusion models were brought in.
Synthetic degradation pipelines
Pairs come from three sources. (1) Synthetic: degrade clean images with a known model (bicubic downsampling, Gaussian noise, Gaussian blur, JPEG). Cheap and unlimited, but limited by how realistic the model is. (2) Captured: photograph the same scene twice, e.g. a short and a long exposure, or a burst averaged into a clean reference (as in the SIDD real-noise dataset [22]), or averaging high-speed video frames to create real motion blur (GoPro [44]). Realistic but expensive and specific to one camera. (3) Unpaired / self-supervised: learn from degraded images alone, using GANs, cycle consistency or noise statistics. Most strong models today train on synthetic pairs from a rich degradation pipeline and evaluate on both synthetic and captured data.
A typical “classic” pipeline is blur → downsample → noise → JPEG, mirroring the order in which a camera and an image-sharing site would damage a photo:
Code · Python · 26 lines
import numpy as np, cv2, torch, torch.nn.functional as F
from skimage import data, img_as_float32

def gaussian_kernel(sigma, size=21):
    ax = torch.arange(size) - size // 2
    g = torch.exp(-ax**2 / (2 * sigma**2))
    k = torch.outer(g, g)
    return k / k.sum()

def degrade(x, scale=4, sigma_blur=1.6, sigma_noise=0.03, jpeg_q=40, rng=None):
    """x: float tensor (C,H,W) in [0,1]. Returns the low-quality image y = D(x) + n."""
    rng = rng or np.random.default_rng(0)
    C = x.shape[0]
    k = gaussian_kernel(sigma_blur).to(x)[None, None].repeat(C, 1, 1, 1)
    y = F.conv2d(F.pad(x[None], (10,) * 4, mode="reflect"), k, groups=C)   # 1) blur  h * x
    y = y[..., ::scale, ::scale]                                           # 2) downsample  (.)↓s
    y = y + sigma_noise * torch.from_numpy(rng.standard_normal(y.shape).astype(np.float32))  # 3) noise n
    y = y.clamp(0, 1)[0]
    img = (y.permute(1, 2, 0).numpy() * 255).round().astype(np.uint8)      # 4) JPEG round trip
    ok, buf = cv2.imencode(".jpg", img[..., ::-1], [cv2.IMWRITE_JPEG_QUALITY, jpeg_q])
    img = cv2.imdecode(buf, cv2.IMREAD_COLOR)[..., ::-1]
    return torch.from_numpy(img.copy()).permute(2, 0, 1).float() / 255

x = torch.from_numpy(img_as_float32(data.astronaut())).permute(2, 0, 1)    # (3, 512, 512)
y = degrade(x)
print(x.shape, "->", y.shape)        # torch.Size([3, 512, 512]) -> torch.Size([3, 128, 128])
In training, every parameter (kernel width and shape, noise level and type, JPEG quality, even the order) is sampled at random per image, so the network sees a distribution of degradations instead of a single one.
Real-world and blind degradations
A model trained on one fixed (say, bicubic ) breaks on real photos, whose degradation is unknown, spatially varying and a mix of several effects. This is the blind (or real-world) restoration problem. Two broad strategies exist:
- Make the synthetic distribution wide enough to cover reality. Real-ESRGAN [4] applies the classic pipeline twice in sequence (“high-order” degradation, with randomized blur kernels, resizing, noise and JPEG in each round) and adds sinc filters to simulate ringing and overshoot. Trained on purely synthetic data, it generalizes much better to real low-quality images than bicubic-trained models.
- Bring in a strong generative prior. Pretrained text-to-image diffusion models already know what natural images look like. DiffBIR [16], SUPIR [17] and OSEDiff [18] condition such a model on the degraded input, so that the prior “fills in” plausible detail. This is the main recent trend in real-world SR and is discussed below.
A third, complementary strategy is to estimate the degradation (noise level, kernel, degradation type) and feed it to the network, as FFDNet’s noise-level map [21] and the all-in-one models do. In blind super-resolution the main unknown is the blur kernel in , and a whole family of methods gives the kernel to the network, estimates and corrects it in a loop, or estimates it from the test image alone [87]–[91]. The result to remember: explicit kernel methods are accurate and interpretable when the degradation really is “blur, downsample, noise”, but a wrong kernel propagates into the output. That is why most real-world models, such as BSRGAN [92], Real-ESRGAN [4] and the diffusion-prior methods, learn the degradation implicitly from a randomized pipeline instead.
Optional: Blind super-resolution: conditioning on and estimating the kernel (in the Supplementary notes). How SRMD, USRNet, IKC, DAN and KernelGAN handle the kernel, and when the explicit route beats the implicit one.
Optional: Plug-and-play priors and half-quadratic splitting (in the Supplementary notes). How a solver can split the data term from the prior so that any denoiser acts as the prior, the idea behind deep unfolding networks such as USRNet.
Super-resolution
Plain version. Make a small image bigger and sharper, i.e. predict the missing high-resolution pixels rather than just stretching the existing ones.
This section is an overview; DLCV 09A · Non-Blind Image Super-Resolution treats known-degradation SR in depth: ambiguity, classical baselines, network design decisions, perceptual and diffusion SR, and evaluation. Blind and real-world SR has its own chapter.
Problem setup
Single-image super-resolution (SISR) estimates from under . The traditional answer is interpolation: nearest-neighbor, bilinear and bicubic. Bicubic, which fits a cubic polynomial through a neighborhood, is the best known and is still used everywhere, both as a baseline and as the standard way to create benchmark low-resolution inputs. Interpolation only redistributes existing information; it cannot recreate the high frequencies that removed.
How a network gets bigger: three upsampling strategies
Because the output is larger than the input, every SR network must decide where the resolution increases.
a. Pre-upsampling (interpolate first). SRCNN [6] bicubically enlarges the input to the target size, then applies three convolution layers (patch extraction, non-linear mapping, reconstruction). Simple and intuitive, but every layer runs at high resolution, which is slow, and the network must clean up interpolation artifacts.
b. Transposed convolution (deconvolution). FSRCNN [7] works at low resolution and enlarges only at the end with a learned transposed convolution, giving a large speed-up over SRCNN. Transposed convolutions with a stride that does not divide the kernel size overlap unevenly and tend to produce checkerboard artifacts [9], so they are now rare as the final SR upsampler, although they remain common elsewhere in neural networks (for example in decoders of segmentation and generative models).
c. Sub-pixel convolution (pixel shuffle). ESPCN [8] computes channels at low resolution and rearranges them into an image times larger:
where is the low-resolution feature tensor with channels, a low-resolution position, the sub-pixel offset and the output channel. All learning happens at low resolution, and the rearrangement itself has no parameters. It is the dominant choice in modern SR networks (torch.nn.PixelShuffle).
Milestones and current families
Plain version. SR networks first got deeper, then learned to draw realistic texture, and most recently borrowed transformers and large pretrained generative models.
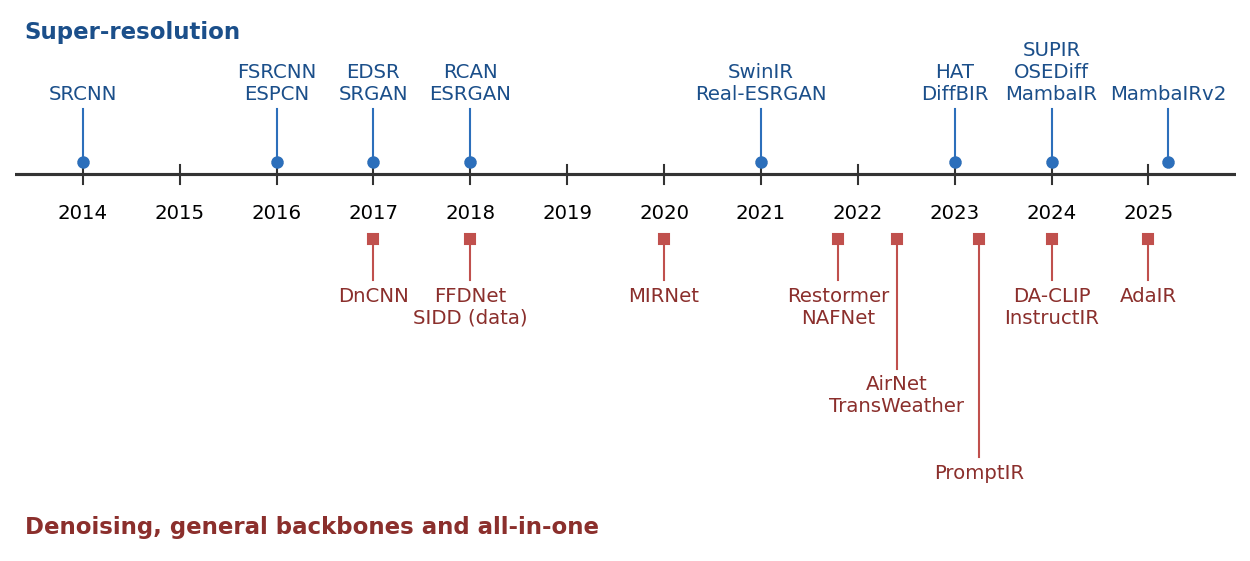
The main steps: SRCNN [6] was the first end-to-end CNN for SR; EDSR [10] and RCAN [11] made SR networks very deep (EDSR without batch normalization, RCAN with channel attention); SRGAN [12] and ESRGAN [13] added adversarial and perceptual losses, giving sharp, realistic texture instead of the blurry MSE average. Today’s families are transformers such as SwinIR [14] and HAT [15], state-space models such as MambaIR [49], and diffusion priors (DiffBIR [16], SUPIR [17] and the one-step OSEDiff [18]), which produce far more convincing textures on real photos but can also invent detail that was not in the scene. Models are usually trained on DIV2K [19] and compared by PSNR and SSIM on the luminance channel; real-world SR, which has no ground truth, relies on perceptual and no-reference metrics (see Evaluation). Once outputs looked much better than interpolation (around 2018), how to judge SR became a central question (see the perception–distortion section).
Optional: Super-resolution milestones, families and benchmarks (in the Supplementary notes). What each milestone changed, how the diffusion-prior methods differ, and the benchmark conventions.
Denoising
Plain version. Remove the random grain from a photo without wiping out the real texture. Noise is the simplest degradation, so denoising became the testbed where most deep restoration ideas appeared first.
Problem setup
. In the synthetic setting (additive white Gaussian noise, AWGN, with standard deviation , usually quoted on a 0–255 scale such as ). Real camera noise is different: it is signal-dependent (photon shot noise grows with brightness), spatially correlated after demosaicking, and reshaped by the camera’s processing pipeline. The Poisson–Gaussian model of such noise, written out for dark images, is in DLCV 09C.
Milestones
DnCNN [20] made two choices that became standard. It uses residual learning: instead of predicting , the network predicts the noise, and the output is
where . The residual (noise) is a “simpler” function to learn than the clean image, which made deep plain CNNs with batch normalization train well. A single DnCNN can also be trained for a range of noise levels (blind Gaussian denoising), and the same network handles SR and JPEG deblocking.
FFDNet [21] feeds a noise-level map (same size as the image, value at each pixel) to the network along with a downsampled version of the input. Changing at test time trades noise removal against detail preservation, and a non-uniform handles spatially varying noise. It is fast enough to run on a CPU.
Real noise. The SIDD dataset [22] provides real smartphone noisy images with clean references obtained by careful capture and processing of image bursts. Models trained only on AWGN do poorly on it, which pushed the field toward realistic noise synthesis and captured training data.
General backbones. MIRNet [30], Restormer [23] and NAFNet [24] are general restoration architectures that reported state-of-the-art results on SIDD as well as on deblurring and other tasks. They are covered in the backbones section.
Code: a tiny residual denoiser
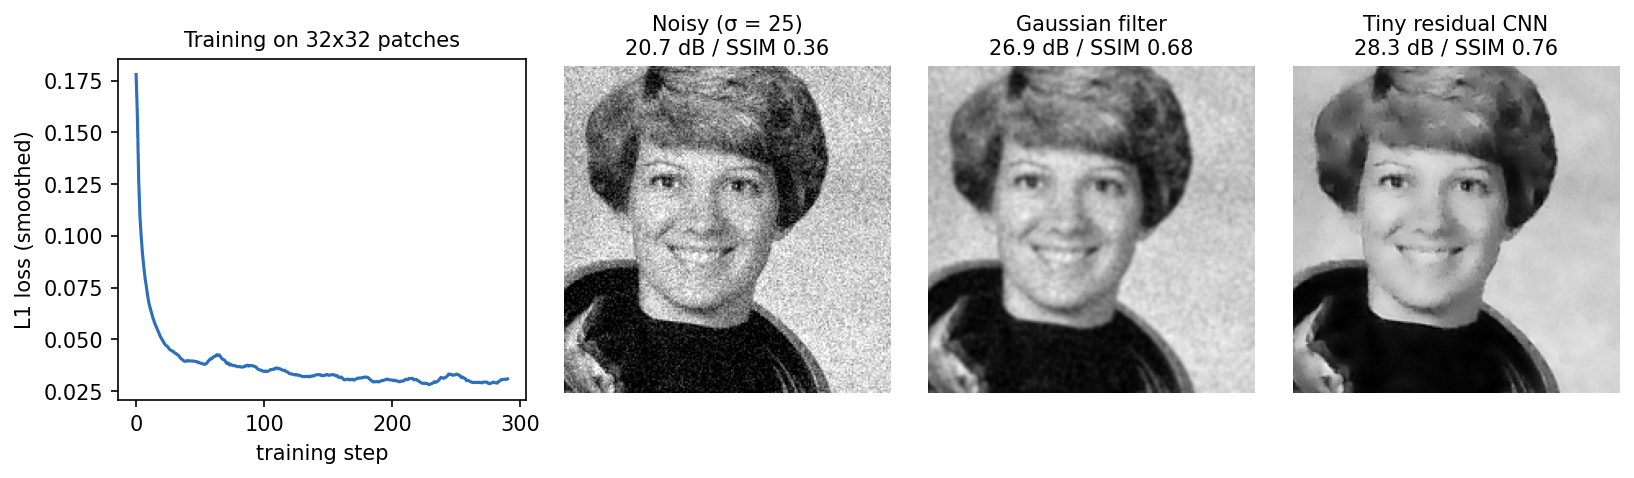
The snippet trains a five-layer DnCNN-style network on random patches cut from four skimage images, with fresh Gaussian noise every step, then tests on an image it has never seen. On a laptop CPU it takes well under a minute (we measured about one minute on a heavily loaded machine).
Code · Python · 48 lines
import time, numpy as np, torch, torch.nn as nn
from skimage import data, img_as_float32
from skimage.color import rgb2gray

torch.manual_seed(0); torch.set_num_threads(2)
rng = np.random.default_rng(0)
sigma = 25 / 255                                    # noise level (on a [0,1] scale)
train_imgs = [img_as_float32(im) for im in (data.camera(), data.coins(), data.moon(), data.page())]
test_img = img_as_float32(rgb2gray(data.astronaut()))   # held out

def random_patches(n=32, p=32):
    batch = []
    for _ in range(n):
        im = train_imgs[rng.integers(len(train_imgs))]
        i, j = rng.integers(0, im.shape[0] - p), rng.integers(0, im.shape[1] - p)
        batch.append(im[i:i + p, j:j + p])
    return torch.from_numpy(np.stack(batch))[:, None]   # (n, 1, p, p)

class TinyDnCNN(nn.Module):
    """conv-ReLU, (depth-2) x conv-BN-ReLU, conv. Predicts the NOISE, not the image."""
    def __init__(self, depth=5, ch=32):
        super().__init__()
        layers = [nn.Conv2d(1, ch, 3, padding=1), nn.ReLU(inplace=True)]
        for _ in range(depth - 2):
            layers += [nn.Conv2d(ch, ch, 3, padding=1), nn.BatchNorm2d(ch), nn.ReLU(inplace=True)]
        layers += [nn.Conv2d(ch, 1, 3, padding=1)]
        self.body = nn.Sequential(*layers)
    def forward(self, y):
        return y - self.body(y)                         # x_hat = y - R(y): residual learning

net = TinyDnCNN()
opt = torch.optim.Adam(net.parameters(), lr=2e-3)
t0 = time.time()
for step in range(300):
    x = random_patches()
    y = x + sigma * torch.randn_like(x)                 # synthetic pairs, made on the fly
    loss = nn.functional.l1_loss(net(y), x)
    opt.zero_grad(); loss.backward(); opt.step()
print(f"trained in {time.time() - t0:.0f} s, last L1 = {loss.item():.4f}")

net.eval()
with torch.no_grad():
    x = torch.from_numpy(test_img)[None, None]
    y = x + sigma * torch.randn_like(x)
    x_hat = net(y).clamp(0, 1)
mse = lambda a, b: torch.mean((a - b) ** 2).item()
print(f"PSNR noisy {10*np.log10(1/mse(y.clamp(0,1), x)):.2f} dB -> denoised {10*np.log10(1/mse(x_hat, x)):.2f} dB")
# e.g. PSNR noisy 20.74 dB -> denoised 28.64 dB
Even this toy model, trained for 300 small steps on four images, gains about 8 dB on an unseen photo and beats a hand-tuned Gaussian filter (Figure 4). Drag the slider to compare the noisy input with the tiny network’s output.
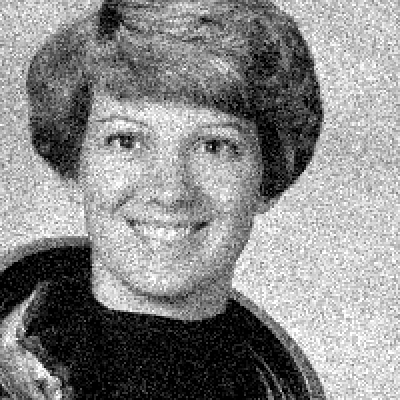
 Noisy (σ = 25)Tiny residual CNN
Dehazing
Plain version. Dehazing aims to recover contrast and color obscured by atmospheric scattering, especially in distant regions.
The classical recipe and the dark channel prior
Classical methods estimate the unknowns of (the transmission map and the airlight ), then invert the model. The hard part is finding a reliable relationship that pins those unknowns down. The most famous one is He et al.’s dark channel prior [25]. In haze-free outdoor images, most local patches contain some pixel that is very dark in at least one color channel (shadows, dark or colorful objects):
where is a small patch around and is color channel . Applying the same min–min operation to the haze model and using gives a transmission estimate
where (0.95 in the paper) keeps a little haze for depth perception. Then , with a small to avoid dividing by zero. The prior fails on large bright regions similar to the airlight (white walls, sky), and the coarse patch-based must be refined to follow edges.
Deep dehazing: two schools
The post [1] divides deep dehazing into two schools, and the split still describes the field well.
1. Physics-guided (“apply the formula”). Learn the unknown parameters, then invert the model. DehazeNet [26] uses a CNN (with Maxout units and a bounded ReLU) to regress the transmission from hazy patches. AOD-Net [27] simplifies the scattering model further by folding and into a single function :
where is a constant bias. A light-weight CNN predicts , so the whole network is end-to-end, and it can be attached in front of a detector and trained jointly.
2. Strong general architectures (“big learner”). Skip the physics and learn directly with a powerful network. GridDehazeNet [28] uses an attention-based multi-scale grid; FFA-Net [29] stacks channel- and pixel-attention blocks with adaptive feature fusion. These designs transfer well to other degradations, which is exactly the route taken by general restoration networks such as MIRNet [30]. Transformer dehazers followed: DehazeFormer [31] adapts the Swin Transformer to dehazing with a modified normalization layer, activation and spatial aggregation.
Datasets
- RESIDE [32]: a large benchmark with synthetic indoor and outdoor hazy images (generated from depth with the scattering model) plus real hazy images for task-driven evaluation. Its SOTS test set is the most quoted dehazing benchmark.
- O-HAZE [33] and Dense-Haze [34]: real hazy/haze-free pairs captured with professional haze machines, outdoor and with dense haze respectively. They are small but expose the synthetic-to-real gap.
- KITTI [35] is not a dehazing dataset. It is an autonomous-driving benchmark (stereo, optical flow, odometry, 3-D detection, tracking) recorded around Karlsruhe. Some dehazing papers synthesize fog on its images (it has depth from LiDAR and stereo) or use it to measure how dehazing affects downstream detection.
Desnowing
Plain version. Remove falling snow. It looks like a cousin of deraining, but it also behaves like dehazing.
Snow is harder than it looks. Snowflakes vary hugely in size and transparency, from opaque white blobs to semi-transparent streaks, and heavy snow also creates a veiling effect much like haze. So a desnowing model has to handle both the flakes and the fog-like veil. DesnowNet [36] introduced the Snow100K dataset (synthetic snow over real images, plus real snowy images) and a network that estimates both the translucency of snow and the residual it leaves. JSTASR [37] explicitly models snow size and transparency and adds a veiling-effect removal step. Desnowing is now usually studied inside “adverse weather” all-in-one models such as TransWeather [52].
Deraining
Plain version. Remove rain from photos. “Rain” means two very different things: thin streaks falling through the air, and drops sitting on the lens or windshield.
Rain streaks versus raindrops
- Rain streaks are thin, bright, oriented lines overlaid on the scene, modeled as . Distant streaks accumulate into a haze-like veil. Methods learn to separate the two layers. An early influential deep method jointly detects and removes rain [38] and comes with widely used synthetic datasets of light and heavy rain.
- Raindrops on a glass surface act as tiny lenses: they hide and refract the background, are often out of focus, and have no consistent orientation. The attentive GAN of Qian et al. [39] uses an attention map (where are the drops?) to guide both the generator and the discriminator, and introduced a paired raindrop dataset captured through glass with and without water drops.
Toward real scenes
Most deraining datasets are synthetic, and models trained on synthetic streaks often fail on real rain. The NTIRE 2025 Day and Night Raindrop Removal for Dual-Focused Images challenge [40] reflects the shift to real data: it uses the real-captured Raindrop Clarity dataset, covering daytime and nighttime scenes and both raindrop-focused and background-focused shots (14,139 training, 240 validation and 731 test images). The focus setting matters: when the camera focuses on the drops, the background is blurred too, so raindrop removal becomes partly deblurring.
Low-light enhancement (brief)
Plain version. Make a dark photo look properly exposed, with visible details and natural colors, without blowing up the noise.
Training compares dark images with normally exposed references of the same scene, for example the LOL dataset of paired low/normal-light images introduced with RetinexNet [41]. Classical methods rely on contrast adjustment (histogram equalization) and Retinex-based models (and, less often, an inverted atmospheric scattering model). Deep methods follow two lines: Retinex-inspired networks that decompose and adjust (RetinexNet [41]), and general well-designed networks. Retinexformer [42] (ICCV 2023), which its authors describe as the first Transformer-based low-light enhancement method, combines both: a one-stage Retinex formulation with illumination-guided attention. Low-light enhancement has enough of its own (zero-reference methods, curves, noise, color, video) to deserve a separate chapter: see DLCV 09C.
Image fusion (brief)
Plain version. Combine several images of the same scene, each good at something different, into one image that has the best of each.
Three common settings appear in the post [1]: infrared and visible fusion (thermal targets from IR, textures and color from the visible camera), multi-exposure fusion (detail from under- and over-exposed shots, an HDR-like result) and multi-focus fusion (an all-in-focus image from shots focused at different depths). Unlike the other tasks, there is usually no ground-truth fused image, so deep fusion relies on unsupervised losses that keep gradients and intensities from the sources, or on GANs. The survey by Zhang et al. [43] organizes deep fusion methods by these scenarios and by learning strategy.
Deblurring
Plain version. Recover a sharp image from one smeared by camera shake, object motion or defocus.
Problem setup
Deblurring is the direct instance of . If the kernel is known it is non-blind deblurring (the setting of the classical Wiener and CLS filters in DIP 5, and of learned non-blind solvers); if is unknown it is blind deblurring. Real motion blur in dynamic scenes is worse: different objects move differently and depth varies, so there is no single global .
Blind deblurring: estimating the kernel
Plain version. Blind deblurring must infer both a sharp image and the blur. Alternating methods refine one estimate while holding the other fixed.
The joint problem. For a spatially uniform blur, blind deconvolution solves
where is the blurred image, the unknown sharp image, the unknown kernel (a small window, e.g. to pixels for camera shake), an image prior (typically a sparse gradient penalty, because natural images have mostly flat regions and a few strong edges), a kernel prior, and their weights. The constraints say that a blur kernel only redistributes light: it is non-negative and preserves total brightness. Even so, the kernel can only be recovered up to a small shift, because moving one way and the other leaves unchanged.
Why it is badly ill-posed. Far more unknowns ( and ) than equations, and many pairs explain exactly. Worse, the most obvious pair is wrong: (no blur) and fits the data perfectly. Levin et al. [74] showed that with the usual sparse gradient priors, the blurry image often has a lower prior cost than the sharp one, because blur shrinks gradients and rewards small gradients. So naive joint MAP estimation over tends to return the no-blur solution. Their analysis points to a better-posed target: estimate only the kernel, averaging over all the sharp images that could have produced . A kernel has few unknowns compared with the many pixel observations, so it is much better determined than the full image; once is known, a non-blind deconvolution recovers .
Classical remedies. The methods that worked in practice either approximate that averaging over images (Fergus et al. [75], with variational Bayes), predict and select sharp edges so that the kernel is estimated only from reliable gradients (Cho and Lee [77] sharpen the current estimate with a shock filter, as the code below does; Xu and Jia [78] keep only informative edges), or change the prior so that the sharp image wins (Krishnan et al. [79], Pan et al. [80]). All of them share the loop below.
The standard recipe. Almost all classical blind deblurring methods follow the same loop. Starting from a delta kernel at the coarsest level of an image pyramid, alternate
where is the iteration, the image gradient, and the latent image after edge prediction or selection (sharpened, with weak gradients set to zero). The kernel step works in the gradient domain because convolution commutes with differentiation, , and gradients are where the blur information sits; with a quadratic penalty it has a closed form in the Fourier domain, followed by projection onto the constraints. After a few iterations the kernel is upsampled to the next pyramid level (coarse-to-fine), which avoids poor local minima because a large blur is only a few pixels wide at coarse scales. Finally, with fixed, a non-blind deconvolution produces the output image: Wiener or constrained least squares filtering as in IP 05, or a hyper-Laplacian or learned non-blind solver.
Deep learning and the kernel. Networks entered blind deblurring in three ways: they predict the kernel (or a deconvolution filter) and then deconvolve classically [81]–[83]; they fit a kernel and an image to one photo with untrained generator networks and no training data, as SelfDeblur [85] does; or they skip the kernel and map blurred to sharp images end to end, like the multi-scale network of Nah et al. [44], DeblurGAN [86], Restormer and NAFNet.
Optional: Classical and learned blind-deblurring methods (in the Supplementary notes). The kernel-only MAP formula and what each method named above does.
Optional: Deep Image Prior: the network as the prior (in the Paper guides). A reading guide to the paper behind SelfDeblur’s image generator.
Which is preferable? Kernel-based methods suit spatially uniform blur and give an interpretable kernel that can be checked and reused, but they are slower and break when the blur varies across the image. Kernel-free networks handle non-uniform blur from object motion and depth and are the current state of the art on dynamic-scene benchmarks such as GoPro, but they generalize only as far as their training blur and give no explicit kernel. The survey of Zhang et al. [69] summarizes this shift (the full comparison is in the same note).
Code: a toy alternating blind deconvolution. The snippet blurs a camera image with a curved camera-shake kernel, then alternates a closed-form image step (a CLS-like filter with a quadratic gradient penalty) and a kernel step (least squares on the strongest 2% of shock-filtered gradients, projected onto , ). It runs in about a second on a CPU.
Code · Python · 59 lines
import numpy as np
from numpy.fft import fft2, ifft2
from scipy.ndimage import convolve, gaussian_filter, laplace
from skimage import data, img_as_float, transform

rng = np.random.default_rng(0)
f_true = transform.resize(img_as_float(data.camera()), (256, 256), anti_aliasing=True)
K = 15                                               # kernel support K x K
h_true = np.zeros((K, K))
for t in np.linspace(0, 1, 40):                      # a curved "camera-shake" path
    h_true[round(3 + 8 * t), round(2 + 10 * t + 2 * np.sin(3 * t))] += 1
h_true = gaussian_filter(h_true, 0.5); h_true /= h_true.sum()
g = convolve(f_true, h_true, mode="wrap") + 0.005 * rng.standard_normal(f_true.shape)

def otf(h, shape):                                   # centered kernel -> transfer function
    p = np.zeros(shape); p[:h.shape[0], :h.shape[1]] = h
    return fft2(np.roll(p, (-(h.shape[0] // 2), -(h.shape[1] // 2)), (0, 1)))

G = fft2(g)
Dx, Dy = otf(np.array([[0, -1, 1]]), g.shape), otf(np.array([[0], [-1], [1]]), g.shape)

def image_step(h, lam):        # f = argmin ||h*f - g||^2 + lam ||grad f||^2  (closed form, CLS-like)
    H = otf(h, g.shape)
    return np.real(ifft2(np.conj(H) * G / (np.abs(H)**2 + lam * (np.abs(Dx)**2 + np.abs(Dy)**2))))

def shock(f, n=5, dt=0.5):     # edge prediction: a shock filter turns soft edges into steps
    f = gaussian_filter(f, 0.7)
    for _ in range(n):
        gy, gx = np.gradient(f)
        f = f - dt * np.sign(laplace(f)) * np.hypot(gx, gy)
    return f

def kernel_step(f, keep=0.02, beta=1e-3):   # least squares in the gradient domain, strong edges only
    num = den = 0
    for D in (Dx, Dy):
        fx = np.real(ifft2(D * fft2(f)))
        fx[np.abs(fx) < np.quantile(np.abs(fx), 1 - keep)] = 0
        Fx = fft2(fx)
        num, den = num + np.conj(Fx) * D * G, den + np.abs(Fx)**2
    h = np.roll(np.real(ifft2(num / (den + beta))), (K // 2, K // 2), (0, 1))[:K, :K]
    h = np.maximum(h, 0)                             # project onto h >= 0 ...
    return h / h.sum()                               # ... and sum(h) = 1

def best_shift(fn):            # blind deconvolution recovers h (and f) only up to a small translation
    return min(fn(dy, dx) for dy in range(-3, 4) for dx in range(-3, 4))
kernel_error = lambda h: best_shift(lambda dy, dx: np.linalg.norm(np.roll(h, (dy, dx), (0, 1)) - h_true)) / np.linalg.norm(h_true)
psnr = lambda f: -best_shift(lambda dy, dx: 10 * np.log10(np.mean((np.clip(np.roll(f, (dy, dx), (0, 1)), 0, 1) - f_true)[8:-8, 8:-8] ** 2)))

h = np.zeros((K, K)); h[K // 2, K // 2] = 1
h = gaussian_filter(h, 1.0); h /= h.sum()            # start from an almost-delta kernel ("no blur")
print(f"kernel error at start: {kernel_error(h):.2f}")
for _ in range(30):                                  # alternate: image update, then kernel update
    h = kernel_step(shock(image_step(h, lam=0.02)))
print(f"kernel error after 30 alternations: {kernel_error(h):.2f}")
print(f"PSNR  blurry {psnr(g):.2f} dB | estimated kernel {psnr(image_step(h, 1e-2)):.2f} dB"
      f" | true kernel {psnr(image_step(h_true, 1e-2)):.2f} dB")
# kernel error at start: 1.19
# kernel error after 30 alternations: 0.57
# PSNR  blurry 22.59 dB | estimated kernel 27.11 dB | true kernel 29.67 dB
The relative kernel error roughly halves, and the final non-blind step with the estimated kernel recovers most of the gap between the blurry input and the true-kernel result. Be honest about what this toy is: the blur is synthetic, uniform and circular (so the FFT model is exact), the noise is low, and the parameters (lam, keep, the number of shock iterations) were tuned on this one image. There is no image pyramid, so larger kernels would fail, and with real photos you would also need boundary handling, saturated-pixel handling and robust losses. Both errors are measured after the best small shift, because of the translation ambiguity explained above.
Data and milestones
Nah et al. [44] (CVPR 2017) addressed this with the GoPro dataset: they recorded sharp video with a high-speed camera and averaged consecutive frames to produce realistically blurred images, keeping the middle frame as the sharp target. Their network is multi-scale: it restores a coarse version first, then refines at finer scales, like the coarse-to-fine schemes of classical blind deblurring, but without estimating a kernel at all. GoPro is still the most common deblurring benchmark.
Today the most common baselines are the general backbones Restormer [23] and NAFNet [24]. NAFNet’s striking finding is that the usual nonlinear activations (ReLU, GELU, Sigmoid) are not needed: they can be replaced by a simple element-wise multiplication of two feature halves (“SimpleGate”) or removed, giving a “nonlinear activation free” network that is both simpler and stronger on GoPro and SIDD. Multiplying features is still nonlinear; the name concerns conventional activation functions. The deblurring survey by Zhang et al. [69] covers the wider landscape (blind and non-blind, video, defocus, losses).
Inpainting (brief)
Plain version. Fill in missing or damaged regions (scratches, removed objects, holes) with plausible content.
Inpainting is the restoration task closest to image generation: inside a large hole there is nothing to restore, only something to invent that matches the surroundings. The degradation is a mask, , where is 0 in the hole and 1 elsewhere. Masked autoencoders (MAE) [45] can be seen as inpainting used as a pre-training task: hide 75% of image patches and train a ViT to reconstruct them, which turns out to teach strong visual representations. For practical inpainting, LaMa [46] uses fast Fourier convolutions with an image-wide receptive field and training on large masks to fill big holes at high resolution; today, diffusion-based inpainting is the default for large, semantic edits.
Matting (brief)
Plain version. Cut out the foreground (a person, their hair) with soft, partially transparent edges so it can be pasted on a new background.
Matting assumes each pixel is a blend of foreground and background,
where is the opacity (alpha matte), the foreground color and the background color. With seven unknowns per pixel ( and two RGB colors) and three observations, the problem is badly underdetermined, so classical methods ask the user for a trimap (definite foreground, definite background, unknown band). It can be seen as a soft variant of segmentation. Background Matting [47] replaces the trimap with an extra photo of the background without the subject, and trains networks first on synthetic composites and then on real images with an adversarial loss that judges how natural the new composites look.
General backbones
Plain version. Across all these tasks, a handful of network designs keep winning. They are general “image-to-image engines” that you can train on any of the degradations above.
| Backbone | Core idea | Why it suits restoration |
|---|---|---|
| U-Net [48] | Encoder–decoder with skip connections at every scale | Large receptive field from the downsampling path, fine detail from the skips |
| SwinIR [14] | Residual groups of shifted-window self-attention blocks at full resolution | Content-adaptive weights; strong for SR, denoising, JPEG |
| Restormer [23] | U-Net of transformer blocks; attention computed across channels (transposed attention) plus gated feed-forward | Cost linear in the number of pixels, so it scales to large images |
| NAFNet [24] | U-Net of simple conv blocks with LayerNorm, SimpleGate and simplified channel attention; no conventional activation functions; gates remain nonlinear | Very strong accuracy per FLOP; the default “simple baseline” |
| MambaIR / MambaIRv2 [49], [50] | Selective state-space (Mamba) scans with local enhancement and channel attention; v2 adds “attentive” non-causal scanning | Global receptive field at linear cost |
Design reasons that recur. (1) Global residual: predict (or minus an upsampled ) so the network learns only the missing part. (2) No batch normalization in most SR/restoration nets since EDSR [10]: BN statistics differ between training patches and full test images and hurt color/range fidelity. (3) Large receptive field at manageable cost: multi-scale U-Nets, windowed or channel attention, state-space scans. Restoration needs context (to tell a texture from noise) and full-resolution detail. (4) Attention or gating for content-adaptive processing: channel attention (RCAN), gating (NAFNet, Restormer). The post’s “Extension” list predicted new architectures from ViT, flow, GAN and diffusion; by 2026 the state-space model joined CNNs and transformers as a third backbone option [49], [50].
All-in-one and universal restoration
Plain version. Instead of training one model for rain, another for haze and another for noise, train one model that figures out what is wrong with the image and fixes it.
Motivation
The post’s “Extension” section lists all-in-one restoration as one of the hottest topics of 2023, starting around 2021. The motivation is practical: in a deployed system we do not know in advance which degradation (or mixture) a given image has, and weather can change or combine at any moment. A bank of task-specific models needs a reliable classifier in front and wastes memory; a single model that adapts is more convenient. The difficulty is task interference: different degradations need different, sometimes opposite operations (denoising smooths, deblurring sharpens), so naive multi-task training underperforms specialists.
Representative methods
- AirNet [51] (CVPR 2022): a contrastive degradation encoder learns from paired restoration data and contrastive crop pairs how the image is degraded, without a user-supplied task label at inference and guides the restorer; its noise + rain + haze setting became the standard three-task benchmark.
- TransWeather [52] (CVPR 2022): one transformer for rain, fog and snow, with learnable weather-type queries.
- PromptIR [53] (NeurIPS 2023): lightweight prompt blocks inject degradation-specific information into a Restormer-style decoder.
- AdaIR [54] (ICLR 2025): different degradations affect different frequency bands, so it adapts low- and high-frequency features separately.
- DA-CLIP [55] (ICLR 2024): an adapted CLIP model supplies a degradation embedding that guides the restorer.
- InstructIR [56] (ECCV 2024): a natural-language instruction (“remove the rain”) conditions the network.
Optional: All-in-one methods in more detail (in the Supplementary notes). How each of the six models represents the degradation and injects it into the network.
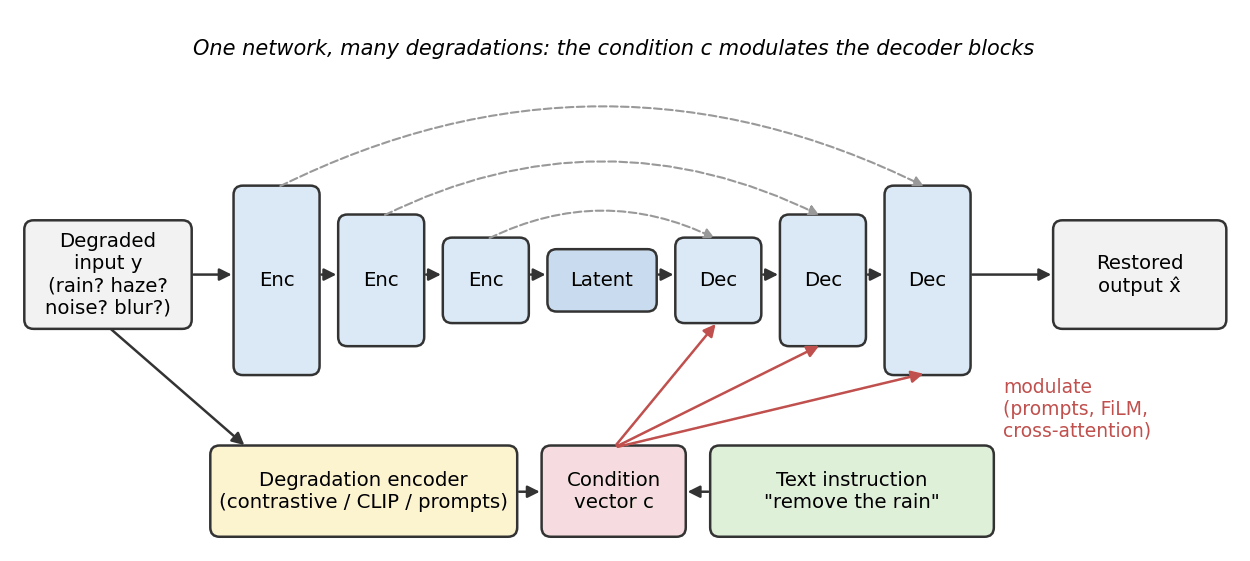
The post’s original motivation is still the core; what changed is who decides the degradation type. It moved from fixed task labels to learned prompts, to vision–language embeddings and finally to human instructions, often backed by large pretrained models. The all-in-one survey [72] discusses this in detail.
Generative and tool-based extensions. AutoDIR [119] uses automatic quality assessment, latent diffusion and structural correction. PromptFix [122] combines user instructions with visual auxiliary descriptions and high-frequency preservation. AgenticIR [120] and 4KAgent [121] instead arrange and evaluate pretrained tools; their planning loop and repeated candidates have a different cost from one forward pass through an all-in-one backbone.
Optional: Restormer and NAFNet (in the Paper guides). Start with how a restoration backbone preserves detail and gathers context.
Optional: AirNet, TransWeather, PromptIR, AdaIR (in the Paper guides). Then compare degradation features, learned queries, feature prompts and frequency adaptation.
Optional: DA-CLIP, InstructIR, AutoDIR, PromptFix (in the Paper guides). Distinguish inferred visual guidance from human instructions and generative editing.
Optional: AgenticIR, 4KAgent (in the Paper guides). Finish with planning, candidate selection, reflection and rollback across tools.
Loss functions
Plain version. The loss decides what “good” means. Pixel losses reward being close to the truth on average; perceptual and adversarial losses reward looking real; frequency losses reward getting fine detail.
Pixel losses. With ,
where is the number of pixel values and a small constant that makes the last one a smooth, differentiable version of L1. L2 directly optimizes PSNR but penalizes large errors heavily and converges to the posterior mean. Zhao et al. [57] showed that the loss alone changes results noticeably with the architecture fixed, and that L1 and perceptually motivated losses (including combinations with SSIM) often beat L2 even on L2-related metrics. L1 is the default in most modern SR and restoration papers.
Perceptual (feature) loss. Compare images in the feature space of a pretrained classification network (usually VGG) [58]:
where is the feature map of layer with channels and size . It tolerates small misalignments and rewards matching edges and textures rather than exact values.
Adversarial loss. A discriminator learns to tell restored from real images and the restorer learns to fool it, e.g. . This pushes outputs onto the manifold of natural images (SRGAN [12], ESRGAN [13], Real-ESRGAN [4]) at the cost of possible hallucinated texture. In practice GAN-based restorers use a weighted sum such as with weights .
Frequency losses. Networks tend to fit low frequencies first and under-fit fine detail. Adding a loss on the Fourier transform , such as on complex values or on amplitude, directly penalizes missing high frequencies. The focal frequency loss [59] goes further and adaptively up-weights the frequency components that are currently hardest to reconstruct. Frequency terms are now common in deblurring and all-in-one models.
Evaluation metrics
Plain version. “Is the restored image close to the truth?” and “Does it look like a real photo?” are different questions, answered by different metrics, and you cannot maximize both at once.
Full-reference metrics
PSNR (peak signal-to-noise ratio):
where is the largest possible pixel value (1 or 255) and is the mean squared error. It is measured in dB; +1 dB is a 21% reduction in MSE.
SSIM (structural similarity) [60] compares local means, variances and covariance:
computed over local windows , of the two images and averaged, where are local means, local variances, the local covariance and small constants for stability. It correlates better with perceived structure than PSNR but still prefers smooth results.
LPIPS [61] measures distance between deep-network features (calibrated on human similarity judgments). Lower is better, and it rewards realistic textures that PSNR penalizes.
Code · Python · 17 lines
import numpy as np
from scipy import ndimage as ndi
from skimage import data, img_as_float32
from skimage.metrics import peak_signal_noise_ratio, structural_similarity

x = img_as_float32(data.camera())
y = np.clip(x + np.random.default_rng(0).normal(0, 0.1, x.shape), 0, 1).astype(np.float32)
x_hat = ndi.gaussian_filter(y, 1.0)

def psnr(ref, est, peak=1.0):
    mse = np.mean((ref.astype(np.float64) - est) ** 2)
    return 10 * np.log10(peak ** 2 / mse)

print(f"PSNR  ours {psnr(x, x_hat):.2f} dB | skimage {peak_signal_noise_ratio(x, x_hat, data_range=1):.2f} dB")
print(f"SSIM  {structural_similarity(x, x_hat, data_range=1):.3f}")
# PSNR  ours 27.20 dB | skimage 27.20 dB
# SSIM  0.639
Always report the conventions (RGB or Y channel, border crop, data range, 8-bit rounding): differences in these alone can shift published PSNR by tenths of a dB.
No-reference metrics
Plain version. A no-reference metric estimates quality from the restored image alone. It is useful when no clean reference exists, but cannot establish that recovered details are correct.
Full-reference, reduced-reference and no-reference
Image quality assessment (IQA) methods are grouped by how much they know about the pristine image :
- Full-reference (FR): the whole is available, and the metric compares with it pixel by pixel or feature by feature (PSNR, SSIM [60], LPIPS [61]). This is what synthetic benchmarks use.
- Reduced-reference (RR): only a few summary features of are available (for example statistics sent alongside a compressed video), and the metric compares the same features computed on .
- No-reference (NR, blind): only is available. The metric must carry its own model of what “good” looks like.
Restoration needs NR metrics for three reasons. (1) Real test images have no ground truth: real-world SR, deraining and dehazing are evaluated on photos where nobody has the clean version. (2) The reference itself can be imperfect or only one of many valid answers: a GAN or diffusion output can look excellent yet have low PSNR because its texture differs from the reference’s (the perception–distortion trade-off below). (3) NR scores can steer systems at run time, for example to choose among outputs or parameters when no reference exists. The price: an NR metric is a model of human opinion, and every model has blind spots.
How NR metrics are validated: correlation with human opinion
Plain version. We trust an NR metric only if it ranks images the way people do. So researchers collect many human ratings on many images and check how well the metric’s scores agree with them.
Mean opinion score. In a subjective study, each image is rated by several observers, and the average rating is its mean opinion score, , where is the score of rater and the number of raters. Some datasets publish a differential score (DMOS), based on the difference between the ratings of the distorted image and its reference; for DMOS, lower usually means better.
SRCC (Spearman rank-order correlation) measures whether the metric puts the images in the same order as people:
where is the number of test images and the difference between the rank of image by predicted score and its rank by MOS (this short form assumes no tied ranks; with ties one computes the Pearson correlation of the ranks). SRCC is unchanged by any monotonic transformation of the scores, so it measures prediction monotonicity.
PLCC (Pearson linear correlation) measures how linearly the scores agree:
where is the metric’s score for image , its MOS, and , their means. Because metric scales are arbitrary, it is common practice to first pass through a fitted monotonic (usually logistic) function and compute PLCC on the mapped scores, so PLCC measures prediction accuracy after calibration. Both lie in . For “lower is better” metrics such as NIQE the raw correlation with MOS is negative, and papers report its absolute value. A metric is typically trained on part of a dataset and tested on the rest, and its cross-dataset correlation is the more honest test of generalization.
Human-rated datasets. NR metrics are trained and tested on image-quality datasets with human scores. What matters for restoration is where the distortions come from: synthetic damage (LIVE [104], TID2013 [105], KADID-10k [106]), real camera photos (KonIQ-10k [107], SPAQ [108]) or the outputs of restoration algorithms themselves (PIPAL [109]). Only datasets of the last kind contain the images a restoration paper actually needs to score.
Optional: Human-rated IQA datasets (in the Supplementary notes). What each dataset contains, in one table.
Family 1: natural-scene-statistics (NSS) models
Plain version. Clean photos share hidden statistical habits. If you remove local brightness and local contrast from a photo, the leftovers follow a bell-shaped histogram of a typical shape, and neighboring leftovers are only weakly related. Blur, noise and compression change that shape in characteristic ways. NSS metrics measure the shape and ask how unusual it is.
MSCN coefficients. For a grayscale image , the mean-subtracted contrast-normalized (MSCN) coefficients are [94]
where is a pixel position, a small circularly symmetric Gaussian window whose weights sum to 1, and the local weighted mean and standard deviation, and a small constant (1 for 8-bit images) that prevents division by zero in flat regions. This is a divisive normalization, loosely modeled on contrast gain control in early human vision.
The generalized Gaussian fit. The histogram of is modeled by a zero-mean generalized Gaussian distribution (GGD),
where is an MSCN value, the shape ( is a Gaussian, a Laplacian; smaller means a peakier histogram with heavier tails, larger a flatter top), the variance, the corresponding scale and the gamma function. A simple way to estimate is moment matching: the ratio depends only on , so one computes the left side from the data and searches for the that matches it.
BRISQUE [94] (Blind/Referenceless Image Spatial Quality Evaluator) computes the GGD shape and variance of the MSCN coefficients, plus parameters of asymmetric GGDs fitted to products of neighboring MSCN coefficients in four orientations (horizontal, vertical and the two diagonals), at two image scales. A support-vector regressor trained on human scores of synthetically distorted images maps these features to a quality score. Lower is better. It is opinion-aware: it needs human scores for training.
NIQE [62] (Natural Image Quality Evaluator) is opinion-unaware: it never sees human scores or distorted images. It computes similar NSS features on sharp patches, fits a multivariate Gaussian (MVG) with mean and covariance to features from a corpus of pristine images, fits another MVG to the test image’s patches, and reports
a Mahalanobis-like distance between the two Gaussians ( is the transpose). Lower is better; zero means “statistically like the pristine corpus”.
Two relatives appear often in restoration papers. PIQE [96] applies MSCN statistics block by block, needs no opinion scores, and also gives a map of where the image looks distorted. The Perceptual Index (PI) of the 2018 PIRM super-resolution challenge [63] combines NIQE with a score learned by Ma et al. [95] from human ratings of super-resolved images; lower PI means better perceptual quality, and many perceptual SR papers still report it.
Optional: PIQE and the Perceptual Index (in the Supplementary notes). How PIQE pools block distortions, the PI formula, and how the PIRM challenge used it.
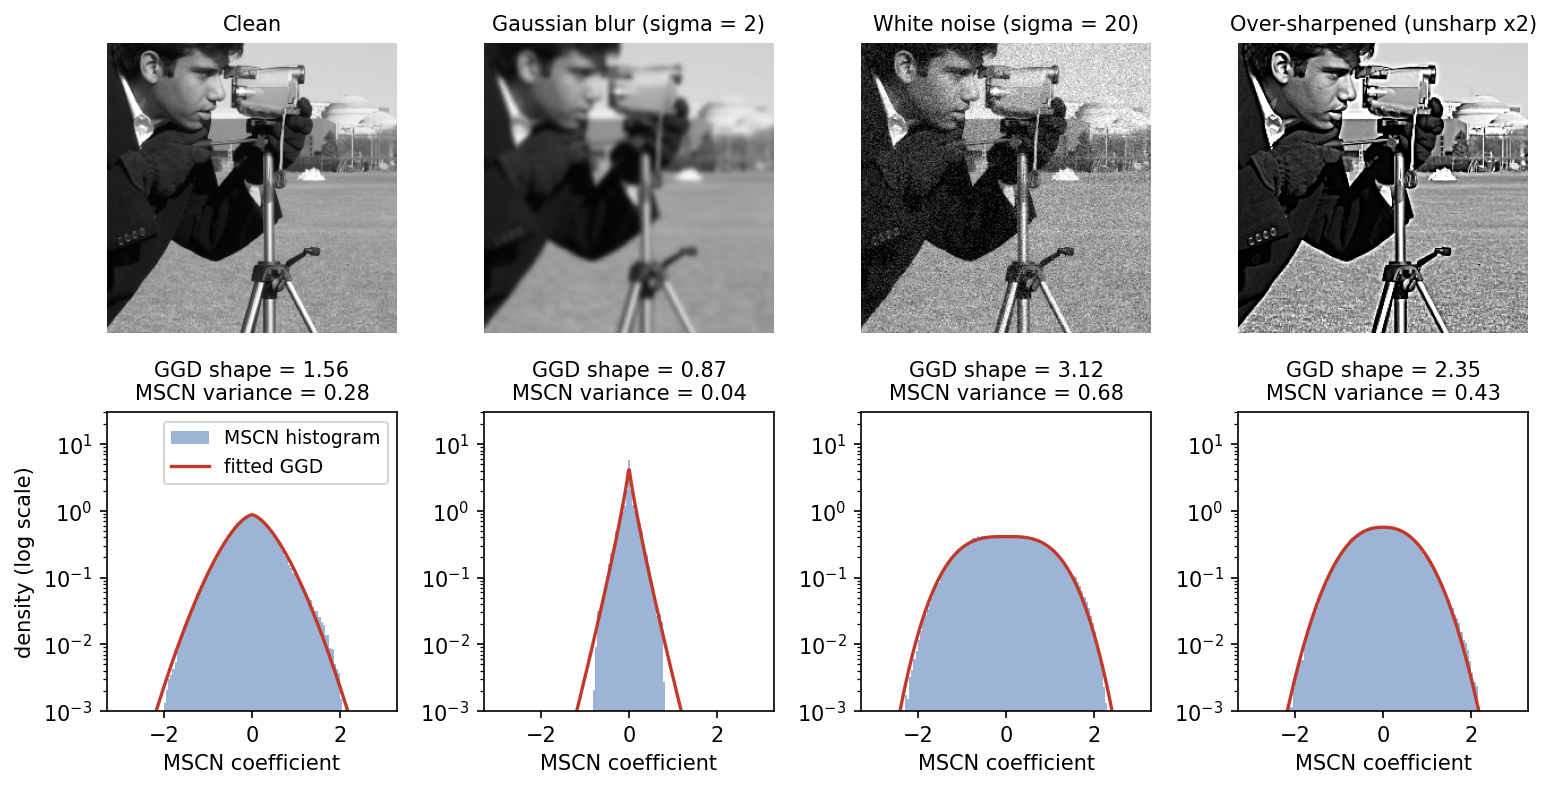
Code: MSCN statistics in practice. The snippet computes MSCN coefficients, the GGD shape by moment matching, the MSCN variance and the correlation between horizontal neighbors (a simplified version of BRISQUE’s pairwise features) on camera and on blurred, noisy and over-sharpened versions:
Code · Python · 35 lines
import numpy as np
from scipy.ndimage import gaussian_filter
from scipy.special import gamma
from skimage import data, img_as_float

def mscn(img, sigma=7/6, C=1.0):
    """Mean-subtracted contrast-normalized coefficients of a grayscale image in [0, 255]."""
    mu = gaussian_filter(img, sigma)
    sd = np.sqrt(np.abs(gaussian_filter(img * img, sigma) - mu * mu))
    return (img - mu) / (sd + C)

def ggd_shape(x):
    """Moment-matching estimate of the generalized Gaussian shape alpha (2 = Gaussian)."""
    alphas = np.arange(0.2, 10.0, 0.001)
    r_theory = gamma(1 / alphas) * gamma(3 / alphas) / gamma(2 / alphas) ** 2
    r_data = np.mean(x ** 2) / np.mean(np.abs(x)) ** 2
    return alphas[np.argmin((r_theory - r_data) ** 2)], np.mean(x ** 2)

rng = np.random.default_rng(0)
clean = img_as_float(data.camera()) * 255
versions = {
    "clean": clean,
    "blur (sigma=2)": gaussian_filter(clean, 2),
    "noise (sigma=20)": np.clip(clean + rng.normal(0, 20, clean.shape), 0, 255),
    "over-sharpened": np.clip(clean + 2.0 * (clean - gaussian_filter(clean, 2)), 0, 255),
}
for name, img in versions.items():
    m = mscn(img)
    alpha, var = ggd_shape(m)
    rho = np.mean(m[:, :-1] * m[:, 1:]) / var           # correlation of horizontal neighbors
    print(f"{name:17s} GGD shape {alpha:4.2f} | MSCN variance {var:4.2f} | neighbor corr. {rho:+.2f}")
# clean             GGD shape 1.56 | MSCN variance 0.28 | neighbor corr. +0.12
# blur (sigma=2)    GGD shape 0.87 | MSCN variance 0.04 | neighbor corr. +0.89
# noise (sigma=20)  GGD shape 3.12 | MSCN variance 0.68 | neighbor corr. -0.10
# over-sharpened    GGD shape 2.35 | MSCN variance 0.43 | neighbor corr. +0.09
Each distortion pushes the features in its own direction (Figure 6). Blur removes local contrast, so most MSCN values collapse toward zero: tiny variance, a very peaky histogram (small ) and strongly correlated neighbors. Noise adds independent energy: larger variance, a flat-topped histogram ( above 2) and neighbor correlation near zero (slightly negative, because subtracting the local mean couples neighbors). Over-sharpening moves the features in the same direction as noise. That is the core weakness of NSS metrics for restoration: they cannot tell restored texture from invented high-frequency energy. Note also that the absolute numbers depend on content and on (the clean camera image is not a unit Gaussian), which is why BRISQUE needs a trained regressor and NIQE a pristine reference corpus rather than fixed thresholds.
Family 2: learned deep models
Plain version. Instead of hand-made statistics, train a neural network to predict human ratings directly. Deep features capture content, semantics and complex artifacts far better, but the model only knows the kinds of images and opinions it was trained on.
Five widely used examples: NIMA [97] predicts the whole distribution of human ratings rather than one number; HyperIQA [98] adapts its quality rule to the image content, since the same blur is judged differently on a sky and on a face; MUSIQ [99] reads the image at its native resolution and aspect ratio, so no resizing changes the artifacts it judges; MANIQA [100] is a transformer that won the no-reference track of the NTIRE 2022 perceptual IQA challenge, whose data include restoration and GAN outputs; and TOPIQ [101] lets high-level semantics decide which low-level distortions matter.
All of these are opinion-aware and output “higher is better” scores, and each depends on its training dataset: a model trained on KonIQ-10k and the same architecture trained on PIPAL can rank restoration methods differently.
Optional: How the learned NR assessors work (in the Supplementary notes). The architecture and training target behind each of the five models.
Family 3: vision-language and large multimodal models
Plain version. Models trained on huge collections of images and text already “know” what a good or bad photo looks like. You can ask them, either by comparing the image with text prompts or by literally asking a chatbot-style model to rate it.
CLIP-IQA [102] compares the CLIP embedding of the image with those of an opposite prompt pair such as “Good photo.” and “Bad photo.” and turns the two similarities into a score between 0 and 1 (higher is better). The basic version needs no opinion scores at all; other prompt pairs (“Sharp photo.” / “Blurry photo.”) probe single attributes, and the wording of the prompts changes the scores. Q-Align [103] fine-tunes a large multimodal model to answer the way human raters do, with a rating word from bad to excellent, and turns its probabilities for the five words into a score. Such models are strong across datasets but heavy, and they inherit the biases of their base model.
Optional: CLIP-IQA and Q-Align scores (in the Supplementary notes). The two formulas that turn similarities and word probabilities into a quality score.
Distribution-level metrics
Some metrics score a set of outputs rather than one image. FID [64] compares the distribution of Inception features of the restored set with that of a set of real images; it was designed for generative models and is used for generative restoration such as diffusion SR, but it needs many images and says nothing about any single one. IS (Inception Score), mentioned in the post, measures the confidence and diversity of class predictions; it suits class-conditional generation rather than restoration and is rarely used there today.
User studies and paired comparisons
Plain version. In the end, people decide what looks good. The two standard ways to ask them are to rate images on a scale or to choose the better of two. Such a study is also the yardstick every NR metric above is validated against, and it is the strongest evidence a new method can bring.
Mean opinion score (MOS). Each of raters gives an image a score on a fixed scale (often 1 to 5), and the MOS is their average, as defined for metric validation above. ITU-R BT.500 [111] standardizes such tests: viewing conditions, rating scales, single- and double-stimulus and comparison methods, and screening of unreliable raters.
Paired comparison. Absolute scales drift between raters; choosing the better of two images is easier and more consistent. The Bradley–Terry model [112] turns many such choices into one strength per method , fitted so that method is preferred over method with probability . Sorting methods by their fitted strengths gives one consistent ranking, although each rater only ever compared two images at a time.
Optional: Fitting the Bradley–Terry model (in the Supplementary notes). The maximum-likelihood update and a runnable three-method example.
Good practice: hide method names, randomize the order and the left/right position, show the input for context, use enough images and raters, report confidence intervals or significance, and state the display and viewing conditions. A study with a handful of raters and hand-picked images is a demonstration, not evidence.
Pitfalls
- Metrics can be gamed. A restorer that adds grain or sharpens edges can improve NSS scores, as the code above shows, without becoming more faithful. Any differentiable metric (and any learned IQA network) used as a training loss or for model selection can be optimized directly, and the network may learn to please the metric rather than people. If a method uses CLIP or an IQA network in its loss, evaluating it with the same model is not independent.
- Domain mismatch. Most opinion-aware metrics were trained on synthetic distortions (LIVE, TID2013, KADID-10k) or on camera photos (KonIQ-10k, SPAQ). Restoration outputs contain different artifacts: hallucinated textures, over-smoothing, GAN patterns. This mismatch was the explicit motivation for PIPAL [109], whose authors found that existing IQA methods could not fairly evaluate GAN-based restoration. For low light, the problems are exposure and color, which most NSS features normalize away; see the low-light-specific discussion in DLCV 09C.
- Metrics disagree. NSS, learned and vision-language metrics often rank the same methods differently, and all can disagree with people. Scores also depend on the implementation, checkpoint, color space, input size and whether the image is resized, so numbers copied from different papers are often not comparable.
- “Higher NR quality” is not “more correct”. An NR metric cannot know whether a sharp face or line of text matches the real scene. A hallucinated license plate can score perfectly.
Recommended practice
- When a reference exists, lead with FR metrics (PSNR, SSIM, LPIPS) and add NR metrics as a complement; place your method on the perception–distortion plane (next subsection).
- On real images without references, report several NR metrics from different families (for example NIQE or PI, one or two learned models such as MUSIQ, MANIQA or TOPIQ, and a vision-language one such as CLIP-IQA or Q-Align), and say which way each one points.
- Use one shared implementation and state it, with versions and checkpoints. The open-source IQA-PyTorch toolbox (
pyiqa) [110] reimplements most metrics in this section (NIQE, BRISQUE, PIQE, the Ma score and PI, NIMA, HyperIQA, MUSIQ, MANIQA, TOPIQ, CLIP-IQA, Q-Align, and FR metrics) behind one interface. - Do not tune on the judge: keep at least one metric that played no role in training or model selection.
- Back important claims with a user study (mean opinion scores or paired comparisons, blind and randomized); the user-study subsection above describes MOS and Bradley–Terry paired-comparison protocols. When metrics disagree with each other or with people, say so.
Summary table
The four families at a glance:
| Family | Examples | Needs human scores? | Better | Typical blind spot |
|---|---|---|---|---|
| NSS | NIQE, BRISQUE, PIQE, PI | NIQE and PIQE no; BRISQUE and PI (through Ma) yes | Lower | Rewards added grain and sharpening; normalizes away exposure and color |
| Learned deep | NIMA, HyperIQA, MUSIQ, MANIQA, TOPIQ | Yes | Higher | Depends on its training data; restoration artifacts differ from the training distortions |
| Vision-language | CLIP-IQA, Q-Align | CLIP-IQA (zero-shot) no; Q-Align yes | Higher | Prompt wording; biases of the base model; heavy |
| Distribution-level | FID | No (pretrained Inception features) | Lower | Needs many images; says nothing about a single one |
Optional: Metric-by-metric summary table (in the Supplementary notes). Family, training requirement, direction and main sensitivity of all thirteen metrics.
The perception–distortion trade-off
Blau and Michaeli [65] formalized the tension. Let be any distortion measure (MSE, SSIM, …) and a divergence between the distribution of real images and that of restored images (perceptual quality: small means outputs are statistically indistinguishable from real images). The perception–distortion function is
where the minimum is over all (possibly random) restoration methods. They proved that is non-increasing and (for divergences convex in their second argument) convex: there is an unattainable region near the origin. A method cannot be both minimal-distortion and perfectly realistic. In particular, the MMSE estimator has the lowest distortion but a blurry, unrealistic output distribution; to look real you must accept higher MSE. GANs (and now diffusion models) are principled ways to move along the bound.
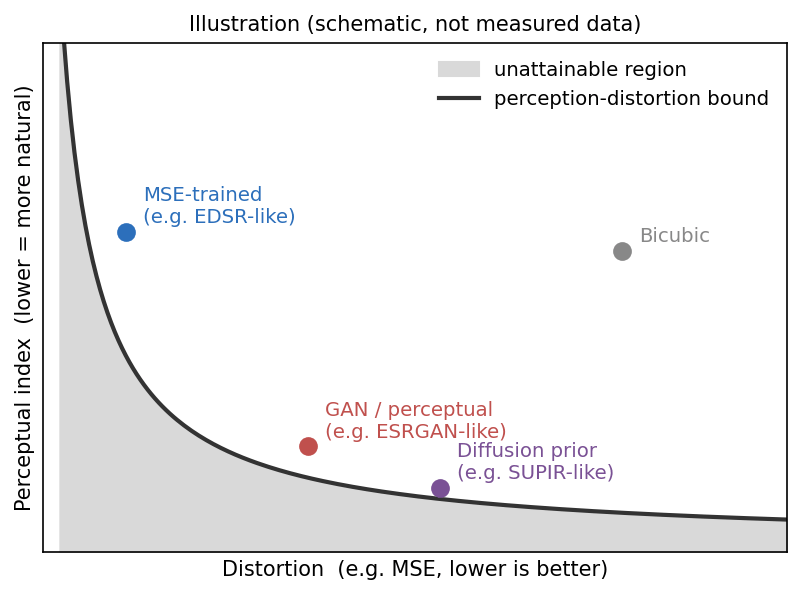
This is the update in the post’s metric section: since diffusion models can generate plausible but unfaithful detail, the gap between fidelity (PSNR/SSIM) and perceptual quality has become central. The NTIRE 2025 SR challenge therefore ran two tracks: a restoration track ranked by PSNR and a perceptual track ranked by a perceptual score [3], whereas the 2024 edition ranked by PSNR [2]. Practical advice: report both a distortion and a perceptual metric, and say where on the trade-off your method aims.
NTIRE challenges
Plain version. Each year a CVPR workshop runs public competitions on fixed datasets and publishes a report describing the winning ideas: the easiest way to see what currently works.
The NTIRE challenge reports are a good way to follow restoration now that per-task leaderboards are gone. Each report describes the task, data, evaluation protocol and the methods of top teams. Examples cited in this tutorial:
- NTIRE 2017 SR [19]: introduced DIV2K; EDSR [10] won.
- NTIRE 2024 SR [2]: bicubic on DIV2K, ranked by PSNR.
- NTIRE 2025 SR [3]: separate restoration (PSNR) and perceptual tracks.
- NTIRE 2025 raindrop removal [40]: real day and night raindrop images with dual focus.
- NTIRE 2024 and 2025 low-light enhancement: the two editions of the low-light challenge are summarized in DLCV 09C.
Two patterns appear across recent reports: winning entries are usually ensembles or large hybrids of the backbones above (HAT-, Restormer-, NAFNet- or Mamba-style, sometimes with diffusion priors) trained with heavy data and compute, and challenges increasingly use real captured data and perceptual tracks.
Modern view
The post closes with an extension list (medical images, multimodal, unsupervised, new architectures, all-in-one, low-level plus high-level, real-time, underwater). Most of these are now active areas. Here we summarize the survey literature task by task, then the 2023–2026 state of the art and the open problems.
Survey papers
- Super-resolution (Wang, Chen and Hoi [66]): describes SR models as choices of upsampling position and operator, network design, losses and training, and flagged unsupervised, real-world SR as the main open direction.
- Denoising (Tian et al. [67]; Elad, Kawar and Vaksman [68]): the realism of the noise model is often the bottleneck; denoisers are now building blocks for other inverse problems and for diffusion models, and the frontier moved toward sampling from the posterior.
- Deblurring (Zhang et al. [69]): dynamic-scene deblurring moved from kernel estimation to end-to-end multi-scale networks trained on captured pairs such as GoPro.
- Dehazing (Gui et al. [70]) and deraining (Yang et al. [71]): physics-guided and physics-free designs coexist, and realistic degradation models and real-world evaluation matter more than further architecture tweaks on synthetic data.
- All-in-one (Jiang et al. [72]): a taxonomy by architecture, learning paradigm and core innovation; inconsistent task sets complicate comparisons, and generalization to unseen and mixed degradations is open.
- Diffusion restoration (Li et al. [73]): the best perceptual quality, but costly and with fidelity and hallucination concerns; few-step distillation and better evaluation are the key directions.
Optional: Survey papers in detail (in the Paper guides). The full title, venue, taxonomy and takeaway of each survey.
State of the art, 2023–2026
- All-in-one and blind restoration became the mainstream setting, not a niche topic. Methods moved from learned degradation representations (AirNet) to prompts (PromptIR), frequency-aware adaptation (AdaIR) and language guidance (DA-CLIP, InstructIR).
- Pretrained diffusion models as generative priors transformed real-world SR and blind restoration (DiffBIR, SUPIR), and one-step variants (OSEDiff) cut the inference cost from tens or hundreds of steps to one.
- State-space models (MambaIR, MambaIRv2) joined CNNs and transformers as backbone options with global receptive fields at linear cost.
- Evaluation caught up with generation: challenges separate fidelity from perceptual tracks [3], and real captured datasets (SIDD, O-HAZE, Dense-Haze, Raindrop Clarity) are standard alongside synthetic benchmarks.
Open problems
- Real-world generalization. Synthetic pipelines still miss real camera processing, spatially varying blur and mixed weather; models degrade on unseen combinations.
- Fidelity versus hallucination. Generative priors can invent text, faces or textures. For medical, forensic and scientific use this is unacceptable, and we lack good metrics for “faithful but sharp”.
- Evaluation. PSNR/SSIM reward blur; no-reference metrics can be gamed; human studies are costly. Agreement between metrics and human preference for generative restoration is still weak.
- Efficiency. High-resolution, real-time (and video) restoration on phones and cameras remains a strong constraint, for transformers and diffusion models especially.
- Task interference and scaling in all-in-one models, and how to add a new degradation without retraining.
- Low-level plus high-level. Restoration that helps downstream detection or segmentation, rather than human viewers, is a different objective (task-driven evaluation, as in RESIDE [32]).
A perspective from the original post
The post ends with two observations that still hold. First, because each task is simple to state, the race for state of the art is largely won by special architectures, which means a lot of compute and complicated experiments; but these tasks are very practical and easy to apply, so there is much room in applications and in combining tasks (exactly where all-in-one restoration went). Second, compared with high-level tasks the learning curve is gentle: a beginner can easily picture what the model is doing (a damaged image goes in, a cleaner one comes out), which makes low-level vision a good door into deep learning research.
Key takeaways
- State the degradation assumptions before choosing a restorer or interpreting its output.
- Training pairs and degradation synthesis define what the network learns to undo.
- Match resolution paths, receptive fields and normalization to the restoration task.
- Conditioning can help one model handle multiple degradations; test unknown and mixed cases separately.
- Pixel accuracy, perceptual realism and input consistency answer different questions; report more than one.
- Blind restoration may estimate, condition on or implicitly handle degradation; joint estimation can favor degenerate solutions [74].
- Use task-appropriate datasets and treat no-reference scores as fallible quality estimates, not proof of recovered detail.
Exercises
- Degradation order. Using the
degradefunction, compare (a) blur → downsample → noise → JPEG with (b) noise → blur → downsample → JPEG at the same parameters. Visually and with the noise standard deviation measured on a flat patch, explain why the order matters for what the network has to learn.
Hint
In (b), the blur and downsampling filter the noise: its standard deviation drops and it becomes spatially correlated (smooth blotches rather than per-pixel grain). In (a), the noise stays white at the low resolution. A network trained only on (a) will under-remove correlated noise at test time. This is one reason Real-ESRGAN randomizes and repeats the stages.
- Pixel shuffle by hand. A feature tensor has shape with , , and channel is filled with the constant . Write the output of pixel shuffle using the formula in the SR section, then check with
torch.nn.PixelShuffle(2).
Hint
Output pixel takes channel . So every block is , and the output repeats that block four times. Each output block gathers one value from each of the four channels at the same low-resolution position.
- Residual or direct? Modify
TinyDnCNN.forwardto returnself.body(y)(predict the clean image directly) and train both versions with the same seed and steps. Compare PSNR and the loss curves. Then repeat with . When does residual learning help most?
Hint
With few training steps, the residual version usually converges faster and reaches a higher PSNR, because at initialization it already outputs roughly (good PSNR) and only needs to learn a small correction. At low noise the direct version struggles most, since it must learn a near-identity mapping through several ReLU layers.
- Dark channel by numbers. A hazy pixel has , the darkest value of over its patch and channels is , and . With and , compute and the recovered for this pixel.
Hint
. Then , giving about . The output is darker and more saturated than the input, as expected when the veil is removed.
- Perception versus distortion. Take the tiny denoiser’s output and add a small amount of fresh Gaussian noise () to it. Compute PSNR and SSIM before and after. The image may look more natural (less plastic) although both metrics drop. Relate this to the perception–distortion function .
Hint
The MMSE-like output lies at low distortion but far from the natural-image distribution (too smooth). Adding grain moves the output distribution closer to real photos (lower ) at the price of higher MSE: a move along, or toward, the convex bound, not past it.
- Design an all-in-one experiment. You must build a single model for noise (), rain streaks and haze. Describe the training data mix, how you would condition the network (no labels at test time), the baselines you would compare against, and how you would detect task interference.
Hint
Mix datasets per task with balanced sampling; add a degradation encoder (contrastive as in AirNet, or prompts as in PromptIR) trained jointly. Compare with three single-task models of the same backbone and size, and with a version without conditioning. Interference shows up as the all-in-one model falling behind the single-task model on one task while matching it on others; also test on mixed degradations (rain + haze) unseen in training.
- Kernel estimation by hand. In the blind-deconvolution snippet, (a) remove the
shock(...)call and setkeep=1.0(use all gradients) and compare the kernel error and final PSNR; (b) start from a box kernel instead of the near-delta; (c) replaceh_trueby a straight -pixel motion path in a window. Explain each result with the discussion of Levin et al. [74] and the coarse-to-fine strategy.
Hint
(a) With all gradients, the many weak gradients of the smoothed latent image dominate the least-squares fit, and the estimate no longer improves (in our run the kernel error grew instead of shrinking and the final PSNR stayed at the blurry input’s level). Selecting a few strong, well-predicted edges is what makes the kernel step informative, which is the practical answer to the “no-blur” bias of naive joint MAP. (b) The loop is a non-convex alternation, so the start matters; a different start can converge to a different local minimum. (c) A large kernel at full resolution is hard to find from a delta start: in our run the error dropped much less and most of the true-kernel PSNR was not recovered. Estimating the kernel on a downsampled image first (where it is only a few pixels long) and upsampling the result is what the image pyramid is for.
- Validating an NR metric. Five restored images have mean opinion scores and NIQE scores . (a) Compute SRCC by hand and interpret its sign. (b) Would SRCC change if you reported instead? Would PLCC? (c) Run the MSCN snippet on an over-sharpened version of a denoised image and explain why an NSS metric might rate it better than the plain denoised output.
Hint
(a) Ranking from smallest to largest, the MOS ranks of images 1–5 are and the NIQE ranks are . The rank differences are , so and . The sign is negative because lower NIQE means better quality; one reports . Only images 1 and 5 are swapped. (b) SRCC depends only on ranks, so any monotonic transform such as leaves it unchanged; PLCC changes, which is why PLCC is usually computed after a fitted monotonic mapping. (c) Denoising leaves a smooth image whose MSCN statistics resemble mild blur (low variance, peaky histogram). Sharpening restores high-frequency energy and pushes the statistics back toward those of natural images, whether or not the added detail is real.
References
- Shyandram, “Low-Level Vision Task-Image Restoration簡介,” Medium post (in Traditional Chinese), 2023; updated 2026. link
- Z. Chen, Z. Wu, E. Zamfir, K. Zhang, Y. Zhang, R. Timofte et al., “NTIRE 2024 Challenge on Image Super-Resolution (×4): Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2024. arXiv
- Z. Chen, K. Liu, J. Gong, J. Wang, L. Sun et al., “NTIRE 2025 Challenge on Image Super-Resolution (×4): Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2025. arXiv
- X. Wang, L. Xie, C. Dong and Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution with Pure Synthetic Data,” in Proc. IEEE/CVF ICCV Workshops, 2021. arXiv
- E. H. Land and J. J. McCann, “Lightness and Retinex Theory,” Journal of the Optical Society of America, vol. 61, no. 1, pp. 1–11, 1971. doi
- C. Dong, C. C. Loy, K. He and X. Tang, “Image Super-Resolution Using Deep Convolutional Networks,” IEEE TPAMI, 2016 (conference version ECCV 2014). arXiv
- C. Dong, C. C. Loy and X. Tang, “Accelerating the Super-Resolution Convolutional Neural Network,” in Proc. ECCV, 2016. arXiv
- W. Shi, J. Caballero, F. Huszár, J. Totz, A. P. Aitken, R. Bishop, D. Rueckert and Z. Wang, “Real-Time Single Image and Video Super-Resolution Using an Efficient Sub-Pixel Convolutional Neural Network,” in Proc. IEEE CVPR, 2016. arXiv
- A. Odena, V. Dumoulin and C. Olah, “Deconvolution and Checkerboard Artifacts,” Distill, 2016. link
- B. Lim, S. Son, H. Kim, S. Nah and K. M. Lee, “Enhanced Deep Residual Networks for Single Image Super-Resolution,” in Proc. IEEE CVPR Workshops, 2017. arXiv
- Y. Zhang, K. Li, K. Li, L. Wang, B. Zhong and Y. Fu, “Image Super-Resolution Using Very Deep Residual Channel Attention Networks,” in Proc. ECCV, 2018. arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017. arXiv
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, C. C. Loy, Y. Qiao and X. Tang, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018. arXiv
- J. Liang, J. Cao, G. Sun, K. Zhang, L. Van Gool and R. Timofte, “SwinIR: Image Restoration Using Swin Transformer,” in Proc. IEEE/CVF ICCV Workshops, 2021. arXiv
- X. Chen, X. Wang, J. Zhou, Y. Qiao and C. Dong, “Activating More Pixels in Image Super-Resolution Transformer,” in Proc. IEEE/CVF CVPR, 2023. arXiv
- X. Lin, J. He, Z. Chen, Z. Lyu, B. Dai, F. Yu, W. Ouyang, Y. Qiao and C. Dong, “DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior,” arXiv:2308.15070, 2023. arXiv
- F. Yu, J. Gu, Z. Li, J. Hu, X. Kong, X. Wang, J. He, Y. Qiao and C. Dong, “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” in Proc. IEEE/CVF CVPR, 2024. arXiv
- R. Wu, L. Sun, Z. Ma and L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” in Proc. NeurIPS, 2024. arXiv
- E. Agustsson and R. Timofte, “NTIRE 2017 Challenge on Single Image Super-Resolution: Dataset and Study,” in Proc. IEEE CVPR Workshops, 2017. doi
- K. Zhang, W. Zuo, Y. Chen, D. Meng and L. Zhang, “Beyond a Gaussian Denoiser: Residual Learning of Deep CNN for Image Denoising,” IEEE Transactions on Image Processing, vol. 26, no. 7, pp. 3142–3155, 2017. arXiv
- K. Zhang, W. Zuo and L. Zhang, “FFDNet: Toward a Fast and Flexible Solution for CNN-Based Image Denoising,” IEEE Transactions on Image Processing, 2018. arXiv
- A. Abdelhamed, S. Lin and M. S. Brown, “A High-Quality Denoising Dataset for Smartphone Cameras,” in Proc. IEEE/CVF CVPR, 2018. doi
- S. W. Zamir, A. Arora, S. Khan, M. Hayat, F. S. Khan and M.-H. Yang, “Restormer: Efficient Transformer for High-Resolution Image Restoration,” in Proc. IEEE/CVF CVPR, 2022. arXiv
- L. Chen, X. Chu, X. Zhang and J. Sun, “Simple Baselines for Image Restoration,” in Proc. ECCV, 2022. arXiv
- K. He, J. Sun and X. Tang, “Single Image Haze Removal Using Dark Channel Prior,” in Proc. IEEE CVPR, 2009. doi
- B. Cai, X. Xu, K. Jia, C. Qing and D. Tao, “DehazeNet: An End-to-End System for Single Image Haze Removal,” IEEE Transactions on Image Processing, 2016. arXiv
- B. Li, X. Peng, Z. Wang, J. Xu and D. Feng, “AOD-Net: All-in-One Dehazing Network,” in Proc. IEEE ICCV, 2017. doi · arXiv
- X. Liu, Y. Ma, Z. Shi and J. Chen, “GridDehazeNet: Attention-Based Multi-Scale Network for Image Dehazing,” in Proc. IEEE/CVF ICCV, 2019. arXiv
- X. Qin, Z. Wang, Y. Bai, X. Xie and H. Jia, “FFA-Net: Feature Fusion Attention Network for Single Image Dehazing,” in Proc. AAAI, 2020. arXiv
- S. W. Zamir, A. Arora, S. Khan, M. Hayat, F. S. Khan, M.-H. Yang and L. Shao, “Learning Enriched Features for Real Image Restoration and Enhancement,” in Proc. ECCV, 2020. arXiv
- Y. Song, Z. He, H. Qian and X. Du, “Vision Transformers for Single Image Dehazing,” IEEE Transactions on Image Processing, vol. 32, 2023. arXiv
- B. Li, W. Ren, D. Fu, D. Tao, D. Feng, W. Zeng and Z. Wang, “Benchmarking Single-Image Dehazing and Beyond,” IEEE Transactions on Image Processing, 2019. arXiv
- C. O. Ancuti, C. Ancuti, R. Timofte and C. De Vleeschouwer, “O-HAZE: A Dehazing Benchmark with Real Hazy and Haze-Free Outdoor Images,” in Proc. IEEE/CVF CVPR Workshops, 2018. doi
- C. O. Ancuti, C. Ancuti, M. Sbert and R. Timofte, “Dense-Haze: A Benchmark for Image Dehazing with Dense-Haze and Haze-Free Images,” in Proc. IEEE ICIP, 2019. doi
- A. Geiger, P. Lenz and R. Urtasun, “Are We Ready for Autonomous Driving? The KITTI Vision Benchmark Suite,” in Proc. IEEE CVPR, 2012. project page
- Y.-F. Liu, D.-W. Jaw, S.-C. Huang and J.-N. Hwang, “DesnowNet: Context-Aware Deep Network for Snow Removal,” IEEE Transactions on Image Processing, 2018. arXiv
- W.-T. Chen, H.-Y. Fang, J.-J. Ding, C.-C. Tsai and S.-Y. Kuo, “JSTASR: Joint Size and Transparency-Aware Snow Removal Algorithm Based on Modified Partial Convolution and Veiling Effect Removal,” in Proc. ECCV, 2020. doi
- W. Yang, R. T. Tan, J. Feng, J. Liu, Z. Guo and S. Yan, “Deep Joint Rain Detection and Removal from a Single Image,” in Proc. IEEE CVPR, 2017. arXiv
- R. Qian, R. T. Tan, W. Yang, J. Su and J. Liu, “Attentive Generative Adversarial Network for Raindrop Removal from a Single Image,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- X. Li, Y. Jin, X. Jin, Z. Wu, B. Li, Y. Wang et al., “NTIRE 2025 Challenge on Day and Night Raindrop Removal for Dual-Focused Images: Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2025. arXiv
- C. Wei, W. Wang, W. Yang and J. Liu, “Deep Retinex Decomposition for Low-Light Enhancement,” in Proc. BMVC, 2018. arXiv
- Y. Cai, H. Bian, J. Lin, H. Wang, R. Timofte and Y. Zhang, “Retinexformer: One-stage Retinex-based Transformer for Low-light Image Enhancement,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- H. Zhang, H. Xu, X. Tian, J. Jiang and J. Ma, “Image Fusion Meets Deep Learning: A Survey and Perspective,” Information Fusion, vol. 76, pp. 323–336, 2021. doi
- S. Nah, T. H. Kim and K. M. Lee, “Deep Multi-scale Convolutional Neural Network for Dynamic Scene Deblurring,” in Proc. IEEE CVPR, 2017. doi · arXiv
- K. He, X. Chen, S. Xie, Y. Li, P. Dollár and R. Girshick, “Masked Autoencoders Are Scalable Vision Learners,” in Proc. IEEE/CVF CVPR, 2022. arXiv
- R. Suvorov, E. Logacheva, A. Mashikhin, A. Remizova, A. Ashukha, A. Silvestrov, N. Kong, H. Goka, K. Park and V. Lempitsky, “Resolution-robust Large Mask Inpainting with Fourier Convolutions,” in Proc. IEEE/CVF WACV, 2022. arXiv
- S. Sengupta, V. Jayaram, B. Curless, S. Seitz and I. Kemelmacher-Shlizerman, “Background Matting: The World is Your Green Screen,” in Proc. IEEE/CVF CVPR, 2020. arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” in Proc. MICCAI, 2015. arXiv
- H. Guo, J. Li, T. Dai, Z. Ouyang, X. Ren and S.-T. Xia, “MambaIR: A Simple Baseline for Image Restoration with State-Space Model,” in Proc. ECCV, 2024. arXiv
- H. Guo, Y. Guo, Y. Zha, Y. Zhang, W. Li, T. Dai, S.-T. Xia and Y. Li, “MambaIRv2: Attentive State Space Restoration,” in Proc. IEEE/CVF CVPR, 2025. arXiv
- B. Li, X. Liu, P. Hu, Z. Wu, J. Lv and X. Peng, “All-In-One Image Restoration for Unknown Corruption,” in Proc. IEEE/CVF CVPR, 2022. code & paper
- J. M. J. Valanarasu, R. Yasarla and V. M. Patel, “TransWeather: Transformer-based Restoration of Images Degraded by Adverse Weather Conditions,” in Proc. IEEE/CVF CVPR, 2022. arXiv
- V. Potlapalli, S. W. Zamir, S. Khan and F. S. Khan, “PromptIR: Prompting for All-in-One Image Restoration,” in Proc. NeurIPS, 2023. arXiv
- Y. Cui, S. W. Zamir, S. Khan, A. Knoll, M. Shah and F. S. Khan, “AdaIR: Adaptive All-in-One Image Restoration via Frequency Mining and Modulation,” in Proc. ICLR, 2025. arXiv
- Z. Luo, F. K. Gustafsson, Z. Zhao, J. Sjölund and T. B. Schön, “Controlling Vision-Language Models for Multi-Task Image Restoration,” in Proc. ICLR, 2024. arXiv
- M. V. Conde, G. Geigle and R. Timofte, “InstructIR: High-Quality Image Restoration Following Human Instructions,” in Proc. ECCV, 2024. arXiv
- H. Zhao, O. Gallo, I. Frosio and J. Kautz, “Loss Functions for Image Restoration with Neural Networks,” IEEE Transactions on Computational Imaging, 2017 (arXiv title: “Loss Functions for Neural Networks for Image Processing”). arXiv
- J. Johnson, A. Alahi and L. Fei-Fei, “Perceptual Losses for Real-Time Style Transfer and Super-Resolution,” in Proc. ECCV, 2016. doi · arXiv
- L. Jiang, B. Dai, W. Wu and C. C. Loy, “Focal Frequency Loss for Image Reconstruction and Synthesis,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a ‘Completely Blind’ Image Quality Analyzer,” IEEE Signal Processing Letters, 2013. doi
- Y. Blau, R. Mechrez, R. Timofte, T. Michaeli and L. Zelnik-Manor, “The 2018 PIRM Challenge on Perceptual Image Super-resolution,” in Proc. ECCV Workshops, 2018. arXiv
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler and S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” in Proc. NeurIPS, 2017. arXiv
- Y. Blau and T. Michaeli, “The Perception-Distortion Tradeoff,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- Z. Wang, J. Chen and S. C. H. Hoi, “Deep Learning for Image Super-Resolution: A Survey,” IEEE TPAMI, 2021. arXiv
- C. Tian, L. Fei, W. Zheng, Y. Xu, W. Zuo and C.-W. Lin, “Deep Learning on Image Denoising: An Overview,” Neural Networks, vol. 131, pp. 251–275, 2020. arXiv
- M. Elad, B. Kawar and G. Vaksman, “Image Denoising: The Deep Learning Revolution and Beyond — A Survey Paper,” SIAM Journal on Imaging Sciences, vol. 16, no. 3, pp. 1594–1654, 2023. doi · arXiv
- K. Zhang, W. Ren, W. Luo, W.-S. Lai, B. Stenger, M.-H. Yang and H. Li, “Deep Image Deblurring: A Survey,” International Journal of Computer Vision, 2022. arXiv
- J. Gui, X. Cong, Y. Cao, W. Ren, J. Zhang, J. Zhang, J. Cao and D. Tao, “A Comprehensive Survey and Taxonomy on Single Image Dehazing Based on Deep Learning,” ACM Computing Surveys, 2023. doi · arXiv
- W. Yang, R. T. Tan, S. Wang, Y. Fang and J. Liu, “Single Image Deraining: From Model-Based to Data-Driven and Beyond,” IEEE TPAMI, 2021. doi · arXiv
- J. Jiang, Z. Zuo, G. Wu, K. Jiang and X. Liu, “A Survey on All-in-One Image Restoration: Taxonomy, Evaluation and Future Trends,” IEEE TPAMI, 2025. arXiv
- X. Li, Y. Ren, X. Jin, C. Lan, X. Wang, W. Zeng, X. Wang and Z. Chen, “Diffusion Models for Image Restoration and Enhancement: A Comprehensive Survey,” International Journal of Computer Vision, 2025. arXiv
- A. Levin, Y. Weiss, F. Durand and W. T. Freeman, “Understanding and Evaluating Blind Deconvolution Algorithms,” in Proc. IEEE CVPR, 2009, pp. 1964–1971. doi
- R. Fergus, B. Singh, A. Hertzmann, S. T. Roweis and W. T. Freeman, “Removing Camera Shake from a Single Photograph,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 25, no. 3, pp. 787–794, 2006. doi
- Q. Shan, J. Jia and A. Agarwala, “High-quality Motion Deblurring from a Single Image,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 27, no. 3, 2008. doi
- S. Cho and S. Lee, “Fast Motion Deblurring,” ACM Transactions on Graphics (Proc. SIGGRAPH Asia), vol. 28, no. 5, 2009. doi
- L. Xu and J. Jia, “Two-Phase Kernel Estimation for Robust Motion Deblurring,” in Proc. ECCV, 2010, pp. 157–170. doi
- D. Krishnan, T. Tay and R. Fergus, “Blind Deconvolution Using a Normalized Sparsity Measure,” in Proc. IEEE CVPR, 2011, pp. 233–240. doi
- J. Pan, D. Sun, H. Pfister and M.-H. Yang, “Blind Image Deblurring Using Dark Channel Prior,” in Proc. IEEE CVPR, 2016, pp. 1628–1636. doi
- J. Sun, W. Cao, Z. Xu and J. Ponce, “Learning a Convolutional Neural Network for Non-uniform Motion Blur Removal,” in Proc. IEEE CVPR, 2015. arXiv
- C. J. Schuler, M. Hirsch, S. Harmeling and B. Schölkopf, “Learning to Deblur,” IEEE TPAMI, vol. 38, no. 7, pp. 1439–1451, 2016. doi · arXiv
- A. Chakrabarti, “A Neural Approach to Blind Motion Deblurring,” in Proc. ECCV, 2016. arXiv
- D. Ulyanov, A. Vedaldi and V. Lempitsky, “Deep Image Prior,” in Proc. IEEE/CVF CVPR, 2018, pp. 9446–9454. doi · arXiv
- D. Ren, K. Zhang, Q. Wang, Q. Hu and W. Zuo, “Neural Blind Deconvolution Using Deep Priors,” in Proc. IEEE/CVF CVPR, 2020. arXiv
- O. Kupyn, V. Budzan, M. Mykhailych, D. Mishkin and J. Matas, “DeblurGAN: Blind Motion Deblurring Using Conditional Adversarial Networks,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- K. Zhang, W. Zuo and L. Zhang, “Learning a Single Convolutional Super-Resolution Network for Multiple Degradations,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- J. Gu, H. Lu, W. Zuo and C. Dong, “Blind Super-Resolution With Iterative Kernel Correction,” in Proc. IEEE/CVF CVPR, 2019. arXiv
- S. Bell-Kligler, A. Shocher and M. Irani, “Blind Super-Resolution Kernel Estimation using an Internal-GAN,” in Proc. NeurIPS, 2019. link · arXiv
- Z. Luo, Y. Huang, S. Li, L. Wang and T. Tan, “Unfolding the Alternating Optimization for Blind Super Resolution,” in Proc. NeurIPS, 2020. arXiv
- K. Zhang, L. Van Gool and R. Timofte, “Deep Unfolding Network for Image Super-Resolution,” in Proc. IEEE/CVF CVPR, 2020. arXiv
- K. Zhang, J. Liang, L. Van Gool and R. Timofte, “Designing a Practical Degradation Model for Deep Blind Image Super-Resolution,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- A. Liu, Y. Liu, J. Gu, Y. Qiao and C. Dong, “Blind Image Super-Resolution: A Survey and Beyond,” IEEE TPAMI, 2022 (early access). doi · arXiv
- A. Mittal, A. K. Moorthy and A. C. Bovik, “No-Reference Image Quality Assessment in the Spatial Domain,” IEEE Transactions on Image Processing, vol. 21, no. 12, pp. 4695–4708, 2012. doi
- C. Ma, C.-Y. Yang, X. Yang and M.-H. Yang, “Learning a No-Reference Quality Metric for Single-Image Super-Resolution,” Computer Vision and Image Understanding, vol. 158, pp. 1–16, 2017. doi · arXiv
- N. Venkatanath, D. Praneeth, M. C. Bh, S. S. Channappayya and S. S. Medasani, “Blind Image Quality Evaluation Using Perception Based Features,” in Proc. Twenty First National Conference on Communications (NCC), 2015, pp. 1–6. doi · MATLAB documentation
- H. Talebi and P. Milanfar, “NIMA: Neural Image Assessment,” IEEE Transactions on Image Processing, vol. 27, no. 8, pp. 3998–4011, 2018. doi · arXiv
- S. Su, Q. Yan, Y. Zhu, C. Zhang, X. Ge, J. Sun and Y. Zhang, “Blindly Assess Image Quality in the Wild Guided by a Self-Adaptive Hyper Network,” in Proc. IEEE/CVF CVPR, 2020, pp. 3664–3673. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar and F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” in Proc. IEEE/CVF ICCV, 2021, pp. 5128–5137. doi · arXiv
- S. Yang, T. Wu, S. Shi, S. Lao, Y. Gong, M. Cao, J. Wang and Y. Yang, “MANIQA: Multi-dimension Attention Network for No-Reference Image Quality Assessment,” in Proc. IEEE/CVF CVPR Workshops, 2022, pp. 1190–1199. doi · arXiv
- C. Chen, J. Mo, J. Hou, H. Wu, L. Liao, W. Sun, Q. Yan and W. Lin, “TOPIQ: A Top-Down Approach From Semantics to Distortions for Image Quality Assessment,” IEEE Transactions on Image Processing, vol. 33, pp. 2404–2418, 2024. doi · arXiv
- J. Wang, K. C. K. Chan and C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” in Proc. AAAI Conference on Artificial Intelligence, 2023. arXiv
- H. Wu, Z. Zhang, W. Zhang, C. Chen, L. Liao, C. Li, Y. Gao, A. Wang, E. Zhang, W. Sun, Q. Yan, X. Min, G. Zhai and W. Lin, “Q-Align: Teaching LMMs for Visual Scoring via Discrete Text-Defined Levels,” in Proc. ICML, PMLR 235, pp. 54015–54029, 2024. link · arXiv
- H. R. Sheikh, M. F. Sabir and A. C. Bovik, “A Statistical Evaluation of Recent Full Reference Image Quality Assessment Algorithms,” IEEE Transactions on Image Processing, vol. 15, no. 11, pp. 3440–3451, 2006 (LIVE Image Quality Assessment Database). doi · database
- N. Ponomarenko, L. Jin, O. Ieremeiev, V. Lukin, K. Egiazarian, J. Astola, B. Vozel, K. Chehdi, M. Carli, F. Battisti and C.-C. J. Kuo, “Image Database TID2013: Peculiarities, Results and Perspectives,” Signal Processing: Image Communication, vol. 30, pp. 57–77, 2015. doi · database
- H. Lin, V. Hosu and D. Saupe, “KADID-10k: A Large-scale Artificially Distorted IQA Database,” in Proc. Eleventh International Conference on Quality of Multimedia Experience (QoMEX), 2019. doi · database
- V. Hosu, H. Lin, T. Sziranyi and D. Saupe, “KonIQ-10k: An Ecologically Valid Database for Deep Learning of Blind Image Quality Assessment,” IEEE Transactions on Image Processing, vol. 29, pp. 4041–4056, 2020. arXiv
- Y. Fang, H. Zhu, Y. Zeng, K. Ma and Z. Wang, “Perceptual Quality Assessment of Smartphone Photography,” in Proc. IEEE/CVF CVPR, 2020, pp. 3674–3683. doi
- J. Gu, H. Cai, H. Chen, X. Ye, J. Ren and C. Dong, “PIPAL: A Large-Scale Image Quality Assessment Dataset for Perceptual Image Restoration,” in Proc. ECCV, 2020. arXiv
- C. Chen and J. Mo, “IQA-PyTorch: PyTorch Toolbox for Image Quality Assessment,” software (pip package
pyiqa), 2022. GitHub - ITU-R, “Recommendation BT.500-15: Methodologies for the Subjective Assessment of the Quality of Television Images,” 2023. ITU
- R. A. Bradley and M. E. Terry, “Rank Analysis of Incomplete Block Designs: The Method of Paired Comparisons,” Biometrika, vol. 39, no. 3–4, pp. 324–345, 1952. doi
- D. Geman and C. Yang, “Nonlinear Image Recovery with Half-Quadratic Regularization,” IEEE Transactions on Image Processing, vol. 4, no. 7, pp. 932–946, 1995. doi
- S. V. Venkatakrishnan, C. A. Bouman and B. Wohlberg, “Plug-and-Play Priors for Model Based Reconstruction,” in Proc. IEEE Global Conference on Signal and Information Processing (GlobalSIP), 2013, pp. 945–948. doi
- K. Zhang, W. Zuo, S. Gu and L. Zhang, “Learning Deep CNN Denoiser Prior for Image Restoration,” in Proc. IEEE/CVF CVPR, 2017, pp. 2808–2817. doi · arXiv
- A. Chambolle, “An Algorithm for Total Variation Minimization and Applications,” Journal of Mathematical Imaging and Vision, vol. 20, no. 1–2, pp. 89–97, 2004. doi
- A. Buades, B. Coll and J.-M. Morel, “A Non-Local Algorithm for Image Denoising,” in Proc. IEEE CVPR, vol. 2, 2005, pp. 60–65. doi
- D. Ulyanov, A. Vedaldi and V. Lempitsky, “Deep Image Prior,” International Journal of Computer Vision, vol. 128, no. 7, pp. 1867–1888, 2020. doi · arXiv
- Y. Jiang, Z. Zhang, T. Xue and J. Gu, “AutoDIR: Automatic All-in-One Image Restoration with Latent Diffusion,” in Proc. ECCV, 2024. paper
- K. Zhu, J. Gu, Z. You, Y. Qiao and C. Dong, “An Intelligent Agentic System for Complex Image Restoration Problems,” in Proc. ICLR, 2025. paper
- Y. Zuo, Q. Zheng, M. Wu, X. Jiang, R. Li, J. Wang, Y. Zhang, G. Mai, L. V. Wang, J. Zou, X. Wang, M.-H. Yang and Z. Tu, “4KAgent: Agentic Any Image to 4K Super-Resolution,” in Proc. NeurIPS, 2025. paper
- Y. Yu, Z. Zeng, H. Hua, J. Fu and J. Luo, “PromptFix: You Prompt and We Fix the Photo,” in Proc. NeurIPS, 2024. paper
Check your understanding
This tutorial has 8 exercises. Can you solve them without opening the hints?
Go to the exercises ↑Next DLCV 09A · Non-Blind Image Super-Resolution · 44 min