YOLOv10: NMS-free training with dual assignments
Optional · paper guide 13 of 22 for DLCV 03A · One-Stage Detection, Read Through YOLOv4. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- YOLO v1: detection as a single regression
- YOLOv2 and YOLO9000: anchors, priors and joint training
- YOLOv3: three scales and Darknet-53
- SSD: multi-scale default boxes
- RetinaNet and the focal loss
- FCOS: per-pixel anchor-free detection
- CenterNet: objects as points
- YOLOR: explicit features and learned implicit representations
- YOLOX: anchor-free YOLO with SimOTA
- YOLOv6: a re-parameterized industrial detector
- YOLOv7: a trainable bag of freebies
- YOLOv9: programmable gradient information
- YOLOv10: NMS-free training with dual assignments
- YOLOv12: an attention-centric YOLO
- YOLOv13: hypergraph correlation
- YOLO26: a DFL-free end-to-end YOLO
- RT-DETR: a real-time DETR
- RT-DETRv2: a bag of freebies for RT-DETR
- D-FINE: boxes as refined distributions
- DEIM: dense one-to-one matching
- RF-DETR: architecture search on a DINOv2 backbone
- DEIMv2: DINOv3 features for real-time DETRs
Deep Learning for Computer Vision
Paper: A. Wang, H. Chen, L. Liu, K. Chen, Z. Lin, J. Han and G. Ding, “YOLOv10: Real-time end-to-end object detection,” NeurIPS 2024 [17]. Related part of YOLOv4: label assignment and post-processing.
Challenge
YOLOs are trained with one-to-many assignment (YOLOv4’s several anchors per object is one form), so several predictions fire on each object and NMS must remove the duplicates; NMS adds latency, depends on thresholds and requires an extra post-processing stage [17]. One-to-one assignment, as in DETR [59], removes NMS but gives weak supervision, which slows convergence and lowers accuracy. Separately, the paper argues that YOLO architectures had accumulated computational redundancy without a holistic efficiency and accuracy design [17].
Method
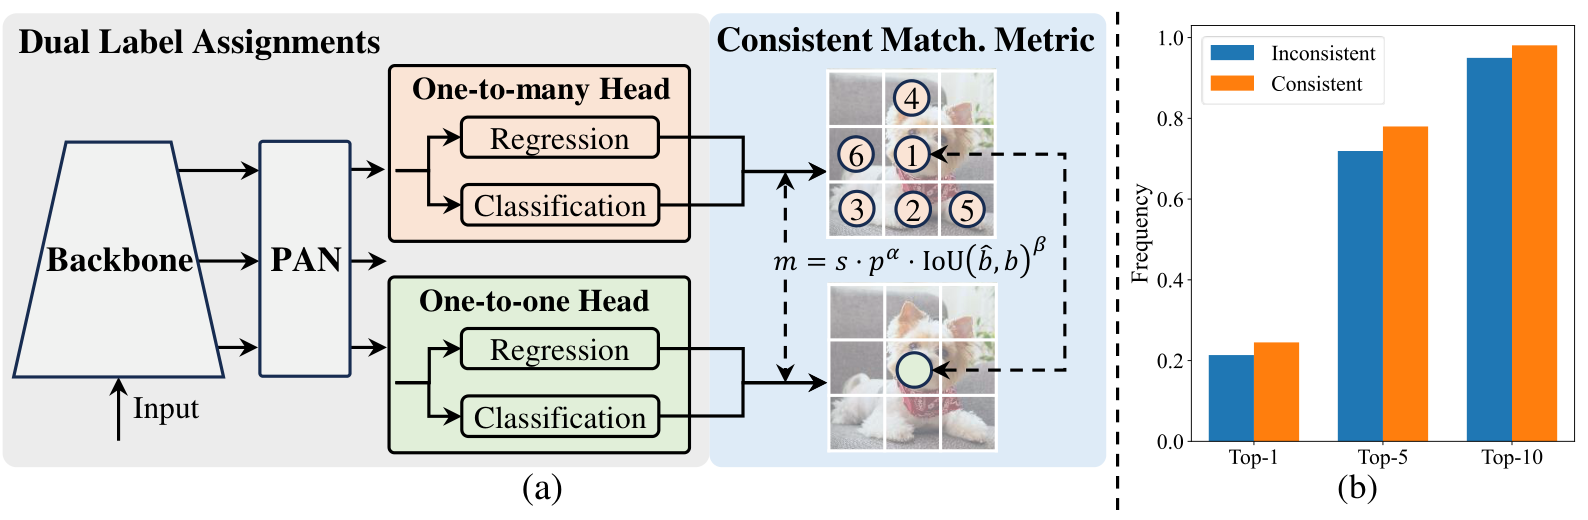
Figure source: [17], arXiv:2405.14458v2, PDF page 4. Original PDF.
Dual label assignments. A second head with the same structure as the usual one-to-many head is added and trained with one-to-one assignment. Both share the backbone and neck, which therefore receive the rich one-to-many supervision; at inference only the one-to-one head is used, so no NMS is needed [17]. The one-to-one match is chosen by “top one selection”, which the paper reports performs as well as Hungarian matching [60] with less training time [17].
Consistent matching metric. Both heads rank predictions with the task-aligned metric
where is the classification score for the object’s class, and are the predicted and true boxes, is a spatial prior that is 1 if the prediction’s anchor point lies inside the object and 0 otherwise, and balance classification against localization [17]; YOLOv8-S uses , by default [17]. The paper derives the supervision gap between the heads. For an object with largest IoU among the predictions, let be the one-to-many positives and the one-to-one match; with task-aligned classification targets and , the 1-Wasserstein distance between the two classification objectives is
where is the indicator function [17]. The gap is smallest when is the best positive of the one-to-many head, which holds when and (then , and both heads rank predictions in the same order); the paper uses [17].
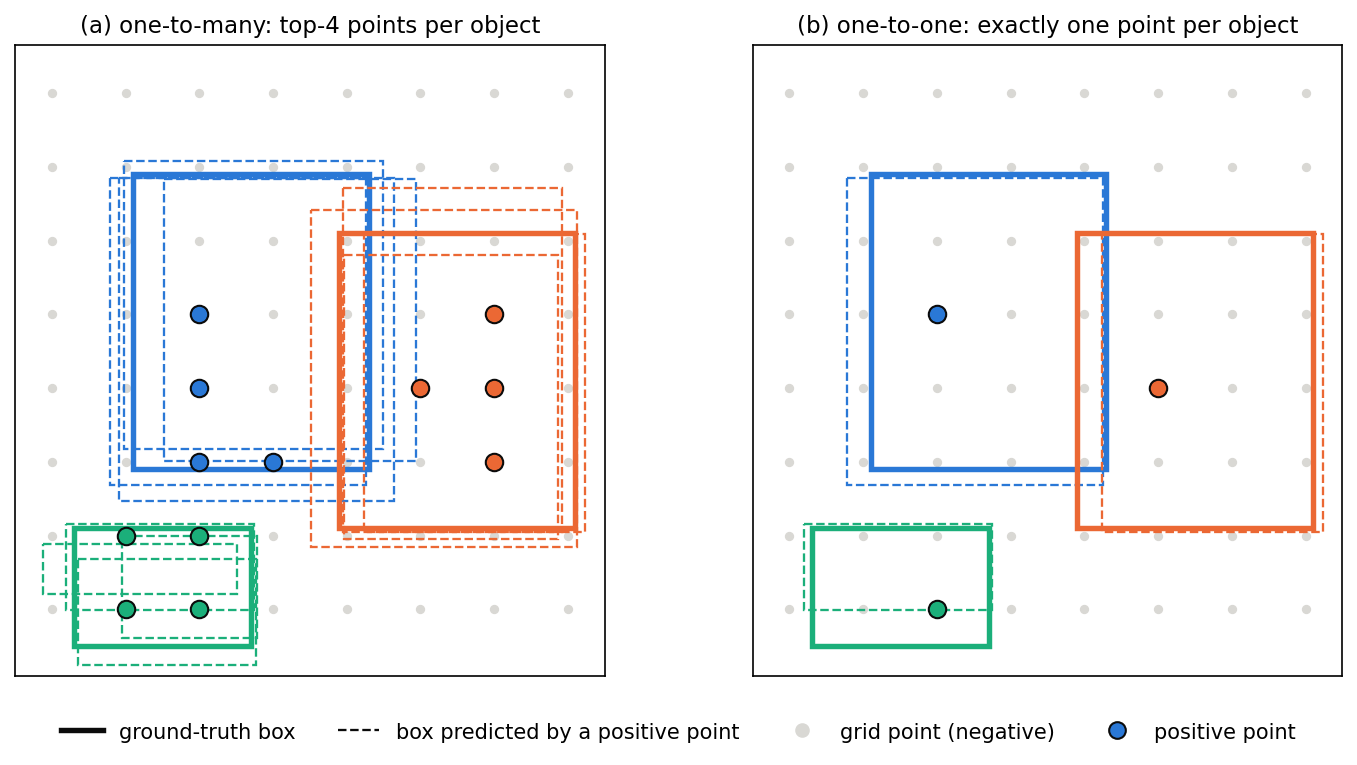
The toy snippet places an grid of anchor points on a image with three objects, computes with these defaults, and compares top-4 one-to-many assignment with Hungarian one-to-one assignment.
Code · Python · 38 lines
import numpy as np
from scipy.optimize import linear_sum_assignment

def iou_matrix(a, b):
    x1 = np.maximum(a[:, None, 0], b[None, :, 0]); y1 = np.maximum(a[:, None, 1], b[None, :, 1])
    x2 = np.minimum(a[:, None, 2], b[None, :, 2]); y2 = np.minimum(a[:, None, 3], b[None, :, 3])
    inter = np.clip(x2 - x1, 0, None) * np.clip(y2 - y1, 0, None)
    area = lambda b: (b[:, 2] - b[:, 0]) * (b[:, 3] - b[:, 1])
    return inter / (area(a)[:, None] + area(b)[None, :] - inter)

rng = np.random.default_rng(3)
gt = np.array([[20, 20, 60, 70], [55, 30, 95, 80], [10, 80, 40, 100]], float)
# 8 x 8 grid of anchor points (stride 12.5 on a 100 x 100 image), each with a predicted box
ys, xs = np.mgrid[0:8, 0:8]
pts = np.stack([(xs.ravel() + 0.5) * 12.5, (ys.ravel() + 0.5) * 12.5], axis=1)
inside = ((pts[:, None, 0] > gt[None, :, 0]) & (pts[:, None, 0] < gt[None, :, 2]) &
          (pts[:, None, 1] > gt[None, :, 1]) & (pts[:, None, 1] < gt[None, :, 3]))      # spatial prior s
near = inside.argmax(axis=1)                       # the object each point "looks at"
pred = gt[near] + rng.normal(0, 5, (len(pts), 4))  # noisy box predictions
p = np.where(inside.any(axis=1), rng.uniform(0.3, 0.9, len(pts)), rng.uniform(0, 0.2, len(pts)))

alpha, beta = 0.5, 6.0                             # the defaults quoted in the YOLOv10 paper
m = inside * p[:, None] ** alpha * iou_matrix(pred, gt) ** beta   # (points, objects)

# one-to-many: the top-k points by m for every object become positives
k = 4
o2m = {}
for j in range(len(gt)):
    best = np.argsort(-m[:, j])[:k]
    o2m[j] = best[m[best, j] > 0].tolist()
# one-to-one: Hungarian matching on cost -m (each object gets exactly one point)
rows, cols = linear_sum_assignment(-m)
o2o = {int(c): [int(r)] for r, c in zip(rows, cols)}
print("one-to-many positives:", o2m)
print("one-to-one positives: ", dict(sorted(o2o.items())))
print("positives per image: o2m", sum(map(len, o2m.values())), "| o2o", len(o2o))
top1 = m.argmax(axis=0)                            # YOLOv10's cheaper top-1 choice
print("top-1 equals Hungarian here:", all(top1[j] == o2o[j][0] for j in o2o))
Output
one-to-many positives: {0: [26, 34, 42, 43], 1: [37, 46, 38, 30], 2: [58, 50, 49, 57]}
one-to-one positives:  {0: [26], 1: [37], 2: [58]}
positives per image: o2m 12 | o2o 3
top-1 equals Hungarian here: True
One-to-many gives four times as many positives, and Figure 5 shows their cost: four overlapping boxes per object, all taught to fire. One-to-one keeps the single best point per object, which is also the top-ranked point under one-to-many, the property the consistent metric is designed to guarantee. The cheap per-object top-1 choice agrees with Hungarian matching here because no two objects compete for the same point. This agreement is specific to the toy inputs: competing targets require conflict resolution, and global matching need not equal independent top-1 selection.
Efficiency-driven design. Three changes reduce computation [17]: a lightweight classification head (two depthwise-separable convolutions and a convolution), justified by an analysis showing that regression errors matter more than classification errors; spatial–channel decoupled downsampling, a pointwise convolution that changes the channels followed by a depthwise stride-2 convolution, instead of one stride-2 convolution, which lowers the cost from to ; and a rank-guided block design, which measures the numerical rank of each stage’s last convolution (the number of singular values above half the largest), sorts stages from most redundant to least, and replaces their blocks with a cheaper compact inverted block (CIB) as long as accuracy does not drop.
Accuracy-driven design. Large-kernel () depthwise convolutions in the CIBs of deep stages, re-parameterized with an extra branch, for small models only; and partial self-attention (PSA), which splits the channels in two after a convolution, applies multi-head self-attention and a feed-forward network to one half only, and is placed once after the lowest-resolution stage [17].
Results
Latency is end to end on a T4 GPU with TensorRT FP16, at batch 1, averaged over COCO val, with TensorRT’s efficient-NMS plugin appended for models that need NMS and I/O excluded [17]. YOLOv10-S reaches 46.3% AP at 2.49 ms, against 44.9% at 7.07 ms for YOLOv8-S and 46.5% at 4.58 ms for RT-DETR-R18; YOLOv10-X reaches 54.4% AP at 10.70 ms, against 54.3% at 13.71 ms for RT-DETR-R101; YOLOv10-B matches YOLOv9-C’s 52.5% AP at 5.74 ms instead of 10.57 ms [17]. The table also reports a forward-only latency () for comparisons without post-processing; do not mix the two columns.
Ablations
On COCO val [17]:
- NMS-free and the architecture (Table 2): YOLOv10-S goes from 44.9% AP at 7.07 ms (YOLOv8-S with NMS) to 44.3% at 2.44 ms (NMS-free), 44.5% at 2.31 ms (+ efficiency design) and 46.3% at 2.49 ms (+ accuracy design).
- Dual assignments (Table 3): one-to-many only, 44.9% AP at 7.07 ms; one-to-one only, 43.4% at 2.44 ms; both heads, 44.3% at 2.44 ms. The latency difference is NMS; the accuracy price of NMS-free inference is 0.6 AP.
- Matching metric (Table 4, with , ): the consistent setting gives 44.3%; inconsistent settings such as give as little as 42.7%; and the proportional settings and , which the theory predicts to be equally consistent, also reach 44.3%.
- Efficiency components (Table 5): the lighter classification head, the decoupled downsampling and the rank-guided blocks reduce YOLOv10-S from 11.2 M to 6.2 M parameters and 2.44 to 2.31 ms while AP stays between 44.2% and 44.5%.
Conclusion
YOLOv10 brings NMS-free inference to YOLOs without giving up their dense training signal: a second, one-to-one head trained with a metric consistent with the one-to-many head. Combined with a careful efficiency and accuracy redesign, it cuts end-to-end latency substantially at equal accuracy.
Problems
The NMS-free head is 0.6 AP below the NMS-based one in its own ablation; the two heads receive equal loss weights throughout training; the box head still uses the distribution focal loss of its YOLOv8 base; and the ablations are single runs. YOLO26 adds a progressive loss weighting toward the one-to-one head and removes the distribution head; DEIM attacks the same weak one-to-one supervision from the DETR side.
References
- C.-Y. Wang, A. Bochkovskiy and H.-Y. M. Liao, “YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” in Proc. IEEE/CVF CVPR, pp. 7464–7475, 2023. doi
- C.-Y. Wang, I-H. Yeh and H.-Y. M. Liao, “YOLOv9: Learning what you want to learn using programmable gradient information,” in Proc. ECCV, 2024. doi
- G. Jocher, “Ultralytics YOLOv5,” software (first released 2020; v7.0 released 22 November 2022). release · documentation
- G. Jocher, A. Chaurasia and J. Qiu, “Ultralytics YOLOv8,” software, version 8.0.0, 2023 (no paper). docs · code
- G. Jocher and J. Qiu, “Ultralytics YOLO11,” software, version 11.0.0, 2024 (no paper). docs · code
- J. Lu, J. Jia, J. Yawl and C. Zhang, “YOLOv14: Adaptive real-time object detection for diverse imaging conditions,” arXiv:2608.04720, 2026 (withdrawn by the authors, 20 August 2026). arXiv
- J. Redmon, S. Divvala, R. Girshick and A. Farhadi, “You only look once: Unified, real-time object detection,” in Proc. IEEE CVPR, pp. 779–788, 2016. doi · arXiv
- J. Redmon and A. Farhadi, “YOLO9000: Better, faster, stronger,” in Proc. IEEE CVPR, pp. 6517–6525, 2017. doi · arXiv
- J. Redmon and A. Farhadi, “YOLOv3: An incremental improvement,” tech. report, arXiv:1804.02767, 2018. arXiv
- W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C. Fu, A. C. Berg, “SSD: Single Shot MultiBox Detector,” Lecture Notes in Computer Science / Computer Vision – ECCV 2016, 2016. doi · manuscript
- T.-Y. Lin, P. Goyal, R. Girshick, K. He and P. Dollár, “Focal loss for dense object detection,” in Proc. IEEE ICCV, pp. 2999–3007, 2017. doi
- Z. Tian, C. Shen, H. Chen, T. He, “FCOS: Fully Convolutional One-Stage Object Detection,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- X. Zhou, D. Wang, P. Krähenbühl, “Objects as Points,” arXiv preprint, 2019. source
- C. Wang, I. Yeh, H. M. Liao, “You Only Learn One Representation: Unified Network for Multiple Tasks,” arXiv preprint, 2021. source
- Z. Ge, S. Liu, F. Wang, Z. Li and J. Sun, “YOLOX: Exceeding YOLO series in 2021,” arXiv:2107.08430, 2021. arXiv
- C. Li, L. Li, H. Jiang, K. Weng, Y. Geng et al., “YOLOv6: A single-stage object detection framework for industrial applications,” tech. report, arXiv:2209.02976, 2022. arXiv
- A. Wang, H. Chen, L. Liu, K. Chen, Z. Lin, J. Han and G. Ding, “YOLOv10: Real-time end-to-end object detection,” in Proc. NeurIPS, 2024. arXiv
- Y. Tian, Q. Ye and D. Doermann, “YOLOv12: Attention-centric real-time object detectors,” in Advances in Neural Information Processing Systems 38 (NeurIPS), 2025. proceedings · arXiv
- M. Lei, S. Li, Y. Wu, H. Hu, Y. Zhou et al., “YOLOv13: Real-time object detection with hypergraph-enhanced adaptive visual perception,” arXiv:2506.17733, 2025. arXiv
- G. Jocher, J. Qiu, M. Liu, S. Lyu, F. C. Akyon and M. E. Kalfaoglu, “Ultralytics YOLO26: Unified real-time end-to-end vision models,” arXiv:2606.03748, 2026 (software released January 2026). arXiv · docs
- Y. Zhao, W. Lv, S. Xu, J. Wei, G. Wang, Q. Dang, Y. Liu, J. Chen, “DETRs Beat YOLOs on Real-time Object Detection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source
- W. Lv, Y. Zhao, Q. Chang, K. Huang, G. Wang and Y. Liu, “RT-DETRv2: Improved baseline with bag-of-freebies for real-time detection transformer,” arXiv:2407.17140, 2024. arXiv
- Y. Peng, H. Li, P. Wu, Y. Zhang, X. Sun and F. Wu, “D-FINE: Redefine regression task in DETRs as fine-grained distribution refinement,” in Proc. ICLR, 2025. arXiv · code
- S. Huang, Z. Lu, X. Cun, Y. Yu, X. Zhou, X. Shen, “DEIM: DETR with Improved Matching for Fast Convergence,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025. source
- I. Robinson, P. Robicheaux, M. Popov, D. Ramanan and N. Peri, “RF-DETR: Neural architecture search for real-time detection transformers,” in Proc. ICLR, 2026. arXiv
- S. Huang, Y. Hou, L. Liu, X. Yu and X. Shen, “Real-time object detection meets DINOv3,” arXiv:2509.20787, 2025 (revised 2026). arXiv
- A. Bochkovskiy, C.-Y. Wang and H.-Y. M. Liao, “YOLOv4: Optimal speed and accuracy of object detection,” arXiv:2004.10934, 2020. arXiv
- M. Tan, R. Pang, Q. V. Le, “EfficientDet: Scalable and Efficient Object Detection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- NVIDIA, “TensorRT documentation,” official documentation. link
- J. Deng, W. Dong, R. Socher, L. Li, Kai Li, Li Fei-Fei, “ImageNet: A large-scale hierarchical image database,” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 2009. source
- K. Simonyan, A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” arXiv preprint, 2014. source
- K. He, X. Zhang, S. Ren, J. Sun, “Deep Residual Learning for Image Recognition,” arXiv preprint, 2015. source
- T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE CVPR, 2017. doi
- S. Liu, L. Qi, H. Qin, J. Shi and J. Jia, “Path aggregation network for instance segmentation,” in Proc. IEEE/CVF CVPR, pp. 8759–8768, 2018. doi
- K. He, X. Zhang, S. Ren, J. Sun, “Spatial Pyramid Pooling in Deep Convolutional Networks for Visual Recognition,” Lecture Notes in Computer Science / Computer Vision – ECCV 2014, 2014. doi · manuscript
- C.-Y. Wang, H.-Y. M. Liao, I-H. Yeh, Y.-H. Wu, P.-Y. Chen and J.-W. Hsieh, “CSPNet: A new backbone that can enhance learning capability of CNN,” CVPR Workshops, 2020. arXiv · doi
- A. Bochkovskiy and contributors, “Darknet: YOLOv4 configuration and detection layer,” official implementation, accessed 2 November 2026. configuration · assignment and decoding
- M. Tan, Q. V. Le, “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks,” ICML, 2019. source · proceedings
- G. Huang, Z. Liu, L. Van Der Maaten, K. Q. Weinberger, “Densely Connected Convolutional Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- S. Xie, R. Girshick, P. Dollar, Z. Tu, K. He, “Aggregated Residual Transformations for Deep Neural Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- D. Misra, “Mish: A Self Regularized Non-Monotonic Activation Function,” BMVC, 2020. source
- P. Ramachandran, B. Zoph, Q. V. Le, “Searching for Activation Functions,” arXiv preprint, 2017. source
- J. Yu, Y. Jiang, Z. Wang, Z. Cao, T. Huang, “UnitBox: An Advanced Object Detection Network,” ACM Multimedia, 2016. source
- H. Rezatofighi, N. Tsoi, J. Gwak, A. Sadeghian, I. Reid, S. Savarese, “Generalized Intersection over Union: A Metric and A Loss for Bounding Box Regression,” arXiv preprint, 2019. source
- Z. Zheng, P. Wang, W. Liu, J. Li, R. Ye and D. Ren, “Distance-IoU loss: Faster and better learning for bounding box regression,” in Proc. AAAI, pp. 12993–13000, 2020. doi
- H. Zhang, M. Cisse, Y. N. Dauphin and D. Lopez-Paz, “mixup: Beyond empirical risk minimization,” in Proc. ICLR, 2018. arXiv
- S. Yun, D. Han, S. Chun, S. J. Oh, Y. Yoo, J. Choe, “CutMix: Regularization Strategy to Train Strong Classifiers With Localizable Features,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, Ruslan Salakhutdinov, “Dropout: A Simple Way to Prevent Neural Networks from Overfitting,” Journal of Machine Learning Research, 2014. source
- G. Ghiasi, T. Lin, Q. V. Le, “DropBlock: A regularization method for convolutional networks,” NeurIPS, 2018. source · proceedings
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- S. Ioffe and C. Szegedy, “Batch normalization: Accelerating deep network training by reducing internal covariate shift,” in Proc. ICML, PMLR vol. 37, pp. 448–456, 2015. link
- Z. Yao, Y. Cao, S. Zheng, G. Huang, S. Lin, “Cross-Iteration Batch Normalization,” 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021. doi · manuscript
- S. Woo, J. Park, J. Lee, I. S. Kweon, “CBAM: Convolutional Block Attention Module,” Lecture Notes in Computer Science / Computer Vision – ECCV 2018, 2018. doi · manuscript
- I. Loshchilov, F. Hutter, “SGDR: Stochastic Gradient Descent with Warm Restarts,” ICLR, 2017. source
- T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár and C. L. Zitnick, “Microsoft COCO: Common objects in context,” in Proc. ECCV, pp. 740–755, 2014. doi
- COCO Consortium, “COCO detection evaluation,” official evaluation description. link
- ONNX, “Open Neural Network Exchange,” official project page. link
- B. Jacob, S. Kligys, B. Chen, M. Zhu, M. Tang, A. Howard, H. Adam and D. Kalenichenko, “Quantization and training of neural networks for efficient integer-arithmetic-only inference,” in Proc. IEEE/CVF CVPR, pp. 2704–2713, 2018. doi
- N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. ECCV, 2020. doi
- H. W. Kuhn, “The Hungarian method for the assignment problem,” Naval Research Logistics Quarterly, vol. 2, pp. 83–97, 1955. doi
- J. Terven, D.-M. Córdova-Esparza and J.-A. Romero-González, “A comprehensive review of YOLO architectures in computer vision: From YOLOv1 to YOLOv8 and YOLO-NAS,” Machine Learning and Knowledge Extraction, vol. 5, no. 4, pp. 1680–1716, 2023. doi · arXiv
- N. Jegham, C. Y. Koh, M. Abdelatti and A. Hendawi, “YOLO evolution: A comprehensive benchmark and architectural review of YOLOv12, YOLO11, and their previous versions,” arXiv:2411.00201, 2024 (revised 2025). arXiv
- R. Sapkota and M. Karkee, “Ultralytics YOLO evolution: An overview of YOLO27, YOLO26, YOLO11, YOLOv8, and YOLOv5 object detectors for computer vision and pattern recognition,” arXiv:2510.09653, 2025 (revised 2026). arXiv
- T. Shehzadi, K. A. Hashmi, M. Liwicki, D. Stricker and M. Z. Afzal, “Object detection with transformers: A review,” Sensors, vol. 25, no. 19, 2025. doi
- Ultralytics, “YOLO27 (coming soon),” official documentation page, accessed 2 November 2026. docs
- M. Oquab, T. Darcet, T. Moutakanni, H. Vo, M. Szafraniec et al., “DINOv2: Learning robust visual features without supervision,” arXiv:2304.07193, 2023. arXiv
- O. Siméoni, H. V. Vo, M. Seitzer, F. Baldassarre, M. Oquab et al., “DINOv3,” arXiv:2508.10104, 2025. arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, pp. 13728–13737, 2021. doi
- R. Girshick, “Fast R-CNN,” 2015 IEEE International Conference on Computer Vision (ICCV), 2015. doi · manuscript
- S. Ren, K. He, R. Girshick, J. Sun, “Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks,” arXiv preprint, 2015. source
- M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, A. Zisserman, “The Pascal Visual Object Classes (VOC) Challenge,” International Journal of Computer Vision, 2009. source
- A. Shrivastava, A. Gupta, R. Girshick, “Training Region-Based Object Detectors with Online Hard Example Mining,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- H. Zhang, Y. Wang, F. Dayoub and N. Sünderhauf, “VarifocalNet: An IoU-aware dense object detector,” in Proc. IEEE/CVF CVPR, pp. 8510–8519, 2021. doi
- YOLOX contributors, “YOLOX detection head,” official implementation, accessed 2 November 2026. code
- K. Duan, S. Bai, L. Xie, H. Qi, Q. Huang, Q. Tian, “CenterNet: Keypoint Triplets for Object Detection,” arXiv preprint, 2019. source
- Z. Ge, S. Liu, Z. Li, O. Yoshie and J. Sun, “OTA: Optimal transport assignment for object detection,” in Proc. IEEE/CVF CVPR, pp. 303–312, 2021. doi
- C. Li, L. Li, Y. Geng, et al., “YOLOv6 v3.0: A Full-Scale Reloading,” arXiv preprint, 2023. source
- C. Feng, Y. Zhong, Y. Gao, M. R. Scott, W. Huang, “TOOD: Task-Aligned One-Stage Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- Z. Gevorgyan, “SIoU Loss: More Powerful Learning for Bounding Box Regression,” arXiv preprint, 2022. source
- X. Li, W. Wang, L. Wu, S. Chen, X. Hu, J. Li, J. Tang and J. Yang, “Generalized focal loss: Learning qualified and distributed bounding boxes for dense object detection,” in Advances in Neural Information Processing Systems 33 (NeurIPS), 2020. proceedings
- X. Ding, H. Chen, X. Zhang, K. Huang, J. Han, G. Ding, “Re-parameterizing Your Optimizers rather than Architectures,” ICLR, 2023. source
- S. Zhang, C. Chi, Y. Yao, Z. Lei, S. Z. Li, “Bridging the Gap Between Anchor-Based and Anchor-Free Detection via Adaptive Training Sample Selection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- C. Wang, H. M. Liao, I. Yeh, “Designing Network Design Strategies Through Gradient Path Analysis,” arXiv preprint, 2022. source
- T. Dao, D. Fu, S. Ermon, A. Rudra, C. Ré, “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness,” Advances in Neural Information Processing Systems 35, 2022. doi · manuscript
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- K. Jordan, “Muon: An optimizer for hidden layers in neural networks,” technical blog, 2024. source
- S. Shao, Z. Li, T. Zhang, C. Peng, G. Yu, X. Zhang, J. Li, J. Sun, “Objects365: A Large-Scale, High-Quality Dataset for Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source