CenterNet: objects as points
Optional · paper guide 7 of 22 for DLCV 03A · One-Stage Detection, Read Through YOLOv4. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- YOLO v1: detection as a single regression
- YOLOv2 and YOLO9000: anchors, priors and joint training
- YOLOv3: three scales and Darknet-53
- SSD: multi-scale default boxes
- RetinaNet and the focal loss
- FCOS: per-pixel anchor-free detection
- CenterNet: objects as points
- YOLOR: explicit features and learned implicit representations
- YOLOX: anchor-free YOLO with SimOTA
- YOLOv6: a re-parameterized industrial detector
- YOLOv7: a trainable bag of freebies
- YOLOv9: programmable gradient information
- YOLOv10: NMS-free training with dual assignments
- YOLOv12: an attention-centric YOLO
- YOLOv13: hypergraph correlation
- YOLO26: a DFL-free end-to-end YOLO
- RT-DETR: a real-time DETR
- RT-DETRv2: a bag of freebies for RT-DETR
- D-FINE: boxes as refined distributions
- DEIM: dense one-to-one matching
- RF-DETR: architecture search on a DINOv2 backbone
- DEIMv2: DINOv3 features for real-time DETRs
Deep Learning for Computer Vision
Paper: X. Zhou, D. Wang and P. Krähenbühl, “Objects as points,” arXiv, 2019 [13]. Related part of YOLOv4: post-processing. DLCV 03 introduces the heatmap formulation. Note the name clash: the “CenterNet” in YOLOv4’s comparison tables is a different detector, based on keypoint triplets, by Duan et al. [75].
Challenge
Most detectors enumerate many potential boxes and then remove duplicates with NMS, a post-processing step that is not differentiable and is hard to train end to end [13]. The paper asks whether an object can be represented by a single point, its centre, so that detection becomes keypoint estimation and duplicates disappear without IoU-based NMS.
Method
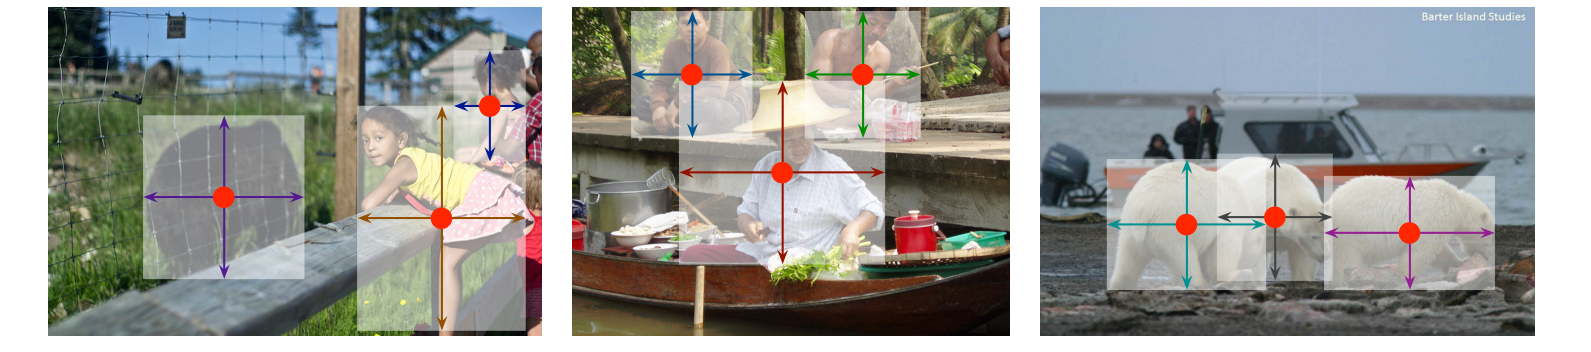
Figure source: [13], arXiv:1904.07850v2, PDF page 2. Original PDF.
Heatmap of centres. For an input of size and output stride , the network predicts a keypoint heatmap , one channel per class [13]. Each ground-truth centre is splatted onto the heatmap with a Gaussian whose standard deviation adapts to the object size; overlapping Gaussians of the same class take the element-wise maximum.
Focal loss on the heatmap. With the target heatmap,
where is the number of objects, and , and the factor reduces the penalty for locations near a true centre [13].
Size and offset. At each location the network also predicts the box size in raw pixels, trained with an L1 loss at the centre points only, and a sub-pixel offset that recovers the discretization error of the output stride, also with an L1 loss. The total loss is with and [13]. The network outputs channels per location; each output has its own convolution, ReLU and convolution on a shared backbone.
Decoding without NMS. Peaks are locations whose value is greater than or equal to their 8 neighbours, which a max pooling finds; the top 100 peaks are kept and turned into boxes from the predicted size and offset [13].
Keep coordinate systems explicit. If the network selects grid point , predicts sub-cell offset and uses output stride , its image-space centre is . A predicted pixel-space size gives corners at the centre plus or minus . Width and height should not be multiplied by the stride again when they are already expressed in input pixels.
Local-maximum selection is still a kind of heatmap suppression. The narrower claim is that the default decoder does not need IoU-based box NMS. Two nearby centres may remain separate peaks, while two same-class objects mapped to the same output location cannot be independently represented by one size/offset vector. Thus removing box NMS changes the representation and its failure modes; it does not make duplicate handling or output resolution irrelevant.
Results
On COCO validation, timed on a Titan Xp, CenterNet with a ResNet-18 backbone reaches 28.1% AP at 142 FPS, a mid-sized backbone 37.4% AP at 52 FPS, and the largest (a 104-layer hourglass network) 40.3% AP at 14 FPS, 42.2% with flip testing at 7.8 FPS and 45.1% with multi-scale testing at 1.4 FPS [13]. The same design extends to 3D boxes and human pose by regressing more quantities at the centre.
Ablations
The paper checks that IoU-based NMS is unnecessary by applying it anyway: AP rises from 39.2% to 39.7% for the mid-sized backbone with flip testing and stays at 42.2% for the largest one, so NMS is not used [13]. It also counts centre collisions: in COCO training data, 614 pairs of objects fall on the same centre point at stride 4, out of 860,001 objects, so fewer than 0.1% of objects cannot be represented [13]. Further ablations cover the size-loss weight ( works well) and longer training schedules.
Conclusion
CenterNet showed that a detector can be a keypoint estimator: one positive per object (its centre), no anchors and no IoU-based NMS, with a simple, fast and general design. It is an instructive example of geometric centre supervision before the later NMS-free YOLOs. Its fixed centre target is different from learned bipartite matching.
Problems
It remains an arXiv paper; objects whose centres coincide on the stride-4 grid cannot both be represented (fewer than 0.1% of COCO objects, as counted above); its size regression in raw pixels needs a hand-set loss weight; and its best accuracy uses multi-scale testing, which merges the results with NMS again [13]. Training one prediction per object directly, with a learned matching rather than a geometric one, became the route of YOLOv10 and the real-time DETRs.
References
- C.-Y. Wang, A. Bochkovskiy and H.-Y. M. Liao, “YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” in Proc. IEEE/CVF CVPR, pp. 7464–7475, 2023. doi
- C.-Y. Wang, I-H. Yeh and H.-Y. M. Liao, “YOLOv9: Learning what you want to learn using programmable gradient information,” in Proc. ECCV, 2024. doi
- G. Jocher, “Ultralytics YOLOv5,” software (first released 2020; v7.0 released 22 November 2022). release · documentation
- G. Jocher, A. Chaurasia and J. Qiu, “Ultralytics YOLOv8,” software, version 8.0.0, 2023 (no paper). docs · code
- G. Jocher and J. Qiu, “Ultralytics YOLO11,” software, version 11.0.0, 2024 (no paper). docs · code
- J. Lu, J. Jia, J. Yawl and C. Zhang, “YOLOv14: Adaptive real-time object detection for diverse imaging conditions,” arXiv:2608.04720, 2026 (withdrawn by the authors, 20 August 2026). arXiv
- J. Redmon, S. Divvala, R. Girshick and A. Farhadi, “You only look once: Unified, real-time object detection,” in Proc. IEEE CVPR, pp. 779–788, 2016. doi · arXiv
- J. Redmon and A. Farhadi, “YOLO9000: Better, faster, stronger,” in Proc. IEEE CVPR, pp. 6517–6525, 2017. doi · arXiv
- J. Redmon and A. Farhadi, “YOLOv3: An incremental improvement,” tech. report, arXiv:1804.02767, 2018. arXiv
- W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C. Fu, A. C. Berg, “SSD: Single Shot MultiBox Detector,” Lecture Notes in Computer Science / Computer Vision – ECCV 2016, 2016. doi · manuscript
- T.-Y. Lin, P. Goyal, R. Girshick, K. He and P. Dollár, “Focal loss for dense object detection,” in Proc. IEEE ICCV, pp. 2999–3007, 2017. doi
- Z. Tian, C. Shen, H. Chen, T. He, “FCOS: Fully Convolutional One-Stage Object Detection,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- X. Zhou, D. Wang, P. Krähenbühl, “Objects as Points,” arXiv preprint, 2019. source
- C. Wang, I. Yeh, H. M. Liao, “You Only Learn One Representation: Unified Network for Multiple Tasks,” arXiv preprint, 2021. source
- Z. Ge, S. Liu, F. Wang, Z. Li and J. Sun, “YOLOX: Exceeding YOLO series in 2021,” arXiv:2107.08430, 2021. arXiv
- C. Li, L. Li, H. Jiang, K. Weng, Y. Geng et al., “YOLOv6: A single-stage object detection framework for industrial applications,” tech. report, arXiv:2209.02976, 2022. arXiv
- A. Wang, H. Chen, L. Liu, K. Chen, Z. Lin, J. Han and G. Ding, “YOLOv10: Real-time end-to-end object detection,” in Proc. NeurIPS, 2024. arXiv
- Y. Tian, Q. Ye and D. Doermann, “YOLOv12: Attention-centric real-time object detectors,” in Advances in Neural Information Processing Systems 38 (NeurIPS), 2025. proceedings · arXiv
- M. Lei, S. Li, Y. Wu, H. Hu, Y. Zhou et al., “YOLOv13: Real-time object detection with hypergraph-enhanced adaptive visual perception,” arXiv:2506.17733, 2025. arXiv
- G. Jocher, J. Qiu, M. Liu, S. Lyu, F. C. Akyon and M. E. Kalfaoglu, “Ultralytics YOLO26: Unified real-time end-to-end vision models,” arXiv:2606.03748, 2026 (software released January 2026). arXiv · docs
- Y. Zhao, W. Lv, S. Xu, J. Wei, G. Wang, Q. Dang, Y. Liu, J. Chen, “DETRs Beat YOLOs on Real-time Object Detection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source
- W. Lv, Y. Zhao, Q. Chang, K. Huang, G. Wang and Y. Liu, “RT-DETRv2: Improved baseline with bag-of-freebies for real-time detection transformer,” arXiv:2407.17140, 2024. arXiv
- Y. Peng, H. Li, P. Wu, Y. Zhang, X. Sun and F. Wu, “D-FINE: Redefine regression task in DETRs as fine-grained distribution refinement,” in Proc. ICLR, 2025. arXiv · code
- S. Huang, Z. Lu, X. Cun, Y. Yu, X. Zhou, X. Shen, “DEIM: DETR with Improved Matching for Fast Convergence,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025. source
- I. Robinson, P. Robicheaux, M. Popov, D. Ramanan and N. Peri, “RF-DETR: Neural architecture search for real-time detection transformers,” in Proc. ICLR, 2026. arXiv
- S. Huang, Y. Hou, L. Liu, X. Yu and X. Shen, “Real-time object detection meets DINOv3,” arXiv:2509.20787, 2025 (revised 2026). arXiv
- A. Bochkovskiy, C.-Y. Wang and H.-Y. M. Liao, “YOLOv4: Optimal speed and accuracy of object detection,” arXiv:2004.10934, 2020. arXiv
- M. Tan, R. Pang, Q. V. Le, “EfficientDet: Scalable and Efficient Object Detection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- NVIDIA, “TensorRT documentation,” official documentation. link
- J. Deng, W. Dong, R. Socher, L. Li, Kai Li, Li Fei-Fei, “ImageNet: A large-scale hierarchical image database,” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 2009. source
- K. Simonyan, A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” arXiv preprint, 2014. source
- K. He, X. Zhang, S. Ren, J. Sun, “Deep Residual Learning for Image Recognition,” arXiv preprint, 2015. source
- T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE CVPR, 2017. doi
- S. Liu, L. Qi, H. Qin, J. Shi and J. Jia, “Path aggregation network for instance segmentation,” in Proc. IEEE/CVF CVPR, pp. 8759–8768, 2018. doi
- K. He, X. Zhang, S. Ren, J. Sun, “Spatial Pyramid Pooling in Deep Convolutional Networks for Visual Recognition,” Lecture Notes in Computer Science / Computer Vision – ECCV 2014, 2014. doi · manuscript
- C.-Y. Wang, H.-Y. M. Liao, I-H. Yeh, Y.-H. Wu, P.-Y. Chen and J.-W. Hsieh, “CSPNet: A new backbone that can enhance learning capability of CNN,” CVPR Workshops, 2020. arXiv · doi
- A. Bochkovskiy and contributors, “Darknet: YOLOv4 configuration and detection layer,” official implementation, accessed 2 November 2026. configuration · assignment and decoding
- M. Tan, Q. V. Le, “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks,” ICML, 2019. source · proceedings
- G. Huang, Z. Liu, L. Van Der Maaten, K. Q. Weinberger, “Densely Connected Convolutional Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- S. Xie, R. Girshick, P. Dollar, Z. Tu, K. He, “Aggregated Residual Transformations for Deep Neural Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- D. Misra, “Mish: A Self Regularized Non-Monotonic Activation Function,” BMVC, 2020. source
- P. Ramachandran, B. Zoph, Q. V. Le, “Searching for Activation Functions,” arXiv preprint, 2017. source
- J. Yu, Y. Jiang, Z. Wang, Z. Cao, T. Huang, “UnitBox: An Advanced Object Detection Network,” ACM Multimedia, 2016. source
- H. Rezatofighi, N. Tsoi, J. Gwak, A. Sadeghian, I. Reid, S. Savarese, “Generalized Intersection over Union: A Metric and A Loss for Bounding Box Regression,” arXiv preprint, 2019. source
- Z. Zheng, P. Wang, W. Liu, J. Li, R. Ye and D. Ren, “Distance-IoU loss: Faster and better learning for bounding box regression,” in Proc. AAAI, pp. 12993–13000, 2020. doi
- H. Zhang, M. Cisse, Y. N. Dauphin and D. Lopez-Paz, “mixup: Beyond empirical risk minimization,” in Proc. ICLR, 2018. arXiv
- S. Yun, D. Han, S. Chun, S. J. Oh, Y. Yoo, J. Choe, “CutMix: Regularization Strategy to Train Strong Classifiers With Localizable Features,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, Ruslan Salakhutdinov, “Dropout: A Simple Way to Prevent Neural Networks from Overfitting,” Journal of Machine Learning Research, 2014. source
- G. Ghiasi, T. Lin, Q. V. Le, “DropBlock: A regularization method for convolutional networks,” NeurIPS, 2018. source · proceedings
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- S. Ioffe and C. Szegedy, “Batch normalization: Accelerating deep network training by reducing internal covariate shift,” in Proc. ICML, PMLR vol. 37, pp. 448–456, 2015. link
- Z. Yao, Y. Cao, S. Zheng, G. Huang, S. Lin, “Cross-Iteration Batch Normalization,” 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021. doi · manuscript
- S. Woo, J. Park, J. Lee, I. S. Kweon, “CBAM: Convolutional Block Attention Module,” Lecture Notes in Computer Science / Computer Vision – ECCV 2018, 2018. doi · manuscript
- I. Loshchilov, F. Hutter, “SGDR: Stochastic Gradient Descent with Warm Restarts,” ICLR, 2017. source
- T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár and C. L. Zitnick, “Microsoft COCO: Common objects in context,” in Proc. ECCV, pp. 740–755, 2014. doi
- COCO Consortium, “COCO detection evaluation,” official evaluation description. link
- ONNX, “Open Neural Network Exchange,” official project page. link
- B. Jacob, S. Kligys, B. Chen, M. Zhu, M. Tang, A. Howard, H. Adam and D. Kalenichenko, “Quantization and training of neural networks for efficient integer-arithmetic-only inference,” in Proc. IEEE/CVF CVPR, pp. 2704–2713, 2018. doi
- N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. ECCV, 2020. doi
- H. W. Kuhn, “The Hungarian method for the assignment problem,” Naval Research Logistics Quarterly, vol. 2, pp. 83–97, 1955. doi
- J. Terven, D.-M. Córdova-Esparza and J.-A. Romero-González, “A comprehensive review of YOLO architectures in computer vision: From YOLOv1 to YOLOv8 and YOLO-NAS,” Machine Learning and Knowledge Extraction, vol. 5, no. 4, pp. 1680–1716, 2023. doi · arXiv
- N. Jegham, C. Y. Koh, M. Abdelatti and A. Hendawi, “YOLO evolution: A comprehensive benchmark and architectural review of YOLOv12, YOLO11, and their previous versions,” arXiv:2411.00201, 2024 (revised 2025). arXiv
- R. Sapkota and M. Karkee, “Ultralytics YOLO evolution: An overview of YOLO27, YOLO26, YOLO11, YOLOv8, and YOLOv5 object detectors for computer vision and pattern recognition,” arXiv:2510.09653, 2025 (revised 2026). arXiv
- T. Shehzadi, K. A. Hashmi, M. Liwicki, D. Stricker and M. Z. Afzal, “Object detection with transformers: A review,” Sensors, vol. 25, no. 19, 2025. doi
- Ultralytics, “YOLO27 (coming soon),” official documentation page, accessed 2 November 2026. docs
- M. Oquab, T. Darcet, T. Moutakanni, H. Vo, M. Szafraniec et al., “DINOv2: Learning robust visual features without supervision,” arXiv:2304.07193, 2023. arXiv
- O. Siméoni, H. V. Vo, M. Seitzer, F. Baldassarre, M. Oquab et al., “DINOv3,” arXiv:2508.10104, 2025. arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, pp. 13728–13737, 2021. doi
- R. Girshick, “Fast R-CNN,” 2015 IEEE International Conference on Computer Vision (ICCV), 2015. doi · manuscript
- S. Ren, K. He, R. Girshick, J. Sun, “Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks,” arXiv preprint, 2015. source
- M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, A. Zisserman, “The Pascal Visual Object Classes (VOC) Challenge,” International Journal of Computer Vision, 2009. source
- A. Shrivastava, A. Gupta, R. Girshick, “Training Region-Based Object Detectors with Online Hard Example Mining,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- H. Zhang, Y. Wang, F. Dayoub and N. Sünderhauf, “VarifocalNet: An IoU-aware dense object detector,” in Proc. IEEE/CVF CVPR, pp. 8510–8519, 2021. doi
- YOLOX contributors, “YOLOX detection head,” official implementation, accessed 2 November 2026. code
- K. Duan, S. Bai, L. Xie, H. Qi, Q. Huang, Q. Tian, “CenterNet: Keypoint Triplets for Object Detection,” arXiv preprint, 2019. source
- Z. Ge, S. Liu, Z. Li, O. Yoshie and J. Sun, “OTA: Optimal transport assignment for object detection,” in Proc. IEEE/CVF CVPR, pp. 303–312, 2021. doi
- C. Li, L. Li, Y. Geng, et al., “YOLOv6 v3.0: A Full-Scale Reloading,” arXiv preprint, 2023. source
- C. Feng, Y. Zhong, Y. Gao, M. R. Scott, W. Huang, “TOOD: Task-Aligned One-Stage Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- Z. Gevorgyan, “SIoU Loss: More Powerful Learning for Bounding Box Regression,” arXiv preprint, 2022. source
- X. Li, W. Wang, L. Wu, S. Chen, X. Hu, J. Li, J. Tang and J. Yang, “Generalized focal loss: Learning qualified and distributed bounding boxes for dense object detection,” in Advances in Neural Information Processing Systems 33 (NeurIPS), 2020. proceedings
- X. Ding, H. Chen, X. Zhang, K. Huang, J. Han, G. Ding, “Re-parameterizing Your Optimizers rather than Architectures,” ICLR, 2023. source
- S. Zhang, C. Chi, Y. Yao, Z. Lei, S. Z. Li, “Bridging the Gap Between Anchor-Based and Anchor-Free Detection via Adaptive Training Sample Selection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- C. Wang, H. M. Liao, I. Yeh, “Designing Network Design Strategies Through Gradient Path Analysis,” arXiv preprint, 2022. source
- T. Dao, D. Fu, S. Ermon, A. Rudra, C. Ré, “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness,” Advances in Neural Information Processing Systems 35, 2022. doi · manuscript
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- K. Jordan, “Muon: An optimizer for hidden layers in neural networks,” technical blog, 2024. source
- S. Shao, Z. Li, T. Zhang, C. Peng, G. Yu, X. Zhang, J. Li, J. Sun, “Objects365: A Large-Scale, High-Quality Dataset for Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source