YOLOR: explicit features and learned implicit representations
Optional · paper guide 8 of 22 for DLCV 03A · One-Stage Detection, Read Through YOLOv4. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- YOLO v1: detection as a single regression
- YOLOv2 and YOLO9000: anchors, priors and joint training
- YOLOv3: three scales and Darknet-53
- SSD: multi-scale default boxes
- RetinaNet and the focal loss
- FCOS: per-pixel anchor-free detection
- CenterNet: objects as points
- YOLOR: explicit features and learned implicit representations
- YOLOX: anchor-free YOLO with SimOTA
- YOLOv6: a re-parameterized industrial detector
- YOLOv7: a trainable bag of freebies
- YOLOv9: programmable gradient information
- YOLOv10: NMS-free training with dual assignments
- YOLOv12: an attention-centric YOLO
- YOLOv13: hypergraph correlation
- YOLO26: a DFL-free end-to-end YOLO
- RT-DETR: a real-time DETR
- RT-DETRv2: a bag of freebies for RT-DETR
- D-FINE: boxes as refined distributions
- DEIM: dense one-to-one matching
- RF-DETR: architecture search on a DINOv2 backbone
- DEIMv2: DINOv3 features for real-time DETRs
Deep Learning for Computer Vision
Wang, Yeh and Liao’s 2021 technical report asks whether a detector can benefit from learned representations that do not depend on the current image [14]. Its practical meaning is much narrower than the analogy to human subconscious learning in the introduction: these are ordinary trainable tensors, optimized through the task loss.
Challenge
A shared backbone produces image-dependent features, but different tasks and prediction channels may prefer different feature spaces. One response is to build larger task-specific branches. YOLOR instead asks whether a small, persistent learned representation can align features, refine predictions and help joint learning. This follows naturally after YOLOv4: keep a strong detector recipe and investigate how to change its representations without rebuilding the whole inference network.
The central distinction is between explicit features, computed from the current input, and implicit representations, model parameters shared across inputs. An implicit tensor is not an additional annotation, an image-specific latent inferred by another network, or evidence that a model understands a task like a person. Keeping these meanings separate makes the paper much easier to read.
Method
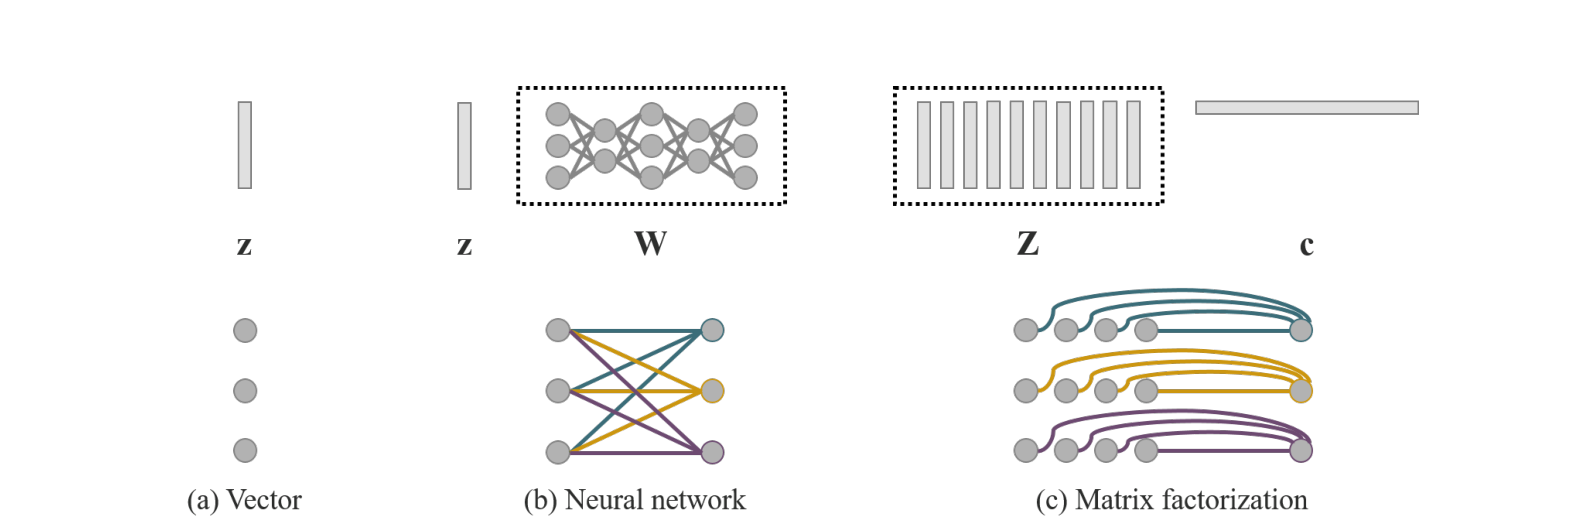
Figure source: [14], arXiv:2105.04206v1, PDF page 5. Original PDF.
Represent and combine. Write an image-dependent feature as and a learned, image-independent representation as . Here is the input image, are the feature extractor’s parameters and are the implicit representation’s parameters. YOLOR studies addition, multiplication and concatenation:
is the combined representation and is element-wise multiplication. A channel vector can be broadcast over spatial positions; concatenation requires matching the remaining dimensions. These are alternatives, not three mandatory successive layers.
Feature alignment. The first application adds implicit representations to feature-pyramid levels. Each level contains different spatial and semantic information. A learned offset can adjust the feature space seen by a downstream shared operation. The tensor has no spatial knowledge about a particular object; its effect must emerge through gradients accumulated across training images.
Prediction refinement. The second application modifies output channels. The choice of operator should respect the decoder. Centre offsets are added to grid coordinates, whereas width and height scale anchor dimensions multiplicatively. The paper therefore tests both generic operators and versions tailored to these meanings. This is more informative than treating all output channels as interchangeable numbers.
Joint learning. The third application combines detection with classification or embedding tasks. Implicit representations allow the common features to be adjusted for the objectives. The report demonstrates particular joint-training experiments; it does not establish that an arbitrary set of tasks can share one representation without interference.
Parameterizations. A directly learned vector is the simplest option. A small neural network can map an implicit code into the required representation, or matrix factorization can generate it from lower-dimensional factors. These approaches change the capacity and parameterization of the adjustment. They are not a second image encoder: the representation remains independent of the current observation.
Possible deployment simplification. When an additive implicit vector lies immediately before an affine prediction convolution, and a multiplicative vector immediately after it, they can be absorbed into weights and bias. At a spatial position, write
is the local input feature, the additive vector, the prediction matrix, its bias, and the multiplicative vector. is the output and are the equivalent fused parameters. This identity requires the stated affine arrangement: intervening nonlinearities, incompatible shapes or spatial boundary effects invalidate this simple derivation. It explains why a richer training parameterization need not imply a proportionally larger deployment graph.
Results
Table 8 is a useful controlled starting point. On the YOLOv4-P6-light baseline at , validation AP changes from 51.4 to 51.9 after adding the tested implicit representations and to 52.5 after fine-tuning [14]. The latter step changes training as well, so the full 1.1-point difference cannot be attributed to the implicit tensors alone.
Table 9 reports the larger YOLOR model at 55.4 test AP and 30 FPS on a V100, compared with 55.5 AP and 16 FPS for the listed Scaled-YOLOv4 model [14]. This is a comparison of complete systems in that table, not proof that adding one tensor doubles any detector’s speed. The paper also distinguishes extra pretraining, segmentation labels and additional images in competing rows; keep those columns when interpreting the result.
Ablations
The small experiments are more revealing than the headline result:
| Experiment | Baseline AP | Modified AP | What it tests |
|---|---|---|---|
| Table 1: additive feature alignment | 47.8 | 47.9 | A small feature-space adjustment |
| Table 2: additive prediction refinement | 47.8 | 47.8 | Not every modification improves aggregate AP |
| Table 4: multiplicative feature alignment | 47.8 | 47.4 | Operator choice can hurt |
| Table 4: multiplicative prediction refinement | 47.8 | 48.0 | Multiplication has a different effect at the output |
| Table 5: width/height-focused refinement | 47.8 | 48.1 | Matching the operator to channel meaning |
These rows use the report’s YOLOv4-CSP-fast setting at [14]. Do not combine them with the different baseline in Table 3 or the larger model in Table 8. Table 6 additionally compares direct vectors, neural-network parameterization and matrix factorization. Table 7 shows that the tested implicit variants add very few parameters and operations; this supports the narrow efficiency claim for those models, rather than a universal zero-cost claim.
Conclusion
YOLOR’s contribution is a way to adjust task representations using small learned constants and carefully chosen operators. It connects YOLOv4’s feature-fusion recipe to YOLOv7’s broader concern with training parameterization. Read it as an investigation of where and how to insert an adjustment, rather than a numbered replacement for every component of YOLOv4.
Problems
The strongest conceptual language is broader than the evidence. Detection and selected joint tasks do not demonstrate general-purpose understanding. Several ablations differ by only tenths of an AP point, without uncertainty estimates that would establish their stability across seeds. Addition, multiplication and factorization are useful engineering choices, but their benefit depends on placement, training and the baseline.
Finally, always distinguish the technical report, particular released model configurations and later implementations. A family name alone does not specify which implicit modules remain in the exported graph, which input resolution was used or how speed was measured. Those details are necessary to reproduce the claimed advantage.
References
- C.-Y. Wang, A. Bochkovskiy and H.-Y. M. Liao, “YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” in Proc. IEEE/CVF CVPR, pp. 7464–7475, 2023. doi
- C.-Y. Wang, I-H. Yeh and H.-Y. M. Liao, “YOLOv9: Learning what you want to learn using programmable gradient information,” in Proc. ECCV, 2024. doi
- G. Jocher, “Ultralytics YOLOv5,” software (first released 2020; v7.0 released 22 November 2022). release · documentation
- G. Jocher, A. Chaurasia and J. Qiu, “Ultralytics YOLOv8,” software, version 8.0.0, 2023 (no paper). docs · code
- G. Jocher and J. Qiu, “Ultralytics YOLO11,” software, version 11.0.0, 2024 (no paper). docs · code
- J. Lu, J. Jia, J. Yawl and C. Zhang, “YOLOv14: Adaptive real-time object detection for diverse imaging conditions,” arXiv:2608.04720, 2026 (withdrawn by the authors, 20 August 2026). arXiv
- J. Redmon, S. Divvala, R. Girshick and A. Farhadi, “You only look once: Unified, real-time object detection,” in Proc. IEEE CVPR, pp. 779–788, 2016. doi · arXiv
- J. Redmon and A. Farhadi, “YOLO9000: Better, faster, stronger,” in Proc. IEEE CVPR, pp. 6517–6525, 2017. doi · arXiv
- J. Redmon and A. Farhadi, “YOLOv3: An incremental improvement,” tech. report, arXiv:1804.02767, 2018. arXiv
- W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C. Fu, A. C. Berg, “SSD: Single Shot MultiBox Detector,” Lecture Notes in Computer Science / Computer Vision – ECCV 2016, 2016. doi · manuscript
- T.-Y. Lin, P. Goyal, R. Girshick, K. He and P. Dollár, “Focal loss for dense object detection,” in Proc. IEEE ICCV, pp. 2999–3007, 2017. doi
- Z. Tian, C. Shen, H. Chen, T. He, “FCOS: Fully Convolutional One-Stage Object Detection,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- X. Zhou, D. Wang, P. Krähenbühl, “Objects as Points,” arXiv preprint, 2019. source
- C. Wang, I. Yeh, H. M. Liao, “You Only Learn One Representation: Unified Network for Multiple Tasks,” arXiv preprint, 2021. source
- Z. Ge, S. Liu, F. Wang, Z. Li and J. Sun, “YOLOX: Exceeding YOLO series in 2021,” arXiv:2107.08430, 2021. arXiv
- C. Li, L. Li, H. Jiang, K. Weng, Y. Geng et al., “YOLOv6: A single-stage object detection framework for industrial applications,” tech. report, arXiv:2209.02976, 2022. arXiv
- A. Wang, H. Chen, L. Liu, K. Chen, Z. Lin, J. Han and G. Ding, “YOLOv10: Real-time end-to-end object detection,” in Proc. NeurIPS, 2024. arXiv
- Y. Tian, Q. Ye and D. Doermann, “YOLOv12: Attention-centric real-time object detectors,” in Advances in Neural Information Processing Systems 38 (NeurIPS), 2025. proceedings · arXiv
- M. Lei, S. Li, Y. Wu, H. Hu, Y. Zhou et al., “YOLOv13: Real-time object detection with hypergraph-enhanced adaptive visual perception,” arXiv:2506.17733, 2025. arXiv
- G. Jocher, J. Qiu, M. Liu, S. Lyu, F. C. Akyon and M. E. Kalfaoglu, “Ultralytics YOLO26: Unified real-time end-to-end vision models,” arXiv:2606.03748, 2026 (software released January 2026). arXiv · docs
- Y. Zhao, W. Lv, S. Xu, J. Wei, G. Wang, Q. Dang, Y. Liu, J. Chen, “DETRs Beat YOLOs on Real-time Object Detection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source
- W. Lv, Y. Zhao, Q. Chang, K. Huang, G. Wang and Y. Liu, “RT-DETRv2: Improved baseline with bag-of-freebies for real-time detection transformer,” arXiv:2407.17140, 2024. arXiv
- Y. Peng, H. Li, P. Wu, Y. Zhang, X. Sun and F. Wu, “D-FINE: Redefine regression task in DETRs as fine-grained distribution refinement,” in Proc. ICLR, 2025. arXiv · code
- S. Huang, Z. Lu, X. Cun, Y. Yu, X. Zhou, X. Shen, “DEIM: DETR with Improved Matching for Fast Convergence,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025. source
- I. Robinson, P. Robicheaux, M. Popov, D. Ramanan and N. Peri, “RF-DETR: Neural architecture search for real-time detection transformers,” in Proc. ICLR, 2026. arXiv
- S. Huang, Y. Hou, L. Liu, X. Yu and X. Shen, “Real-time object detection meets DINOv3,” arXiv:2509.20787, 2025 (revised 2026). arXiv
- A. Bochkovskiy, C.-Y. Wang and H.-Y. M. Liao, “YOLOv4: Optimal speed and accuracy of object detection,” arXiv:2004.10934, 2020. arXiv
- M. Tan, R. Pang, Q. V. Le, “EfficientDet: Scalable and Efficient Object Detection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- NVIDIA, “TensorRT documentation,” official documentation. link
- J. Deng, W. Dong, R. Socher, L. Li, Kai Li, Li Fei-Fei, “ImageNet: A large-scale hierarchical image database,” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 2009. source
- K. Simonyan, A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” arXiv preprint, 2014. source
- K. He, X. Zhang, S. Ren, J. Sun, “Deep Residual Learning for Image Recognition,” arXiv preprint, 2015. source
- T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE CVPR, 2017. doi
- S. Liu, L. Qi, H. Qin, J. Shi and J. Jia, “Path aggregation network for instance segmentation,” in Proc. IEEE/CVF CVPR, pp. 8759–8768, 2018. doi
- K. He, X. Zhang, S. Ren, J. Sun, “Spatial Pyramid Pooling in Deep Convolutional Networks for Visual Recognition,” Lecture Notes in Computer Science / Computer Vision – ECCV 2014, 2014. doi · manuscript
- C.-Y. Wang, H.-Y. M. Liao, I-H. Yeh, Y.-H. Wu, P.-Y. Chen and J.-W. Hsieh, “CSPNet: A new backbone that can enhance learning capability of CNN,” CVPR Workshops, 2020. arXiv · doi
- A. Bochkovskiy and contributors, “Darknet: YOLOv4 configuration and detection layer,” official implementation, accessed 2 November 2026. configuration · assignment and decoding
- M. Tan, Q. V. Le, “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks,” ICML, 2019. source · proceedings
- G. Huang, Z. Liu, L. Van Der Maaten, K. Q. Weinberger, “Densely Connected Convolutional Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- S. Xie, R. Girshick, P. Dollar, Z. Tu, K. He, “Aggregated Residual Transformations for Deep Neural Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- D. Misra, “Mish: A Self Regularized Non-Monotonic Activation Function,” BMVC, 2020. source
- P. Ramachandran, B. Zoph, Q. V. Le, “Searching for Activation Functions,” arXiv preprint, 2017. source
- J. Yu, Y. Jiang, Z. Wang, Z. Cao, T. Huang, “UnitBox: An Advanced Object Detection Network,” ACM Multimedia, 2016. source
- H. Rezatofighi, N. Tsoi, J. Gwak, A. Sadeghian, I. Reid, S. Savarese, “Generalized Intersection over Union: A Metric and A Loss for Bounding Box Regression,” arXiv preprint, 2019. source
- Z. Zheng, P. Wang, W. Liu, J. Li, R. Ye and D. Ren, “Distance-IoU loss: Faster and better learning for bounding box regression,” in Proc. AAAI, pp. 12993–13000, 2020. doi
- H. Zhang, M. Cisse, Y. N. Dauphin and D. Lopez-Paz, “mixup: Beyond empirical risk minimization,” in Proc. ICLR, 2018. arXiv
- S. Yun, D. Han, S. Chun, S. J. Oh, Y. Yoo, J. Choe, “CutMix: Regularization Strategy to Train Strong Classifiers With Localizable Features,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, Ruslan Salakhutdinov, “Dropout: A Simple Way to Prevent Neural Networks from Overfitting,” Journal of Machine Learning Research, 2014. source
- G. Ghiasi, T. Lin, Q. V. Le, “DropBlock: A regularization method for convolutional networks,” NeurIPS, 2018. source · proceedings
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- S. Ioffe and C. Szegedy, “Batch normalization: Accelerating deep network training by reducing internal covariate shift,” in Proc. ICML, PMLR vol. 37, pp. 448–456, 2015. link
- Z. Yao, Y. Cao, S. Zheng, G. Huang, S. Lin, “Cross-Iteration Batch Normalization,” 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021. doi · manuscript
- S. Woo, J. Park, J. Lee, I. S. Kweon, “CBAM: Convolutional Block Attention Module,” Lecture Notes in Computer Science / Computer Vision – ECCV 2018, 2018. doi · manuscript
- I. Loshchilov, F. Hutter, “SGDR: Stochastic Gradient Descent with Warm Restarts,” ICLR, 2017. source
- T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár and C. L. Zitnick, “Microsoft COCO: Common objects in context,” in Proc. ECCV, pp. 740–755, 2014. doi
- COCO Consortium, “COCO detection evaluation,” official evaluation description. link
- ONNX, “Open Neural Network Exchange,” official project page. link
- B. Jacob, S. Kligys, B. Chen, M. Zhu, M. Tang, A. Howard, H. Adam and D. Kalenichenko, “Quantization and training of neural networks for efficient integer-arithmetic-only inference,” in Proc. IEEE/CVF CVPR, pp. 2704–2713, 2018. doi
- N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. ECCV, 2020. doi
- H. W. Kuhn, “The Hungarian method for the assignment problem,” Naval Research Logistics Quarterly, vol. 2, pp. 83–97, 1955. doi
- J. Terven, D.-M. Córdova-Esparza and J.-A. Romero-González, “A comprehensive review of YOLO architectures in computer vision: From YOLOv1 to YOLOv8 and YOLO-NAS,” Machine Learning and Knowledge Extraction, vol. 5, no. 4, pp. 1680–1716, 2023. doi · arXiv
- N. Jegham, C. Y. Koh, M. Abdelatti and A. Hendawi, “YOLO evolution: A comprehensive benchmark and architectural review of YOLOv12, YOLO11, and their previous versions,” arXiv:2411.00201, 2024 (revised 2025). arXiv
- R. Sapkota and M. Karkee, “Ultralytics YOLO evolution: An overview of YOLO27, YOLO26, YOLO11, YOLOv8, and YOLOv5 object detectors for computer vision and pattern recognition,” arXiv:2510.09653, 2025 (revised 2026). arXiv
- T. Shehzadi, K. A. Hashmi, M. Liwicki, D. Stricker and M. Z. Afzal, “Object detection with transformers: A review,” Sensors, vol. 25, no. 19, 2025. doi
- Ultralytics, “YOLO27 (coming soon),” official documentation page, accessed 2 November 2026. docs
- M. Oquab, T. Darcet, T. Moutakanni, H. Vo, M. Szafraniec et al., “DINOv2: Learning robust visual features without supervision,” arXiv:2304.07193, 2023. arXiv
- O. Siméoni, H. V. Vo, M. Seitzer, F. Baldassarre, M. Oquab et al., “DINOv3,” arXiv:2508.10104, 2025. arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, pp. 13728–13737, 2021. doi
- R. Girshick, “Fast R-CNN,” 2015 IEEE International Conference on Computer Vision (ICCV), 2015. doi · manuscript
- S. Ren, K. He, R. Girshick, J. Sun, “Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks,” arXiv preprint, 2015. source
- M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, A. Zisserman, “The Pascal Visual Object Classes (VOC) Challenge,” International Journal of Computer Vision, 2009. source
- A. Shrivastava, A. Gupta, R. Girshick, “Training Region-Based Object Detectors with Online Hard Example Mining,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- H. Zhang, Y. Wang, F. Dayoub and N. Sünderhauf, “VarifocalNet: An IoU-aware dense object detector,” in Proc. IEEE/CVF CVPR, pp. 8510–8519, 2021. doi
- YOLOX contributors, “YOLOX detection head,” official implementation, accessed 2 November 2026. code
- K. Duan, S. Bai, L. Xie, H. Qi, Q. Huang, Q. Tian, “CenterNet: Keypoint Triplets for Object Detection,” arXiv preprint, 2019. source
- Z. Ge, S. Liu, Z. Li, O. Yoshie and J. Sun, “OTA: Optimal transport assignment for object detection,” in Proc. IEEE/CVF CVPR, pp. 303–312, 2021. doi
- C. Li, L. Li, Y. Geng, et al., “YOLOv6 v3.0: A Full-Scale Reloading,” arXiv preprint, 2023. source
- C. Feng, Y. Zhong, Y. Gao, M. R. Scott, W. Huang, “TOOD: Task-Aligned One-Stage Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- Z. Gevorgyan, “SIoU Loss: More Powerful Learning for Bounding Box Regression,” arXiv preprint, 2022. source
- X. Li, W. Wang, L. Wu, S. Chen, X. Hu, J. Li, J. Tang and J. Yang, “Generalized focal loss: Learning qualified and distributed bounding boxes for dense object detection,” in Advances in Neural Information Processing Systems 33 (NeurIPS), 2020. proceedings
- X. Ding, H. Chen, X. Zhang, K. Huang, J. Han, G. Ding, “Re-parameterizing Your Optimizers rather than Architectures,” ICLR, 2023. source
- S. Zhang, C. Chi, Y. Yao, Z. Lei, S. Z. Li, “Bridging the Gap Between Anchor-Based and Anchor-Free Detection via Adaptive Training Sample Selection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- C. Wang, H. M. Liao, I. Yeh, “Designing Network Design Strategies Through Gradient Path Analysis,” arXiv preprint, 2022. source
- T. Dao, D. Fu, S. Ermon, A. Rudra, C. Ré, “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness,” Advances in Neural Information Processing Systems 35, 2022. doi · manuscript
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- K. Jordan, “Muon: An optimizer for hidden layers in neural networks,” technical blog, 2024. source
- S. Shao, Z. Li, T. Zhang, C. Peng, G. Yu, X. Zhang, J. Li, J. Sun, “Objects365: A Large-Scale, High-Quality Dataset for Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source