Donut: a reading guide
Optional · paper guide 4 of 4 for DLCV 06 · Text in Images: OCR and Document Understanding. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
Challenge
Document-understanding systems relied on an external OCR engine whose cost, language coverage and errors limited everything downstream [34].
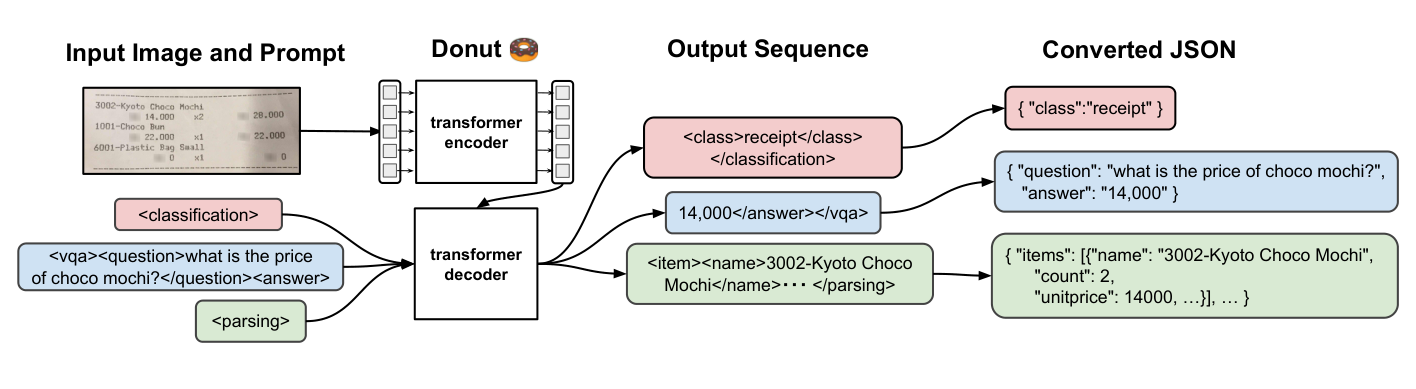
Figure source: [34], arXiv:2111.15664v5, PDF page 4. Original PDF.
Method
A single image-to-sequence transformer (a Swin encoder and a BART decoder) trained in two stages. Reading: predict all the text of a page in reading order, using 11 million scanned English documents with pseudo-labels from a commercial OCR service, plus synthetic pages from SynthDoG in Chinese, Japanese, Korean and English. Understanding: fine-tune the decoder to emit token sequences that map one-to-one to JSON — a class token for classification, nested fields for information extraction, an answer for question answering.
Results
Experiments cover document classification (RVL-CDIP), information extraction (the public CORD receipt and Chinese train-ticket datasets, plus in-service Japanese business-card and Korean receipt datasets) and DocVQA, comparing against OCR-based models in accuracy and in speed including OCR time. Analyses vary the backbone, the pre-training data and the input resolution, visualize the decoder’s cross-attention as a rough text locator, and show that OCR-based baselines depend strongly on which OCR engine they use.
Reading the evidence
Two metrics are used for information extraction: field-level F1 (exact field match) and TED-based accuracy (tree edit distance, with partial credit). They can rank methods differently, so read both. Speed columns for OCR-based methods include the OCR engine; check which engine, because the paper shows that this choice changes both speed and accuracy. For DocVQA, the resolution study is the key result: accuracy grows quickly with input size because documents contain tiny text, and the larger input makes the model slower.
Problems
The paper’s own example shows Donut missing tiny text in a large image, and generation offers no character-level grounding, so errors cannot be traced to pixels as with an OCR box. The pre-training labels on real documents come from an OCR engine, so OCR is not absent from the pipeline, only from inference.
Conclusion
Donut is the clearest early statement of the OCR-free design that today’s VLM-based document readers follow, and of its two costs: resolution and verifiability.
References
- S. Long, X. He and C. Yao, “Scene text detection and recognition: The deep learning era,” International Journal of Computer Vision, vol. 129, pp. 161–184, 2021. doi
- X. Chen, L. Jin, Y. Zhu, C. Luo and T. Wang, “Text recognition in the wild: A survey,” ACM Computing Surveys, vol. 54, no. 2, 2021. doi
- L. Cui, Y. Xu, T. Lv and F. Wei, “Document AI: Benchmarks, models and applications,” arXiv:2111.08609, 2021. arXiv
- Q. Zhang, B. Wang, V. S.-J. Huang, J. Zhang, Z. Wang, H. Liang, C. He and W. Zhang, “Document parsing unveiled: Techniques, challenges, and prospects for structured information extraction,” arXiv:2410.21169, 2024. arXiv
- D. Karatzas, F. Shafait, S. Uchida, M. Iwamura, L. Gomez i Bigorda, S. Robles Mestre, J. Mas et al., “ICDAR 2013 Robust Reading Competition,” in Proc. International Conference on Document Analysis and Recognition (ICDAR), pp. 1484–1493, 2013. doi
- D. Karatzas, L. Gomez-Bigorda, A. Nicolaou, S. Ghosh, A. Bagdanov, M. Iwamura, J. Matas et al., “ICDAR 2015 competition on Robust Reading,” in Proc. International Conference on Document Analysis and Recognition (ICDAR), pp. 1156–1160, 2015. doi
- J. Baek, G. Kim, J. Lee, S. Park, D. Han, S. Yun, S. J. Oh and H. Lee, “What is wrong with scene text recognition model comparisons? Dataset and model analysis,” in Proc. IEEE/CVF ICCV, pp. 4714–4722, 2019. doi
- N. Otsu, “A threshold selection method from gray-level histograms,” IEEE Transactions on Systems, Man, and Cybernetics, vol. 9, no. 1, pp. 62–66, 1979. doi
- J. Sauvola and M. Pietikäinen, “Adaptive document image binarization,” Pattern Recognition, vol. 33, no. 2, pp. 225–236, 2000. doi
- C. K. Ch’ng and C. S. Chan, “Total-Text: A comprehensive dataset for scene text detection and recognition,” in Proc. ICDAR, pp. 935–942, 2017. doi
- Y. Liu, L. Jin, S. Zhang, C. Luo and S. Zhang, “Curved scene text detection via transverse and longitudinal sequence connection,” Pattern Recognition, vol. 90, pp. 337–345, 2019. doi
- X. Zhou, C. Yao, H. Wen, Y. Wang, S. Zhou, W. He and J. Liang, “EAST: An efficient and accurate scene text detector,” in Proc. IEEE CVPR, pp. 2642–2651, 2017. doi
- W. Wang, E. Xie, X. Li, W. Hou, T. Lu, G. Yu and S. Shao, “Shape robust text detection with progressive scale expansion network,” in Proc. IEEE/CVF CVPR, pp. 9328–9337, 2019. doi
- M. Liao, Z. Wan, C. Yao, K. Chen and X. Bai, “Real-time scene text detection with differentiable binarization,” in Proc. AAAI Conference on Artificial Intelligence, vol. 34, pp. 11474–11481, 2020. doi
- Y. Baek, B. Lee, D. Han, S. Yun and H. Lee, “Character region awareness for text detection,” in Proc. IEEE/CVF CVPR, pp. 9357–9366, 2019. doi
- B. Shi, X. Bai and C. Yao, “An end-to-end trainable neural network for image-based sequence recognition and its application to scene text recognition,” IEEE TPAMI, vol. 39, no. 11, pp. 2298–2304, 2017. doi
- A. Graves, S. Fernández, F. Gomez and J. Schmidhuber, “Connectionist temporal classification: Labelling unsegmented sequence data with recurrent neural networks,” in Proc. ICML, pp. 369–376, 2006. doi
- B. Shi, M. Yang, X. Wang, P. Lyu, C. Yao and X. Bai, “ASTER: An attentional scene text recognizer with flexible rectification,” IEEE TPAMI, vol. 41, no. 9, pp. 2035–2048, 2019. doi
- M. Li, T. Lv, J. Chen, L. Cui, Y. Lu, D. Florencio, C. Zhang, Z. Li and F. Wei, “TrOCR: Transformer-based optical character recognition with pre-trained models,” in Proc. AAAI Conference on Artificial Intelligence, vol. 37, pp. 13094–13102, 2023. doi
- D. Bautista and R. Atienza, “Scene text recognition with permuted autoregressive sequence models,” in Proc. ECCV, pp. 178–196, 2022. doi
- S. Fang, H. Xie, Y. Wang, Z. Mao and Y. Zhang, “Read like humans: Autonomous, bidirectional and iterative language modeling for scene text recognition,” in Proc. IEEE/CVF CVPR, pp. 7094–7103, 2021. doi
- Y. Liu, Z. Li, M. Huang, B. Yang, W. Yu, C. Li, X.-C. Yin, C.-L. Liu, L. Jin and X. Bai, “OCRBench: On the hidden mystery of OCR in large multimodal models,” Science China Information Sciences, vol. 67, 2024. doi
- M. Jaderberg, K. Simonyan, A. Vedaldi and A. Zisserman, “Synthetic data and artificial neural networks for natural scene text recognition,” arXiv:1406.2227, 2014. arXiv
- A. Gupta, A. Vedaldi and A. Zisserman, “Synthetic data for text localisation in natural images,” in Proc. IEEE CVPR, pp. 2315–2324, 2016. doi
- X. Liu, D. Liang, S. Yan, D. Chen, Y. Qiao and J. Yan, “FOTS: Fast oriented text spotting with a unified network,” in Proc. IEEE/CVF CVPR, pp. 5676–5685, 2018. doi
- P. Lyu, M. Liao, C. Yao, W. Wu and X. Bai, “Mask TextSpotter: An end-to-end trainable neural network for spotting text with arbitrary shapes,” in Proc. ECCV, pp. 71–88, 2018. doi
- Y. Liu, H. Chen, C. Shen, T. He, L. Jin and L. Wang, “ABCNet: Real-time scene text spotting with adaptive Bezier-curve network,” in Proc. IEEE/CVF CVPR, pp. 9806–9815, 2020. doi
- X. Zhong, J. Tang and A. Jimeno Yepes, “PubLayNet: Largest dataset ever for document layout analysis,” in Proc. ICDAR, pp. 1015–1022, 2019. doi
- B. Pfitzmann, C. Auer, M. Dolfi, A. S. Nassar and P. Staar, “DocLayNet: A large human-annotated dataset for document-layout segmentation,” in Proc. ACM SIGKDD, pp. 3743–3751, 2022. doi
- Y. Xu, M. Li, L. Cui, S. Huang, F. Wei and M. Zhou, “LayoutLM: Pre-training of text and layout for document image understanding,” in Proc. ACM SIGKDD, pp. 1192–1200, 2020. doi
- R. Smith, “An overview of the Tesseract OCR engine,” in Proc. ICDAR, vol. 2, pp. 629–633, 2007. doi
- Y. Huang, T. Lv, L. Cui, Y. Lu and F. Wei, “LayoutLMv3: Pre-training for document AI with unified text and image masking,” in Proc. ACM International Conference on Multimedia, pp. 4083–4091, 2022. doi
- G. Jaume, H. K. Ekenel and J.-P. Thiran, “FUNSD: A dataset for form understanding in noisy scanned documents,” in Proc. ICDAR Workshops (OST), 2019. doi
- G. Kim, T. Hong, M. Yim, J. Nam, J. Park, J. Yim, W. Hwang, S. Yun, D. Han and S. Park, “OCR-free document understanding transformer,” in Proc. ECCV, pp. 498–517, 2022. doi
- K. Lee, M. Joshi, I. R. Turc, H. Hu, F. Liu, J. M. Eisenschlos, U. Khandelwal, P. Shaw, M.-W. Chang and K. Toutanova, “Pix2Struct: Screenshot parsing as pretraining for visual language understanding,” in Proc. ICML, PMLR vol. 202, pp. 18893–18912, 2023. PMLR
- L. Blecher, G. Cucurull, T. Scialom and R. Stojnic, “Nougat: Neural optical understanding for academic documents,” in Proc. ICLR, 2024. OpenReview · arXiv
- U.-V. Marti and H. Bunke, “The IAM-database: An English sentence database for offline handwriting recognition,” International Journal on Document Analysis and Recognition, vol. 5, pp. 39–46, 2002. doi
- C.-L. Liu, F. Yin, D.-H. Wang and Q.-F. Wang, “CASIA online and offline Chinese handwriting databases,” in Proc. ICDAR, pp. 37–41, 2011. doi
- B. Shi, C. Yao, M. Liao, M. Yang, P. Xu, L. Cui, S. Belongie, S. Lu and X. Bai, “ICDAR2017 competition on reading Chinese text in the wild (RCTW-17),” in Proc. ICDAR, pp. 1429–1434, 2017. doi · arXiv
- T.-L. Yuan, Z. Zhu, K. Xu, C.-J. Li, T.-J. Mu and S.-M. Hu, “A large Chinese text dataset in the wild,” Journal of Computer Science and Technology, vol. 34, pp. 509–521, 2019. doi · arXiv
- F. Xue and R. Ishida (eds.), “Requirements for Chinese Text Layout,” W3C Group Note (draft of 7 October 2026). W3C
- N. Nayef, Y. Patel, M. Busta, P. N. Chowdhury, D. Karatzas, W. Khlif, J. Matas et al., “ICDAR2019 Robust Reading Challenge on multi-lingual scene text detection and recognition — RRC-MLT-2019,” in Proc. ICDAR, pp. 1582–1587, 2019. doi · arXiv
- R. A. Wagner and M. J. Fischer, “The string-to-string correction problem,” Journal of the ACM, vol. 21, no. 1, pp. 168–173, 1974. doi
- M. Mathew, D. Karatzas and C. V. Jawahar, “DocVQA: A dataset for VQA on document images,” in Proc. IEEE/CVF WACV, pp. 2199–2208, 2021. doi
- A. Mishra, K. Alahari and C. V. Jawahar, “Scene text recognition using higher order language priors,” in Proc. BMVC, 2012. doi
- K. Wang, B. Babenko and S. Belongie, “End-to-end scene text recognition,” in Proc. IEEE ICCV, pp. 1457–1464, 2011. doi
- L. Ouyang, Y. Qu, H. Zhou, J. Zhu, R. Zhang, Q. Lin, B. Wang, Z. Zhao et al., “OmniDocBench: Benchmarking diverse PDF document parsing with comprehensive annotations,” in Proc. IEEE/CVF CVPR, pp. 24838–24848, 2025. CVF
- H. Wei, C. Liu, J. Chen, J. Wang, L. Kong, Y. Xu, Z. Ge, L. Zhao et al., “General OCR theory: Towards OCR-2.0 via a unified end-to-end model,” arXiv:2409.01704, 2024. arXiv
- J. Poznanski, A. Rangapur, J. Borchardt, J. Dunkelberger, R. Huff, D. Lin, C. Wilhelm et al., “olmOCR: Unlocking trillions of tokens in PDFs with vision language models,” arXiv:2502.18443, 2025. arXiv
- H. Wei, Y. Sun and Y. Li, “DeepSeek-OCR: Contexts optical compression,” arXiv:2510.18234, 2025. arXiv
- C. Wolf and J.-M. Jolion, “Object count/area graphs for the evaluation of object detection and segmentation algorithms,” International Journal of Document Analysis and Recognition, vol. 8, pp. 280–296, 2006. doi