DDNM: preserve measured components and generate the null space
Optional · paper guide 3 of 5 for DLCV 09B · Generative Image Restoration: Sampling a Plausible Answer. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- Blau and Michaeli, “The Perception-Distortion Tradeoff” (CVPR 2018)
- Chung et al., “Diffusion Posterior Sampling for General Noisy Inverse Problems” (ICLR 2023)
- DDNM: preserve measured components and generate the null space
- BlindDPS: infer an image and its degradation together
- Li et al., “Diffusion Models for Image Restoration and Enhancement: A Comprehensive Survey” (IJCV 2025)
Deep Learning for Computer Vision
Challenge
A learned prior can invent values that disagree with a known noiseless measurement. DDNM [19] separates the part fixed by a linear measurement from the part left unconstrained, correcting the former after each clean-image prediction. The base model’s exact-consistency argument requires a suitable known operator and feasible noiseless data.
Method
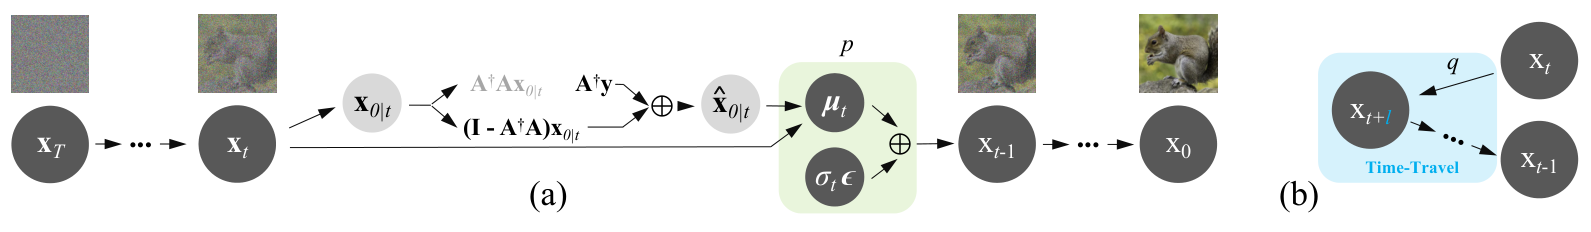
Figure source: [19], PDF page 5. Original PDF.
Let map image vector to . Choose generalized inverse satisfying . For a diffusion clean-image estimate , form
is the identity; is sampling time. The first term inserts a measurement-compatible component; the second retains the prior’s component in the null space of . With the Moore–Penrose inverse, these are orthogonal row-space/null-space components. A general inverse can instead produce an oblique projection.
For feasible , multiplying the equation by gives . This says nothing about whether the retained null-space detail equals the original unseen image. The corrected clean estimate is inserted into the next reverse-diffusion/DDIM update; one should not simply overwrite the noisy state with a clean image.
Use operators that can actually be checked. For masking, the binary mask acts as its own inverse on observed entries. For block averaging, replication supplies the corresponding measurement-consistent lift. Bicubic downsampling has a different operator/inverse. Reversing the order of several generalized inverses is not automatically a valid inverse for every composed degradation: verify .
DDNM+ handles measurement noise. If , hard projection also inserts . DDNM+ scales the range correction and adjusts the injected sampling noise to respect the diffusion noise budget. Its time-travel procedure temporarily returns to a noisier state and repeats refinement to improve global compatibility. These are separate improvements; neither is a claim that noisy observations should be copied exactly.
Read the figure and choose a baseline. In the projection step, separate the part determined by the measurement from the part in the operator’s null space. For a noiseless mask, observed pixels can be imposed while the prior fills missing pixels; this example does not imply that a general blur operator is implemented by pixel replacement. Check the operator and pseudoinverse together before interpreting exact consistency. If the measurements are noisy, use the paper’s noise-aware setting rather than blindly projecting onto every observed value. Consistency constrains admissible outputs, but multiple different images can still satisfy the same measurement.
Results
Under original Table 1’s common denoiser and 100-step DDIM protocol, noiseless CelebA SR gives 31.63 dB / 0.945 SSIM / 22.27 FID. DDRM has the same displayed PSNR/SSIM but FID 31.04. Matching distortion scores therefore does not imply matching output distributions.
The paper evaluates ImageNet and CelebA at across SR, deblurring, colorization, compressed sensing and inpainting. The tables specify their particular operators; success with a linear grayscale model is not evidence for arbitrary unknown camera rendering.
Ablations
Table 2 separates noisy-data handling from time travel. On CelebA SR at the setting labeled , PSNR rises from 13.10 to 19.44 dB with DDNM+. In the time-travel comparison for SR, the displayed values change from 17.55 to 18.44 dB. Repeated refinement adds work and must be counted when comparing inference cost.
The same table includes colorization and compressed sensing, showing that the magnitude of a gain is task dependent. Do not attribute both the noise-budget change and repeated sampling to the projection equation alone.
Conclusion
DDNM provides a clear algebraic split between measurement constraints and prior-generated freedom. DDNM+ explains why observation noise and repeated refinement need explicit treatment beyond the noiseless projection.
Problems
A wrong operator or inaccurate generalized inverse invalidates the consistency argument. Exact consistency can preserve noise or misspecification, while a large null space still permits hallucination. Compression and nonlinear camera processing may violate the assumed linear model. “Zero-shot” means reusing a pretrained prior for a new inverse task; it does not mean that the denoiser needed no training.
References
- Y. Blau and T. Michaeli, “The Perception-Distortion Tradeoff,” in Proc. IEEE/CVF CVPR, 2018, pp. 6228–6237 (extended version on arXiv). doi · arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017, pp. 105–114. doi · arXiv
- J. Johnson, A. Alahi and L. Fei-Fei, “Perceptual Losses for Real-Time Style Transfer and Super-Resolution,” in Proc. ECCV, 2016, pp. 694–711. doi · arXiv
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018 (LNCS, 2019), pp. 63–79. doi · arXiv
- X. Wang, L. Xie, C. Dong and Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution with Pure Synthetic Data,” in Proc. IEEE/CVF ICCV Workshops, 2021, pp. 1905–1914. doi · arXiv
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” in Proc. IEEE/CVF CVPR, 2019, pp. 4396–4405. doi · arXiv
- S. Menon, A. Damian, S. Hu, N. Ravi and C. Rudin, “PULSE: Self-Supervised Photo Upsampling via Latent Space Exploration of Generative Models,” in Proc. IEEE/CVF CVPR, 2020, pp. 2434–2442. doi · arXiv
- K. C. K. Chan, X. Wang, X. Xu, J. Gu and C. C. Loy, “GLEAN: Generative Latent Bank for Large-Factor Image Super-Resolution,” in Proc. IEEE/CVF CVPR, 2021, pp. 14240–14249. doi · arXiv
- X. Wang, Y. Li, H. Zhang and Y. Shan, “Towards Real-World Blind Face Restoration with Generative Facial Prior,” in Proc. IEEE/CVF CVPR, 2021, pp. 9164–9174. doi · arXiv
- S. Zhou, K. C. K. Chan, C. Li and C. C. Loy, “Towards Robust Blind Face Restoration with Codebook Lookup Transformer,” in Proc. NeurIPS, vol. 35, 2022, pp. 30599–30611. doi · arXiv
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” in Proc. NeurIPS, 2020. proceedings · arXiv
- Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon and B. Poole, “Score-Based Generative Modeling through Stochastic Differential Equations,” in Proc. ICLR, 2021. arXiv
- B. Efron, “Tweedie’s Formula and Selection Bias,” Journal of the American Statistical Association, vol. 106, no. 496, pp. 1602–1614, 2011. doi
- C. Saharia, J. Ho, W. Chan, T. Salimans, D. J. Fleet and M. Norouzi, “Image Super-Resolution via Iterative Refinement,” IEEE TPAMI, 2022 (early access). doi · arXiv
- C. Saharia, W. Chan, H. Chang, C. Lee, J. Ho, T. Salimans, D. Fleet and M. Norouzi, “Palette: Image-to-Image Diffusion Models,” in Proc. ACM SIGGRAPH Conference, 2022, pp. 1–10. doi · arXiv
- Z. Yue, J. Wang and C. C. Loy, “ResShift: Efficient Diffusion Model for Image Super-resolution by Residual Shifting,” in Proc. NeurIPS, vol. 36, 2023, pp. 13294–13307. doi · arXiv
- H. Chung, J. Kim, M. T. McCann, M. L. Klasky and J. C. Ye, “Diffusion Posterior Sampling for General Noisy Inverse Problems,” in Proc. ICLR, 2023. arXiv
- B. Kawar, M. Elad, S. Ermon and J. Song, “Denoising Diffusion Restoration Models,” in Proc. NeurIPS, vol. 35, 2022, pp. 23593–23606. doi · arXiv
- Y. Wang, J. Yu and J. Zhang, “Zero-Shot Image Restoration Using Denoising Diffusion Null-Space Model,” in Proc. ICLR, 2023. arXiv
- J. Song, A. Vahdat, M. Mardani and J. Kautz, “Pseudoinverse-Guided Diffusion Models for Inverse Problems,” in Proc. ICLR, 2023. ICLR page
- Y. Zhu, K. Zhang, J. Liang, J. Cao, B. Wen, R. Timofte and L. Van Gool, “Denoising Diffusion Models for Plug-and-Play Image Restoration,” in Proc. IEEE/CVF CVPR Workshops, 2023, pp. 1219–1229. doi · arXiv
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” in Proc. IEEE/CVF CVPR, 2022, pp. 10674–10685. doi · arXiv
- L. Zhang, A. Rao and M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” in Proc. IEEE/CVF ICCV, 2023, pp. 3813–3824. doi · arXiv
- J. Wang, Z. Yue, S. Zhou, K. C. K. Chan and C. C. Loy, “Exploiting Diffusion Prior for Real-World Image Super-Resolution,” International Journal of Computer Vision, vol. 132, no. 12, pp. 5929–5949, 2024. doi · arXiv
- X. Lin, J. He, Z. Chen, Z. Lyu, B. Dai, F. Yu, Y. Qiao, W. Ouyang and C. Dong, “DiffBIR: Toward Blind Image Restoration with Generative Diffusion Prior,” in Proc. ECCV, 2024 (LNCS), pp. 430–448. doi · arXiv
- F. Yu, J. Gu, Z. Li, J. Hu, X. Kong, X. Wang, J. He, Y. Qiao and C. Dong, “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” in Proc. IEEE/CVF CVPR, 2024, pp. 25669–25680. doi · arXiv
- Y. Wang, W. Yang, X. Chen, Y. Wang, L. Guo, L.-P. Chau, Z. Liu, Y. Qiao, A. C. Kot and B. Wen, “SinSR: Diffusion-Based Image Super-Resolution in a Single Step,” in Proc. IEEE/CVF CVPR, 2024, pp. 25796–25805. doi · arXiv
- R. Wu, L. Sun, Z. Ma and L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” in Proc. NeurIPS, vol. 37, 2024, pp. 92529–92553. doi · arXiv
- Z. Yue, K. Liao and C. C. Loy, “Arbitrary-steps Image Super-resolution via Diffusion Inversion,” in Proc. IEEE/CVF CVPR, 2025, pp. 23153–23163. doi · arXiv
- L. Dong, Q. Fan, Y. Guo, Z. Wang, Q. Zhang, J. Chen, Y. Luo and C. Zou, “TSD-SR: One-Step Diffusion with Target Score Distillation for Real-World Image Super-Resolution,” in Proc. IEEE/CVF CVPR, 2025, pp. 23174–23184. doi · arXiv
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” in Proc. ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” in Proc. ICLR, 2023. arXiv
- G. Ohayon, T. Michaeli and M. Elad, “Posterior-Mean Rectified Flow: Towards Minimum MSE Photo-Realistic Image Restoration,” in Proc. ICLR, 2025. arXiv
- S. Martin, A. Gagneux, P. Hagemann and G. Steidl, “PnP-Flow: Plug-and-Play Image Restoration with Flow Matching,” in Proc. ICLR, 2025. arXiv
- S. Bhadra, V. A. Kelkar, F. J. Brooks and M. A. Anastasio, “On Hallucinations in Tomographic Image Reconstruction,” IEEE Transactions on Medical Imaging, vol. 40, no. 11, pp. 3249–3260, 2021. doi · arXiv
- W. Ren, R. Goyal, Z. Hu, T. T. Aumentado-Armstrong, I. Mohomed and A. Levinshtein, “Hallucination Score: Towards Mitigating Hallucinations in Generative Image Super-Resolution,” arXiv:2507.14367, 2025. arXiv
- A. N. Angelopoulos, A. P. Kohli, S. Bates, M. I. Jordan, J. Malik, T. Alshaabi, S. Upadhyayula and Y. Romano, “Image-to-Image Regression with Distribution-Free Uncertainty Quantification and Applications in Imaging,” in Proc. ICML, PMLR 162, 2022. proceedings · arXiv
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler and S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” in Proc. NeurIPS (NIPS), 2017. arXiv
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a ‘Completely Blind’ Image Quality Analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar and F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” in Proc. IEEE/CVF ICCV, 2021, pp. 5128–5137. doi · arXiv
- J. Wang, K. C. K. Chan and C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” in Proc. AAAI, vol. 37, no. 2, 2023, pp. 2555–2563. doi · arXiv
- X. Li, Y. Ren, X. Jin, C. Lan, X. Wang, W. Zeng, X. Wang and Z. Chen, “Diffusion Models for Image Restoration and Enhancement: A Comprehensive Survey,” International Journal of Computer Vision, vol. 133, no. 11, pp. 8078–8108, 2025. doi · arXiv
- G. Daras, H. Chung, C.-H. Lai, Y. Mitsufuji, J. C. Ye, P. Milanfar, A. G. Dimakis and M. Delbracio, “A Survey on Diffusion Models for Inverse Problems,” arXiv:2410.00083, 2024. arXiv
- B. B. Moser, A. S. Shanbhag, F. Raue, S. Frolov, S. Palacio and A. Dengel, “Diffusion Models, Image Super-Resolution, and Everything: A Survey,” IEEE Transactions on Neural Networks and Learning Systems, vol. 36, no. 7, pp. 11793–11813, 2025. doi · arXiv
- W. Xia, Y. Zhang, Y. Yang, J.-H. Xue, B. Zhou and M.-H. Yang, “GAN Inversion: A Survey,” IEEE TPAMI, vol. 45, no. 3, pp. 3121–3138, 2023. doi · arXiv
- Y. Song and S. Ermon, “Generative Modeling by Estimating Gradients of the Data Distribution,” in Proc. NeurIPS, 2019. arXiv
- H. Chung, J. Kim, S. Kim and J. C. Ye, “Parallel Diffusion Models of Operator and Image for Blind Inverse Problems,” in Proc. IEEE/CVF CVPR, 2023, pp. 6059–6069. paper