Esser et al., “Scaling Rectified Flow Transformers for High-Resolution Image Synthesis” (ICML 2024)
Optional · paper guide 2 of 3 for DLCV 12 · Image Generation: From GANs to Text-to-Image Systems. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
Challenge
Stable Diffusion 3’s research paper [20] asks which combination of training objective, time sampling, representation and backbone scales well for text-to-image generation. Changing only the sampler name would not answer that question. The paper studies rectified-flow training and a joint text–image transformer while also changing autoencoder capacity and caption data.
Method
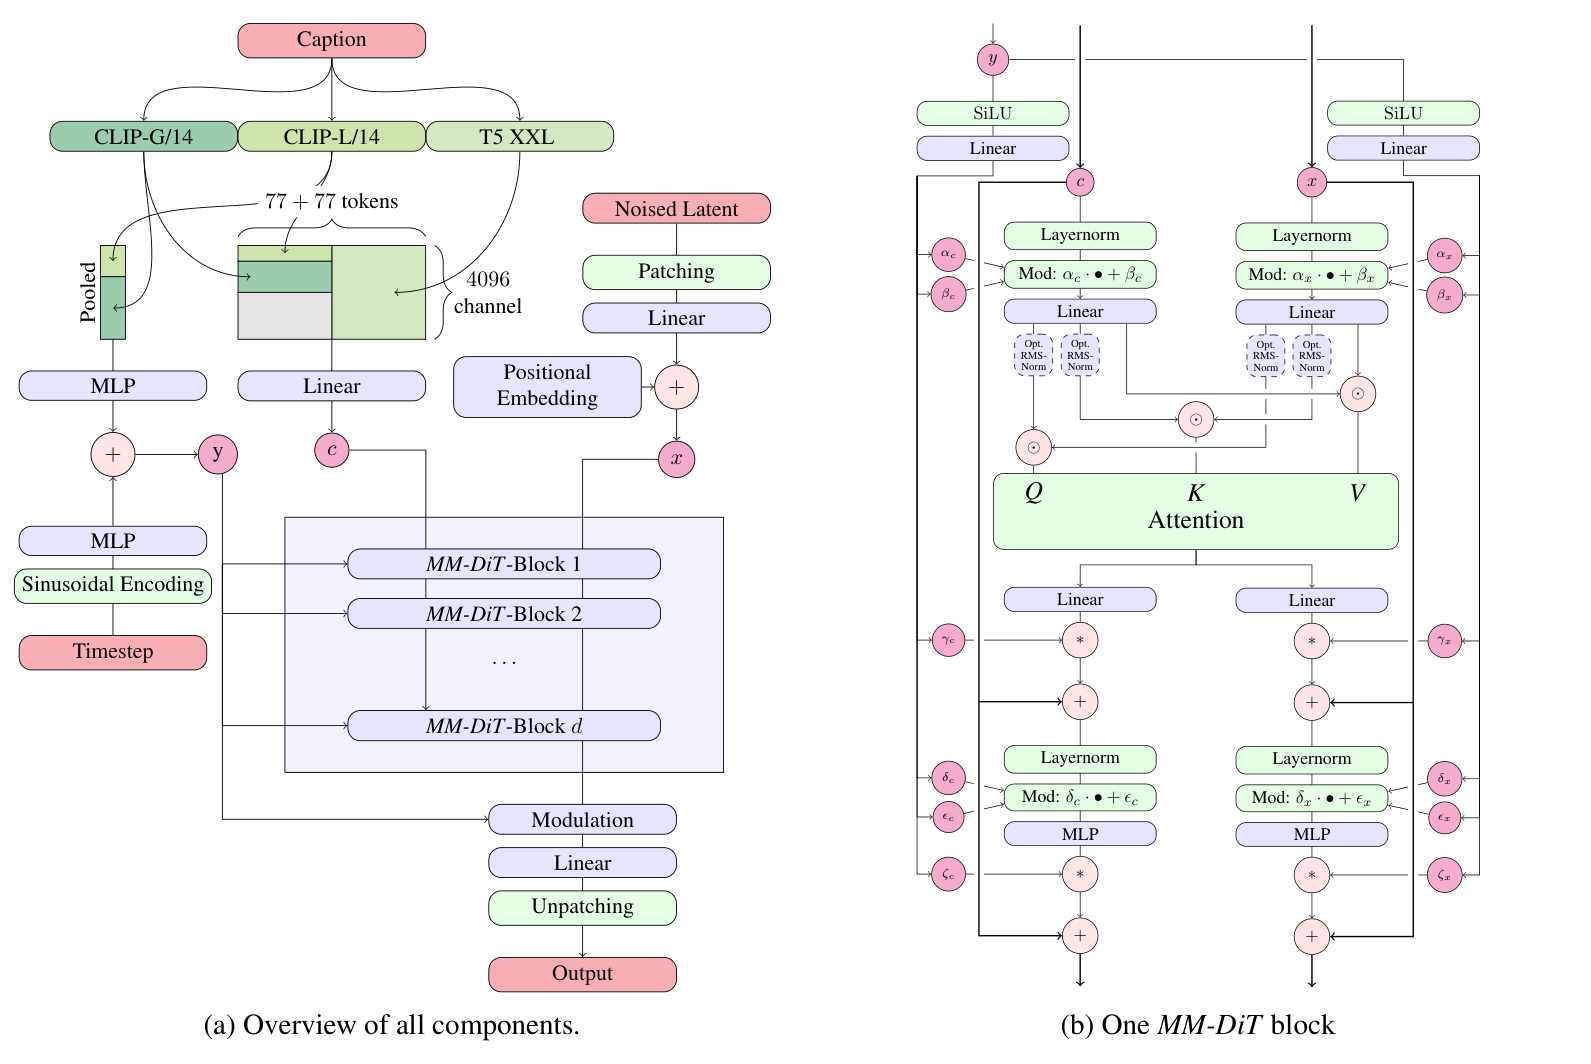
Figure source: [20], PDF page 5. Original PDF.
Regress a velocity along noisy latent paths. Using the paper’s data-to-noise clock,
is a clean image latent, is independent Gaussian noise, is time, denotes text/global conditioning, and predicts velocity. Sampling integrates from noise at toward data at , then decodes. A training pair follows a straight interpolation; the learned marginal flow trajectory need not be exactly straight.
The paper compares distributions for drawing , including logit-normal sampling: draw and set . Here control emphasis on different noise levels. Concentrating training near intermediate times changes error allocation across the path; it is not a declaration that inference must use the same random time distribution.
Let text and image representations interact. MM-DiT projects latent image patches and text representations into compatible token widths. The modalities use separate transformation weights, then concatenate their query/key/value sequences for joint attention. Both streams can be updated using information from the other. This is more specific than adding ordinary one-way text cross-attention to an image-only U-Net.
Conditioning combines two CLIP encoders and T5-XXL. Pooled text features and timestep embeddings modulate blocks, while sequence features participate in attention. Encoder dropout during training makes subsets of text encoders usable at inference; dropping an encoder is still a change to the conditioning setting.
Scale the surrounding system too. The paper increases latent channels, studies model depths up to its 8B configuration, and mixes original captions with generated captions. A stronger autoencoder, richer captions and a larger transformer are separate interventions. The reference guide concerns the ICML 2024 research system, not every later product carrying an SD3-family name.
Read the figure and choose a baseline. Follow text and image tokens into joint attention while keeping their separate transformations in view. Then locate the time condition: it specifies where the noisy latent lies along the training path, not the number of words or an image-quality target. To interpret the final results, make a small ledger of changes to the objective, time distribution, caption mixture, latent channels, model size and preference optimization. A gain from a row that changes several entries cannot isolate MM-DiT alone. The autoencoder reconstruction table and text-to-image alignment table also evaluate different parts of the system.
Results
Table 5 reports overall GenEval 0.68 for the depth-38 model at , 0.71 with preference optimization at that resolution, and 0.74 for the preference-optimized configuration. These rows change optimization and/or resolution and must not be attributed to architecture alone.
Table 3’s autoencoder reconstruction PSNR rises from 25.12 to 28.62 dB when latent channels increase from four to sixteen at the same spatial factor eight. That is a reconstruction result, not a text-to-image PSNR benchmark.
Ablations
Tables 1–2 compare objective/time-sampling variants using controlled smaller experiments and multiple sampling settings. Rectified flow with uniform time sampling does not universally win; tuned time distributions are central to the result, and rankings change with the number of sampling steps.
Table 4 raises overall GenEval from 43.27% to 49.78% when replacing the original-caption-only setup with a 50/50 original/synthetic-caption mixture. Data descriptions can improve alignment independently of the final backbone.
The T5 omission experiment reports approximately 50% aesthetic, 46% prompt-adherence and 38% typography win rates against the full setting. Similar aesthetics therefore do not mean equivalent text rendering. Figure 7 further shows that a larger latent representation needs sufficient prior capacity; low-capacity conclusions need not survive scaling unchanged.
Conclusion
SD3 is a documented combination of flow training, time weighting, multimodal attention and data/representation choices. Its results are best understood by tracking which of those components changed in each experiment.
Problems
Large-scale training data and compute restrict full reproduction. Small-scale ablations do not isolate every interaction in the largest model, and benchmark detectors cover only part of prompt understanding. Typography remains difficult, larger latents increase modeling cost, and human-preference results concern particular prompts and contemporary comparison systems.
References
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” CVPR, 2019. arXiv
- A. Brock, J. Donahue and K. Simonyan, “Large Scale GAN Training for High Fidelity Natural Image Synthesis,” ICLR, 2019. arXiv
- W. Peebles and S. Xie, “Scalable Diffusion Models with Transformers,” ICCV, 2023. CVF
- C. Saharia, W. Chan, S. Saxena et al., “Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding,” NeurIPS, 2022. arXiv · project page
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. CVF
- C. Meng, Y. He, Y. Song et al., “SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations,” ICLR, 2022. arXiv
- L. Zhang, A. Rao and M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” ICCV, 2023. CVF
- A. Hertz, R. Mokady, J. Tenenbaum et al., “Prompt-to-Prompt Image Editing with Cross-Attention Control,” ICLR, 2023. arXiv
- T. Brooks, A. Holynski and A. A. Efros, “InstructPix2Pix: Learning to Follow Image Editing Instructions,” CVPR, 2023. CVF
- A. Lugmayr, M. Danelljan, A. Romero et al., “RePaint: Inpainting using Denoising Diffusion Probabilistic Models,” CVPR, 2022. CVF
- J. Ho and T. Salimans, “Classifier-Free Diffusion Guidance,” NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications; arXiv:2207.12598, 2022. arXiv
- I. J. Goodfellow, J. Pouget-Abadie, M. Mirza et al., “Generative Adversarial Nets,” NeurIPS, 2014. arXiv
- D. P. Kingma and M. Welling, “Auto-Encoding Variational Bayes,” ICLR, 2014. arXiv
- A. van den Oord, O. Vinyals and K. Kavukcuoglu, “Neural Discrete Representation Learning,” NeurIPS, 2017. arXiv
- P. Esser, R. Rombach and B. Ommer, “Taming Transformers for High-Resolution Image Synthesis,” CVPR, 2021. CVF
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. arXiv
- P. Dhariwal and A. Nichol, “Diffusion Models Beat GANs on Image Synthesis,” NeurIPS, 2021. arXiv
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” ICLR, 2023. arXiv
- P. Esser, S. Kulal, A. Blattmann et al., “Scaling Rectified Flow Transformers for High-Resolution Image Synthesis,” ICML, PMLR 235, 2024. arXiv
- T. Li, Y. Tian, H. Li, M. Deng and K. He, “Autoregressive Image Generation without Vector Quantization,” NeurIPS, 2024. arXiv
- A. Sauer, D. Lorenz, A. Blattmann and R. Rombach, “Adversarial Diffusion Distillation,” ECCV, LNCS, pp. 87–103, 2024. doi · arXiv
- A. Radford, J. W. Kim, C. Hallacy et al., “Learning Transferable Visual Models From Natural Language Supervision,” ICML, PMLR 139, 2021. arXiv
- C. Raffel, N. Shazeer, A. Roberts et al., “Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer,” Journal of Machine Learning Research, vol. 21, 2020. arXiv
- D. Podell, Z. English, K. Lacey et al., “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. arXiv
- R. Liu, D. Garrette, C. Saharia et al., “Character-Aware Models Improve Visual Text Rendering,” ACL, 2023. ACL Anthology
- A. Ramesh, P. Dhariwal, A. Nichol, C. Chu and M. Chen, “Hierarchical Text-Conditional Image Generation with CLIP Latents,” arXiv:2204.06125, 2022. arXiv
- H. Chefer, Y. Alaluf, Y. Vinker, L. Wolf and D. Cohen-Or, “Attend-and-Excite: Attention-Based Semantic Guidance for Text-to-Image Diffusion Models,” ACM Transactions on Graphics, vol. 42, no. 4 (SIGGRAPH), 2023. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” MICCAI, 2015. arXiv
- J. Yu, Y. Xu, J. Y. Koh et al., “Scaling Autoregressive Models for Content-Rich Text-to-Image Generation,” Transactions on Machine Learning Research, 2022. arXiv
- H. Chang, H. Zhang, J. Barber et al., “Muse: Text-To-Image Generation via Masked Generative Transformers,” ICML, PMLR 202, 2023. arXiv
- R. Gal, Y. Alaluf, Y. Atzmon et al., “An Image is Worth One Word: Personalizing Text-to-Image Generation using Textual Inversion,” ICLR, 2023. arXiv
- N. Ruiz, Y. Li, V. Jampani, Y. Pritch, M. Rubinstein and K. Aberman, “DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation,” CVPR, 2023. CVF
- E. J. Hu, Y. Shen, P. Wallis et al., “LoRA: Low-Rank Adaptation of Large Language Models,” ICLR, 2022. arXiv
- Y. Huang, J. Huang, Y. Liu et al., “Diffusion Model-Based Image Editing: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2025. doi · arXiv
- J. Song, C. Meng and S. Ermon, “Denoising Diffusion Implicit Models,” ICLR, 2021. arXiv
- T. Salimans and J. Ho, “Progressive Distillation for Fast Sampling of Diffusion Models,” ICLR, 2022. arXiv
- Y. Song, P. Dhariwal, M. Chen and I. Sutskever, “Consistency Models,” ICML, PMLR 202, 2023. arXiv
- P. Sun, Y. Jiang, S. Chen et al., “Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation,” arXiv:2406.06525, 2024. arXiv
- H. Chang, H. Zhang, L. Jiang, C. Liu and W. T. Freeman, “MaskGIT: Masked Generative Image Transformer,” CVPR, 2022. CVF
- K. Tian, Y. Jiang, Z. Yuan, B. Peng and L. Wang, “Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction,” NeurIPS, 2024. arXiv
- L. Yu, J. Lezama, N. B. Gundavarapu et al., “Language Model Beats Diffusion — Tokenizer is Key to Visual Generation,” ICLR, 2024. arXiv
- Chameleon Team, “Chameleon: Mixed-Modal Early-Fusion Foundation Models,” arXiv:2405.09818, 2024. arXiv
- X. Wang, Y. Cui, J. Wang et al., “Multimodal learning with next-token prediction for large multimodal models,” Nature, vol. 650, pp. 327–333, 2026 (preprint “Emu3: Next-Token Prediction is All You Need,” 2024). doi · arXiv
- C. Zhou, L. Yu, A. Babu et al., “Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal Model,” ICLR, 2025. arXiv
- J. Xie, W. Mao, Z. Bai et al., “Show-o: One Single Transformer to Unify Multimodal Understanding and Generation,” ICLR, 2025. arXiv
- C. Wu, X. Chen, Z. Wu et al., “Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation,” CVPR, 2025. CVF
- T.-Y. Lin, M. Maire, S. Belongie et al., “Microsoft COCO: Common Objects in Context,” ECCV, 2014. arXiv
- M. J. Chong and D. Forsyth, “Effectively Unbiased FID and Inception Score and Where to Find Them,” CVPR, 2020. arXiv
- G. Parmar, R. Zhang and J.-Y. Zhu, “On Aliased Resizing and Surprising Subtleties in GAN Evaluation,” CVPR, 2022. CVF
- T. Kynkäänniemi, T. Karras, M. Aittala, T. Aila and J. Lehtinen, “The Role of ImageNet Classes in Fréchet Inception Distance,” ICLR, 2023. arXiv
- G. Stein, J. C. Cresswell, R. Hosseinzadeh et al., “Exposing Flaws of Generative Model Evaluation Metrics and Their Unfair Treatment of Diffusion Models,” NeurIPS, 2023. arXiv
- S. Jayasumana, S. Ramalingam, A. Veit, D. Glasner, A. Chakrabarti and S. Kumar, “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. CVF
- J. Hessel, A. Holtzman, M. Forbes, R. Le Bras and Y. Choi, “CLIPScore: A Reference-free Evaluation Metric for Image Captioning,” EMNLP, 2021. ACL Anthology
- D. Ghosh, H. Hajishirzi and L. Schmidt, “GenEval: An Object-Focused Framework for Evaluating Text-to-Image Alignment,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- K. Huang, K. Sun, E. Xie, Z. Li and X. Liu, “T2I-CompBench: A Comprehensive Benchmark for Open-world Compositional Text-to-image Generation,” NeurIPS Datasets and Benchmarks Track, 2023. proceedings
- J. Xu, X. Liu, Y. Wu et al., “ImageReward: Learning and Evaluating Human Preferences for Text-to-Image Generation,” NeurIPS, 2023. arXiv
- Y. Kirstain, A. Polyak, U. Singer et al., “Pick-a-Pic: An Open Dataset of User Preferences for Text-to-Image Generation,” NeurIPS, 2023. arXiv
- T. Lee, M. Yasunaga, C. Meng et al., “Holistic Evaluation of Text-To-Image Models,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A Large-Scale Hierarchical Image Database,” CVPR, 2009. doi
- C. Schuhmann, R. Beaumont, R. Vencu et al., “LAION-5B: An Open Large-Scale Dataset for Training Next Generation Image-Text Models,” NeurIPS Datasets and Benchmarks Track, 2022. arXiv
- A. Birhane, V. U. Prabhu and E. Kahembwe, “Multimodal datasets: misogyny, pornography, and malignant stereotypes,” arXiv:2110.01963, 2021. arXiv
- N. Carlini, J. Hayes, M. Nasr et al., “Extracting Training Data from Diffusion Models,” USENIX Security Symposium, 2023. USENIX · arXiv
- G. Somepalli, V. Singla, M. Goldblum, J. Geiping and T. Goldstein, “Diffusion Art or Digital Forgery? Investigating Data Replication in Diffusion Models,” CVPR, 2023. CVF
- F. Bianchi, P. Kalluri, E. Durmus et al., “Easily Accessible Text-to-Image Generation Amplifies Demographic Stereotypes at Large Scale,” ACM FAccT, 2023. doi
- A. S. Luccioni, C. Akiki, M. Mitchell and Y. Jernite, “Stable Bias: Analyzing Societal Representations in Diffusion Models,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- Coalition for Content Provenance and Authenticity (C2PA), “C2PA Technical Specification,” version 2.1, 2024. specification
- Y. Wen, J. Kirchenbauer, J. Geiping and T. Goldstein, “Tree-Ring Watermarks: Fingerprints for Diffusion Images that are Invisible and Robust,” NeurIPS, 2023. arXiv
- P. Fernandez, G. Couairon, H. Jégou, M. Douze and T. Furon, “The Stable Signature: Rooting Watermarks in Latent Diffusion Models,” ICCV, 2023. CVF
- X. Zhao, K. Zhang, Z. Su et al., “Invisible Image Watermarks Are Provably Removable Using Generative AI,” NeurIPS, 2024. arXiv
- M. Saberi, V. S. Sadasivan, K. Rezaei et al., “Robustness of AI-Image Detectors: Fundamental Limits and Practical Attacks,” ICLR, 2024. arXiv
- W. Lu, Y. Xu, J. Zhang, C. Wang and D. Tao, “HandRefiner: Refining Malformed Hands in Generated Images by Diffusion-based Conditional Inpainting,” ACM Multimedia, 2024, pp. 7085–7093. doi
- C. Zhang, C. Zhang, M. Zhang, I. S. Kweon and J. Kim, “Text-to-image Diffusion Models in Generative AI: A Survey,” arXiv:2303.07909, 2023. arXiv
- F.-A. Croitoru, V. Hondru, R. T. Ionescu and M. Shah, “Diffusion Models in Vision: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023. doi
- J. Xiong, G. Liu, L. Huang et al., “Autoregressive Models in Vision: A Survey,” Transactions on Machine Learning Research, 2025. arXiv