Esser 等人:Scaling Rectified Flow Transformers for High-Resolution Image Synthesis(ICML 2024)
選讀・DLCV 12・影像生成:從 GAN 到文字生成影像系統 的論文導讀(第 2/3 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
Stable Diffusion 3 的研究論文 [20] 問的是:什麼訓練目標、時間取樣、表示與骨幹組合,能有效擴展文字生成影像?只改取樣器名稱,無法回答此問題。原文研究整流流訓練與文字—影像聯合 Transformer,同時也改變自編碼器容量與描述資料。
方法
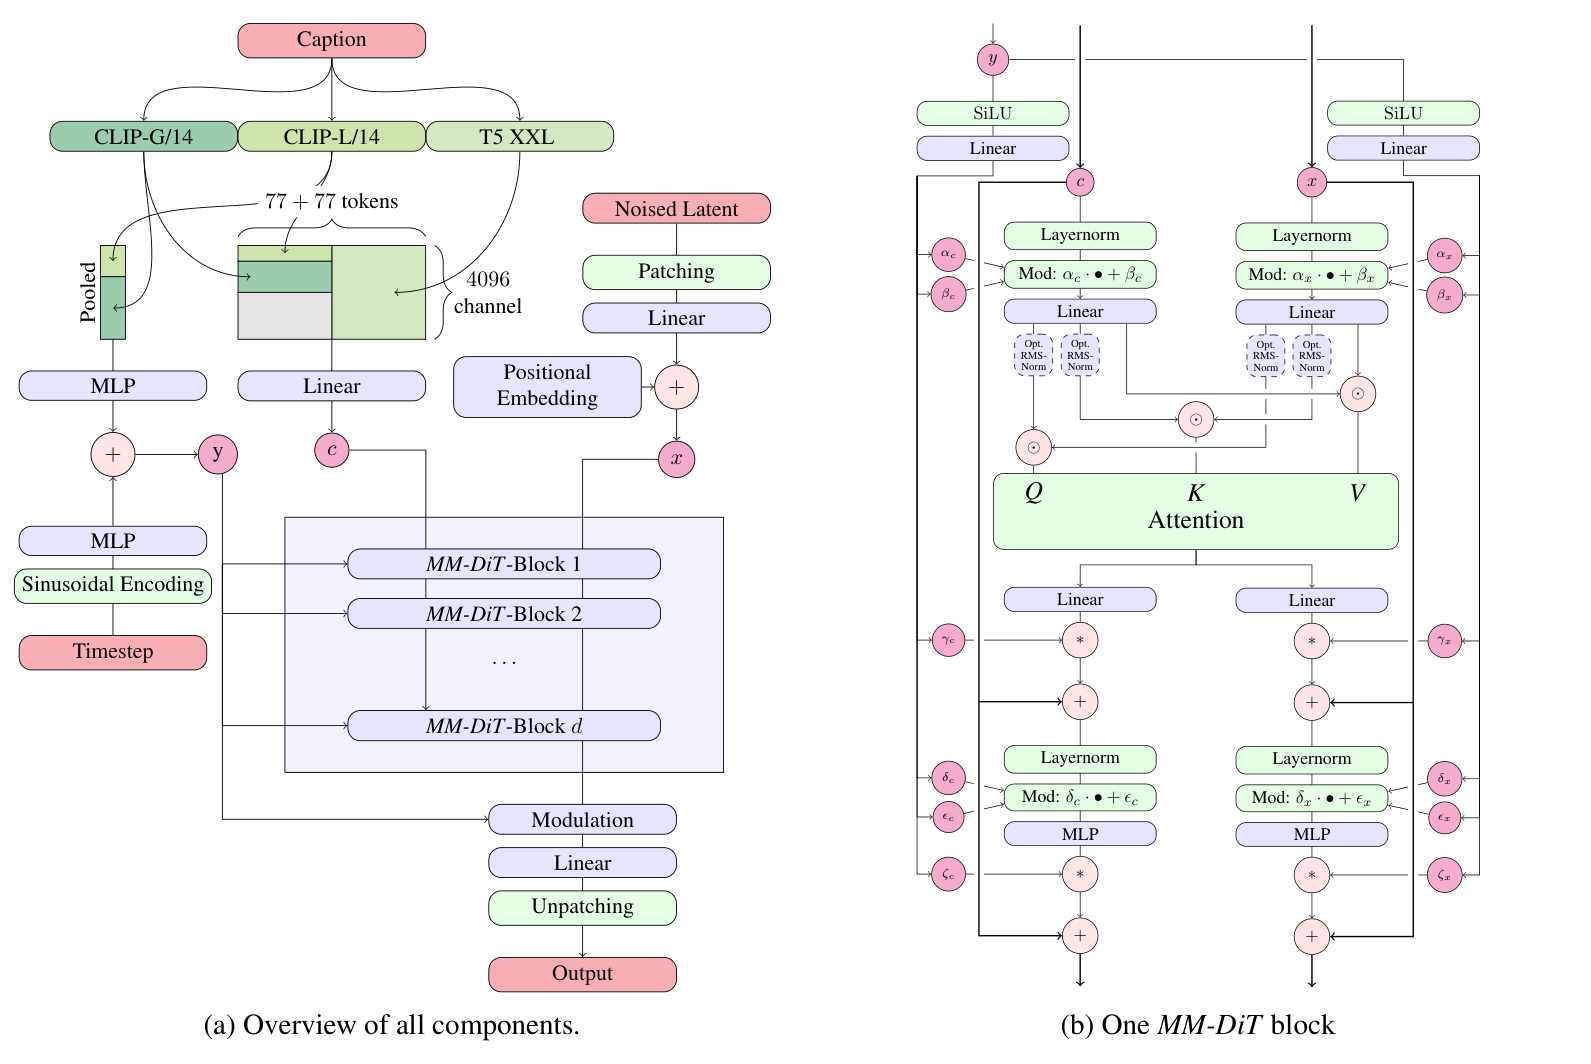
圖片來源: [20], PDF 第 5 頁. 原始 PDF.
沿帶雜訊潛在路徑迴歸速度。 採原文從資料到雜訊的時鐘,
是乾淨影像潛在, 是獨立高斯雜訊, 為時間, 是文字/全域條件, 預測速度。取樣從 的雜訊反向積分至 ,再解碼。單一訓練配對採直線內插,不代表學到的邊際流軌跡必定完全筆直。
原文比較抽取 的分布,包含 logit-normal:先抽 ,再令 。 控制不同雜訊程度的訓練比重。集中於中間時間會改變路徑各處的誤差配置,不表示推論必須用同一隨機時間分布。
讓文字與影像表示互動。 MM-DiT 把潛在影像區塊與文字表示投影到相容詞元寬度。兩模態使用獨立轉換權重,再把查詢/鍵/值序列串接做聯合注意力,兩路都能依對方資訊更新。這比在影像 U-Net 加一般單向文字交叉注意力更具體。
條件組合兩個 CLIP 編碼器與 T5-XXL。池化文字特徵、時間嵌入用來調變區塊,序列特徵參與注意力。訓練時的編碼器丟棄讓推論可使用文字編碼器子集;但移除編碼器仍是條件設定的改變。
也擴展周邊系統。 原文增加潛在通道、把模型深度擴至 8B 配置,並混合原始與生成描述。更強自編碼器、更豐富描述、更大 Transformer 是不同介入。本導讀針對 ICML 2024 研究系統,不把它等同所有後續 SD3 系列產品。
讀圖與選用判斷。 追蹤文字與影像 token 如何進入聯合注意力,同時留意兩者各自的轉換。再找到時間條件:它指出帶雜訊潛在值在訓練路徑上的位置,不是字數或影像品質目標。解讀最終結果時,可列出目標函數、時間分布、描述文字組合、潛在通道數、模型大小與偏好最佳化有哪些改變。若某一列同時改了多項,就不能單獨歸因於 MM-DiT。自動編碼器重建表與文字生圖對齊表,也是在評估系統的不同部分。
結果
表 5 的深度 38 模型在 的整體 GenEval 為 0.68,同解析度加入偏好最佳化為 0.71,偏好最佳化的 配置則為 0.74。這些列改變了最佳化與/或解析度,不能只歸因於架構。
表 3 在固定空間倍率八時,把潛在通道從四增加到十六,重建 PSNR 由 25.12 升至 28.62 dB。這是自編碼器重建結果,不是文字生成影像的 PSNR 基準。
消融實驗
表 1–2 以受控的小型實驗、不同取樣設定比較目標與時間分布。均勻時間取樣的整流流不會普遍勝出;時間分布調整是主要結果的一部分,排名也隨取樣步數改變。
表 4 從只用原始描述改為原始/合成描述各半,整體 GenEval 由 43.27% 升為 49.78%。資料描述本身就能改善對齊,不只取決於最後骨幹。
移除 T5 的實驗,相對完整設定的美感、提示遵循、文字呈現勝率約為 50%、46%、38%。美感接近,不表示文字渲染等價。圖 7 也指出更大的潛在表示需要足夠先驗容量,低容量的結論未必原樣延續到擴展後的模型。
結論
SD3 是有完整紀錄的組合設計,包含流訓練、時間加權、多模態注意力、資料與表示選擇。應追蹤各實驗究竟改變哪些元件,才能理解結果。
限制與問題
大規模資料與運算限制完整重現。小規模消融不能分離最大模型內的所有交互作用;基準偵測器也只涵蓋部分提示理解。文字呈現仍困難,更大潛在會增加建模成本,人類偏好結果則受特定提示與當時比較系統影響。
參考文獻
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” CVPR, 2019. arXiv
- A. Brock, J. Donahue and K. Simonyan, “Large Scale GAN Training for High Fidelity Natural Image Synthesis,” ICLR, 2019. arXiv
- W. Peebles and S. Xie, “Scalable Diffusion Models with Transformers,” ICCV, 2023. CVF
- C. Saharia, W. Chan, S. Saxena et al., “Photorealistic Text-to-Image Diffusion Models with Deep Language Understanding,” NeurIPS, 2022. arXiv · project page
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. CVF
- C. Meng, Y. He, Y. Song et al., “SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations,” ICLR, 2022. arXiv
- L. Zhang, A. Rao and M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” ICCV, 2023. CVF
- A. Hertz, R. Mokady, J. Tenenbaum et al., “Prompt-to-Prompt Image Editing with Cross-Attention Control,” ICLR, 2023. arXiv
- T. Brooks, A. Holynski and A. A. Efros, “InstructPix2Pix: Learning to Follow Image Editing Instructions,” CVPR, 2023. CVF
- A. Lugmayr, M. Danelljan, A. Romero et al., “RePaint: Inpainting using Denoising Diffusion Probabilistic Models,” CVPR, 2022. CVF
- J. Ho and T. Salimans, “Classifier-Free Diffusion Guidance,” NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications; arXiv:2207.12598, 2022. arXiv
- I. J. Goodfellow, J. Pouget-Abadie, M. Mirza et al., “Generative Adversarial Nets,” NeurIPS, 2014. arXiv
- D. P. Kingma and M. Welling, “Auto-Encoding Variational Bayes,” ICLR, 2014. arXiv
- A. van den Oord, O. Vinyals and K. Kavukcuoglu, “Neural Discrete Representation Learning,” NeurIPS, 2017. arXiv
- P. Esser, R. Rombach and B. Ommer, “Taming Transformers for High-Resolution Image Synthesis,” CVPR, 2021. CVF
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. arXiv
- P. Dhariwal and A. Nichol, “Diffusion Models Beat GANs on Image Synthesis,” NeurIPS, 2021. arXiv
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” ICLR, 2023. arXiv
- P. Esser, S. Kulal, A. Blattmann et al., “Scaling Rectified Flow Transformers for High-Resolution Image Synthesis,” ICML, PMLR 235, 2024. arXiv
- T. Li, Y. Tian, H. Li, M. Deng and K. He, “Autoregressive Image Generation without Vector Quantization,” NeurIPS, 2024. arXiv
- A. Sauer, D. Lorenz, A. Blattmann and R. Rombach, “Adversarial Diffusion Distillation,” ECCV, LNCS, pp. 87–103, 2024. doi · arXiv
- A. Radford, J. W. Kim, C. Hallacy et al., “Learning Transferable Visual Models From Natural Language Supervision,” ICML, PMLR 139, 2021. arXiv
- C. Raffel, N. Shazeer, A. Roberts et al., “Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer,” Journal of Machine Learning Research, vol. 21, 2020. arXiv
- D. Podell, Z. English, K. Lacey et al., “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. arXiv
- R. Liu, D. Garrette, C. Saharia et al., “Character-Aware Models Improve Visual Text Rendering,” ACL, 2023. ACL Anthology
- A. Ramesh, P. Dhariwal, A. Nichol, C. Chu and M. Chen, “Hierarchical Text-Conditional Image Generation with CLIP Latents,” arXiv:2204.06125, 2022. arXiv
- H. Chefer, Y. Alaluf, Y. Vinker, L. Wolf and D. Cohen-Or, “Attend-and-Excite: Attention-Based Semantic Guidance for Text-to-Image Diffusion Models,” ACM Transactions on Graphics, vol. 42, no. 4 (SIGGRAPH), 2023. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” MICCAI, 2015. arXiv
- J. Yu, Y. Xu, J. Y. Koh et al., “Scaling Autoregressive Models for Content-Rich Text-to-Image Generation,” Transactions on Machine Learning Research, 2022. arXiv
- H. Chang, H. Zhang, J. Barber et al., “Muse: Text-To-Image Generation via Masked Generative Transformers,” ICML, PMLR 202, 2023. arXiv
- R. Gal, Y. Alaluf, Y. Atzmon et al., “An Image is Worth One Word: Personalizing Text-to-Image Generation using Textual Inversion,” ICLR, 2023. arXiv
- N. Ruiz, Y. Li, V. Jampani, Y. Pritch, M. Rubinstein and K. Aberman, “DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation,” CVPR, 2023. CVF
- E. J. Hu, Y. Shen, P. Wallis et al., “LoRA: Low-Rank Adaptation of Large Language Models,” ICLR, 2022. arXiv
- Y. Huang, J. Huang, Y. Liu et al., “Diffusion Model-Based Image Editing: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2025. doi · arXiv
- J. Song, C. Meng and S. Ermon, “Denoising Diffusion Implicit Models,” ICLR, 2021. arXiv
- T. Salimans and J. Ho, “Progressive Distillation for Fast Sampling of Diffusion Models,” ICLR, 2022. arXiv
- Y. Song, P. Dhariwal, M. Chen and I. Sutskever, “Consistency Models,” ICML, PMLR 202, 2023. arXiv
- P. Sun, Y. Jiang, S. Chen et al., “Autoregressive Model Beats Diffusion: Llama for Scalable Image Generation,” arXiv:2406.06525, 2024. arXiv
- H. Chang, H. Zhang, L. Jiang, C. Liu and W. T. Freeman, “MaskGIT: Masked Generative Image Transformer,” CVPR, 2022. CVF
- K. Tian, Y. Jiang, Z. Yuan, B. Peng and L. Wang, “Visual Autoregressive Modeling: Scalable Image Generation via Next-Scale Prediction,” NeurIPS, 2024. arXiv
- L. Yu, J. Lezama, N. B. Gundavarapu et al., “Language Model Beats Diffusion — Tokenizer is Key to Visual Generation,” ICLR, 2024. arXiv
- Chameleon Team, “Chameleon: Mixed-Modal Early-Fusion Foundation Models,” arXiv:2405.09818, 2024. arXiv
- X. Wang, Y. Cui, J. Wang et al., “Multimodal learning with next-token prediction for large multimodal models,” Nature, vol. 650, pp. 327–333, 2026 (preprint “Emu3: Next-Token Prediction is All You Need,” 2024). doi · arXiv
- C. Zhou, L. Yu, A. Babu et al., “Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal Model,” ICLR, 2025. arXiv
- J. Xie, W. Mao, Z. Bai et al., “Show-o: One Single Transformer to Unify Multimodal Understanding and Generation,” ICLR, 2025. arXiv
- C. Wu, X. Chen, Z. Wu et al., “Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation,” CVPR, 2025. CVF
- T.-Y. Lin, M. Maire, S. Belongie et al., “Microsoft COCO: Common Objects in Context,” ECCV, 2014. arXiv
- M. J. Chong and D. Forsyth, “Effectively Unbiased FID and Inception Score and Where to Find Them,” CVPR, 2020. arXiv
- G. Parmar, R. Zhang and J.-Y. Zhu, “On Aliased Resizing and Surprising Subtleties in GAN Evaluation,” CVPR, 2022. CVF
- T. Kynkäänniemi, T. Karras, M. Aittala, T. Aila and J. Lehtinen, “The Role of ImageNet Classes in Fréchet Inception Distance,” ICLR, 2023. arXiv
- G. Stein, J. C. Cresswell, R. Hosseinzadeh et al., “Exposing Flaws of Generative Model Evaluation Metrics and Their Unfair Treatment of Diffusion Models,” NeurIPS, 2023. arXiv
- S. Jayasumana, S. Ramalingam, A. Veit, D. Glasner, A. Chakrabarti and S. Kumar, “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. CVF
- J. Hessel, A. Holtzman, M. Forbes, R. Le Bras and Y. Choi, “CLIPScore: A Reference-free Evaluation Metric for Image Captioning,” EMNLP, 2021. ACL Anthology
- D. Ghosh, H. Hajishirzi and L. Schmidt, “GenEval: An Object-Focused Framework for Evaluating Text-to-Image Alignment,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- K. Huang, K. Sun, E. Xie, Z. Li and X. Liu, “T2I-CompBench: A Comprehensive Benchmark for Open-world Compositional Text-to-image Generation,” NeurIPS Datasets and Benchmarks Track, 2023. proceedings
- J. Xu, X. Liu, Y. Wu et al., “ImageReward: Learning and Evaluating Human Preferences for Text-to-Image Generation,” NeurIPS, 2023. arXiv
- Y. Kirstain, A. Polyak, U. Singer et al., “Pick-a-Pic: An Open Dataset of User Preferences for Text-to-Image Generation,” NeurIPS, 2023. arXiv
- T. Lee, M. Yasunaga, C. Meng et al., “Holistic Evaluation of Text-To-Image Models,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A Large-Scale Hierarchical Image Database,” CVPR, 2009. doi
- C. Schuhmann, R. Beaumont, R. Vencu et al., “LAION-5B: An Open Large-Scale Dataset for Training Next Generation Image-Text Models,” NeurIPS Datasets and Benchmarks Track, 2022. arXiv
- A. Birhane, V. U. Prabhu and E. Kahembwe, “Multimodal datasets: misogyny, pornography, and malignant stereotypes,” arXiv:2110.01963, 2021. arXiv
- N. Carlini, J. Hayes, M. Nasr et al., “Extracting Training Data from Diffusion Models,” USENIX Security Symposium, 2023. USENIX · arXiv
- G. Somepalli, V. Singla, M. Goldblum, J. Geiping and T. Goldstein, “Diffusion Art or Digital Forgery? Investigating Data Replication in Diffusion Models,” CVPR, 2023. CVF
- F. Bianchi, P. Kalluri, E. Durmus et al., “Easily Accessible Text-to-Image Generation Amplifies Demographic Stereotypes at Large Scale,” ACM FAccT, 2023. doi
- A. S. Luccioni, C. Akiki, M. Mitchell and Y. Jernite, “Stable Bias: Analyzing Societal Representations in Diffusion Models,” NeurIPS Datasets and Benchmarks Track, 2023. arXiv
- Coalition for Content Provenance and Authenticity (C2PA), “C2PA Technical Specification,” version 2.1, 2024. specification
- Y. Wen, J. Kirchenbauer, J. Geiping and T. Goldstein, “Tree-Ring Watermarks: Fingerprints for Diffusion Images that are Invisible and Robust,” NeurIPS, 2023. arXiv
- P. Fernandez, G. Couairon, H. Jégou, M. Douze and T. Furon, “The Stable Signature: Rooting Watermarks in Latent Diffusion Models,” ICCV, 2023. CVF
- X. Zhao, K. Zhang, Z. Su et al., “Invisible Image Watermarks Are Provably Removable Using Generative AI,” NeurIPS, 2024. arXiv
- M. Saberi, V. S. Sadasivan, K. Rezaei et al., “Robustness of AI-Image Detectors: Fundamental Limits and Practical Attacks,” ICLR, 2024. arXiv
- W. Lu, Y. Xu, J. Zhang, C. Wang and D. Tao, “HandRefiner: Refining Malformed Hands in Generated Images by Diffusion-based Conditional Inpainting,” ACM Multimedia, 2024, pp. 7085–7093. doi
- C. Zhang, C. Zhang, M. Zhang, I. S. Kweon and J. Kim, “Text-to-image Diffusion Models in Generative AI: A Survey,” arXiv:2303.07909, 2023. arXiv
- F.-A. Croitoru, V. Hondru, R. T. Ionescu and M. Shah, “Diffusion Models in Vision: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023. doi
- J. Xiong, G. Liu, L. Huang et al., “Autoregressive Models in Vision: A Survey,” Transactions on Machine Learning Research, 2025. arXiv