Retinexformer: illumination guides restoration
Optional · paper guide 7 of 13 for DLCV 09C · Low-Light Image Enhancement. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- CLAHE: equalizing locally without amplifying noise
- More deep LLIE methods
- Counting resolution, arithmetic and memory
- A bilateral-grid experiment
- Implementing and checking trilinear LUTs
- Fitting and slicing a bilateral grid in detail
- Learnable LUT variants in detail
- Structural re-parameterization step by step
- Understanding no-reference low-light metrics
- Efficient network building blocks
- Banding, halos and temporal stability
- Bilateral grids and color-table mathematics
- From retouching to low light
- A lightness-order exercise
- KinD: repair reflectance while controlling illumination
- Retinex-Net: decompose, adjust and denoise
- EnlightenGAN: unpaired appearance learning with content constraints
- Zero-DCE and Zero-DCE++: learn curves without reference images
- RUAS: search the priors inside an unrolled enhancement model
- SCI: train with calibration, deploy one illumination block
- Retinexformer: illumination guides restoration
- IAT: local affine maps and a global camera-style transform
- Multinex: fuse analytic priors into a Retinex residual
- CPGA-Net: channel priors, gamma estimation and learned fusion
- CPGA-Net+: attention, BDSF and stronger variants
- HDRNet: deep bilateral learning for real-time image enhancement
- Image-adaptive 3D LUTs (Zeng et al., TPAMI 2022)
Deep Learning for Computer Vision
Challenge
Real low-light images violate a clean reflectance-times-illumination model: sensor noise and illumination-estimation errors remain after brightening. Retinexformer [22] treats the lit-up image as an intermediate result that still needs restoration. It also avoids full all-pairs spatial attention at every resolution by performing illumination-guided attention across feature channels.
Method
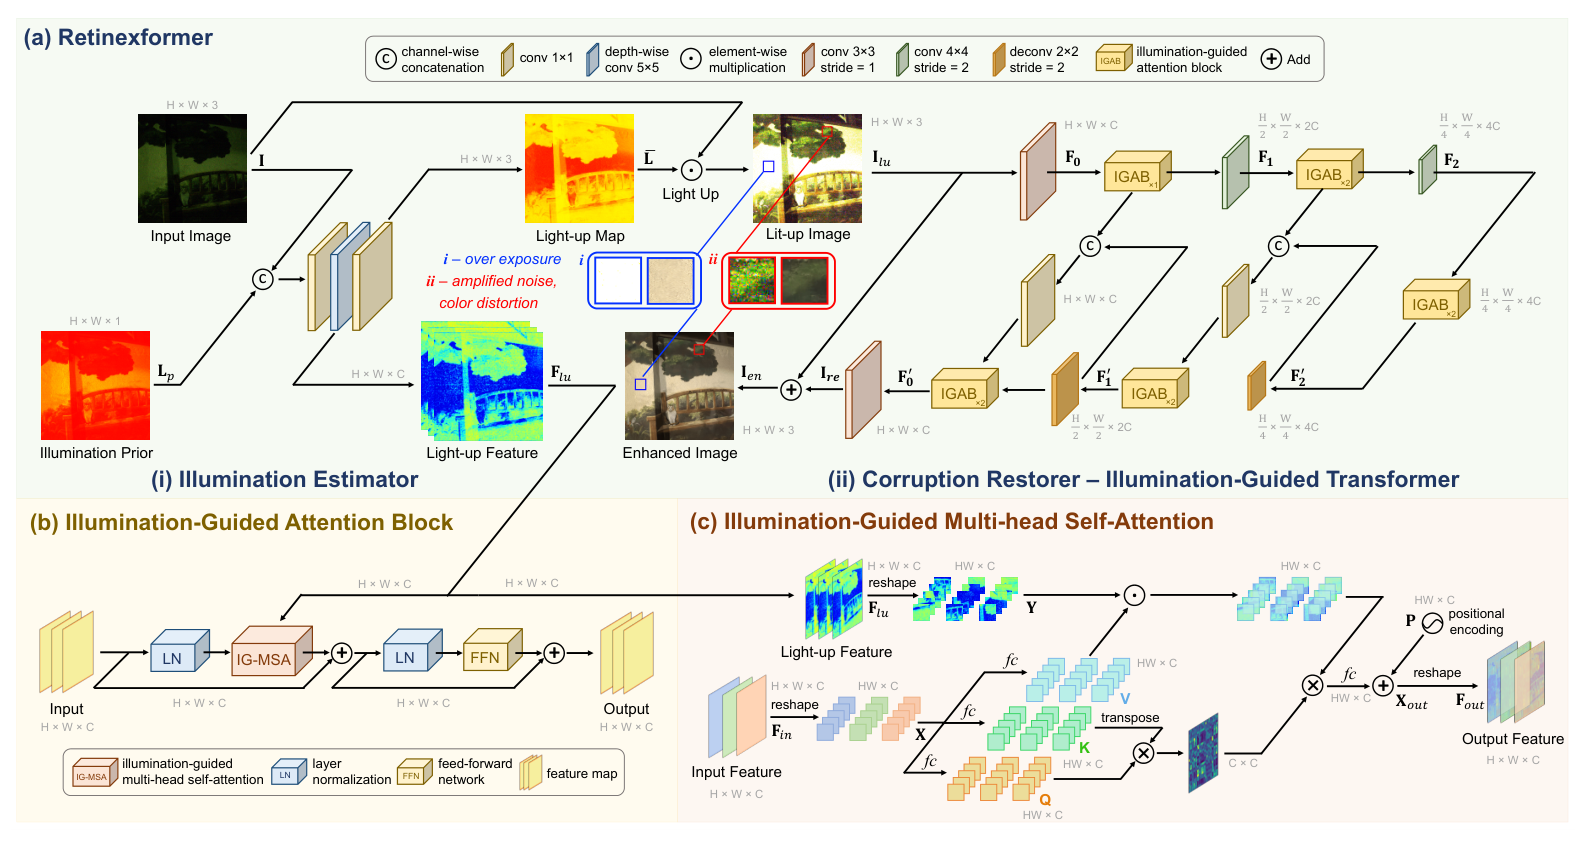
Figure source: [22], arXiv:2303.06705v3, PDF page 3. Original PDF.
A perturbed model motivates two components. With reflectance , illumination and perturbations , the observed image is modeled as . Multiplying by a learned light-up map leads conceptually to
Here is RGB input, is its lit-up version and collects amplified noise, artifacts and illumination error. This motivates an illumination estimator followed by a corruption restorer. The equation is a modeling explanation, not measured supervision for each perturbation tensor.
Illumination estimation predicts a multiplier and features. Concatenate the RGB input with its channel-mean prior map, giving four input channels. A 1 × 1 convolution mixes them; a depthwise 5 × 5 operation models local interaction and produces illumination features . A final 1 × 1 projection predicts a three-channel light-up map. Here is feature width, distinct from the corruption image . Three output channels permit different color corrections. Predicting a multiplier avoids explicitly dividing by an estimated illumination that may be near zero, although the multiplier itself still needs suitable learned behavior.
A three-scale restorer corrects the lit-up result. The U-shaped network processes feature maps at full, half and quarter spatial resolution, with increasing channel width. Strided convolutions downsample; transposed convolutions upsample; skip connections retain corresponding local features. Illumination-guided attention blocks combine layer normalization, attention, a feed-forward network and residual paths. The final prediction is a residual added to , so restoration can correct brightness errors as well as noise.
Attention is channel-to-channel. For one head, reshape features to , then project to of that shape. Reshape the corresponding illumination features to . The paper’s head computation is
Here is per-head width, is a learned scaling parameter, and is the output. The attention matrix is , not . Illumination features modulate the values, while channel interactions summarize information over spatial positions. Several heads are concatenated and projected, with a positional contribution. Illumination features are downsampled to match each restoration scale.
The two attention matrix products cost on the order of per head at fixed width. This is linear in pixel count for that attention operation, but does not mean the complete model has no convolution, projection, memory or multiscale costs. It is also different from a windowed spatial Transformer such as SwinFusion.
Paired training learns both components jointly. The paper uses an L1/MAE image reconstruction objective, Adam for 250,000 iterations, initial learning rate decaying to , 128 × 128 crops and batch size eight. There are no measured ground-truth illumination maps. Each dataset/model setting must be kept separate when interpreting the benchmark table.
Results
Table 1 reports LOL-v1 25.16/0.845 PSNR/SSIM, LOL-v2-real 22.80/0.840 and SDSD-outdoor 29.84/0.877. On LOL-v2-real, SNR-Net’s SSIM 0.849 is higher than 0.840, despite Retinexformer’s higher PSNR. The result is therefore not a win in every column. The model has 1.61 M parameters and 15.57 G FLOPs at 256 × 256 in the ablation protocol.
The ExDark detection experiment reports average AP 66.1, using enhancement as preprocessing with fixed enhancement parameters and a detector trained from scratch. It measures a trained downstream pipeline, not necessarily a plug-in improvement for an unchanged pretrained detector. FiveK and converted raw-image datasets in the broader evaluation also have different meanings from native raw restoration.
Ablations
Table 4 uses SDSD-outdoor. Baseline-1 gives 26.47/0.843 PSNR/SSIM; adding the one-stage Retinex framework gives 27.92/0.857; adding illumination-guided attention without that framework gives 28.86/0.868; combining both gives 29.84/0.877. Parameter/FLOP counts also grow, so the table is not a constant-compute comparison.
The light-up/feature ablation reports PSNR 28.86 without light-up, 28.97 for division-based light-up, 29.26 for a multiplier and 29.84 when illumination features also guide restoration. The attention comparison reports 27.92 for its baseline, 28.43 with global spatial attention, 28.65 with window attention and 29.84 with illumination-guided attention. These test representation and interaction choices within the disclosed setup.
Conclusion
Retinexformer separates initial light-up from subsequent restoration and uses illumination features to guide an efficient channel-attention mechanism. Its contribution depends on the combined representation, restoration backbone and paired training; “Retinex plus Transformer” alone does not specify the method.
Problems
Paired training inherits the reference exposure and camera domain. A learned multiplier can still amplify noise, and restoration can smooth or hallucinate unsupported structure. Channel-attention efficiency does not establish phone latency at full resolution. Evaluate color, temporal consistency and downstream generalization separately from paired PSNR; the chapter’s metric and GT-mean cautions remain applicable.
References
- Shyandram, “簡介Deep Learning Low-Light Image Enhancement (LLIE)” (Introduction to deep-learning low-light image enhancement, in Chinese), Medium post, 2024; updated 2026. link
- A. Foi, M. Trimeche, V. Katkovnik and K. Egiazarian, “Practical Poissonian-Gaussian noise modeling and fitting for single-image raw-data,” IEEE Transactions on Image Processing, vol. 17, no. 10, pp. 1737–1754, 2008. doi
- K. He, J. Sun and X. Tang, “Single image haze removal using dark channel prior,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 33, no. 12, pp. 2341–2353, 2011. doi
- X. Guo, Y. Li and H. Ling, “LIME: Low-light image enhancement via illumination map estimation,” IEEE Transactions on Image Processing, vol. 26, no. 2, pp. 982–993, 2017. doi
- ITU-R, “Recommendation BT.601-7: Studio encoding parameters of digital television for standard 4:3 and wide-screen 16:9 aspect ratios,” 2011. ITU
- Q. Yan, Y. Feng, C. Zhang, et al., “HVI: A new color space for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2025. arXiv
- S. M. Pizer, E. P. Amburn, J. D. Austin, et al., “Adaptive histogram equalization and its variations,” Computer Vision, Graphics, and Image Processing, vol. 39, no. 3, pp. 355–368, 1987. doi
- K. Zuiderveld, “Contrast limited adaptive histogram equalization,” in Graphics Gems IV, Academic Press, 1994, pp. 474–485. doi
- E. H. Land, “The retinex theory of color vision,” Scientific American, vol. 237, no. 6, pp. 108–128, 1977. doi
- D. J. Jobson, Z. Rahman and G. A. Woodell, “Properties and performance of a center/surround retinex,” IEEE Transactions on Image Processing, vol. 6, pp. 451–462, 1997. doi
- D. J. Jobson, Z. Rahman and G. A. Woodell, “A multiscale retinex for bridging the gap between color images and the human observation of scenes,” IEEE Transactions on Image Processing, vol. 6, no. 7, pp. 965–976, 1997. doi
- X. Dong, Y. Pang and J. Wen, “Fast efficient algorithm for enhancement of low lighting video,” ACM SIGGRAPH 2010 Posters, 2010. SIGGRAPH history doi
- S. Wang, J. Zheng, H.-M. Hu and B. Li, “Naturalness preserved enhancement algorithm for non-uniform illumination images,” IEEE Transactions on Image Processing, vol. 22, no. 9, pp. 3538–3548, 2013. doi
- C. Lee, C. Lee and C.-S. Kim, “Contrast enhancement based on layered difference representation of 2D histograms,” IEEE Transactions on Image Processing, vol. 22, no. 12, pp. 5372–5384, 2013. doi
- C. Li, C. Guo, L. Han, J. Jiang, M.-M. Cheng, J. Gu and C. C. Loy, “Low-light image and video enhancement using deep learning: A survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 12, pp. 9396–9416, 2022. arXiv
- C. Wei, W. Wang, W. Yang and J. Liu, “Deep retinex decomposition for low-light enhancement,” in Proc. British Machine Vision Conference (BMVC), 2018. arXiv project
- Y. Jiang, X. Gong, D. Liu, et al., “EnlightenGAN: Deep light enhancement without paired supervision,” IEEE Transactions on Image Processing, vol. 30, pp. 2340–2349, 2021. arXiv
- C. Guo, C. Li, J. Guo, et al., “Zero-reference deep curve estimation for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2020, pp. 1777–1786. arXiv
- C. Li, C. Guo and C. C. Loy, “Learning to enhance low-light image via zero-reference deep curve estimation,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 8, 2022. arXiv
- R. Liu, L. Ma, J. Zhang, X. Fan and Z. Luo, “Retinex-inspired unrolling with cooperative prior architecture search for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2021, pp. 10556–10565. arXiv
- L. Ma, T. Ma, R. Liu, X. Fan and Z. Luo, “Toward fast, flexible, and robust low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 5627–5636. arXiv
- Y. Cai, H. Bian, J. Lin, H. Wang, R. Timofte and Y. Zhang, “Retinexformer: One-stage Retinex-based transformer for low-light image enhancement,” in Proc. IEEE/CVF ICCV, 2023. arXiv code
- Y. Wang, R. Wan, W. Yang, H. Li, L.-P. Chau and A. C. Kot, “Low-light image enhancement with normalizing flow,” in Proc. AAAI Conference on Artificial Intelligence, vol. 36, no. 3, pp. 2604–2612, 2022. arXiv
- X. Yi, H. Xu, H. Zhang, L. Tang and J. Ma, “Diff-Retinex: Rethinking low-light image enhancement with a generative diffusion model,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- J. Hou, Z. Zhu, J. Hou, H. Liu, H. Zeng and H. Yuan, “Global structure-aware diffusion process for low-light image enhancement,” in Advances in Neural Information Processing Systems (NeurIPS), 2023. arXiv
- H. Jiang, A. Luo, X. Liu, S. Han and S. Liu, “LightenDiffusion: Unsupervised low-light image enhancement with latent-Retinex diffusion models,” in Proc. European Conference on Computer Vision (ECCV), 2024. arXiv
- C. He, C. Fang, Y. Zhang, et al., “Reti-Diff: Illumination degradation image restoration with Retinex-based latent diffusion model,” in Proc. International Conference on Learning Representations (ICLR), 2025. proceedings
- M. Gharbi, J. Chen, J. T. Barron, S. W. Hasinoff and F. Durand, “Deep bilateral learning for real-time image enhancement,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 36, no. 4, art. 118, 2017. doi arXiv
- H. Zeng, J. Cai, L. Li, Z. Cao and L. Zhang, “Learning image-adaptive 3D lookup tables for high performance photo enhancement in real-time,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 4, 2022. doi arXiv
- K. G. Lore, A. Akintayo and S. Sarkar, “LLNet: A deep autoencoder approach to natural low-light image enhancement,” Pattern Recognition, vol. 61, pp. 650–662, 2017. doi
- L. Tao, C. Zhu, J. Song, T. Lu, H. Jia and X. Xie, “Low-light image enhancement using CNN and bright channel prior,” in Proc. IEEE International Conference on Image Processing (ICIP), 2017, pp. 3215–3219. doi
- S. W. Zamir, A. Arora, S. Khan, et al., “Learning enriched features for real image restoration and enhancement,” in Proc. European Conference on Computer Vision (ECCV), 2020, pp. 492–511. arXiv
- X. Xu, R. Wang, C.-W. Fu and J. Jia, “SNR-aware low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 17693–17703. doi
- Z. Cui, K. Li, L. Gu, S. Su, P. Gao, Z. Jiang, Y. Qiao and T. Harada, “You only need 90K parameters to adapt light: A light weight transformer for image enhancement and exposure correction,” in Proc. British Machine Vision Conference (BMVC), 2022. paper arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, 2021, pp. 13728–13737. doi arXiv
- Y. Zhang, J. Zhang and X. Guo, “Kindling the darkness: A practical low-light image enhancer,” in Proc. ACM International Conference on Multimedia (ACM MM), 2019, pp. 1632–1640. doi
- Y. Zhang, X. Guo, J. Ma, W. Liu and J. Zhang, “Beyond brightening low-light images,” International Journal of Computer Vision, vol. 129, no. 4, pp. 1013–1037, 2021. doi
- J. Bai, Y. Yin, Q. He, Y. Li and X. Zhang, “RetinexMamba: Retinex-based Mamba for low-light image enhancement,” arXiv:2405.03349, 2024. arXiv
- S.-E. Weng, S.-G. Miaou and R. Christanto, “A lightweight low-light image enhancement network via channel prior and gamma correction,” International Journal of Pattern Recognition and Artificial Intelligence, vol. 39, no. 12, art. 2554013, 2025. doi code manuscript
- S.-E. Weng, C.-Y. Hsiao, L.-W. Lu, et al., “Rethinking theoretical illumination for efficient low-light image enhancement” (CPGA-Net+), arXiv:2409.05274, 2024. arXiv
- W. Wu, J. Weng, P. Zhang, X. Wang, W. Yang and J. Jiang, “URetinex-Net: Retinex-based deep unfolding network for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 5891–5900. doi
- Z. Liang, C. Li, S. Zhou, R. Feng and C. C. Loy, “Iterative prompt learning for unsupervised backlit image enhancement,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- C. Yang, M. Jin, X. Jia, Y. Xu and Y. Chen, “AdaInt: Learning adaptive intervals for 3D lookup tables on real-time image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 17522–17531. CVF arXiv
- C. Yang, M. Jin, Y. Xu, R. Zhang, Y. Chen and H. Liu, “SepLUT: Separable image-adaptive lookup tables for real-time image enhancement,” in Proc. European Conference on Computer Vision (ECCV), 2022, pp. 201–217. doi arXiv
- T. Wang, Y. Li, J. Peng, Y. Ma, X. Wang, F. Song and Y. Yan, “Real-time image enhancer via learnable spatial-aware 3D lookup tables,” in Proc. IEEE/CVF ICCV, 2021, pp. 2471–2480. CVF arXiv
- C. Liu, H. Yang, J. Fu and X. Qian, “4D LUT: Learnable context-aware 4D lookup table for image enhancement,” IEEE Transactions on Image Processing, vol. 32, pp. 4742–4756, 2023. doi arXiv
- W. Kim and N. I. Cho, “Image-adaptive 3D lookup tables for real-time image enhancement with bilateral grids,” in Proc. European Conference on Computer Vision (ECCV), 2024, pp. 91–108. doi ECCV
- C. Chen, Q. Chen, J. Xu and V. Koltun, “Learning to see in the dark,” in Proc. IEEE/CVF CVPR, 2018, pp. 3291–3300. arXiv
- M. V. Conde, G. Geigle and R. Timofte, “InstructIR: High-quality image restoration following human instructions,” in Proc. European Conference on Computer Vision (ECCV), 2024. arXiv
- Z. Cui, G.-J. Qi, L. Gu, S. You, Z. Zhang and T. Harada, “Multitask AET with orthogonal tangent regularity for dark object detection,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- K. A. Hashmi, G. Kallempudi, D. Stricker and M. Z. Afzal, “FeatEnHancer: Enhancing hierarchical features for object detection and beyond under low-light vision,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- M. Dehghani, A. Arnab, L. Beyer, A. Vaswani and Y. Tay, “The efficiency misnomer,” in Proc. International Conference on Learning Representations (ICLR), 2022. ICLR arXiv
- A. Ignatov, R. Timofte, S. Liu, et al., “Learned smartphone ISP on mobile GPUs with deep learning, Mobile AI & AIM 2022 challenge: Report,” in Proc. European Conference on Computer Vision (ECCV) Workshops, 2023, pp. 44–70. doi arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image quality assessment: From error visibility to structural similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The unreasonable effectiveness of deep features as a perceptual metric,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- K. Ma, K. Zeng and Z. Wang, “Perceptual quality assessment for multi-exposure image fusion,” IEEE Transactions on Image Processing, vol. 24, no. 11, pp. 3345–3356, 2015. doi
- V. Vonikakis, “Datasets” (source of the VV test images), personal web page. link
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a ‘completely blind’ image quality analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- A. Mittal, A. K. Moorthy and A. C. Bovik, “No-reference image quality assessment in the spatial domain,” IEEE Transactions on Image Processing, vol. 21, no. 12, pp. 4695–4708, 2012. doi
- Y. Blau, R. Mechrez, R. Timofte, T. Michaeli and L. Zelnik-Manor, “The 2018 PIRM challenge on perceptual image super-resolution,” in Proc. European Conference on Computer Vision (ECCV) Workshops, 2018. arXiv
- C. Ma, C.-Y. Yang, X. Yang and M.-H. Yang, “Learning a no-reference quality metric for single-image super-resolution,” Computer Vision and Image Understanding, vol. 158, pp. 1–16, 2017. doi arXiv
- D. Hasler and S. E. Süsstrunk, “Measuring colorfulness in natural images,” in Proc. SPIE 5007, Human Vision and Electronic Imaging VIII, 2003. doi
- J. Immerkær, “Fast noise variance estimation,” Computer Vision and Image Understanding, vol. 64, no. 2, pp. 300–302, 1996. doi
- J. Liao, S. Hao, R. Hong and M. Wang, “GT-Mean loss: A simple yet effective solution for brightness mismatch in low-light image enhancement,” in Proc. IEEE/CVF ICCV, 2025. arXiv
- Y. P. Loh and C. S. Chan, “Getting to know low-light images with the Exclusively Dark dataset,” Computer Vision and Image Understanding, vol. 178, pp. 30–42, 2019. arXiv
- F. Liu and L. Fan, “A review of advancements in low-light image enhancement using deep learning,” Neurocomputing, vol. 652, art. 131052, 2025. arXiv
- J. Liu, D. Xu, W. Yang, M. Fan and H. Huang, “Benchmarking low-light image enhancement and beyond,” International Journal of Computer Vision, vol. 129, no. 4, pp. 1153–1184, 2021. doi project
- W. Yang, W. Wang, H. Huang, S. Wang and J. Liu, “Sparse gradient regularized deep Retinex network for robust low-light image enhancement,” IEEE Transactions on Image Processing, vol. 30, pp. 2072–2086, 2021. doi
- J. Hai, Z. Xuan, R. Yang, et al., “R2RNet: Low-light image enhancement via Real-low to Real-normal Network,” Journal of Visual Communication and Image Representation, vol. 90, art. 103712, 2023. arXiv
- R. Wang, X. Xu, C.-W. Fu, et al., “Seeing dynamic scene in the dark: A high-quality video dataset with mechatronic alignment,” in Proc. IEEE/CVF ICCV, 2021, pp. 9680–9689. doi code
- V. Bychkovsky, S. Paris, E. Chan and F. Durand, “Learning photographic global tonal adjustment with a database of input/output image pairs,” in Proc. IEEE CVPR, 2011, pp. 97–104. dataset
- J. Cai, S. Gu and L. Zhang, “Learning a deep single image contrast enhancer from multi-exposure images,” IEEE Transactions on Image Processing, vol. 27, no. 4, pp. 2049–2062, 2018. doi
- X. Liu, Z. Wu, A. Li, et al., “NTIRE 2024 challenge on low light image enhancement: Methods and results,” in Proc. IEEE/CVF CVPR Workshops, 2024. arXiv
- X. Liu, Z. Wu, F.-A. Vasluianu, et al., “NTIRE 2025 challenge on low light image enhancement: Methods and results,” in Proc. IEEE/CVF CVPR Workshops, 2025. arXiv
- S. Zheng, Y. Ma, J. Pan, C. Lu and G. Gupta, “Low-light image and video enhancement: A comprehensive survey and beyond,” arXiv:2212.10772, 2022. arXiv
- E. Adhikarla, Y. Liu and B. D. Davison, “Diffusion models for low-light image enhancement: A multi-perspective taxonomy and performance analysis,” arXiv:2510.05976, 2025. arXiv
- J. Yan, C. Tu, W. Zhang, Z. Wang, P. Cao, Q. Lin, Y. Fang, X. Liu, Z. Wu, Z. Zhou and R. Timofte, “NTIRE 2026 challenge on efficient low light image enhancement: Methods and results,” NTIRE 2026 workshop report, arXiv:2605.02212, 2026. arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional networks for biomedical image segmentation,” in Proc. Medical Image Computing and Computer-Assisted Intervention (MICCAI), 2015, pp. 234–241. doi arXiv
- J. Chen, A. Adams, N. Wadhwa and S. W. Hasinoff, “Bilateral guided upsampling,” ACM Transactions on Graphics (Proc. SIGGRAPH Asia), vol. 35, no. 6, 2016. doi project
- K. He, J. Sun and X. Tang, “Guided image filtering,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 35, no. 6, pp. 1397–1409, 2013. doi
- C. Chen and J. Mo, “IQA-PyTorch: PyTorch toolbox for image quality assessment,” software (pip package
pyiqa). GitHub - J. Ke, Q. Wang, Y. Wang, P. Milanfar and F. Yang, “MUSIQ: Multi-scale image quality transformer,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- J. Wang, K. C. K. Chan and C. C. Loy, “Exploring CLIP for assessing the look and feel of images,” in Proc. AAAI Conference on Artificial Intelligence, 2023. arXiv
- V. Kannan, S. Malik, N. C. Babu and R. Soundararajan, “Quality assessment of low-light restored images: A subjective study and an unsupervised model,” IEEE Access, vol. 11, pp. 68216–68230, 2023. doi arXiv
- ITU-R, “Recommendation BT.500-15: Methodologies for the subjective assessment of the quality of television images,” 2023. ITU
- R. A. Bradley and M. E. Terry, “Rank analysis of incomplete block designs: The method of paired comparisons,” Biometrika, vol. 39, no. 3–4, pp. 324–345, 1952. doi
- H. Talebi and P. Milanfar, “NIMA: Neural image assessment,” IEEE Transactions on Image Processing, 2018. arXiv
- S. Yang, T. Wu, S. Shi, et al., “MANIQA: Multi-dimension attention network for no-reference image quality assessment,” in Proc. IEEE/CVF CVPR Workshops, 2022, pp. 1190–1199. doi arXiv
- H. Wu, Z. Zhang, W. Zhang, C. Chen, et al., “Q-Align: Teaching LMMs for visual scoring via discrete text-defined levels,” in Proc. International Conference on Machine Learning (ICML), PMLR 235, 2024. arXiv
- A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto and H. Adam, “MobileNets: Efficient convolutional neural networks for mobile vision applications,” arXiv:1704.04861, 2017. arXiv
- M. Sandler, A. Howard, M. Zhu, A. Zhmoginov and L.-C. Chen, “MobileNetV2: Inverted residuals and linear bottlenecks,” in Proc. IEEE/CVF CVPR, 2018, pp. 4510–4520. doi arXiv
- W.-S. Lai, J.-B. Huang, O. Wang, E. Shechtman, E. Yumer and M.-H. Yang, “Learning blind video temporal consistency,” in Proc. European Conference on Computer Vision (ECCV), 2018, pp. 179–195. doi arXiv
- S. W. Hasinoff, D. Sharlet, R. Geiss, A. Adams, J. T. Barron, F. Kainz, J. Chen and M. Levoy, “Burst photography for high dynamic range and low-light imaging on mobile cameras,” ACM Transactions on Graphics (Proc. SIGGRAPH Asia), vol. 35, no. 6, 2016. doi
- J. Chen, S. Paris and F. Durand, “Real-time edge-aware image processing with the bilateral grid,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 26, no. 3, art. 103, 2007. doi
- C. Tomasi and R. Manduchi, “Bilateral filtering for gray and color images,” in Proc. IEEE International Conference on Computer Vision (ICCV), 1998, pp. 839–846. doi
- S. Paris and F. Durand, “A fast approximation of the bilateral filter using a signal processing approach,” International Journal of Computer Vision, vol. 81, no. 1, pp. 24–52, 2009. doi
- H. Wu, S. Zheng, J. Zhang and K. Huang, “Fast end-to-end trainable guided filter,” in Proc. IEEE/CVF CVPR, 2018, pp. 1838–1847. doi arXiv
- R. Wang, Q. Zhang, C.-W. Fu, X. Shen, W.-S. Zheng and J. Jia, “Underexposed photo enhancement using deep illumination estimation,” in Proc. IEEE/CVF CVPR, 2019, pp. 6842–6850. doi CVF
- Y. Lin, Z. Fu, K. Wen, T. Ye, S. Chen, G. Meng, Y. Wang, et al., “DPLUT: Unsupervised low-light image enhancement with lookup tables and diffusion priors,” in Proc. AAAI Conference on Artificial Intelligence, vol. 39, no. 5, pp. 5316–5324, 2025. doi arXiv
- K. Dabov, A. Foi, V. Katkovnik and K. Egiazarian, “Image denoising by sparse 3-D transform-domain collaborative filtering,” IEEE Transactions on Image Processing, 2007. doi
- K. Simonyan and A. Zisserman, “Very deep convolutional networks for large-scale image recognition,” ICLR, 2015. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A large-scale hierarchical image database,” CVPR, 2009. doi
- A. Brateanu, T. Mu, C. O. Ancuti and C. Ancuti, “Multinex: Lightweight Low-light Image Enhancement via Multi-prior Retinex,” in Proc. IEEE/CVF CVPR, 2026. paper supplement