現代觀點綜述導讀
選讀・DLCV 06・影像中的文字:OCR 與文件理解 的論文導讀(第 1/4 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
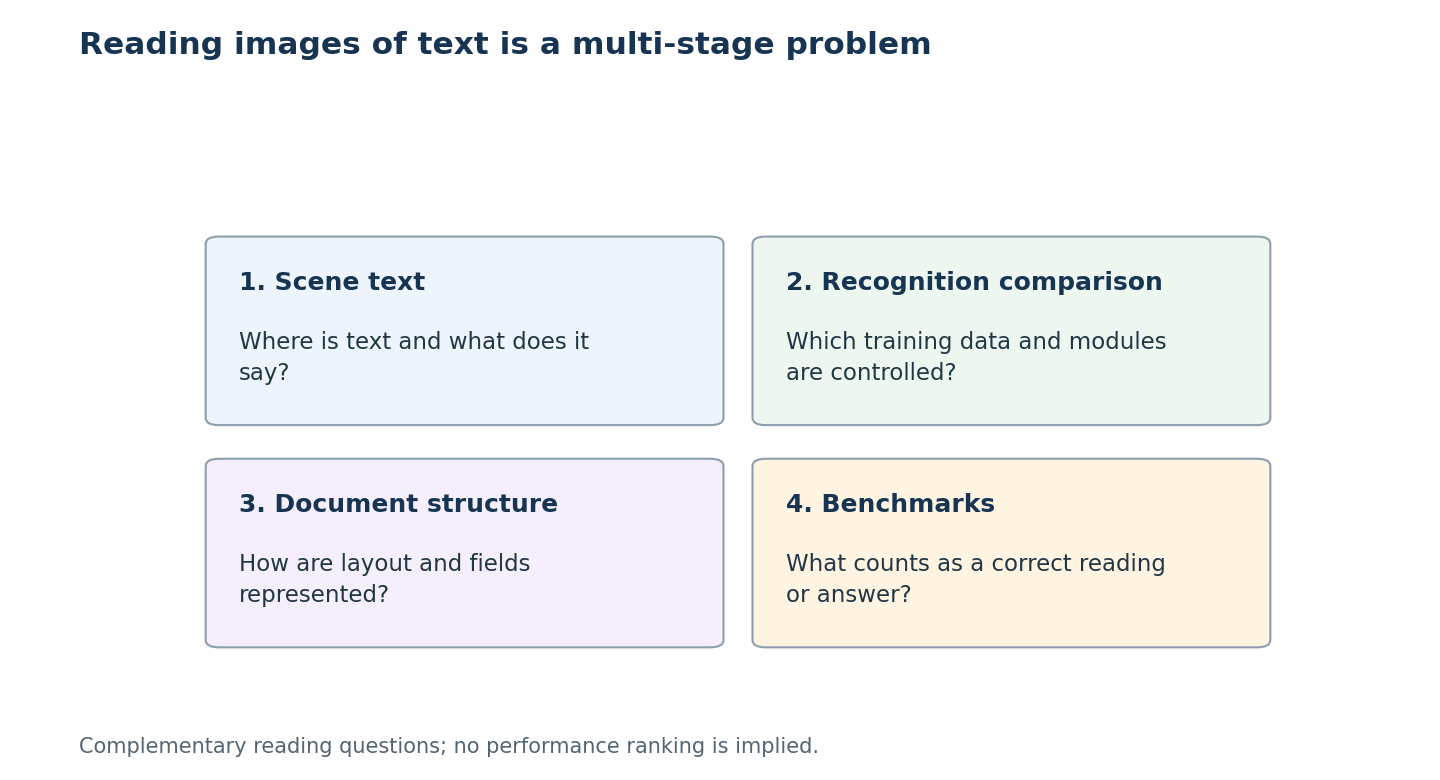
先區分場景文字定位辨識、模組公平比較、文件結構與答案評估,再選對應選讀。
Long、He 與 Yao:「Scene Text Detection and Recognition: The Deep Learning Era」
(IJCV 2021)[1] 把偵測分成早期深度方法、受一般物件偵測啟發的方法,以及以子文字元件(字元、片段、核心)為基礎的方法;把辨識分成以 CTC 為基礎與編碼器–解碼器兩類方法;然後是端到端系統,以及合成資料、弱監督或半監督等輔助技術。它也回顧了基準與評估協定(以 IoU 為基礎與 DetEval 式的配對、端到端詞彙)。它的結論:深度學習讓旋轉與彎曲文字變得可處理,但大多數方法與資料集都集中在英文,字母表有幾萬個符號的語言依然困難,對不完美偵測的穩健性與跨資料集的泛化尚未解決,而單一閾值的 F-score 應該搭配 AP。
Chen、Jin、Zhu、Luo 與 Wang:「Text Recognition in the Wild: A Survey」
(ACM Computing Surveys 2021)[2] 專注於辨識。它把以分割為基礎的方法(前處理、字元切割、字元辨識)和不需分割的方法分開,並依階段描述後者:影像前處理、特徵表示、序列建模與預測(CTC 或注意力)。最實用的部分,是合成與真實資料集的目錄,以及拉丁文字(單字準確率、搭配三種詞彙的端到端辨識與單字定位)與多語言文字(正規化編輯距離)的評估協定。
Cui、Xu、Lv 與 Wei:「Document AI: Benchmarks, Models and Applications」
(arXiv 2021)[3] 是一篇簡短的回顧,涵蓋文件任務——版面分析、視覺資訊擷取、文件問答與文件影像分類——及其基準,追溯方法從規則式啟發法,經統計學習,到深度的預訓練多模態模型。
Zhang 等人:「Document Parsing Unveiled」
(arXiv 2024)[4] 回顧文件解析,也就是把頁面轉成結構化、機器可讀的形式。它的分類有兩個分支:模組化管線(版面分析,再接文字、表格、數學式與視覺元素的辨識器),以及由視覺語言模型驅動的統一模型。它整理了指標與基準,並指出對複雜版面的穩健性、以 VLM 為基礎的解析的可靠度,以及推論效率是尚待解決的挑戰。
Liu 等人:「OCRBench」
(Science China Information Sciences 2024)[22] 是一項評估,而不是綜述。它在 29 個資料集上測試大型多模態模型的文字辨識、場景文字與文件問答、關鍵資訊擷取,以及手寫數學式,發現它們在多語言、手寫、非語意與數學文字上最弱。
如何判讀這些論文的證據
場景文字與文件理解重疊,但證據、目標不相同。裁切字詞辨識可假設定位已完成;頁面剖析還要恢復閱讀順序、版面或欄位;多模態測試有時只要求依文字回答,並非完整抄錄。因此這些文獻應視為流程的互補面向。
比較須核對語言/文字系統、合成與真實訓練來源、裁切校正、詞典與匹配規則。字串準確率、編輯距離、偵測重疊、欄位分數測量不同失敗;一項進步仍可能漏版面或虛構合理答案。資料涵蓋有限,也可能有訓練重疊。分別用辨識研究控制模組、文件綜述理解結構,再依原基準定義解讀分數。
參考文獻
- S. Long, X. He and C. Yao, “Scene text detection and recognition: The deep learning era,” International Journal of Computer Vision, vol. 129, pp. 161–184, 2021. doi
- X. Chen, L. Jin, Y. Zhu, C. Luo and T. Wang, “Text recognition in the wild: A survey,” ACM Computing Surveys, vol. 54, no. 2, 2021. doi
- L. Cui, Y. Xu, T. Lv and F. Wei, “Document AI: Benchmarks, models and applications,” arXiv:2111.08609, 2021. arXiv
- Q. Zhang, B. Wang, V. S.-J. Huang, J. Zhang, Z. Wang, H. Liang, C. He and W. Zhang, “Document parsing unveiled: Techniques, challenges, and prospects for structured information extraction,” arXiv:2410.21169, 2024. arXiv
- D. Karatzas, F. Shafait, S. Uchida, M. Iwamura, L. Gomez i Bigorda, S. Robles Mestre, J. Mas et al., “ICDAR 2013 Robust Reading Competition,” in Proc. International Conference on Document Analysis and Recognition (ICDAR), pp. 1484–1493, 2013. doi
- D. Karatzas, L. Gomez-Bigorda, A. Nicolaou, S. Ghosh, A. Bagdanov, M. Iwamura, J. Matas et al., “ICDAR 2015 competition on Robust Reading,” in Proc. International Conference on Document Analysis and Recognition (ICDAR), pp. 1156–1160, 2015. doi
- J. Baek, G. Kim, J. Lee, S. Park, D. Han, S. Yun, S. J. Oh and H. Lee, “What is wrong with scene text recognition model comparisons? Dataset and model analysis,” in Proc. IEEE/CVF ICCV, pp. 4714–4722, 2019. doi
- N. Otsu, “A threshold selection method from gray-level histograms,” IEEE Transactions on Systems, Man, and Cybernetics, vol. 9, no. 1, pp. 62–66, 1979. doi
- J. Sauvola and M. Pietikäinen, “Adaptive document image binarization,” Pattern Recognition, vol. 33, no. 2, pp. 225–236, 2000. doi
- C. K. Ch’ng and C. S. Chan, “Total-Text: A comprehensive dataset for scene text detection and recognition,” in Proc. ICDAR, pp. 935–942, 2017. doi
- Y. Liu, L. Jin, S. Zhang, C. Luo and S. Zhang, “Curved scene text detection via transverse and longitudinal sequence connection,” Pattern Recognition, vol. 90, pp. 337–345, 2019. doi
- X. Zhou, C. Yao, H. Wen, Y. Wang, S. Zhou, W. He and J. Liang, “EAST: An efficient and accurate scene text detector,” in Proc. IEEE CVPR, pp. 2642–2651, 2017. doi
- W. Wang, E. Xie, X. Li, W. Hou, T. Lu, G. Yu and S. Shao, “Shape robust text detection with progressive scale expansion network,” in Proc. IEEE/CVF CVPR, pp. 9328–9337, 2019. doi
- M. Liao, Z. Wan, C. Yao, K. Chen and X. Bai, “Real-time scene text detection with differentiable binarization,” in Proc. AAAI Conference on Artificial Intelligence, vol. 34, pp. 11474–11481, 2020. doi
- Y. Baek, B. Lee, D. Han, S. Yun and H. Lee, “Character region awareness for text detection,” in Proc. IEEE/CVF CVPR, pp. 9357–9366, 2019. doi
- B. Shi, X. Bai and C. Yao, “An end-to-end trainable neural network for image-based sequence recognition and its application to scene text recognition,” IEEE TPAMI, vol. 39, no. 11, pp. 2298–2304, 2017. doi
- A. Graves, S. Fernández, F. Gomez and J. Schmidhuber, “Connectionist temporal classification: Labelling unsegmented sequence data with recurrent neural networks,” in Proc. ICML, pp. 369–376, 2006. doi
- B. Shi, M. Yang, X. Wang, P. Lyu, C. Yao and X. Bai, “ASTER: An attentional scene text recognizer with flexible rectification,” IEEE TPAMI, vol. 41, no. 9, pp. 2035–2048, 2019. doi
- M. Li, T. Lv, J. Chen, L. Cui, Y. Lu, D. Florencio, C. Zhang, Z. Li and F. Wei, “TrOCR: Transformer-based optical character recognition with pre-trained models,” in Proc. AAAI Conference on Artificial Intelligence, vol. 37, pp. 13094–13102, 2023. doi
- D. Bautista and R. Atienza, “Scene text recognition with permuted autoregressive sequence models,” in Proc. ECCV, pp. 178–196, 2022. doi
- S. Fang, H. Xie, Y. Wang, Z. Mao and Y. Zhang, “Read like humans: Autonomous, bidirectional and iterative language modeling for scene text recognition,” in Proc. IEEE/CVF CVPR, pp. 7094–7103, 2021. doi
- Y. Liu, Z. Li, M. Huang, B. Yang, W. Yu, C. Li, X.-C. Yin, C.-L. Liu, L. Jin and X. Bai, “OCRBench: On the hidden mystery of OCR in large multimodal models,” Science China Information Sciences, vol. 67, 2024. doi
- M. Jaderberg, K. Simonyan, A. Vedaldi and A. Zisserman, “Synthetic data and artificial neural networks for natural scene text recognition,” arXiv:1406.2227, 2014. arXiv
- A. Gupta, A. Vedaldi and A. Zisserman, “Synthetic data for text localisation in natural images,” in Proc. IEEE CVPR, pp. 2315–2324, 2016. doi
- X. Liu, D. Liang, S. Yan, D. Chen, Y. Qiao and J. Yan, “FOTS: Fast oriented text spotting with a unified network,” in Proc. IEEE/CVF CVPR, pp. 5676–5685, 2018. doi
- P. Lyu, M. Liao, C. Yao, W. Wu and X. Bai, “Mask TextSpotter: An end-to-end trainable neural network for spotting text with arbitrary shapes,” in Proc. ECCV, pp. 71–88, 2018. doi
- Y. Liu, H. Chen, C. Shen, T. He, L. Jin and L. Wang, “ABCNet: Real-time scene text spotting with adaptive Bezier-curve network,” in Proc. IEEE/CVF CVPR, pp. 9806–9815, 2020. doi
- X. Zhong, J. Tang and A. Jimeno Yepes, “PubLayNet: Largest dataset ever for document layout analysis,” in Proc. ICDAR, pp. 1015–1022, 2019. doi
- B. Pfitzmann, C. Auer, M. Dolfi, A. S. Nassar and P. Staar, “DocLayNet: A large human-annotated dataset for document-layout segmentation,” in Proc. ACM SIGKDD, pp. 3743–3751, 2022. doi
- Y. Xu, M. Li, L. Cui, S. Huang, F. Wei and M. Zhou, “LayoutLM: Pre-training of text and layout for document image understanding,” in Proc. ACM SIGKDD, pp. 1192–1200, 2020. doi
- R. Smith, “An overview of the Tesseract OCR engine,” in Proc. ICDAR, vol. 2, pp. 629–633, 2007. doi
- Y. Huang, T. Lv, L. Cui, Y. Lu and F. Wei, “LayoutLMv3: Pre-training for document AI with unified text and image masking,” in Proc. ACM International Conference on Multimedia, pp. 4083–4091, 2022. doi
- G. Jaume, H. K. Ekenel and J.-P. Thiran, “FUNSD: A dataset for form understanding in noisy scanned documents,” in Proc. ICDAR Workshops (OST), 2019. doi
- G. Kim, T. Hong, M. Yim, J. Nam, J. Park, J. Yim, W. Hwang, S. Yun, D. Han and S. Park, “OCR-free document understanding transformer,” in Proc. ECCV, pp. 498–517, 2022. doi
- K. Lee, M. Joshi, I. R. Turc, H. Hu, F. Liu, J. M. Eisenschlos, U. Khandelwal, P. Shaw, M.-W. Chang and K. Toutanova, “Pix2Struct: Screenshot parsing as pretraining for visual language understanding,” in Proc. ICML, PMLR vol. 202, pp. 18893–18912, 2023. PMLR
- L. Blecher, G. Cucurull, T. Scialom and R. Stojnic, “Nougat: Neural optical understanding for academic documents,” in Proc. ICLR, 2024. OpenReview · arXiv
- U.-V. Marti and H. Bunke, “The IAM-database: An English sentence database for offline handwriting recognition,” International Journal on Document Analysis and Recognition, vol. 5, pp. 39–46, 2002. doi
- C.-L. Liu, F. Yin, D.-H. Wang and Q.-F. Wang, “CASIA online and offline Chinese handwriting databases,” in Proc. ICDAR, pp. 37–41, 2011. doi
- B. Shi, C. Yao, M. Liao, M. Yang, P. Xu, L. Cui, S. Belongie, S. Lu and X. Bai, “ICDAR2017 competition on reading Chinese text in the wild (RCTW-17),” in Proc. ICDAR, pp. 1429–1434, 2017. doi · arXiv
- T.-L. Yuan, Z. Zhu, K. Xu, C.-J. Li, T.-J. Mu and S.-M. Hu, “A large Chinese text dataset in the wild,” Journal of Computer Science and Technology, vol. 34, pp. 509–521, 2019. doi · arXiv
- F. Xue and R. Ishida (eds.), “Requirements for Chinese Text Layout,” W3C Group Note (draft of 7 October 2026). W3C
- N. Nayef, Y. Patel, M. Busta, P. N. Chowdhury, D. Karatzas, W. Khlif, J. Matas et al., “ICDAR2019 Robust Reading Challenge on multi-lingual scene text detection and recognition — RRC-MLT-2019,” in Proc. ICDAR, pp. 1582–1587, 2019. doi · arXiv
- R. A. Wagner and M. J. Fischer, “The string-to-string correction problem,” Journal of the ACM, vol. 21, no. 1, pp. 168–173, 1974. doi
- M. Mathew, D. Karatzas and C. V. Jawahar, “DocVQA: A dataset for VQA on document images,” in Proc. IEEE/CVF WACV, pp. 2199–2208, 2021. doi
- A. Mishra, K. Alahari and C. V. Jawahar, “Scene text recognition using higher order language priors,” in Proc. BMVC, 2012. doi
- K. Wang, B. Babenko and S. Belongie, “End-to-end scene text recognition,” in Proc. IEEE ICCV, pp. 1457–1464, 2011. doi
- L. Ouyang, Y. Qu, H. Zhou, J. Zhu, R. Zhang, Q. Lin, B. Wang, Z. Zhao et al., “OmniDocBench: Benchmarking diverse PDF document parsing with comprehensive annotations,” in Proc. IEEE/CVF CVPR, pp. 24838–24848, 2025. CVF
- H. Wei, C. Liu, J. Chen, J. Wang, L. Kong, Y. Xu, Z. Ge, L. Zhao et al., “General OCR theory: Towards OCR-2.0 via a unified end-to-end model,” arXiv:2409.01704, 2024. arXiv
- J. Poznanski, A. Rangapur, J. Borchardt, J. Dunkelberger, R. Huff, D. Lin, C. Wilhelm et al., “olmOCR: Unlocking trillions of tokens in PDFs with vision language models,” arXiv:2502.18443, 2025. arXiv
- H. Wei, Y. Sun and Y. Li, “DeepSeek-OCR: Contexts optical compression,” arXiv:2510.18234, 2025. arXiv
- C. Wolf and J.-M. Jolion, “Object count/area graphs for the evaluation of object detection and segmentation algorithms,” International Journal of Document Analysis and Recognition, vol. 8, pp. 280–296, 2006. doi