Mask2Former:論文導讀
選讀・DLCV 04・影像分割:語意、實例與全景分割 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
Cheng、Misra、Schwing、Kirillov 與 Girdhar,Masked-attention Mask Transformer for Universal Image Segmentation,CVPR 2022 [26]。這則導讀說明論文主張什麼,以及看它的表格時要注意什麼。
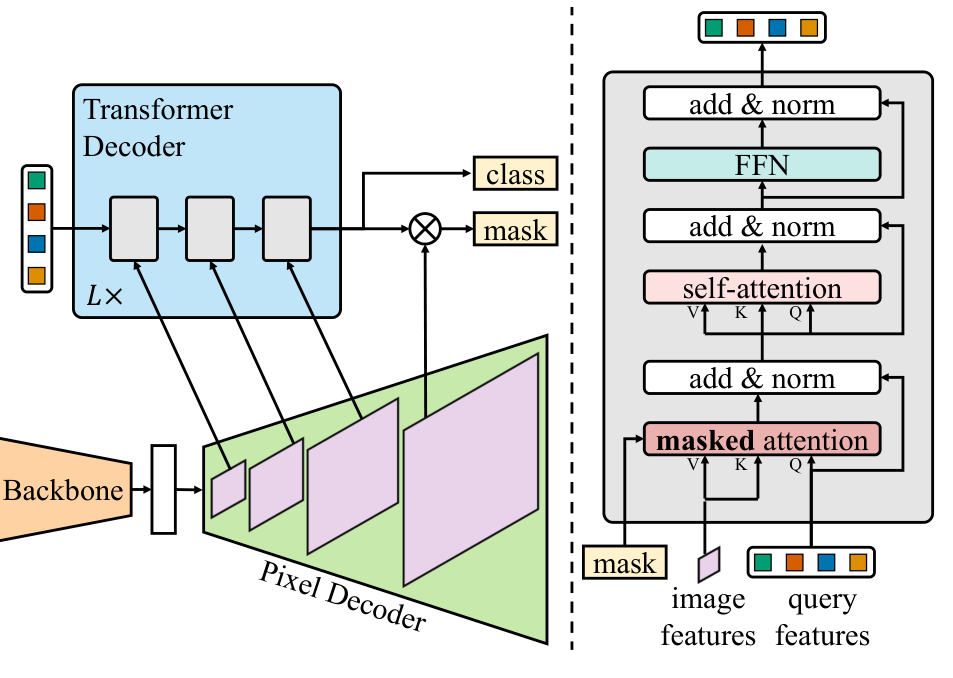
圖片來源: [26], Published paper PDF, PDF 第 3 頁. 原始 PDF.
挑戰
MaskFormer 這類「通用」的遮罩分類模型,可以用同一個架構處理所有分割任務,但它們在實例分割上落後於最好的專門模型,而且訓練成本高:論文指出 MaskFormer 在 COCO 上需要 300 個 epoch,而且在 32 GB 的 GPU 上只放得下一張影像。研究者因此持續為每個任務建造專門的架構。
方法
保留 MaskFormer 的整體架構,並修正 Transformer 解碼器:
- 遮罩注意力,把每個查詢的交叉注意力限制在它自己前一次遮罩預測的前景內(正文中的方程式);
- 輪流使用多尺度特徵,把像素解碼器的 1/32、1/16 與 1/8 特徵圖依序餵給連續的解碼器層,重複 次;
- 最佳化上的改動:交叉注意力放在自注意力之前、直接受監督的可學習查詢特徵(作者說它們的行為像區域提案網路)、不使用 dropout;
- 取樣點的遮罩損失:損失在 ()個取樣點上計算,配對成本用均勻取樣、最終損失用重要性取樣,沿用 PointRend;論文報告每張影像的訓練記憶體從 18 GB 降到 6 GB。
結果
同一個架構,針對每個任務與資料集分別訓練,在 COCO、ADE20K、Cityscapes 與 Mapillary Vistas 的全景、實例與語意分割上,達到或超越了當時專門模型的最佳水準(摘要引述 COCO 全景 57.8 PQ、COCO 實例 50.1 AP 與 ADE20K 57.7 mIoU)。在消融實驗中(它的表 4),遮罩注意力帶來最大的進步,對實例與全景分割的幫助多於語意分割,高解析度的多尺度策略也很重要。
判讀證據
- 檢查訓練排程那一欄。 在 COCO 全景表中(它的表 1),DETR 訓練 500+25 個 epoch,MaskFormer 300 個,Mask2Former 50 個;論文的訊息有一部分是收斂速度,所以論文有提供相同 epoch 的比較時,要在相同 epoch 下比較。
- 檢查骨幹網路與預訓練。 標了 †(dagger,劍號)的列,使用的是在比其他列更大的分類資料集上預訓練的骨幹網路,而最強的幾列使用 200 個查詢,而不是 100 個。要先比較骨幹網路相同的列,再把功勞歸給解碼器。
- 把任務專用與全景訓練的數字分開。 這張表也報告 與 ,它們來自只用全景標註訓練的同一個模型;與專為實例或語意分割訓練的模型數字不是同一回事。
- 看成本那幾欄。 準確率旁邊報告了參數量、FLOPs 與每秒影格數;最大的模型慢很多。
限制與問題
通用的架構還不是通用的模型:只用全景標籤訓練時,Mask2Former 在實例與語意指標上,略差於用任務專用標註訓練的同一個模型(它的表 7),所以仍然需要針對各任務訓練。它也仍然不擅長小物體,並且沒有充分利用多尺度特徵。
結論
Mask2Former 是「遮罩分類」一節背後的參考設計,也是後來多數表格中的基線,包括 OneFormer 的單一模型訓練,以及 EoMT 只留編碼器的簡化。
參考文獻
- S. Minaee, Y. Boykov, F. Porikli, A. Plaza, N. Kehtarnavaz and D. Terzopoulos, “Image segmentation using deep learning: A survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 7, 2022. doi · arXiv
- X. Li, H. Ding, H. Yuan, W. Zhang, J. Pang, G. Cheng, K. Chen, Z. Liu and C. C. Loy, “Transformer-based visual segmentation: A survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 46, no. 12, 2024. doi · arXiv
- T. Zhou, W. Xia, F. Zhang, B. Chang, W. Wang, Y. Yuan, E. Konukoglu and D. Cremers, “Image segmentation in foundation model era: A survey,” arXiv:2408.12957, 2024. arXiv
- A. Kirillov, K. He, R. Girshick, C. Rother and P. Dollár, “Panoptic segmentation,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2019. doi · arXiv
- J. Long, E. Shelhamer and T. Darrell, “Fully convolutional networks for semantic segmentation,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2015. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional networks for biomedical image segmentation,” in Medical Image Computing and Computer-Assisted Intervention (MICCAI), LNCS vol. 9351, 2015. doi
- L.-C. Chen, Y. Zhu, G. Papandreou, F. Schroff and H. Adam, “Encoder-decoder with atrous separable convolution for semantic image segmentation,” in Proc. European Conference on Computer Vision (ECCV), 2018. doi · arXiv
- L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy and A. L. Yuille, “DeepLab: Semantic image segmentation with deep convolutional nets, atrous convolution, and fully connected CRFs,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 40, no. 4, 2018. doi · arXiv
- F. Yu and V. Koltun, “Multi-scale context aggregation by dilated convolutions,” in Proc. International Conference on Learning Representations (ICLR), 2016. arXiv
- L.-C. Chen, G. Papandreou, F. Schroff and H. Adam, “Rethinking atrous convolution for semantic image segmentation,” arXiv:1706.05587, 2017. arXiv
- P. Wang, P. Chen, Y. Yuan, D. Liu, Z. Huang, X. Hou and G. Cottrell, “Understanding convolution for semantic segmentation,” in Proc. IEEE Winter Conference on Applications of Computer Vision (WACV), 2018. doi · arXiv
- H. Zhao, J. Shi, X. Qi, X. Wang and J. Jia, “Pyramid scene parsing network,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · arXiv
- A. Dosovitskiy, L. Beyer, A. Kolesnikov, D. Weissenborn, X. Zhai, T. Unterthiner et al., “An image is worth 16x16 words: Transformers for image recognition at scale,” in Proc. International Conference on Learning Representations (ICLR), 2021. arXiv
- E. Xie, W. Wang, Z. Yu, A. Anandkumar, J. M. Alvarez and P. Luo, “SegFormer: Simple and efficient design for semantic segmentation with transformers,” in Advances in Neural Information Processing Systems (NeurIPS), 2021. NeurIPS · arXiv
- F. Milletari, N. Navab and S.-A. Ahmadi, “V-Net: Fully convolutional neural networks for volumetric medical image segmentation,” in Proc. Fourth International Conference on 3D Vision (3DV), 2016. doi · arXiv
- T.-Y. Lin, P. Goyal, R. Girshick, K. He and P. Dollár, “Focal loss for dense object detection,” in Proc. IEEE International Conference on Computer Vision (ICCV), 2017. doi
- B. Cheng, A. G. Schwing and A. Kirillov, “Per-pixel classification is not all you need for semantic segmentation,” in Advances in Neural Information Processing Systems (NeurIPS), 2021. NeurIPS · arXiv
- M. Cordts, M. Omran, S. Ramos, T. Rehfeld, M. Enzweiler, R. Benenson, U. Franke, S. Roth and B. Schiele, “The Cityscapes dataset for semantic urban scene understanding,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · arXiv
- B. Cheng, R. Girshick, P. Dollár, A. C. Berg and A. Kirillov, “Boundary IoU: Improving object-centric image segmentation evaluation,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021. doi · arXiv
- K. He, G. Gkioxari, P. Dollár and R. Girshick, “Mask R-CNN,” in Proc. IEEE International Conference on Computer Vision (ICCV), 2017. doi · arXiv
- S. Ren, K. He, R. Girshick and J. Sun, “Faster R-CNN: Towards real-time object detection with region proposal networks,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 39, no. 6, 2017. doi
- T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi
- A. Kirillov, Y. Wu, K. He and R. Girshick, “PointRend: Image segmentation as rendering,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · arXiv
- A. Kirillov, R. Girshick, K. He and P. Dollár, “Panoptic feature pyramid networks,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2019. doi · arXiv
- N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. European Conference on Computer Vision (ECCV), 2020. doi · arXiv
- B. Cheng, I. Misra, A. G. Schwing, A. Kirillov and R. Girdhar, “Masked-attention mask transformer for universal image segmentation,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2022. doi · arXiv
- J. Jain, J. Li, M. Chiu, A. Hassani, N. Orlov and H. Shi, “OneFormer: One transformer to rule universal image segmentation,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023. doi · arXiv
- T. Kerssies, N. Cavagnero, A. Hermans, N. Norouzi, G. Averta, B. Leibe, G. Dubbelman and D. de Geus, “Your ViT is secretly an image segmentation model,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025. CVF · arXiv
- A. Kirillov, E. Mintun, N. Ravi, H. Mao, C. Rolland, L. Gustafson et al., “Segment anything,” in Proc. IEEE/CVF International Conference on Computer Vision (ICCV), 2023. doi · arXiv
- N. Ravi, V. Gabeur, Y.-T. Hu, R. Hu, C. Ryali, T. Ma et al., “SAM 2: Segment anything in images and videos,” in Proc. International Conference on Learning Representations (ICLR), 2025. OpenReview · arXiv
- N. Carion, L. Gustafson, Y.-T. Hu, S. Debnath, R. Hu, D. Suris et al., “SAM 3: Segment anything with concepts,” in Proc. International Conference on Learning Representations (ICLR), 2026. OpenReview · arXiv
- A. Radford, J. W. Kim, C. Hallacy, A. Ramesh, G. Goh, S. Agarwal et al., “Learning transferable visual models from natural language supervision,” in Proc. International Conference on Machine Learning (ICML), PMLR 139, 2021. PMLR
- B. Li, K. Q. Weinberger, S. Belongie, V. Koltun and R. Ranftl, “Language-driven semantic segmentation,” in Proc. International Conference on Learning Representations (ICLR), 2022. OpenReview · arXiv
- S. Cho, H. Shin, S. Hong, A. Arnab, P. H. Seo and S. Kim, “CAT-Seg: Cost aggregation for open-vocabulary semantic segmentation,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024. doi · arXiv
- C. Zhu and L. Chen, “A survey on open-vocabulary detection and segmentation: Past, present, and future,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 46, no. 12, 2024. doi
- M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn and A. Zisserman, “The PASCAL Visual Object Classes (VOC) challenge,” International Journal of Computer Vision, vol. 88, no. 2, 2010. doi
- B. Zhou, H. Zhao, X. Puig, S. Fidler, A. Barriuso and A. Torralba, “Scene parsing through ADE20K dataset,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · CVF
- T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan et al., “Microsoft COCO: Common objects in context,” in Proc. European Conference on Computer Vision (ECCV), 2014. doi · arXiv
- H. Caesar, J. Uijlings and V. Ferrari, “COCO-Stuff: Thing and stuff classes in context,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2018. doi · arXiv
- G. Neuhold, T. Ollmann, S. Rota Bulò and P. Kontschieder, “The Mapillary Vistas dataset for semantic understanding of street scenes,” in Proc. IEEE International Conference on Computer Vision (ICCV), 2017. doi
- P. Krähenbühl and V. Koltun, “Efficient inference in fully connected CRFs with Gaussian edge potentials,” in Advances in Neural Information Processing Systems (NeurIPS), 2011. NeurIPS · arXiv