DDNM:保留量測成分,生成零空間內容
選讀・DLCV 09B・生成式影像復原:取樣出一個合理的答案 的論文導讀(第 3/5 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
可學習先驗可能生成與已知無雜訊量測不符的值。DDNM [19] 分開由線性量測決定的部分與未受約束的部分,每次預測乾淨影像後修正前者。基礎模型的精確一致性論證,需要適當的已知算子與可行的無雜訊資料。
方法
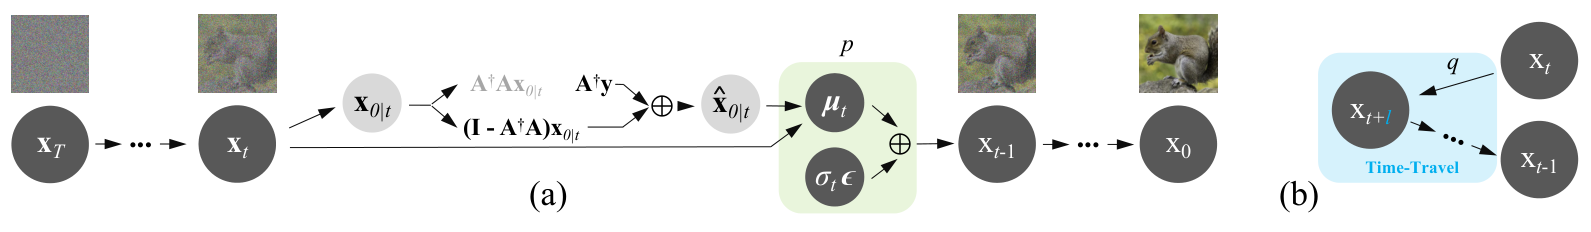
圖片來源: [19], PDF 第 5 頁. 原始 PDF.
令 把影像向量 映射為 ,選擇滿足 的廣義逆 。對擴散的乾淨影像估計 ,建立
是 單位矩陣, 為取樣時間。第一項放入符合量測的成分,第二項保留先驗在 零空間的成分。若使用 Moore–Penrose 逆,這是正交的列空間/零空間分量;一般廣義逆則可能形成斜投影。
若 可行,將等式左乘 可得 ,但不能推論保留的零空間細節就是原始不可見影像。修正的是乾淨估計,再把它放進下一個反向擴散/DDIM 更新;不能直接用乾淨影像覆寫帶雜訊狀態。
使用真正可檢查的算子。 二元遮罩可在觀測位置充當自己的逆;區塊平均則可用複製建立量測一致的提升。雙三次下採樣需要不同算子/廣義逆。把多個廣義逆倒序相乘,不保證對所有複合退化都有效,仍須驗證 。
DDNM+ 處理量測雜訊。 若 ,硬投影也會放入 。DDNM+ 縮放值域修正,並調整取樣注入雜訊以符合擴散雜訊預算。時間旅行程序暫時回到較吵狀態,再反覆細化以改善整體相容性。兩者是分開的改善,都不表示應精確複製帶雜訊觀測。
讀圖與選用判斷。 在投影步驟中,分開看量測決定的部分與算子零空間中的部分。對無雜訊遮罩,可固定已觀測像素,讓先驗填入缺失像素;這個例子不代表一般模糊算子也能靠逐像素替換處理。解讀精確一致性前,必須一起檢查算子與偽逆。若量測含雜訊,應使用論文對應的雜訊處理設定,而不是直接投影到每個觀測值。一致性限制可接受的輸出,但多張不同影像仍可能符合相同量測。
結果
原表 1 使用相同去雜訊器與 100 步 DDIM 配置,無雜訊 CelebA SR 為 31.63 dB/0.945 SSIM/22.27 FID。DDRM 顯示相同 PSNR/SSIM,FID 卻為 31.04。失真分數相同,不代表輸出分布相同。
原文在 ImageNet、CelebA 評估 SR、去模糊、上色、壓縮感知與修補,各表指定其算子。線性灰階模型的成功,不代表能處理任意未知相機呈像。
消融實驗
表 2 分開帶雜訊處理與時間旅行。CelebA SR、標記為 的設定,DDNM+ 將 PSNR 從 13.10 提升至 19.44 dB; SR 的時間旅行比較則從 17.55 變為 18.44 dB。反覆細化會增加運算,比較推論成本時必須計入。
同表也列上色與壓縮感知,顯示增益大小依任務而異。雜訊預算改變、重複取樣兩者的效益,不能全歸因於投影等式。
結論
DDNM 清楚分開量測約束與先驗生成的自由度;DDNM+ 進一步說明,觀測雜訊與重複細化不能只靠無雜訊投影處理。
限制與問題
錯誤算子或不準確廣義逆會破壞一致性論證。精確一致可能保留雜訊與模型錯置,大零空間也仍允許幻覺。壓縮、非線性相機處理可能違反線性模型。「零樣本」表示把預訓練先驗用於新逆問題,不表示去雜訊器未受訓練。
參考文獻
- Y. Blau and T. Michaeli, “The Perception-Distortion Tradeoff,” in Proc. IEEE/CVF CVPR, 2018, pp. 6228–6237 (extended version on arXiv). doi · arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017, pp. 105–114. doi · arXiv
- J. Johnson, A. Alahi and L. Fei-Fei, “Perceptual Losses for Real-Time Style Transfer and Super-Resolution,” in Proc. ECCV, 2016, pp. 694–711. doi · arXiv
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018 (LNCS, 2019), pp. 63–79. doi · arXiv
- X. Wang, L. Xie, C. Dong and Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution with Pure Synthetic Data,” in Proc. IEEE/CVF ICCV Workshops, 2021, pp. 1905–1914. doi · arXiv
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” in Proc. IEEE/CVF CVPR, 2019, pp. 4396–4405. doi · arXiv
- S. Menon, A. Damian, S. Hu, N. Ravi and C. Rudin, “PULSE: Self-Supervised Photo Upsampling via Latent Space Exploration of Generative Models,” in Proc. IEEE/CVF CVPR, 2020, pp. 2434–2442. doi · arXiv
- K. C. K. Chan, X. Wang, X. Xu, J. Gu and C. C. Loy, “GLEAN: Generative Latent Bank for Large-Factor Image Super-Resolution,” in Proc. IEEE/CVF CVPR, 2021, pp. 14240–14249. doi · arXiv
- X. Wang, Y. Li, H. Zhang and Y. Shan, “Towards Real-World Blind Face Restoration with Generative Facial Prior,” in Proc. IEEE/CVF CVPR, 2021, pp. 9164–9174. doi · arXiv
- S. Zhou, K. C. K. Chan, C. Li and C. C. Loy, “Towards Robust Blind Face Restoration with Codebook Lookup Transformer,” in Proc. NeurIPS, vol. 35, 2022, pp. 30599–30611. doi · arXiv
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” in Proc. NeurIPS, 2020. proceedings · arXiv
- Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon and B. Poole, “Score-Based Generative Modeling through Stochastic Differential Equations,” in Proc. ICLR, 2021. arXiv
- B. Efron, “Tweedie’s Formula and Selection Bias,” Journal of the American Statistical Association, vol. 106, no. 496, pp. 1602–1614, 2011. doi
- C. Saharia, J. Ho, W. Chan, T. Salimans, D. J. Fleet and M. Norouzi, “Image Super-Resolution via Iterative Refinement,” IEEE TPAMI, 2022 (early access). doi · arXiv
- C. Saharia, W. Chan, H. Chang, C. Lee, J. Ho, T. Salimans, D. Fleet and M. Norouzi, “Palette: Image-to-Image Diffusion Models,” in Proc. ACM SIGGRAPH Conference, 2022, pp. 1–10. doi · arXiv
- Z. Yue, J. Wang and C. C. Loy, “ResShift: Efficient Diffusion Model for Image Super-resolution by Residual Shifting,” in Proc. NeurIPS, vol. 36, 2023, pp. 13294–13307. doi · arXiv
- H. Chung, J. Kim, M. T. McCann, M. L. Klasky and J. C. Ye, “Diffusion Posterior Sampling for General Noisy Inverse Problems,” in Proc. ICLR, 2023. arXiv
- B. Kawar, M. Elad, S. Ermon and J. Song, “Denoising Diffusion Restoration Models,” in Proc. NeurIPS, vol. 35, 2022, pp. 23593–23606. doi · arXiv
- Y. Wang, J. Yu and J. Zhang, “Zero-Shot Image Restoration Using Denoising Diffusion Null-Space Model,” in Proc. ICLR, 2023. arXiv
- J. Song, A. Vahdat, M. Mardani and J. Kautz, “Pseudoinverse-Guided Diffusion Models for Inverse Problems,” in Proc. ICLR, 2023. ICLR page
- Y. Zhu, K. Zhang, J. Liang, J. Cao, B. Wen, R. Timofte and L. Van Gool, “Denoising Diffusion Models for Plug-and-Play Image Restoration,” in Proc. IEEE/CVF CVPR Workshops, 2023, pp. 1219–1229. doi · arXiv
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” in Proc. IEEE/CVF CVPR, 2022, pp. 10674–10685. doi · arXiv
- L. Zhang, A. Rao and M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” in Proc. IEEE/CVF ICCV, 2023, pp. 3813–3824. doi · arXiv
- J. Wang, Z. Yue, S. Zhou, K. C. K. Chan and C. C. Loy, “Exploiting Diffusion Prior for Real-World Image Super-Resolution,” International Journal of Computer Vision, vol. 132, no. 12, pp. 5929–5949, 2024. doi · arXiv
- X. Lin, J. He, Z. Chen, Z. Lyu, B. Dai, F. Yu, Y. Qiao, W. Ouyang and C. Dong, “DiffBIR: Toward Blind Image Restoration with Generative Diffusion Prior,” in Proc. ECCV, 2024 (LNCS), pp. 430–448. doi · arXiv
- F. Yu, J. Gu, Z. Li, J. Hu, X. Kong, X. Wang, J. He, Y. Qiao and C. Dong, “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” in Proc. IEEE/CVF CVPR, 2024, pp. 25669–25680. doi · arXiv
- Y. Wang, W. Yang, X. Chen, Y. Wang, L. Guo, L.-P. Chau, Z. Liu, Y. Qiao, A. C. Kot and B. Wen, “SinSR: Diffusion-Based Image Super-Resolution in a Single Step,” in Proc. IEEE/CVF CVPR, 2024, pp. 25796–25805. doi · arXiv
- R. Wu, L. Sun, Z. Ma and L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” in Proc. NeurIPS, vol. 37, 2024, pp. 92529–92553. doi · arXiv
- Z. Yue, K. Liao and C. C. Loy, “Arbitrary-steps Image Super-resolution via Diffusion Inversion,” in Proc. IEEE/CVF CVPR, 2025, pp. 23153–23163. doi · arXiv
- L. Dong, Q. Fan, Y. Guo, Z. Wang, Q. Zhang, J. Chen, Y. Luo and C. Zou, “TSD-SR: One-Step Diffusion with Target Score Distillation for Real-World Image Super-Resolution,” in Proc. IEEE/CVF CVPR, 2025, pp. 23174–23184. doi · arXiv
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” in Proc. ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” in Proc. ICLR, 2023. arXiv
- G. Ohayon, T. Michaeli and M. Elad, “Posterior-Mean Rectified Flow: Towards Minimum MSE Photo-Realistic Image Restoration,” in Proc. ICLR, 2025. arXiv
- S. Martin, A. Gagneux, P. Hagemann and G. Steidl, “PnP-Flow: Plug-and-Play Image Restoration with Flow Matching,” in Proc. ICLR, 2025. arXiv
- S. Bhadra, V. A. Kelkar, F. J. Brooks and M. A. Anastasio, “On Hallucinations in Tomographic Image Reconstruction,” IEEE Transactions on Medical Imaging, vol. 40, no. 11, pp. 3249–3260, 2021. doi · arXiv
- W. Ren, R. Goyal, Z. Hu, T. T. Aumentado-Armstrong, I. Mohomed and A. Levinshtein, “Hallucination Score: Towards Mitigating Hallucinations in Generative Image Super-Resolution,” arXiv:2507.14367, 2025. arXiv
- A. N. Angelopoulos, A. P. Kohli, S. Bates, M. I. Jordan, J. Malik, T. Alshaabi, S. Upadhyayula and Y. Romano, “Image-to-Image Regression with Distribution-Free Uncertainty Quantification and Applications in Imaging,” in Proc. ICML, PMLR 162, 2022. proceedings · arXiv
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler and S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” in Proc. NeurIPS (NIPS), 2017. arXiv
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a ‘Completely Blind’ Image Quality Analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar and F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” in Proc. IEEE/CVF ICCV, 2021, pp. 5128–5137. doi · arXiv
- J. Wang, K. C. K. Chan and C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” in Proc. AAAI, vol. 37, no. 2, 2023, pp. 2555–2563. doi · arXiv
- X. Li, Y. Ren, X. Jin, C. Lan, X. Wang, W. Zeng, X. Wang and Z. Chen, “Diffusion Models for Image Restoration and Enhancement: A Comprehensive Survey,” International Journal of Computer Vision, vol. 133, no. 11, pp. 8078–8108, 2025. doi · arXiv
- G. Daras, H. Chung, C.-H. Lai, Y. Mitsufuji, J. C. Ye, P. Milanfar, A. G. Dimakis and M. Delbracio, “A Survey on Diffusion Models for Inverse Problems,” arXiv:2410.00083, 2024. arXiv
- B. B. Moser, A. S. Shanbhag, F. Raue, S. Frolov, S. Palacio and A. Dengel, “Diffusion Models, Image Super-Resolution, and Everything: A Survey,” IEEE Transactions on Neural Networks and Learning Systems, vol. 36, no. 7, pp. 11793–11813, 2025. doi · arXiv
- W. Xia, Y. Zhang, Y. Yang, J.-H. Xue, B. Zhou and M.-H. Yang, “GAN Inversion: A Survey,” IEEE TPAMI, vol. 45, no. 3, pp. 3121–3138, 2023. doi · arXiv
- Y. Song and S. Ermon, “Generative Modeling by Estimating Gradients of the Data Distribution,” in Proc. NeurIPS, 2019. arXiv
- H. Chung, J. Kim, S. Kim and J. C. Ye, “Parallel Diffusion Models of Operator and Image for Blind Inverse Problems,” in Proc. IEEE/CVF CVPR, 2023, pp. 6059–6069. paper