RealBasicVSR
選讀・DLCV 09A.3・影片超解析度:用時間找回細節 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
用 BI 或 BD 退化訓練的模型,在真實影片上會失效,而單純用隨機的真實世界退化來訓練 BasicVSR 類型的模型,又會引發先前研究忽略的新取捨 [27]。
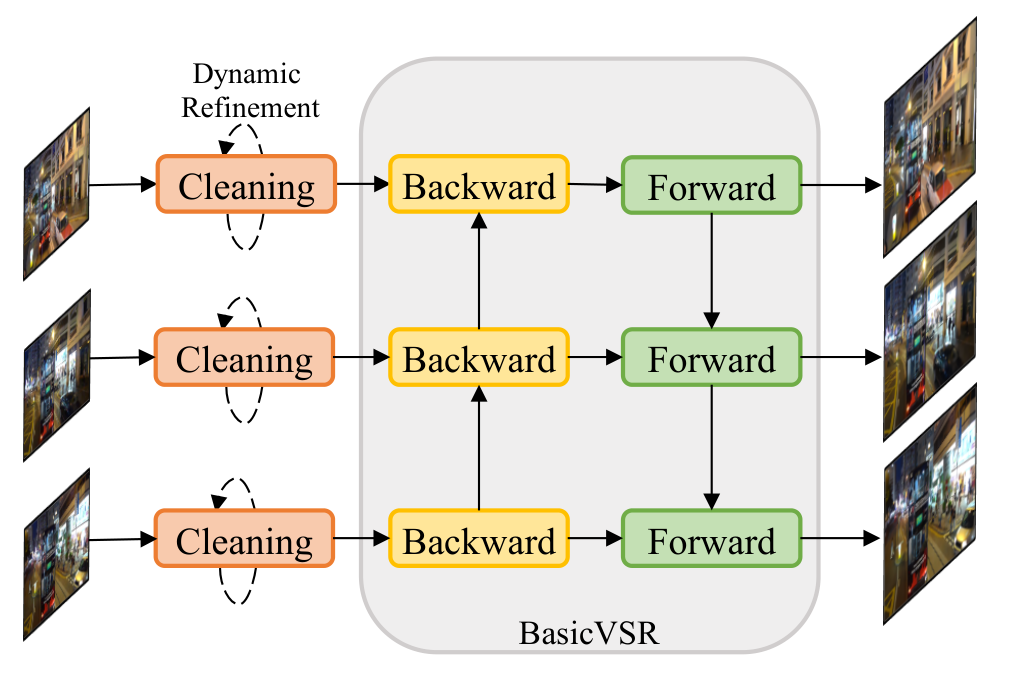
圖片來源: [27], Published paper PDF, PDF 第 4 頁. 原始 PDF.
方法
這篇論文找出三個取捨,並為每一個提出簡單的解法。(1) 細節合成與瑕疵抑制:長期傳播在散播細節的同時也散播雜訊與瑕疵,所以在 BasicVSR 網路傳播之前,先由一個影像預清理模組(一疊殘差區塊)獨立地清理每個 LR 影格。它用一個額外的清理損失訓練,把它的輸出與降取樣後的真實標準答案比較;測試時,動態改進機制會反覆套用它,直到變化降到門檻以下。論文顯示,循環式的清理模組,或沒有清理損失,都無法去除瑕疵。(2) 訓練中的速度與表現:載入許多長的、退化的片段會讓訓練變慢,所以隨機退化機制只載入每段序列的一半並在時間上翻轉它,並讓退化參數以隨機漫步的方式逐影格變化,以維持資料多樣性;這在品質不下降的情況下,最多把訓練時間減少 40%。(3) 批次與長度:在固定的記憶體預算下,較長的序列比較大的批次更有效地利用時間資訊,也讓推論更穩定。
結果
RealBasicVSR 是帶有清理模組的 BasicVSR,並以感知與對抗損失微調(清理模組與這兩個損失分離),在真實影片上,它的品質與效率優於真實世界的影像與影片 SR 模型。這篇論文也釋出 VideoLQ 這個真實低品質影片資料集,作為共同的基準測試。
判讀證據
從清理模組的分析(對未清理的輸入套用傳播時會發生什麼)與批次對長度的實驗開始,因為它們解釋了這個設計。對於 VideoLQ,要檢查比較用的是無參考指標與視覺結果,因為沒有標準答案;並閱讀視覺比較,看更清晰的紋理與捏造的瑕疵之間的取捨。
限制與問題
VideoLQ 上的無參考指標與人類判斷的關聯只算薄弱,所以比較有一部分要靠視覺範例。退化模型是合成的,所以它之外的編碼器與相機流程仍可能讓模型失效。清理模組若移除太多,也會連真實細節一起移除。
結論
它解釋了為什麼真實世界 VSR 不能直接沿用乾淨基準測試的配方,也是 Upscale-A-Video 等擴散式 VSR 論文拿來比較的標準非擴散基線 [28]。
參考文獻
- S. Farsiu, M. D. Robinson, M. Elad and P. Milanfar, “Fast and Robust Multiframe Super Resolution,” IEEE Transactions on Image Processing, vol. 13, no. 10, pp. 1327–1344, 2004. doi
- J. Caballero, C. Ledig, A. Aitken, A. Acosta, J. Totz, Z. Wang and W. Shi, “Real-Time Video Super-Resolution with Spatio-Temporal Networks and Motion Compensation,” in Proc. IEEE CVPR, 2017. CVF · arXiv
- M. S. M. Sajjadi, R. Vemulapalli and M. Brown, “Frame-Recurrent Video Super-Resolution,” in Proc. IEEE/CVF CVPR, 2018. CVF · arXiv
- M. Irani and S. Peleg, “Improving Resolution by Image Registration,” CVGIP: Graphical Models and Image Processing, vol. 53, no. 3, pp. 231–239, 1991. doi
- M. Haris, G. Shakhnarovich and N. Ukita, “Recurrent Back-Projection Network for Video Super-Resolution,” in Proc. IEEE/CVF CVPR, 2019. CVF · arXiv
- M. Guizar-Sicairos, S. T. Thurman and J. R. Fienup, “Efficient Subpixel Image Registration Algorithms,” Optics Letters, vol. 33, no. 2, p. 156, 2008. doi
- K. C. K. Chan, X. Wang, K. Yu, C. Dong and C. C. Loy, “BasicVSR: The Search for Essential Components in Video Super-Resolution and Beyond,” in Proc. IEEE/CVF CVPR, 2021. CVF · arXiv
- B. K. P. Horn and B. G. Schunck, “Determining Optical Flow,” Artificial Intelligence, vol. 17, no. 1–3, pp. 185–203, 1981. doi
- G. Farnebäck, “Two-Frame Motion Estimation Based on Polynomial Expansion,” in Image Analysis (Lecture Notes in Computer Science), pp. 363–370, Springer, 2003. doi
- A. Ranjan and M. J. Black, “Optical Flow Estimation Using a Spatial Pyramid Network,” in Proc. IEEE CVPR, 2017. CVF · arXiv
- Z. Teed and J. Deng, “RAFT: Recurrent All-Pairs Field Transforms for Optical Flow,” in Proc. ECCV (Lecture Notes in Computer Science), pp. 402–419, 2020. doi · arXiv
- M. Jaderberg, K. Simonyan, A. Zisserman and K. Kavukcuoglu, “Spatial Transformer Networks,” in Advances in Neural Information Processing Systems (NeurIPS), 2015. proceedings · arXiv
- W. Shi, J. Caballero, F. Huszár, J. Totz, A. P. Aitken, R. Bishop, D. Rueckert and Z. Wang, “Real-Time Single Image and Video Super-Resolution Using an Efficient Sub-Pixel Convolutional Neural Network,” in Proc. IEEE CVPR, 2016. arXiv
- T. Xue, B. Chen, J. Wu, D. Wei and W. T. Freeman, “Video Enhancement with Task-Oriented Flow,” International Journal of Computer Vision, vol. 127, no. 8, pp. 1106–1125, 2019. doi · arXiv
- J. Dai, H. Qi, Y. Xiong, Y. Li, G. Zhang, H. Hu and Y. Wei, “Deformable Convolutional Networks,” in Proc. IEEE ICCV, 2017. CVF · arXiv
- X. Zhu, H. Hu, S. Lin and J. Dai, “Deformable ConvNets V2: More Deformable, Better Results,” in Proc. IEEE/CVF CVPR, 2019. CVF · arXiv
- Y. Tian, Y. Zhang, Y. Fu and C. Xu, “TDAN: Temporally-Deformable Alignment Network for Video Super-Resolution,” in Proc. IEEE/CVF CVPR, 2020. CVF · arXiv
- X. Wang, K. C. K. Chan, K. Yu, C. Dong and C. C. Loy, “EDVR: Video Restoration with Enhanced Deformable Convolutional Networks,” in Proc. IEEE/CVF CVPR Workshops, 2019. CVF · arXiv
- K. C. K. Chan, X. Wang, K. Yu, C. Dong and C. C. Loy, “Understanding Deformable Alignment in Video Super-Resolution,” in Proc. AAAI Conference on Artificial Intelligence, vol. 35, no. 2, pp. 973–981, 2021. doi · arXiv
- K. C. K. Chan, S. Zhou, X. Xu and C. C. Loy, “BasicVSR++: Improving Video Super-Resolution with Enhanced Propagation and Alignment,” in Proc. IEEE/CVF CVPR, 2022. CVF · arXiv
- Y. Jo, S. W. Oh, J. Kang and S. J. Kim, “Deep Video Super-Resolution Network Using Dynamic Upsampling Filters Without Explicit Motion Compensation,” in Proc. IEEE/CVF CVPR, 2018. CVF
- P. Yi, Z. Wang, K. Jiang, J. Jiang and J. Ma, “Progressive Fusion Video Super-Resolution Network via Exploiting Non-Local Spatio-Temporal Correlations,” in Proc. IEEE/CVF ICCV, 2019. CVF · code and test data (Vid4, UDM10)
- J. Liang, J. Cao, Y. Fan, K. Zhang, R. Ranjan, Y. Li, R. Timofte and L. Van Gool, “VRT: A Video Restoration Transformer,” IEEE Transactions on Image Processing, vol. 33, pp. 2171–2182, 2024. doi · arXiv
- J. Liang, Y. Fan, X. Xiang, R. Ranjan, E. Ilg, S. Green, J. Cao, K. Zhang, R. Timofte and L. Van Gool, “Recurrent Video Restoration Transformer with Guided Deformable Attention,” in Advances in Neural Information Processing Systems (NeurIPS), vol. 35, pp. 378–393, 2022. arXiv
- T. Wiegand, G. J. Sullivan, G. Bjøntegaard and A. Luthra, “Overview of the H.264/AVC Video Coding Standard,” IEEE Transactions on Circuits and Systems for Video Technology, vol. 13, no. 7, pp. 560–576, 2003. doi
- Y. Li, P. Jin, F. Yang, C. Liu, M.-H. Yang and P. Milanfar, “COMISR: Compression-Informed Video Super-Resolution,” in Proc. IEEE/CVF ICCV, 2021. CVF · arXiv
- K. C. K. Chan, S. Zhou, X. Xu and C. C. Loy, “Investigating Tradeoffs in Real-World Video Super-Resolution,” in Proc. IEEE/CVF CVPR, 2022. CVF · arXiv
- S. Zhou, P. Yang, J. Wang, Y. Luo and C. C. Loy, “Upscale-A-Video: Temporal-Consistent Diffusion Model for Real-World Video Super-Resolution,” in Proc. IEEE/CVF CVPR, pp. 2535–2545, 2024. CVF · arXiv
- X. Yang, C. He, J. Ma and L. Zhang, “Motion-Guided Latent Diffusion for Temporally Consistent Real-World Video Super-Resolution,” in Proc. ECCV (Lecture Notes in Computer Science), pp. 224–242, 2024. doi · arXiv
- R. Xie, Y. Liu, P. Zhou, C. Zhao, J. Zhou, K. Zhang, Z. Zhang, J. Yang, Z. Yang and Y. Tai, “STAR: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution,” in Proc. IEEE/CVF ICCV, 2025. CVF · arXiv
- J. Wang, Z. Lin, M. Wei, Y. Zhao, C. Yang, C. C. Loy and L. Jiang, “SeedVR: Seeding Infinity in Diffusion Transformer Towards Generic Video Restoration,” in Proc. IEEE/CVF CVPR, 2025. CVF · arXiv
- Y. Sun, L. Sun, S. Liu, R. Wu, Z. Zhang and L. Zhang, “One-Step Diffusion for Detail-Rich and Temporally Consistent Video Super-Resolution,” in Advances in Neural Information Processing Systems (NeurIPS), vol. 38, 2025. arXiv
- W.-S. Lai, J.-B. Huang, O. Wang, E. Shechtman, E. Yumer and M.-H. Yang, “Learning Blind Video Temporal Consistency,” in Proc. ECCV, 2018. CVF · arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- ITU-R, “Recommendation ITU-R BT.601-7: Studio Encoding Parameters of Digital Television for Standard 4:3 and Wide-Screen 16:9 Aspect Ratios,” International Telecommunication Union, 2011. ITU
- M. Chu, Y. Xie, J. Mayer, L. Leal-Taixé and N. Thuerey, “Learning Temporal Coherence via Self-Supervision for GAN-based Video Generation,” ACM Transactions on Graphics, vol. 39, no. 4, article 75, 2020. doi · arXiv
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018. CVF · arXiv
- S. Nah, S. Baik, S. Hong, G. Moon, S. Son, R. Timofte and K. M. Lee, “NTIRE 2019 Challenge on Video Deblurring and Super-Resolution: Dataset and Study,” in Proc. IEEE/CVF CVPR Workshops, 2019. CVF
- C. Liu and D. Sun, “On Bayesian Adaptive Video Super Resolution,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 36, no. 2, pp. 346–360, 2014. doi
- H. Liu, Z. Ruan, P. Zhao, C. Dong, F. Shang, Y. Liu, L. Yang and R. Timofte, “Video Super-Resolution Based on Deep Learning: A Comprehensive Survey,” Artificial Intelligence Review, vol. 55, no. 8, pp. 5981–6035, 2022. doi · arXiv
- S. Nah, R. Timofte, S. Gu, S. Baik, S. Hong, G. Moon, S. Son and K. M. Lee, “NTIRE 2019 Challenge on Video Super-Resolution: Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2019. CVF
- S. Son, S. Lee, S. Nah, R. Timofte and K. M. Lee, “NTIRE 2021 Challenge on Video Super-Resolution,” in Proc. IEEE/CVF CVPR Workshops, 2021. CVF · arXiv
- A. Ignatov, R. Timofte et al., “Power Efficient Video Super-Resolution on Mobile NPUs with Deep Learning, Mobile AI & AIM 2022 Challenge: Report,” arXiv:2211.05256, 2022. arXiv
- M. V. Conde, Z. Lei, W. Li, C. Bampis, I. Katsavounidis, R. Timofte et al., “AIM 2024 Challenge on Efficient Video Super-Resolution for AV1 Compressed Content,” in Proc. ECCV Workshops (Lecture Notes in Computer Science), pp. 304–325, 2025. doi · arXiv
- Z. Tu, H. Li, W. Xie, Y. Liu, S. Zhang, B. Li and J. Yuan, “Optical Flow for Video Super-Resolution: A Survey,” Artificial Intelligence Review, vol. 55, no. 8, pp. 6505–6546, 2022. doi · arXiv
- A. A. Baniya, T.-K. Lee, P. W. Eklund and S. Aryal, “A Survey of Deep Learning Video Super-Resolution,” IEEE Transactions on Emerging Topics in Computational Intelligence, vol. 8, no. 4, pp. 2655–2676, 2024. doi · arXiv
- B. Wronski, I. Garcia-Dorado, M. Ernst, D. Kelly, M. Krainin, C.-K. Liang, M. Levoy and P. Milanfar, “Handheld Multi-Frame Super-Resolution,” ACM Transactions on Graphics, vol. 38, no. 4, 2019. doi · arXiv