A White Paper on Neural Network Quantization(Nagel 等人,2021)
選讀・DLCV 01C・模型壓縮與高效推論 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
量化對定點硬體上的高效推論是必要的,但實務者面對許多互相影響的選擇(對稱或非對稱、逐張量或逐通道、範圍設定、PTQ 或 QAT),而已發表的方法很難組合 [15]。
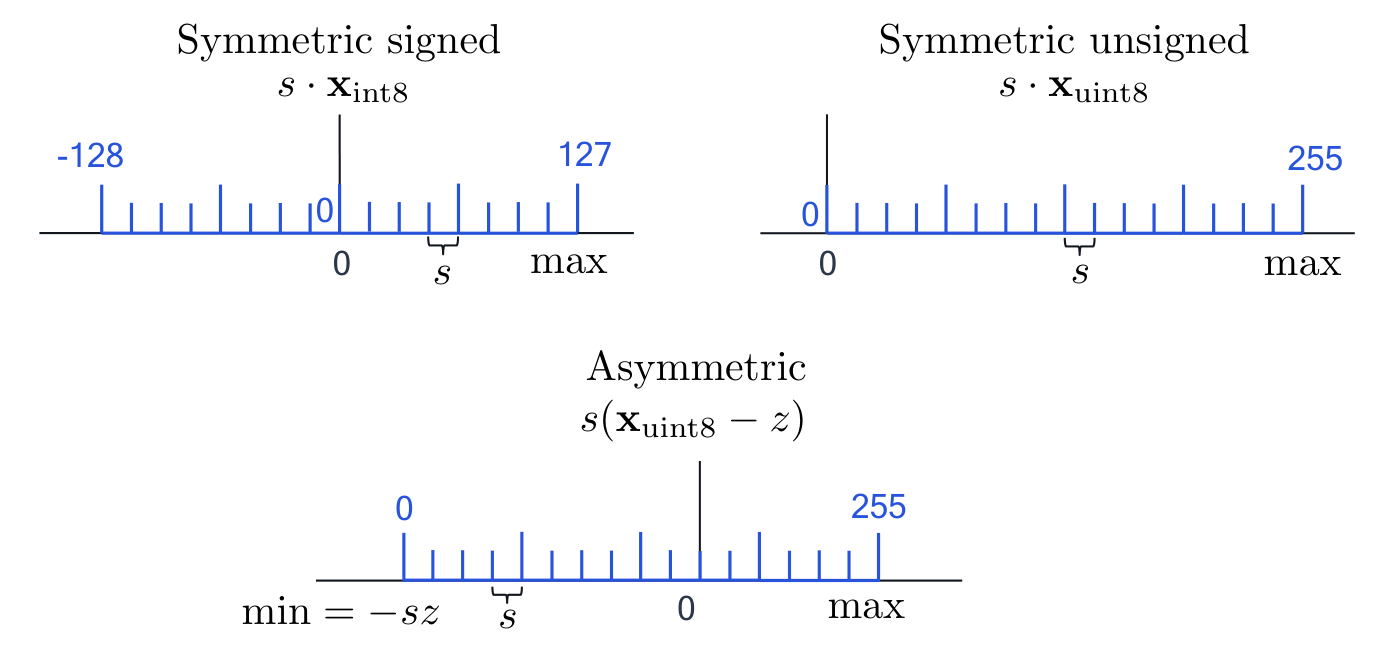
圖片來源: [15], arXiv:2106.08295v1, PDF 第 5 頁. 原始 PDF.
方法
從定點加速器如何計算矩陣乘法出發(8 位元輸入、32 位元累加器、重新量化),推導出在這種硬體上哪些量化選擇是便宜的,再組合出兩條經過測試的流程:一條給 PTQ,一條給 QAT,另外還有一套給仍然失敗的模型使用的除錯工作流程 [15]。
結果
在它的實驗中,PTQ 流程讓所有測試的視覺與語言模型的 8 位元權重與激活值,都在浮點結果的 0.7% 以內;4 位元權重的 PTQ,在 ResNet 與 InceptionV3 上相差約 1% 以內,但對有深度可分離層的模型損失較多,逐通道量化在這些模型上有幫助。QAT 流程讓大多數模型的 4 位元權重與 8 位元激活值接近浮點,而 4 位元激活值對 MobileNetV2、EfficientNet-lite、DeepLabV3,尤其是 EfficientDet-D1,仍然很困難 [15]。
判讀證據
「W4A8」表示 4 位元權重與 8 位元激活值。範圍設定的消融實驗只量化權重(激活值保持浮點)或只量化激活值(權重保持浮點),所以它們一次只隔離一個誤差來源。PTQ 結果是 5 次執行的平均,QAT 結果是 3 次;DeepLabV3 以 Pascal VOC 上的 mIoU 評分,EfficientDet-D1 以 COCO 上的 mAP 評分,分類器以 ImageNet top-1 評分,所以不同列的差異不在同一個尺度上。請看逐張量與逐通道的欄位:它們顯示哪些模型受限於通道範圍的不平衡。
限制與問題
這篇論文對所有層只考慮一種位元寬度(沒有混合精度)、只考慮均勻整數格式,並且主要是 2021 年以前的模型;Transformer 是透過 BERT 出現的,在 PTQ 下它有一些激活值必須保留在 16 位元 [15]。
結論
它是本章實務規則最直接的來源:對稱的權重與非對稱的激活值、硬體允許時權重逐通道、MSE 範圍設定、深度網路的跨層均衡化、先 PTQ,PTQ 不夠時再 QAT。
參考文獻
- M. Dehghani, A. Arnab, L. Beyer, A. Vaswani and Y. Tay, “The efficiency misnomer,” ICLR, 2022. arXiv
- S. Williams, A. Waterman and D. Patterson, “Roofline: an insightful visual performance model for multicore architectures,” Communications of the ACM, vol. 52, no. 4, pp. 65–76, 2009. doi
- Z. Liu, M. Sun, T. Zhou, G. Huang and T. Darrell, “Rethinking the value of network pruning,” ICLR, 2019. arXiv
- D. Blalock, J. J. Gonzalez Ortiz, J. Frankle and J. Guttag, “What is the state of neural network pruning?,” MLSys, 2020. arXiv
- H. Li, A. Kadav, I. Durdanovic, H. Samet and H. P. Graf, “Pruning filters for efficient ConvNets,” ICLR, 2017. arXiv
- A. Mishra, J. Albericio Latorre, J. Pool, D. Stosic, D. Stosic, G. Venkatesh, C. Yu and P. Micikevicius, “Accelerating sparse deep neural networks,” arXiv:2104.08378, 2021. arXiv
- Z. Liu, J. Li, Z. Shen, G. Huang, S. Yan and C. Zhang, “Learning efficient convolutional networks through network slimming,” ICCV, 2017. arXiv
- T. Hoefler, D. Alistarh, T. Ben-Nun, N. Dryden and A. Peste, “Sparsity in deep learning: pruning and growth for efficient inference and training in neural networks,” Journal of Machine Learning Research, vol. 22, no. 241, pp. 1–124, 2021. paper
- G. Fang, X. Ma, M. Song, M. B. Mi and X. Wang, “DepGraph: towards any structural pruning,” CVPR, 2023. doi arXiv
- S. Han, J. Pool, J. Tran and W. J. Dally, “Learning both weights and connections for efficient neural networks,” NeurIPS (NIPS), 2015. arXiv
- S. Han, H. Mao and W. J. Dally, “Deep compression: compressing deep neural networks with pruning, trained quantization and Huffman coding,” ICLR, 2016. arXiv
- M. Zhu and S. Gupta, “To prune, or not to prune: exploring the efficacy of pruning for model compression,” arXiv:1710.01878, 2017. arXiv
- J. Frankle and M. Carbin, “The lottery ticket hypothesis: finding sparse, trainable neural networks,” ICLR, 2019. arXiv
- J. Frankle, G. K. Dziugaite, D. M. Roy and M. Carbin, “Linear mode connectivity and the lottery ticket hypothesis,” ICML, 2020. arXiv
- M. Nagel, M. Fournarakis, R. A. Amjad, Y. Bondarenko, M. van Baalen and T. Blankevoort, “A white paper on neural network quantization,” arXiv:2106.08295, 2021. arXiv
- B. Jacob, S. Kligys, B. Chen, M. Zhu, M. Tang, A. Howard, H. Adam and D. Kalenichenko, “Quantization and training of neural networks for efficient integer-arithmetic-only inference,” CVPR, 2018. doi arXiv
- M. Nagel, M. van Baalen, T. Blankevoort and M. Welling, “Data-free quantization through weight equalization and bias correction,” ICCV, 2019. arXiv
- T. Dettmers, M. Lewis, Y. Belkada and L. Zettlemoyer, “LLM.int8(): 8-bit matrix multiplication for transformers at scale,” NeurIPS, 2022. arXiv
- G. Xiao, J. Lin, M. Seznec, H. Wu, J. Demouth and S. Han, “SmoothQuant: accurate and efficient post-training quantization for large language models,” ICML, 2023. arXiv
- M. Nagel, R. A. Amjad, M. van Baalen, C. Louizos and T. Blankevoort, “Up or down? Adaptive rounding for post-training quantization,” ICML, 2020. arXiv
- Y. Bengio, N. Léonard and A. Courville, “Estimating or propagating gradients through stochastic neurons for conditional computation,” arXiv:1308.3432, 2013. arXiv
- Z. Dong, Z. Yao, A. Gholami, M. W. Mahoney and K. Keutzer, “HAWQ: Hessian aware quantization of neural networks with mixed-precision,” ICCV, 2019. arXiv
- K. Wang, Z. Liu, Y. Lin, J. Lin and S. Han, “HAQ: hardware-aware automated quantization with mixed precision,” CVPR, 2019. arXiv
- P. Micikevicius et al., “FP8 formats for deep learning,” arXiv:2209.05433, 2022. arXiv
- G. Hinton, O. Vinyals and J. Dean, “Distilling the knowledge in a neural network,” NIPS Deep Learning Workshop, 2014; arXiv:1503.02531. arXiv
- L. J. Ba and R. Caruana, “Do deep nets really need to be deep?,” NeurIPS (NIPS), 2014. arXiv
- A. Romero, N. Ballas, S. E. Kahou, A. Chassang, C. Gatta and Y. Bengio, “FitNets: hints for thin deep nets,” ICLR, 2015. arXiv
- S. Zagoruyko and N. Komodakis, “Paying more attention to attention: improving the performance of convolutional neural networks via attention transfer,” ICLR, 2017. arXiv
- J. Gou, B. Yu, S. J. Maybank and D. Tao, “Knowledge distillation: a survey,” International Journal of Computer Vision, vol. 129, no. 6, pp. 1789–1819, 2021. doi
- L. Beyer, X. Zhai, A. Royer, L. Markeeva, R. Anil and A. Kolesnikov, “Knowledge distillation: a good teacher is patient and consistent,” CVPR, 2022. arXiv
- J. H. Cho and B. Hariharan, “On the efficacy of knowledge distillation,” ICCV, 2019. arXiv
- H. Touvron, M. Cord, M. Douze, F. Massa, A. Sablayrolles and H. Jégou, “Training data-efficient image transformers & distillation through attention,” ICML, 2021. arXiv
- R. Denton, W. Zaremba, J. Bruna, Y. LeCun and R. Fergus, “Exploiting linear structure within convolutional networks for efficient evaluation,” NeurIPS (NIPS), 2014. arXiv
- M. Jaderberg, A. Vedaldi and A. Zisserman, “Speeding up convolutional neural networks with low rank expansions,” BMVC, 2014. arXiv
- X. Zhang, J. Zou, K. He and J. Sun, “Accelerating very deep convolutional networks for classification and detection,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 38, no. 10, pp. 1943–1955, 2016. doi arXiv
- A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto and H. Adam, “MobileNets: efficient convolutional neural networks for mobile vision applications,” arXiv:1704.04861, 2017. arXiv
- M. Sandler, A. Howard, M. Zhu, A. Zhmoginov and L.-C. Chen, “MobileNetV2: inverted residuals and linear bottlenecks,” CVPR, 2018. arXiv
- M. Tan and Q. V. Le, “EfficientNet: rethinking model scaling for convolutional neural networks,” ICML, 2019. arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: making VGG-style ConvNets great again,” CVPR, 2021. arXiv
- C. Li et al., “YOLOv6: a single-stage object detection framework for industrial applications,” arXiv:2209.02976, 2022. arXiv
- T. Elsken, J. H. Metzen and F. Hutter, “Neural architecture search: a survey,” Journal of Machine Learning Research, vol. 20, pp. 1–21, 2019. arXiv
- B. Zoph and Q. V. Le, “Neural architecture search with reinforcement learning,” ICLR, 2017. arXiv
- H. Pham, M. Y. Guan, B. Zoph, Q. V. Le and J. Dean, “Efficient neural architecture search via parameter sharing,” ICML, 2018. arXiv
- H. Liu, K. Simonyan and Y. Yang, “DARTS: differentiable architecture search,” ICLR, 2019. arXiv
- H. Cai, C. Gan, T. Wang, Z. Zhang and S. Han, “Once-for-all: train one network and specialize it for efficient deployment,” ICLR, 2020. arXiv
- M. Tan, B. Chen, R. Pang, V. Vasudevan, M. Sandler, A. Howard and Q. V. Le, “MnasNet: platform-aware neural architecture search for mobile,” CVPR, 2019. arXiv
- H. Cai, L. Zhu and S. Han, “ProxylessNAS: direct neural architecture search on target task and hardware,” ICLR, 2019. arXiv
- B. Wu, X. Dai, P. Zhang, Y. Wang, F. Sun, Y. Wu, Y. Tian, P. Vajda, Y. Jia and K. Keutzer, “FBNet: hardware-aware efficient ConvNet design via differentiable neural architecture search,” CVPR, 2019. doi arXiv
- L. Li and A. Talwalkar, “Random search and reproducibility for neural architecture search,” UAI, 2019. arXiv
- S. Ioffe and C. Szegedy, “Batch normalization: accelerating deep network training by reducing internal covariate shift,” ICML, 2015. arXiv
- T. Wang, L. Yuan, X. Zhang and J. Feng, “Distilling object detectors with fine-grained feature imitation,” CVPR, 2019. arXiv
- H. Li, C. Yan, S. Lin, X. Zheng, Y. Li, B. Zhang, F. Yang and R. Ji, “PAMS: quantized super-resolution via parameterized max scale,” ECCV, 2020. arXiv
- C. Hong, H. Kim, S. Baik, J. Oh and K. M. Lee, “DAQ: channel-wise distribution-aware quantization for deep image super-resolution networks,” WACV, 2022. arXiv
- B. Ren, Y. Li, N. Mehta, R. Timofte et al., “The ninth NTIRE 2024 efficient super-resolution challenge report,” CVPR Workshops, 2024. doi arXiv
- Z. Yuan, C. Xue, Y. Chen, Q. Wu and G. Sun, “PTQ4ViT: post-training quantization for vision transformers with twin uniform quantization,” ECCV, 2022. doi arXiv
- Z. Liu, Y. Wang, K. Han, S. Ma and W. Gao, “Post-training quantization for vision transformer,” NeurIPS, 2021. arXiv
- X. Li, Y. Liu, L. Lian, H. Yang, Z. Dong, D. Kang, S. Zhang and K. Keutzer, “Q-Diffusion: quantizing diffusion models,” ICCV, 2023. doi arXiv
- Y. Shang, Z. Yuan, B. Xie, B. Wu and Y. Yan, “Post-training quantization on diffusion models,” CVPR, 2023. arXiv
- A. Kirillov et al., “Segment anything,” ICCV, 2023. doi arXiv
- C. Zhang, D. Han, Y. Qiao, J. U. Kim, S.-H. Bae, S. Lee and C. S. Hong, “Faster segment anything: towards lightweight SAM for mobile applications,” arXiv:2306.14289, 2023. arXiv
- Y. Xiong et al., “EfficientSAM: leveraged masked image pretraining for efficient segment anything,” CVPR, 2024. doi arXiv
- Y. Cheng, D. Wang, P. Zhou and T. Zhang, “Model compression and acceleration for deep neural networks: the principles, progress, and challenges,” IEEE Signal Processing Magazine, vol. 35, no. 1, pp. 126–136, 2018. doi arXiv
- G. Menghani, “Efficient deep learning: a survey on making deep learning models smaller, faster, and better,” ACM Computing Surveys, vol. 55, no. 12, pp. 1–37, 2023. doi arXiv
- A. Gholami, S. Kim, Z. Dong, Z. Yao, M. W. Mahoney and K. Keutzer, “A survey of quantization methods for efficient neural network inference,” book chapter in Low-Power Computer Vision; arXiv:2103.13630, 2021. arXiv
- H. Cheng, M. Zhang and J. Q. Shi, “A survey on deep neural network pruning: taxonomy, comparison, analysis, and recommendations,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 46, no. 12, pp. 10558–10578, 2024. doi arXiv
- L. Wang and K.-J. Yoon, “Knowledge distillation and student-teacher learning for visual intelligence: a review and new outlooks,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 6, pp. 3048–3068, 2022. doi arXiv
- C. White, M. Safari, R. Sukthanker, B. Ru, T. Elsken, A. Zela, D. Dey and F. Hutter, “Neural architecture search: insights from 1000 papers,” arXiv:2301.08727, 2023. arXiv
- E. Frantar, S. Ashkboos, T. Hoefler and D. Alistarh, “GPTQ: accurate post-training quantization for generative pre-trained transformers,” ICLR, 2023. arXiv
- J. Lin, J. Tang, H. Tang, S. Yang, W.-M. Chen, W.-C. Wang, G. Xiao, X. Dang, C. Gan and S. Han, “AWQ: activation-aware weight quantization for LLM compression and acceleration,” MLSys, 2024. arXiv
- M. Li, Y. Lin, Z. Zhang, T. Cai, X. Li, J. Guo, E. Xie, C. Meng, J.-Y. Zhu and S. Han, “SVDQuant: absorbing outliers by low-rank components for 4-bit diffusion models,” ICLR, 2025. arXiv
- Y. Li, R. Gong, X. Tan, Y. Yang, P. Hu, Q. Zhang, F. Yu, W. Wang and S. Gu, “BRECQ: pushing the limit of post-training quantization by block reconstruction,” ICLR, 2021. arXiv
- S. K. Esser, J. L. McKinstry, D. Bablani, R. Appuswamy and D. S. Modha, “Learned step size quantization,” ICLR, 2020. arXiv