理解無參考低光指標
選讀・DLCV 09C・低光影像增強 的補充資料(第 9/14 則)。主線不依賴這則補充;引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
本頁內容
- KinD:修復反射率,另外控制照明
- Retinex-Net:分解、調光、去雜訊
- EnlightenGAN:未配對外觀與內容約束
- Zero-DCE/Zero-DCE++:沒有參考影像的曲線學習
- RUAS:搜尋展開模型中的先驗
- SCI:訓練校準,部署一個照明區塊
- Retinexformer:以照明引導復原
- IAT:局部仿射圖與全域相機式轉換
- Multinex:以解析先驗融合出 Retinex 殘差
- CPGA-Net:通道先驗、gamma 估計與學習式融合
- CPGA-Net+:注意力、BDSF 與較強版本
- HDRNet:Deep bilateral learning for real-time image enhancement
- 影像自適應 3D LUT(Zeng 等人,TPAMI 2022)
電腦視覺深度學習
白話版。 有些量測直接針對增強時會出錯的地方:方法有沒有把「哪裡比較亮」的關係顛倒?顏色是鮮豔還是褪色?調亮之後露出了多少雜訊?
明度順序誤差(Lightness Order Error, LOE)。 NPE 論文 [13] 主張,自然的增強應該保留場景中明度的相對順序:如果燈原本比牆亮,增強後也應該如此,因為這個順序承載了光的方向與深度感。LOE 計算兩個像素的明暗順序被翻轉的次數。令 為輸入的明度, 為增強後影像的明度,
其中 是像素數, 時 、否則為 0, 是互斥或(XOR),因此 就是相對於 改變了順序的像素個數。越低越好。實務上有三點要注意:
- 計算量是 ,所以實作會在降取樣後的影像上計算 LOE。原始數值會隨 增加,只有在相同的降取樣設定下才能比較,而許多論文並未說明自己的設定。
- 比較的基準是輸入,而不是乾淨影像。任何在最大值通道上單調的色調曲線都會得到 LOE ,包括什麼都不做。而且暗輸入裡的雜訊早已打亂相鄰像素的順序,所以去除雜訊的方法反而會被懲罰。
- LOE 完全不管結果夠不夠亮。它是防止不自然局部色調映射的護欄,不是品質分數。
色彩豐富度(colorfulness)。 Hasler 與 Süsstrunk [62] 以 8 位元 RGB 上的對立色軸,擬合出一個與主觀感受相符的簡單色彩豐富度量:
其中 與 是整張影像上的平均與標準差,權重 0.3 來自作者的擬合。越高代表色彩越豐富。它適合當作描述性統計量,用來偵測褪色(只增強亮度通道,圖 2)或過飽和,但它不知道什麼才是正確的顏色,而色度通道裡的雜訊會灌大 與 。
輸出的雜訊程度。 既然調亮會讓雜訊現形(圖 1),回報輸出的雜訊程度就很有幫助。Immerkær 的快速估計法 [63] 用一個能抵消平滑結構、保留雜訊的遮罩對影像濾波:
其中 是影像大小,總和只取內部像素。它假設雜訊是白高斯雜訊,所以遇到紋理豐富的影像會高估,遇到空間相關的雜訊(真實相機管線與許多網路產生的正是這種)則會低估。請只用它比較同一張輸入的不同輸出,不要跨場景比較。
下面的程式碼重建圖 1 的暗咖啡杯影像,比較五種「增強」結果與乾淨照片。
程式碼 · Python · 53 行
import numpy as np
from scipy import ndimage as ndi
from skimage import color, data, exposure, img_as_float

rng = np.random.default_rng(0)
clean = img_as_float(data.coffee())

def synth_low_light(x, k=0.05, peak=2000.0, read_std=8e-4, gamma=2.2):   # as in Figure 1
    lin = k * x ** gamma
    lin = rng.poisson(lin * peak) / peak
    lin = lin + rng.normal(0, read_std, lin.shape)
    return np.round(np.clip(lin, 0, 1) ** (1 / gamma) * 255) / 255

def loe(ref, out, step=8):
    """Lightness Order Error on a strided subsample (m = 50 x 75 = 3750 pixels here)."""
    L, Le = (im.max(axis=2)[::step, ::step].ravel() for im in (ref, out))
    U, Ue = L[:, None] >= L[None, :], Le[:, None] >= Le[None, :]
    return (U ^ Ue).sum(axis=1).mean()                  # mean over x of RD(x)

def colorfulness(im):
    """Hasler-Suesstrunk colorfulness, RGB scaled to 0..255."""
    R, G, B = (255 * im[..., c] for c in range(3))
    rg, yb = R - G, 0.5 * (R + G) - B
    return np.hypot(rg.std(), yb.std()) + 0.3 * np.hypot(rg.mean(), yb.mean())

def noise_sigma(im):
    """Immerkaer's noise estimate on BT.601 luma, in 8-bit units."""
    Y = 255 * (0.299 * im[..., 0] + 0.587 * im[..., 1] + 0.114 * im[..., 2])
    N = np.array([[1, -2, 1], [-2, 4, -2], [1, -2, 1]])
    H, W = Y.shape
    return np.sqrt(np.pi / 2) / (6 * (W - 2) * (H - 2)) * np.abs(ndi.convolve(Y, N)[1:-1, 1:-1]).sum()

dark = synth_low_light(clean)
lab = color.rgb2lab(dark); L = lab[..., 0] / 100
he = lab.copy(); he[..., 0] = 100 * exposure.equalize_hist(L)
cl = lab.copy(); cl[..., 0] = 100 * exposure.equalize_adapthist(L, clip_limit=0.01)
outputs = {
    "dark input": dark,
    "gain x20 (linear)": np.clip(20 * dark ** 2.2, 0, 1) ** (1 / 2.2),
    "gamma 0.4": dark ** 0.4,
    "HE on L*": np.clip(color.lab2rgb(he), 0, 1),
    "CLAHE on L*": np.clip(color.lab2rgb(cl), 0, 1),
    "clean reference": clean,
}
for name, im in outputs.items():
    print(f"{name:18s} mean {im.mean():.2f}  LOE {loe(dark, im):6.1f}  "
          f"colorfulness {colorfulness(im):5.1f}  noise {noise_sigma(im):5.2f}")
# dark input         mean 0.10  LOE    0.0  colorfulness  23.1  noise  3.32
# gain x20 (linear)  mean 0.39  LOE    0.3  colorfulness  90.0  noise 12.93
# gamma 0.4          mean 0.34  LOE    0.0  colorfulness  61.6  noise 11.19
# HE on L*           mean 0.48  LOE  334.7  colorfulness  28.3  noise 16.17
# CLAHE on L*        mean 0.40  LOE  657.6  colorfulness  27.1  noise 23.06
# clean reference    mean 0.39  LOE  322.0  colorfulness  76.9  noise  4.69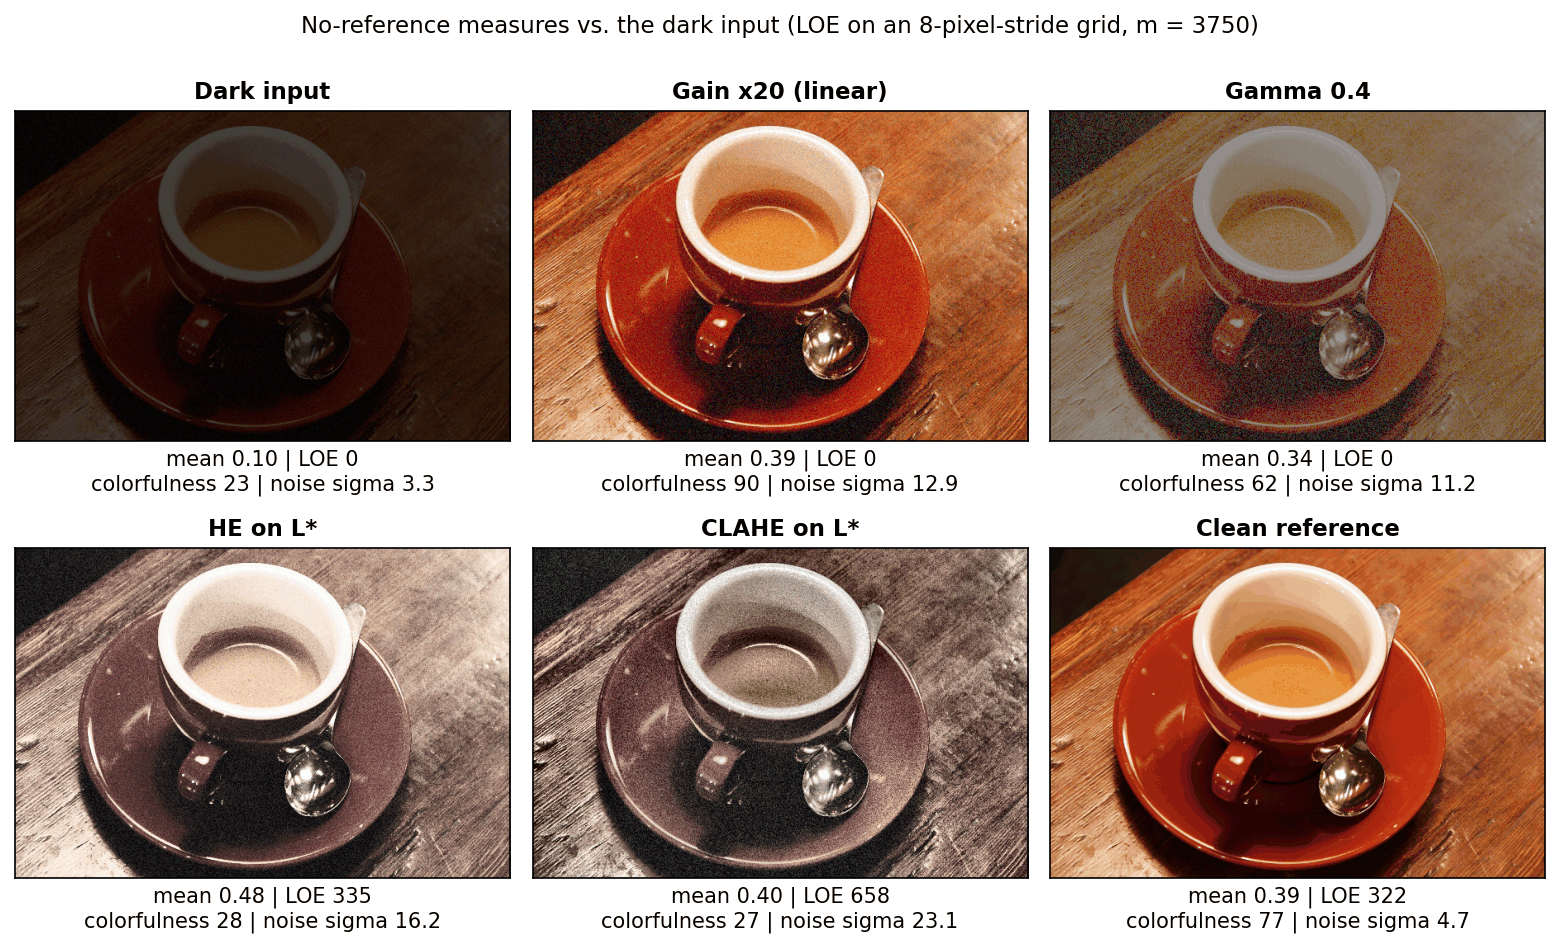
這些數字要一起看,不能各看各的:
- 只看亮度會排錯順序。 HE 的平均最高(0.48),但 LOE 也很大、雜訊第二高,顏色幾乎都沒了。CLAHE 的局部重新映射則是破壞明度順序最嚴重的。
- 色彩豐富度會被雜訊騙。 線性增益得到 90,高於乾淨照片的 77,部分原因是被放大的色度雜訊拉高了 與 。
- LOE 懲罰復原。 乾淨照片明明是理想答案,相對於有雜訊的輸入卻得到 LOE 322;什麼都不做反而是 0。低 LOE 是自然色調曲線的必要條件,而不是品質的充分條件。
- 只有雜訊估計把乾淨照片(4.7)與明亮但多雜訊的輸出(11 到 23)區分開來。沒有任何單一的無參考數字能同時涵蓋「曝光良好、顏色自然、乾淨無雜訊」。
學得的無參考評估器
神經網路與視覺語言評估器(NIMA、MUSIQ、CLIP-IQA、MANIQA、Q-Align 等)請見 DLCV 09 與 DLCV 09;它們都可以套用在 LLIE 的輸出上,也有共用的實作,例如 IQA-PyTorch 工具箱 [81]。以下三點是低光特有的:
- 解析度。 不做縮放對 LLIE 很重要,因為雜訊與細紋理正是縮放會藏起來的東西,所以像 MUSIQ [82] 這類以影像原始解析度輸入的評估器特別適合。
- 曝光提示詞與獨立性。 CLIP-IQA [83] 可以改用針對曝光的提示詞對來探測,例如「Bright photo.」/「Dark photo.」,對曝光評估很方便,但用字不同分數就會不同。同樣的 CLIP 相似度想法也被 CLIP-LIT [42] 當作訓練訊號,所以 CLIP 類指標不應該是評判以 CLIP 訓練之增強器的唯一裁判。
- 低光專用的評估器。 Kannan 等人 [84](2023)針對不同 LLIE 方法復原的影像收集人類主觀評分,以此評測現有的無參考 IQA 模型,並提出一個不需主觀評分(opinion-unaware)的模型:以自監督對比學習,學出對低光復原影像失真敏感的特徵。這類資料集才是決定「在增強輸出上該信任哪個指標」的正確測試平台。
低光情境下的注意事項。 學習式評估器多半以白天照片訓練。它們傾向給更亮、更銳利、更飽和的影像高分,因而偏好過度增強;一張刻意保留暗調的夜景,即使是最忠實的結果,也可能被扣分。分數取決於權重檔(用哪個訓練集)、輸入尺寸與實作,這些都應該回報。另外,當一個方法在損失函數中使用了某個學習式指標或相同的骨幹網路時,那個指標就不再是獨立的裁判。
使用者研究與配對比較
平均意見分數(標準見 ITU-R BT.500 [85])、Bradley–Terry 成對比較 [86],以及進行研究的良好做法,請見 DLCV 09。兩篇低光論文示範了典型做法:
- Zero-DCE [18] 請 15 位受試者以 1–5 分評分 NPE、LIME、MEF、DICM 與 VV 共 202 張影像的結果,並指示他們留意過曝或曝光不足、色彩偏差,以及不自然的紋理或雜訊。
- EnlightenGAN [17] 採用成對比較:9 位受試者在 23 張影像上,比較五種方法輸出的配對,判斷是否有可見雜訊、曝光假影,以及不真實的顏色或紋理,再以 Bradley–Terry 擬合得到排名。
給評分者的判準(曝光、色彩偏差、雜訊、不自然的紋理),是設計新的低光研究時很好的起始清單。
選擇並報告無參考指標
NR 指標的通用比較(類別、是否需要訓練、方向、敏感性)是 DLCV 09 補充資料中的逐一指標總覽表,其建議做法在此完全適用。下表只保留低光輸出會有所不同的部分。
| 指標 | 方向 | 低光情境的注意事項 |
|---|---|---|
| NIQE [58] | 越低越好 | 幾乎看不到整體曝光與色彩;可能偏好多雜訊、高對比的輸出 |
| BRISQUE [59] | 越低越好 | 以白天失真訓練;忽略色偏 |
| PI [60], [61] | 越低越好 | 為超解析度設計;獎勵細節,包括被放大的雜訊 |
| LOE [13](任務專用) | 越低越好 | 取決於降取樣;什麼都不做得 0;懲罰去噪 |
| 色彩豐富度 [62](任務專用、描述性) | 視情況而定 | 不知道正確顏色;會被色度雜訊灌大 |
| 雜訊估計 [63](任務專用、描述性) | 越低越好 | 假設白雜訊;會被紋理與相關雜訊混淆 |
| NIMA [87] | 越高越好 | 美感模型獎勵好看而非忠實的結果 |
| MUSIQ [82] | 越高越好 | 多以白天照片訓練;依權重檔而定 |
| CLIP-IQA [83] | 越高越好 | 提示詞用字有影響;對以 CLIP 訓練的增強器不獨立 |
| MANIQA [88] | 越高越好 | 並非專門針對曝光錯誤訓練 |
| Q-Align [89] | 越高越好 | 運算量大;繼承基礎模型的偏差;依版本而定 |
| MOS/成對比較 [85], [86] | MOS 越高/強度越高 | 成本高;小規模研究雜訊大;必須回報協定 |
在通用做法之外,還要做的事:
- 在成對資料集上,以標準協定下的全參考指標(PSNR、SSIM、LPIPS)為主,無參考分數只作為補充。
- 在非配對資料集上,回報多個來自不同類別的無參考指標(一個 NSS、一到兩個學習式,以及 LOE),說明實作、權重檔與影像尺寸,並展示大量視覺範例,包括失敗案例。
- 預期會有分歧。 NSS 與學習式指標對方法的排名經常不同,兩者也都可能與人的判斷不一致;Li 等人的綜述 [15] 指出指標分數與視覺品質常常不符,Liu 與 Fan [66] 則發現畫質與下游任務表現之間還有另一道落差。指標意見不一時,請直接說明,而不是只挑對自己有利的那一個。
參考文獻
- Shyandram, “簡介Deep Learning Low-Light Image Enhancement (LLIE)” (Introduction to deep-learning low-light image enhancement, in Chinese), Medium post, 2024; updated 2026. link
- A. Foi, M. Trimeche, V. Katkovnik and K. Egiazarian, “Practical Poissonian-Gaussian noise modeling and fitting for single-image raw-data,” IEEE Transactions on Image Processing, vol. 17, no. 10, pp. 1737–1754, 2008. doi
- K. He, J. Sun and X. Tang, “Single image haze removal using dark channel prior,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 33, no. 12, pp. 2341–2353, 2011. doi
- X. Guo, Y. Li and H. Ling, “LIME: Low-light image enhancement via illumination map estimation,” IEEE Transactions on Image Processing, vol. 26, no. 2, pp. 982–993, 2017. doi
- ITU-R, “Recommendation BT.601-7: Studio encoding parameters of digital television for standard 4:3 and wide-screen 16:9 aspect ratios,” 2011. ITU
- Q. Yan, Y. Feng, C. Zhang, et al., “HVI: A new color space for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2025. arXiv
- S. M. Pizer, E. P. Amburn, J. D. Austin, et al., “Adaptive histogram equalization and its variations,” Computer Vision, Graphics, and Image Processing, vol. 39, no. 3, pp. 355–368, 1987. doi
- K. Zuiderveld, “Contrast limited adaptive histogram equalization,” in Graphics Gems IV, Academic Press, 1994, pp. 474–485. doi
- E. H. Land, “The retinex theory of color vision,” Scientific American, vol. 237, no. 6, pp. 108–128, 1977. doi
- D. J. Jobson, Z. Rahman and G. A. Woodell, “Properties and performance of a center/surround retinex,” IEEE Transactions on Image Processing, vol. 6, pp. 451–462, 1997. doi
- D. J. Jobson, Z. Rahman and G. A. Woodell, “A multiscale retinex for bridging the gap between color images and the human observation of scenes,” IEEE Transactions on Image Processing, vol. 6, no. 7, pp. 965–976, 1997. doi
- X. Dong, Y. Pang and J. Wen, “Fast efficient algorithm for enhancement of low lighting video,” ACM SIGGRAPH 2010 Posters, 2010. SIGGRAPH history doi
- S. Wang, J. Zheng, H.-M. Hu and B. Li, “Naturalness preserved enhancement algorithm for non-uniform illumination images,” IEEE Transactions on Image Processing, vol. 22, no. 9, pp. 3538–3548, 2013. doi
- C. Lee, C. Lee and C.-S. Kim, “Contrast enhancement based on layered difference representation of 2D histograms,” IEEE Transactions on Image Processing, vol. 22, no. 12, pp. 5372–5384, 2013. doi
- C. Li, C. Guo, L. Han, J. Jiang, M.-M. Cheng, J. Gu and C. C. Loy, “Low-light image and video enhancement using deep learning: A survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 12, pp. 9396–9416, 2022. arXiv
- C. Wei, W. Wang, W. Yang and J. Liu, “Deep retinex decomposition for low-light enhancement,” in Proc. British Machine Vision Conference (BMVC), 2018. arXiv project
- Y. Jiang, X. Gong, D. Liu, et al., “EnlightenGAN: Deep light enhancement without paired supervision,” IEEE Transactions on Image Processing, vol. 30, pp. 2340–2349, 2021. arXiv
- C. Guo, C. Li, J. Guo, et al., “Zero-reference deep curve estimation for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2020, pp. 1777–1786. arXiv
- C. Li, C. Guo and C. C. Loy, “Learning to enhance low-light image via zero-reference deep curve estimation,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 8, 2022. arXiv
- R. Liu, L. Ma, J. Zhang, X. Fan and Z. Luo, “Retinex-inspired unrolling with cooperative prior architecture search for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2021, pp. 10556–10565. arXiv
- L. Ma, T. Ma, R. Liu, X. Fan and Z. Luo, “Toward fast, flexible, and robust low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 5627–5636. arXiv
- Y. Cai, H. Bian, J. Lin, H. Wang, R. Timofte and Y. Zhang, “Retinexformer: One-stage Retinex-based transformer for low-light image enhancement,” in Proc. IEEE/CVF ICCV, 2023. arXiv code
- Y. Wang, R. Wan, W. Yang, H. Li, L.-P. Chau and A. C. Kot, “Low-light image enhancement with normalizing flow,” in Proc. AAAI Conference on Artificial Intelligence, vol. 36, no. 3, pp. 2604–2612, 2022. arXiv
- X. Yi, H. Xu, H. Zhang, L. Tang and J. Ma, “Diff-Retinex: Rethinking low-light image enhancement with a generative diffusion model,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- J. Hou, Z. Zhu, J. Hou, H. Liu, H. Zeng and H. Yuan, “Global structure-aware diffusion process for low-light image enhancement,” in Advances in Neural Information Processing Systems (NeurIPS), 2023. arXiv
- H. Jiang, A. Luo, X. Liu, S. Han and S. Liu, “LightenDiffusion: Unsupervised low-light image enhancement with latent-Retinex diffusion models,” in Proc. European Conference on Computer Vision (ECCV), 2024. arXiv
- C. He, C. Fang, Y. Zhang, et al., “Reti-Diff: Illumination degradation image restoration with Retinex-based latent diffusion model,” in Proc. International Conference on Learning Representations (ICLR), 2025. proceedings
- M. Gharbi, J. Chen, J. T. Barron, S. W. Hasinoff and F. Durand, “Deep bilateral learning for real-time image enhancement,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 36, no. 4, art. 118, 2017. doi arXiv
- H. Zeng, J. Cai, L. Li, Z. Cao and L. Zhang, “Learning image-adaptive 3D lookup tables for high performance photo enhancement in real-time,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 4, 2022. doi arXiv
- K. G. Lore, A. Akintayo and S. Sarkar, “LLNet: A deep autoencoder approach to natural low-light image enhancement,” Pattern Recognition, vol. 61, pp. 650–662, 2017. doi
- L. Tao, C. Zhu, J. Song, T. Lu, H. Jia and X. Xie, “Low-light image enhancement using CNN and bright channel prior,” in Proc. IEEE International Conference on Image Processing (ICIP), 2017, pp. 3215–3219. doi
- S. W. Zamir, A. Arora, S. Khan, et al., “Learning enriched features for real image restoration and enhancement,” in Proc. European Conference on Computer Vision (ECCV), 2020, pp. 492–511. arXiv
- X. Xu, R. Wang, C.-W. Fu and J. Jia, “SNR-aware low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 17693–17703. doi
- Z. Cui, K. Li, L. Gu, S. Su, P. Gao, Z. Jiang, Y. Qiao and T. Harada, “You only need 90K parameters to adapt light: A light weight transformer for image enhancement and exposure correction,” in Proc. British Machine Vision Conference (BMVC), 2022. paper arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, 2021, pp. 13728–13737. doi arXiv
- Y. Zhang, J. Zhang and X. Guo, “Kindling the darkness: A practical low-light image enhancer,” in Proc. ACM International Conference on Multimedia (ACM MM), 2019, pp. 1632–1640. doi
- Y. Zhang, X. Guo, J. Ma, W. Liu and J. Zhang, “Beyond brightening low-light images,” International Journal of Computer Vision, vol. 129, no. 4, pp. 1013–1037, 2021. doi
- J. Bai, Y. Yin, Q. He, Y. Li and X. Zhang, “RetinexMamba: Retinex-based Mamba for low-light image enhancement,” arXiv:2405.03349, 2024. arXiv
- S.-E. Weng, S.-G. Miaou and R. Christanto, “A lightweight low-light image enhancement network via channel prior and gamma correction,” International Journal of Pattern Recognition and Artificial Intelligence, vol. 39, no. 12, art. 2554013, 2025. doi code manuscript
- S.-E. Weng, C.-Y. Hsiao, L.-W. Lu, et al., “Rethinking theoretical illumination for efficient low-light image enhancement” (CPGA-Net+), arXiv:2409.05274, 2024. arXiv
- W. Wu, J. Weng, P. Zhang, X. Wang, W. Yang and J. Jiang, “URetinex-Net: Retinex-based deep unfolding network for low-light image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 5891–5900. doi
- Z. Liang, C. Li, S. Zhou, R. Feng and C. C. Loy, “Iterative prompt learning for unsupervised backlit image enhancement,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- C. Yang, M. Jin, X. Jia, Y. Xu and Y. Chen, “AdaInt: Learning adaptive intervals for 3D lookup tables on real-time image enhancement,” in Proc. IEEE/CVF CVPR, 2022, pp. 17522–17531. CVF arXiv
- C. Yang, M. Jin, Y. Xu, R. Zhang, Y. Chen and H. Liu, “SepLUT: Separable image-adaptive lookup tables for real-time image enhancement,” in Proc. European Conference on Computer Vision (ECCV), 2022, pp. 201–217. doi arXiv
- T. Wang, Y. Li, J. Peng, Y. Ma, X. Wang, F. Song and Y. Yan, “Real-time image enhancer via learnable spatial-aware 3D lookup tables,” in Proc. IEEE/CVF ICCV, 2021, pp. 2471–2480. CVF arXiv
- C. Liu, H. Yang, J. Fu and X. Qian, “4D LUT: Learnable context-aware 4D lookup table for image enhancement,” IEEE Transactions on Image Processing, vol. 32, pp. 4742–4756, 2023. doi arXiv
- W. Kim and N. I. Cho, “Image-adaptive 3D lookup tables for real-time image enhancement with bilateral grids,” in Proc. European Conference on Computer Vision (ECCV), 2024, pp. 91–108. doi ECCV
- C. Chen, Q. Chen, J. Xu and V. Koltun, “Learning to see in the dark,” in Proc. IEEE/CVF CVPR, 2018, pp. 3291–3300. arXiv
- M. V. Conde, G. Geigle and R. Timofte, “InstructIR: High-quality image restoration following human instructions,” in Proc. European Conference on Computer Vision (ECCV), 2024. arXiv
- Z. Cui, G.-J. Qi, L. Gu, S. You, Z. Zhang and T. Harada, “Multitask AET with orthogonal tangent regularity for dark object detection,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- K. A. Hashmi, G. Kallempudi, D. Stricker and M. Z. Afzal, “FeatEnHancer: Enhancing hierarchical features for object detection and beyond under low-light vision,” in Proc. IEEE/CVF ICCV, 2023. arXiv
- M. Dehghani, A. Arnab, L. Beyer, A. Vaswani and Y. Tay, “The efficiency misnomer,” in Proc. International Conference on Learning Representations (ICLR), 2022. ICLR arXiv
- A. Ignatov, R. Timofte, S. Liu, et al., “Learned smartphone ISP on mobile GPUs with deep learning, Mobile AI & AIM 2022 challenge: Report,” in Proc. European Conference on Computer Vision (ECCV) Workshops, 2023, pp. 44–70. doi arXiv
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image quality assessment: From error visibility to structural similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The unreasonable effectiveness of deep features as a perceptual metric,” in Proc. IEEE/CVF CVPR, 2018. arXiv
- K. Ma, K. Zeng and Z. Wang, “Perceptual quality assessment for multi-exposure image fusion,” IEEE Transactions on Image Processing, vol. 24, no. 11, pp. 3345–3356, 2015. doi
- V. Vonikakis, “Datasets” (source of the VV test images), personal web page. link
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a ‘completely blind’ image quality analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- A. Mittal, A. K. Moorthy and A. C. Bovik, “No-reference image quality assessment in the spatial domain,” IEEE Transactions on Image Processing, vol. 21, no. 12, pp. 4695–4708, 2012. doi
- Y. Blau, R. Mechrez, R. Timofte, T. Michaeli and L. Zelnik-Manor, “The 2018 PIRM challenge on perceptual image super-resolution,” in Proc. European Conference on Computer Vision (ECCV) Workshops, 2018. arXiv
- C. Ma, C.-Y. Yang, X. Yang and M.-H. Yang, “Learning a no-reference quality metric for single-image super-resolution,” Computer Vision and Image Understanding, vol. 158, pp. 1–16, 2017. doi arXiv
- D. Hasler and S. E. Süsstrunk, “Measuring colorfulness in natural images,” in Proc. SPIE 5007, Human Vision and Electronic Imaging VIII, 2003. doi
- J. Immerkær, “Fast noise variance estimation,” Computer Vision and Image Understanding, vol. 64, no. 2, pp. 300–302, 1996. doi
- J. Liao, S. Hao, R. Hong and M. Wang, “GT-Mean loss: A simple yet effective solution for brightness mismatch in low-light image enhancement,” in Proc. IEEE/CVF ICCV, 2025. arXiv
- Y. P. Loh and C. S. Chan, “Getting to know low-light images with the Exclusively Dark dataset,” Computer Vision and Image Understanding, vol. 178, pp. 30–42, 2019. arXiv
- F. Liu and L. Fan, “A review of advancements in low-light image enhancement using deep learning,” Neurocomputing, vol. 652, art. 131052, 2025. arXiv
- J. Liu, D. Xu, W. Yang, M. Fan and H. Huang, “Benchmarking low-light image enhancement and beyond,” International Journal of Computer Vision, vol. 129, no. 4, pp. 1153–1184, 2021. doi project
- W. Yang, W. Wang, H. Huang, S. Wang and J. Liu, “Sparse gradient regularized deep Retinex network for robust low-light image enhancement,” IEEE Transactions on Image Processing, vol. 30, pp. 2072–2086, 2021. doi
- J. Hai, Z. Xuan, R. Yang, et al., “R2RNet: Low-light image enhancement via Real-low to Real-normal Network,” Journal of Visual Communication and Image Representation, vol. 90, art. 103712, 2023. arXiv
- R. Wang, X. Xu, C.-W. Fu, et al., “Seeing dynamic scene in the dark: A high-quality video dataset with mechatronic alignment,” in Proc. IEEE/CVF ICCV, 2021, pp. 9680–9689. doi code
- V. Bychkovsky, S. Paris, E. Chan and F. Durand, “Learning photographic global tonal adjustment with a database of input/output image pairs,” in Proc. IEEE CVPR, 2011, pp. 97–104. dataset
- J. Cai, S. Gu and L. Zhang, “Learning a deep single image contrast enhancer from multi-exposure images,” IEEE Transactions on Image Processing, vol. 27, no. 4, pp. 2049–2062, 2018. doi
- X. Liu, Z. Wu, A. Li, et al., “NTIRE 2024 challenge on low light image enhancement: Methods and results,” in Proc. IEEE/CVF CVPR Workshops, 2024. arXiv
- X. Liu, Z. Wu, F.-A. Vasluianu, et al., “NTIRE 2025 challenge on low light image enhancement: Methods and results,” in Proc. IEEE/CVF CVPR Workshops, 2025. arXiv
- S. Zheng, Y. Ma, J. Pan, C. Lu and G. Gupta, “Low-light image and video enhancement: A comprehensive survey and beyond,” arXiv:2212.10772, 2022. arXiv
- E. Adhikarla, Y. Liu and B. D. Davison, “Diffusion models for low-light image enhancement: A multi-perspective taxonomy and performance analysis,” arXiv:2510.05976, 2025. arXiv
- J. Yan, C. Tu, W. Zhang, Z. Wang, P. Cao, Q. Lin, Y. Fang, X. Liu, Z. Wu, Z. Zhou and R. Timofte, “NTIRE 2026 challenge on efficient low light image enhancement: Methods and results,” NTIRE 2026 workshop report, arXiv:2605.02212, 2026. arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional networks for biomedical image segmentation,” in Proc. Medical Image Computing and Computer-Assisted Intervention (MICCAI), 2015, pp. 234–241. doi arXiv
- J. Chen, A. Adams, N. Wadhwa and S. W. Hasinoff, “Bilateral guided upsampling,” ACM Transactions on Graphics (Proc. SIGGRAPH Asia), vol. 35, no. 6, 2016. doi project
- K. He, J. Sun and X. Tang, “Guided image filtering,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 35, no. 6, pp. 1397–1409, 2013. doi
- C. Chen and J. Mo, “IQA-PyTorch: PyTorch toolbox for image quality assessment,” software (pip package
pyiqa). GitHub - J. Ke, Q. Wang, Y. Wang, P. Milanfar and F. Yang, “MUSIQ: Multi-scale image quality transformer,” in Proc. IEEE/CVF ICCV, 2021. arXiv
- J. Wang, K. C. K. Chan and C. C. Loy, “Exploring CLIP for assessing the look and feel of images,” in Proc. AAAI Conference on Artificial Intelligence, 2023. arXiv
- V. Kannan, S. Malik, N. C. Babu and R. Soundararajan, “Quality assessment of low-light restored images: A subjective study and an unsupervised model,” IEEE Access, vol. 11, pp. 68216–68230, 2023. doi arXiv
- ITU-R, “Recommendation BT.500-15: Methodologies for the subjective assessment of the quality of television images,” 2023. ITU
- R. A. Bradley and M. E. Terry, “Rank analysis of incomplete block designs: The method of paired comparisons,” Biometrika, vol. 39, no. 3–4, pp. 324–345, 1952. doi
- H. Talebi and P. Milanfar, “NIMA: Neural image assessment,” IEEE Transactions on Image Processing, 2018. arXiv
- S. Yang, T. Wu, S. Shi, et al., “MANIQA: Multi-dimension attention network for no-reference image quality assessment,” in Proc. IEEE/CVF CVPR Workshops, 2022, pp. 1190–1199. doi arXiv
- H. Wu, Z. Zhang, W. Zhang, C. Chen, et al., “Q-Align: Teaching LMMs for visual scoring via discrete text-defined levels,” in Proc. International Conference on Machine Learning (ICML), PMLR 235, 2024. arXiv
- A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto and H. Adam, “MobileNets: Efficient convolutional neural networks for mobile vision applications,” arXiv:1704.04861, 2017. arXiv
- M. Sandler, A. Howard, M. Zhu, A. Zhmoginov and L.-C. Chen, “MobileNetV2: Inverted residuals and linear bottlenecks,” in Proc. IEEE/CVF CVPR, 2018, pp. 4510–4520. doi arXiv
- W.-S. Lai, J.-B. Huang, O. Wang, E. Shechtman, E. Yumer and M.-H. Yang, “Learning blind video temporal consistency,” in Proc. European Conference on Computer Vision (ECCV), 2018, pp. 179–195. doi arXiv
- S. W. Hasinoff, D. Sharlet, R. Geiss, A. Adams, J. T. Barron, F. Kainz, J. Chen and M. Levoy, “Burst photography for high dynamic range and low-light imaging on mobile cameras,” ACM Transactions on Graphics (Proc. SIGGRAPH Asia), vol. 35, no. 6, 2016. doi
- J. Chen, S. Paris and F. Durand, “Real-time edge-aware image processing with the bilateral grid,” ACM Transactions on Graphics (Proc. SIGGRAPH), vol. 26, no. 3, art. 103, 2007. doi
- C. Tomasi and R. Manduchi, “Bilateral filtering for gray and color images,” in Proc. IEEE International Conference on Computer Vision (ICCV), 1998, pp. 839–846. doi
- S. Paris and F. Durand, “A fast approximation of the bilateral filter using a signal processing approach,” International Journal of Computer Vision, vol. 81, no. 1, pp. 24–52, 2009. doi
- H. Wu, S. Zheng, J. Zhang and K. Huang, “Fast end-to-end trainable guided filter,” in Proc. IEEE/CVF CVPR, 2018, pp. 1838–1847. doi arXiv
- R. Wang, Q. Zhang, C.-W. Fu, X. Shen, W.-S. Zheng and J. Jia, “Underexposed photo enhancement using deep illumination estimation,” in Proc. IEEE/CVF CVPR, 2019, pp. 6842–6850. doi CVF
- Y. Lin, Z. Fu, K. Wen, T. Ye, S. Chen, G. Meng, Y. Wang, et al., “DPLUT: Unsupervised low-light image enhancement with lookup tables and diffusion priors,” in Proc. AAAI Conference on Artificial Intelligence, vol. 39, no. 5, pp. 5316–5324, 2025. doi arXiv
- K. Dabov, A. Foi, V. Katkovnik and K. Egiazarian, “Image denoising by sparse 3-D transform-domain collaborative filtering,” IEEE Transactions on Image Processing, 2007. doi
- K. Simonyan and A. Zisserman, “Very deep convolutional networks for large-scale image recognition,” ICLR, 2015. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A large-scale hierarchical image database,” CVPR, 2009. doi
- A. Brateanu, T. Mu, C. O. Ancuti and C. Ancuti, “Multinex: Lightweight Low-light Image Enhancement via Multi-prior Retinex,” in Proc. IEEE/CVF CVPR, 2026. paper supplement