IFCNN:支援可變輸入數的監督式融合
選讀・DLCV 10・影像融合:互補來源與有用輸出 的論文導讀(第 7/11 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
Zhang 等人的 Information Fusion 2020 論文用合成多焦點資料訓練小型網路,再測多種融合情境 [29]。特色是轉移第一層卷積、無參數特徵合併,以及重建加感知損失。
挑戰
若串接兩張特徵後接固定寬度卷積,輸入數就固定。IFCNN 希望不改參數形狀即可合併多來源,也需要在多數真實多模態配對沒有真值時取得訓練目標。
解法分兩部分:以逐元素操作接受可變輸入數,再用清晰 RGB 與深度圖產生監督式多焦點配對。其他融合任務的泛化則另行測試,不是由它們的融合真值直接監督。
方法
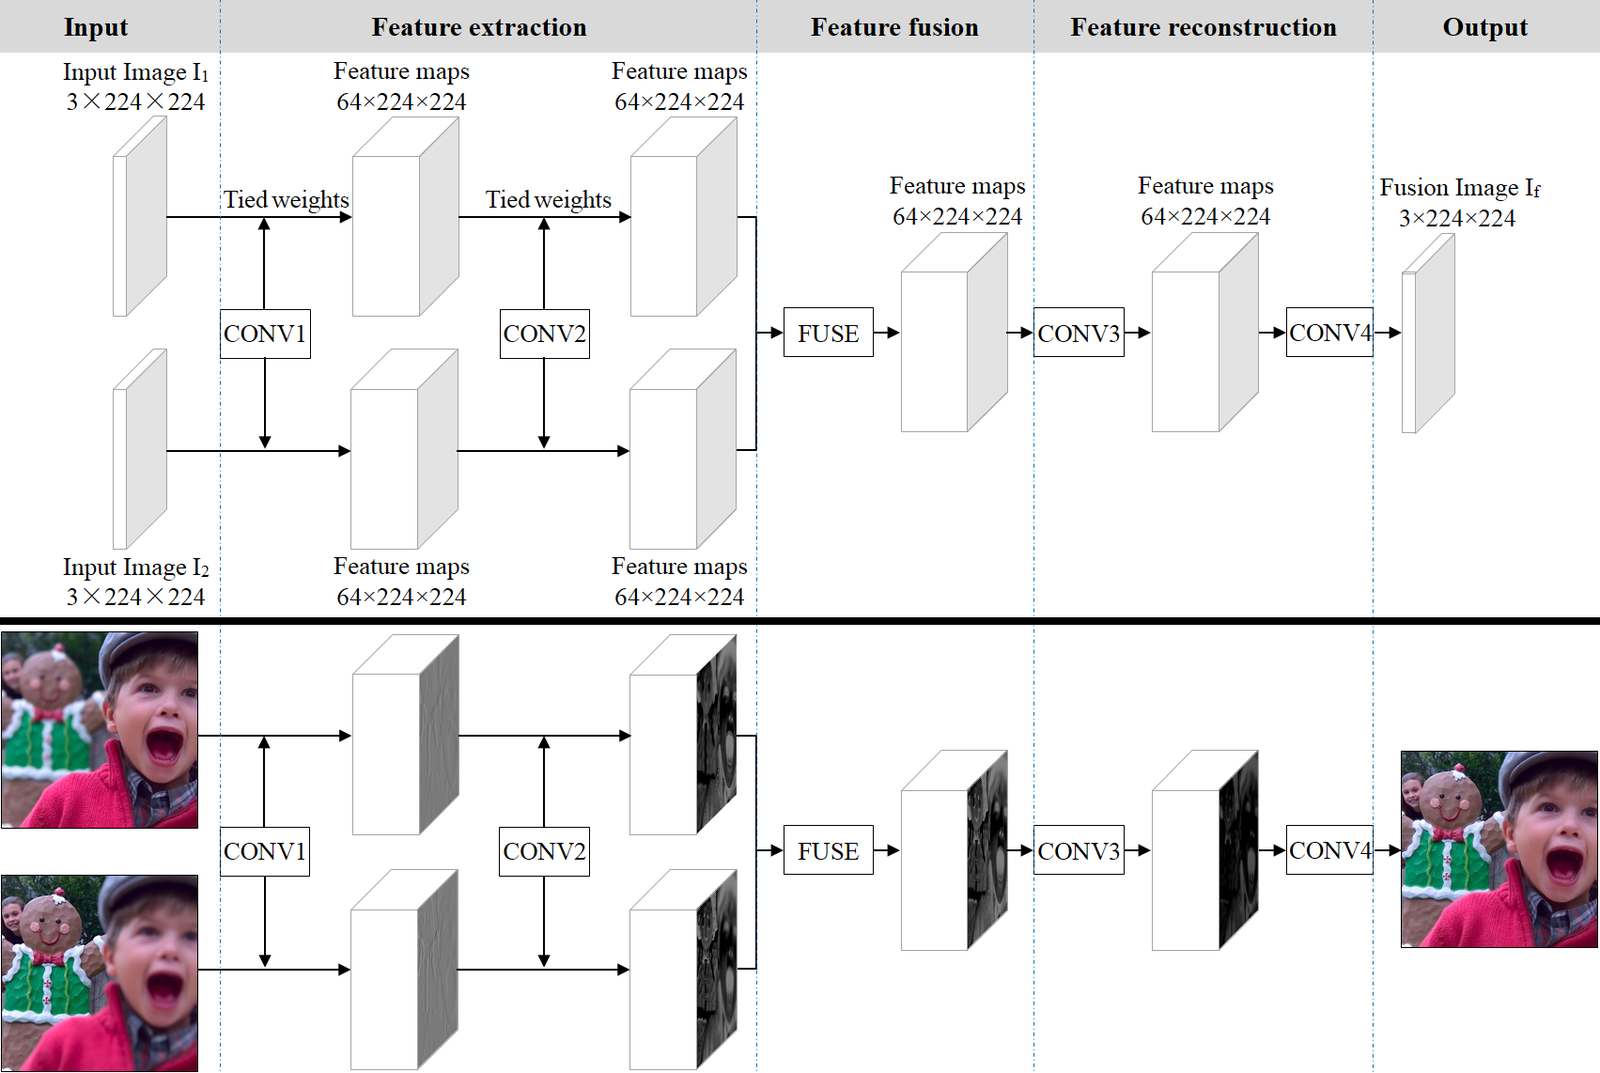
圖片來源:[29],官方實作圖,版本 ee21b644acca914bbb326daab115c458a67a773a. 原始來源.

轉移特徵。 各來源共用擷取器。CONV1 採 ImageNet 預訓練 ResNet101 第一層 [60]、[61],以 將三通道映為 64 通道,訓練時固定。步幅改一、填補改三,保留空間尺寸。
CONV2 為學習式 、64 通道卷積,加批次正規化與整流。它讓低層特徵適應融合,輸出 。所有來源共用參數,並非各輸入獨立編碼器。
特徵合併。 對同形狀的 ,論文比較逐元素最大、總和與平均:
是來源數,最大值在各位置、通道分別取。這些操作沒有學習式融合參數,改 仍維持形狀。最大值偏強響應,平均控制尺度但會混合,總和幅度隨數量改變;三者都不做對齊。
重建。 CONV3 是另一個 64 通道 調適層,含正規化與啟動。CONV4 用 映為三通道,步幅一、填補零;官方勘誤指出原文步幅零是誤植 [59]。所述架構最後沒有正規化或啟動。
灰階可複製成三通道走共用 RGB 路徑,色彩與後處理仍須符合評估設定。可接受多個張量,也不等於任意長來源序列都有相同品質。
合成監督。 由 NYU Depth V2 的 RGB/深度配對 [62],模糊清晰影像 ,對深度設閾值得到遮罩 ,建立互補來源:
是高斯模糊圖, 為逐元素乘。清晰原圖 就是真值。隨機深度閾值、裁切、翻轉增加變化,後續另調色並偶爾轉灰階。即使沒有人工畫融合真值,仍是監督學習。
損失與階段。 先用 RGB 均方誤差,再加入固定 ResNet101 最後卷積特徵的感知損失:
是輸出, 是清晰目標, 是固定感知擷取器, 是其通道與空間尺寸。等係數依原實驗 [29];改特徵正規化就會改相對強度。感知目標鼓勵特徵相似,不保證每個保真指標變好。
先以批次 64、像素損失訓練 5,000 次,再固定批次正規化參數,以批次 32、雙損失微調 60,000 次 [29]。第一轉移卷積維持固定。感知損失的深 ResNet 不在部署融合路徑中。
結果
研究評估多焦點、紅外線—可見光、醫學、多曝光 [29]。表 1 多焦點 IFCNN-MAX 為 VIFF 0.9823、ISSIM 0.6293、SF 19.42;表 2 紅外線—可見光為 VIFF 0.6405、SF 11.31。須沿用其指標慣例與尺度,不能等同單參考 SSIM 或任務準確度。
多曝光的偏好不同:表 4 IFCNN-MEAN 的 MESSIM 0.8786,MAX 為 0.8151,GFF 為 0.9204 [29]。沒有一種合併操作主宰所有任務。
表 5 在 Intel i7-3770K/NVIDIA TITAN X 上, 配對約 0.02 秒 [29]。競爭方法的尺寸與執行路徑不同,不能轉成通用速度排名。
消融實驗
BASELINE-MAX 只用像素訓練,IFCNN-MAX 加感知。表 1 的 VIFF 0.9809→0.9823、NMI 0.8664→0.9034、SF 19.33→19.42,但 ISSIM 0.6318→0.6293 [29],並非全數改善。
紅外線—可見光更明顯:表 2 基準 VIFF 0.6621/ISSIM 0.5002,IFCNN-MAX 0.6405/0.4956,但 SF 11.08→11.31 [29]。泛化與視覺宣稱須連同下降項一起讀。
MAX、SUM、MEAN 另測合併規則。多曝光的平均有較高結構分數,最大值有更高空間頻率,呼應「選細節」與「混曝光」的偏好不同。
結論
IFCNN 共用卷積特徵路徑,以參數形狀不依賴來源數的操作合併。合成監督使訓練可行,任務特定合併選擇則決定特徵如何組合。
限制與問題
合成模糊/遮罩無法涵蓋所有真實散焦邊界、感測響應與錯位;感知特徵源自自然影像分類,也有結構偏好。加入感知損失後部分指標下降,因此「感知」不代表普遍改善。
同一架構能接受不同模態,不表示一種合併器或一個基準即可驗證所有應用。應分別核對輸入慣例、來源數、配準與評估,重現時納入官方勘誤。
參考文獻
- Y. Liu, X. Chen, Z. Wang, Z. J. Wang, R. K. Ward and X. Wang, “Deep learning for pixel-level image fusion: Recent advances and future prospects,” Information Fusion, vol. 42, pp. 158–173, 2018. doi
- J. Liu, G. Wu, Z. Liu, D. Wang, Z. Jiang, L. Ma, W. Zhong, X. Fan and R. Liu, “Infrared and visible image fusion: From data compatibility to task adaption,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 47, no. 4, pp. 2349–2369, 2025. doi arXiv
- J. Ma, Y. Ma and C. Li, “Infrared and visible image fusion methods and applications: A survey,” Information Fusion, vol. 45, pp. 153–178, 2019. doi
- P. E. Debevec and J. Malik, “Recovering high dynamic range radiance maps from photographs,” in Proc. SIGGRAPH, 1997, pp. 369–378. doi
- T. Mertens, J. Kautz and F. Van Reeth, “Exposure fusion: A simple and practical alternative to high dynamic range photography,” Computer Graphics Forum, vol. 28, no. 1, pp. 161–171, 2009. doi
- S. Xu, X. Wei, C. Zhang, J. Liu and J. Zhang, “MFFW: A new dataset for multi-focus image fusion,” arXiv:2002.04780, 2020. arXiv
- X. Zhang, “Multi-focus image fusion: A benchmark,” arXiv:2005.01116, 2020. arXiv
- P. J. Burt and E. H. Adelson, “The Laplacian pyramid as a compact image code,” IEEE Transactions on Communications, vol. 31, no. 4, pp. 532–540, 1983. doi
- P. J. Burt and R. J. Kolczynski, “Enhanced image capture through fusion,” in Proc. 4th International Conference on Computer Vision (ICCV), 1993, pp. 173–182. doi
- P. J. Burt and E. H. Adelson, “A multiresolution spline with application to image mosaics,” ACM Transactions on Graphics, vol. 2, no. 4, pp. 217–236, 1983. doi
- H. Li, B. S. Manjunath and S. K. Mitra, “Multisensor image fusion using the wavelet transform,” Graphical Models and Image Processing, vol. 57, no. 3, pp. 235–245, 1995. doi
- S. Li, X. Kang and J. Hu, “Image fusion with guided filtering,” IEEE Transactions on Image Processing, vol. 22, no. 7, pp. 2864–2875, 2013. doi
- K. He, J. Sun and X. Tang, “Guided image filtering,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 35, no. 6, pp. 1397–1409, 2013. doi
- B. Yang and S. Li, “Multifocus image fusion and restoration with sparse representation,” IEEE Transactions on Instrumentation and Measurement, vol. 59, no. 4, pp. 884–892, 2010. doi
- M. Nejati, S. Samavi and S. Shirani, “Multi-focus image fusion using dictionary-based sparse representation,” Information Fusion, vol. 25, pp. 72–84, 2015. doi
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image quality assessment: From error visibility to structural similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- X. Zhang, P. Ye and G. Xiao, “VIFB: A visible and infrared image fusion benchmark,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops, 2020. CVF arXiv
- X. Zhang, “Benchmarking and comparing multi-exposure image fusion algorithms,” Information Fusion, vol. 74, pp. 111–131, 2021. doi arXiv
- A. M. Eskicioglu and P. S. Fisher, “Image quality measures and their performance,” IEEE Transactions on Communications, vol. 43, no. 12, pp. 2959–2965, 1995. doi
- G. Qu, D. Zhang and P. Yan, “Information measure for performance of image fusion,” Electronics Letters, vol. 38, no. 7, pp. 313–315, 2002. doi
- M. Hossny, S. Nahavandi and D. Creighton, “Comments on ‘Information measure for performance of image fusion’,” Electronics Letters, vol. 44, no. 18, pp. 1066–1067, 2008. doi
- C. S. Xydeas and V. Petrović, “Objective image fusion performance measure,” Electronics Letters, vol. 36, no. 4, pp. 308–309, 2000. doi
- G. Piella and H. Heijmans, “A new quality metric for image fusion,” in Proc. IEEE International Conference on Image Processing (ICIP), 2003, vol. 3, pp. III-173–176. doi
- Y. Han, Y. Cai, Y. Cao and X. Xu, “A new image fusion performance metric based on visual information fidelity,” Information Fusion, vol. 14, no. 2, pp. 127–135, 2013. doi
- K. Ma, K. Zeng and Z. Wang, “Perceptual quality assessment for multi-exposure image fusion,” IEEE Transactions on Image Processing, vol. 24, no. 11, pp. 3345–3356, 2015. doi
- Z. Liu, E. Blasch, Z. Xue, J. Zhao, R. Laganiere and W. Wu, “Objective assessment of multiresolution image fusion algorithms for context enhancement in night vision: A comparative study,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 34, no. 1, pp. 94–109, 2012. doi
- J. Liu, X. Fan, Z. Huang, G. Wu, R. Liu, W. Zhong and Z. Luo, “Target-aware dual adversarial learning and a multi-scenario multi-modality benchmark to fuse infrared and visible for object detection,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2022, pp. 5802–5811. CVF arXiv M3FD
- J. Liu, Z. Liu, G. Wu, L. Ma, R. Liu, W. Zhong, Z. Luo and X. Fan, “Multi-interactive feature learning and a full-time multi-modality benchmark for image fusion and segmentation,” in Proc. IEEE/CVF International Conference on Computer Vision (ICCV), 2023, pp. 8115–8124. CVF arXiv
- Y. Zhang, Y. Liu, P. Sun, H. Yan, X. Zhao and L. Zhang, “IFCNN: A general image fusion framework based on convolutional neural network,” Information Fusion, vol. 54, pp. 99–118, 2020. doi
- H. Li and X.-J. Wu, “DenseFuse: A fusion approach to infrared and visible images,” IEEE Transactions on Image Processing, vol. 28, no. 5, pp. 2614–2623, 2019. doi arXiv
- K. R. Prabhakar, V. S. Srikar and R. V. Babu, “DeepFuse: A deep unsupervised approach for exposure fusion with extreme exposure image pairs,” in Proc. IEEE International Conference on Computer Vision (ICCV), 2017, pp. 4724–4732. doi CVF
- H. Xu, J. Ma, J. Jiang, X. Guo and H. Ling, “U2Fusion: A unified unsupervised image fusion network,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 1, pp. 502–518, 2022. doi RoadScene
- L. Tang, J. Yuan and J. Ma, “Image fusion in the loop of high-level vision tasks: A semantic-aware real-time infrared and visible image fusion network,” Information Fusion, vol. 82, pp. 28–42, 2022. doi
- J. Ma, L. Tang, F. Fan, J. Huang, X. Mei and Y. Ma, “SwinFusion: Cross-domain long-range learning for general image fusion via Swin Transformer,” IEEE/CAA Journal of Automatica Sinica, vol. 9, no. 7, pp. 1200–1217, 2022. doi
- X. Zhang and Y. Demiris, “Visible and infrared image fusion using deep learning,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 45, no. 8, pp. 10535–10554, 2023. doi
- Y. Liu, X. Chen, H. Peng and Z. Wang, “Multi-focus image fusion with a deep convolutional neural network,” Information Fusion, vol. 36, pp. 191–207, 2017. doi
- K. Ma, Z. Duanmu, H. Zhu, Y. Fang and Z. Wang, “Deep guided learning for fast multi-exposure image fusion,” IEEE Transactions on Image Processing, vol. 29, pp. 2808–2819, 2020. doi
- Z. Zhao, H. Bai, J. Zhang, Y. Zhang, S. Xu, Z. Lin, R. Timofte and L. Van Gool, “CDDFuse: Correlation-driven dual-branch feature decomposition for multi-modality image fusion,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2023, pp. 5906–5916. CVF arXiv
- J. Ma, W. Yu, P. Liang, C. Li and J. Jiang, “FusionGAN: A generative adversarial network for infrared and visible image fusion,” Information Fusion, vol. 48, pp. 11–26, 2019. doi · public article transcription
- H. Bai, J. Zhang, Z. Zhao, Y. Wu, L. Deng, Y. Cui, T. Feng and S. Xu, “Task-driven image fusion with learnable fusion loss,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025, pp. 7457–7468. CVF arXiv
- Z. Zhao, H. Bai, Y. Zhu, J. Zhang, S. Xu, Y. Zhang, K. Zhang, D. Meng, R. Timofte and L. Van Gool, “DDFM: Denoising diffusion model for multi-modality image fusion,” in Proc. IEEE/CVF International Conference on Computer Vision (ICCV), 2023, pp. 8082–8093. CVF arXiv
- X. Yi, H. Xu, H. Zhang, L. Tang and J. Ma, “Text-IF: Leveraging semantic text guidance for degradation-aware and interactive image fusion,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024, pp. 27026–27035. CVF arXiv
- D. Wang, J. Liu, X. Fan and R. Liu, “Unsupervised misaligned infrared and visible image fusion via cross-modality image generation and registration,” in Proc. International Joint Conference on Artificial Intelligence (IJCAI), 2022, pp. 3508–3515. doi arXiv
- L. Tang, Y. Deng, Y. Ma, J. Huang and J. Ma, “SuperFusion: A versatile image registration and fusion network with semantic awareness,” IEEE/CAA Journal of Automatica Sinica, vol. 9, no. 12, pp. 2121–2137, 2022. doi
- A. Toet, “The TNO multiband image data collection,” Data in Brief, vol. 15, pp. 249–251, 2017. doi
- L. Tang, J. Yuan, H. Zhang, X. Jiang and J. Ma, “PIAFusion: A progressive infrared and visible image fusion network based on illumination aware,” Information Fusion, vol. 83–84, pp. 79–92, 2022. doi MSRS
- Q. Ha, K. Watanabe, T. Karasawa, Y. Ushiku and T. Harada, “MFNet: Towards real-time semantic segmentation for autonomous vehicles with multi-spectral scenes,” in Proc. IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), 2017, pp. 5108–5115. doi
- X. Jia, C. Zhu, M. Li, W. Tang and W. Zhou, “LLVIP: A visible-infrared paired dataset for low-light vision,” in Proc. IEEE/CVF International Conference on Computer Vision (ICCV) Workshops, 2021, pp. 3496–3504. CVF arXiv
- J. Cai, S. Gu and L. Zhang, “Learning a deep single image contrast enhancer from multi-exposure images,” IEEE Transactions on Image Processing, vol. 27, no. 4, pp. 2049–2062, 2018. doi
- X. Zhang, “Deep learning-based multi-focus image fusion: A survey and a comparative study,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 44, no. 9, 2022. doi
- F. Xu, J. Liu, Y. Song, H. Sun and X. Wang, “Multi-exposure image fusion techniques: A comprehensive review,” Remote Sensing, vol. 14, no. 3, art. 771, 2022. doi
- Z. Zhao, H. Bai, J. Zhang, Y. Zhang, K. Zhang, S. Xu, D. Chen, R. Timofte and L. Van Gool, “Equivariant multi-modality image fusion,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024, pp. 25912–25921. CVF arXiv
- L. Tang, Y. Wang, M. Gong, Z. Li, Y. Deng, X. Yi, C. Li, H. Xu, H. Zhang and J. Ma, “VideoFusion: A spatio-temporal collaborative network for multi-modal video fusion,” in Proc. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026, pp. 19559–19569. CVF
- N. Yokoya, C. Grohnfeldt and J. Chanussot, “Hyperspectral and multispectral data fusion: A comparative review of the recent literature,” IEEE Geoscience and Remote Sensing Magazine, 2017. doi
- H. R. Sheikh and A. C. Bovik, “Image information and visual quality,” IEEE Transactions on Image Processing, 2006. doi
- H. Xu et al., “U2Fusion,” official implementation accompanying the TPAMI paper, 2022. code
- K. Simonyan and A. Zisserman, “Very deep convolutional networks for large-scale image recognition,” ICLR, 2015. arXiv
- J. Kirkpatrick et al., “Overcoming catastrophic forgetting in neural networks,” Proceedings of the National Academy of Sciences, 2017. doi
- Y. Zhang et al., “IFCNN,” official implementation and errata accompanying the Information Fusion paper, 2020. code
- K. He, X. Zhang, S. Ren and J. Sun, “Deep residual learning for image recognition,” CVPR, 2016. CVF
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A large-scale hierarchical image database,” CVPR, 2009. doi
- N. Silberman, D. Hoiem, P. Kohli and R. Fergus, “Indoor segmentation and support inference from RGBD images,” ECCV, 2012. project
- P. Dhariwal and A. Nichol, “Diffusion models beat GANs on image synthesis,” NeurIPS, 2021. arXiv
- J. Liu et al., “TarDAL,” official implementation accompanying the CVPR paper, 2022. code
- G. Jocher et al., “YOLOv5,” Ultralytics object-detection software, 2020 onward. code
- J. Ma et al., “FusionGAN,” official implementation accompanying the Information Fusion paper, 2019. code
- L. Tang, J. Yuan and J. Ma, “SeAFusion,” official implementation accompanying the Information Fusion paper, 2022. code
- T. Mertens, J. Kautz and F. Van Reeth, “Exposure Fusion,” in Proc. Pacific Graphics, 2007. paper · author project