Ge 等人:On the Content Bias in Fréchet Video Distance(CVPR 2024)
選讀・DLCV 12A・影片生成 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
FVD 是影片生成最常用的分布指標,但已有數篇論文報告它與人類判斷相矛盾的案例,並一再懷疑它重視個別影格的品質,勝過動作的真實感 [42]。
圖片來源: [42], Published paper PDF, PDF 第 2 頁. 原始 PDF.
方法
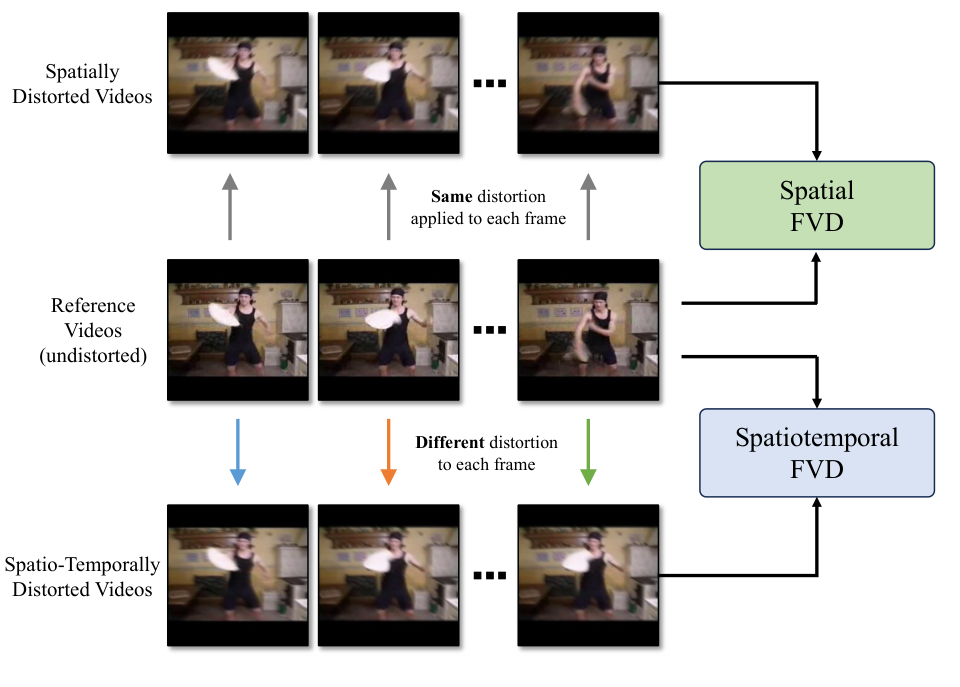
在受控的情境中測量這個偏差。從真實影片出發,製作兩組逐影格品質相同的失真影片:一組對每個影格施加相同的失真(只有空間性),另一組對每個影格施加不同的失真(時空性,增加了時間上的不一致)。以對擷取出的影格計算 FID 來確認影格品質相同;FVD 的時間敏感度就是它的變化量與 FID 變化量的比值。第二,探查這個指標的「感知零空間」:從許多沒有動作的生成影片中,挑出使 FVD 最小的子集。第三,把 I3D 特徵換成自監督影片模型的特徵(VideoMAE v2 [43]),再重複一次。
結果
使用 I3D 特徵時,FVD 在大幅度的時間破壞下只上升一點點,而選取靜態的生成影片可以在不改善時間品質的情況下,大幅降低 FVD,兩者都是偏向逐影格內容的跡象。作者把偏差歸因於在 Kinetics 上訓練的監督式動作分類器的特徵,而 Kinetics 這個資料集中許多動作僅憑外觀就能辨認。以自監督的 VideoMAE v2 特徵計算的 FVD,在所有實驗中對時間品質敏感得多。
判讀證據
先看圖 1(促成研究的例子)和實驗設計圖,再看敏感度圖,依失真類型與資料集比較 I3D 與 VideoMAE v2 的各種變體。要檢查:(a) 結論談的是相對敏感度,而不是絕對的 FVD 值,後者在不同特徵萃取器之間無法比較;(b) 每條曲線用的是哪一種 VideoMAE v2 變體(只做預訓練,還是在動作資料集上微調過);(c) 結尾處的真實案例,在那裡分析被應用到已發表的模型上。
限制與問題
作者指出,FVD 仍需要縮放到低解析度的正方形,長影片仍然難以評估,因為 transformer 特徵的成本是二次方的,而且他們的研究涵蓋的是一組失真與資料集,並非生成影片的每一種失敗。
結論
它說明了為什麼本篇堅持在 FVD 旁邊要搭配時間與動作的衡量,以及為什麼每個 FVD 數字都必須報告所用的特徵萃取器。
參考文獻
- U. Singer, A. Polyak, T. Hayes et al., “Make-A-Video: Text-to-Video Generation without Text-Video Data,” arXiv:2209.14792, 2022. arXiv
- Z. Yang, J. Teng, W. Zheng et al., “CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer,” ICLR, 2025. arXiv
- Team Wan, A. Wang, B. Ai, B. Wen et al., “Wan: Open and Advanced Large-Scale Video Generative Models,” arXiv:2503.20314, 2025. arXiv
- A. Blattmann, T. Dockhorn, S. Kulal et al., “Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets,” arXiv:2311.15127, 2023. arXiv
- J. Xing, M. Xia, Y. Zhang et al., “DynamiCrafter: Animating Open-Domain Images with Video Diffusion Priors,” ECCV, LNCS, pp. 399–417, 2024. doi · arXiv
- J. Ho, T. Salimans, A. Gritsenko, W. Chan, M. Norouzi and D. J. Fleet, “Video Diffusion Models,” NeurIPS, 2022. proceedings · arXiv
- A. Blattmann, R. Rombach, H. Ling et al., “Align your Latents: High-Resolution Video Synthesis with Latent Diffusion Models,” CVPR, 2023. CVF
- R. Henschel, L. Khachatryan, H. Poghosyan et al., “StreamingT2V: Consistent, Dynamic, and Extendable Long Video Generation from Text,” CVPR, 2025. CVF
- J. Z. Wu, Y. Ge, X. Wang et al., “Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation,” ICCV, 2023. CVF
- L. Khachatryan, A. Movsisyan, V. Tadevosyan et al., “Text2Video-Zero: Text-to-Image Diffusion Models are Zero-Shot Video Generators,” ICCV, 2023. CVF
- Z. Wang, Z. Yuan, X. Wang et al., “MotionCtrl: A Unified and Flexible Motion Controller for Video Generation,” SIGGRAPH 2024 Conference Papers, 2024. doi · arXiv
- H. He, Y. Xu, Y. Guo et al., “CameraCtrl: Enabling Camera Control for Text-to-Video Generation,” ICLR, 2025. arXiv
- S. Yin, C. Wu, J. Liang et al., “DragNUWA: Fine-grained Control in Video Generation by Integrating Text, Image, and Trajectory,” arXiv:2308.08089, 2023. arXiv
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. CVF
- L. Yu, J. Lezama, N. B. Gundavarapu et al., “Language Model Beats Diffusion — Tokenizer is Key to Visual Generation,” ICLR, 2024. arXiv
- W. Kong, Q. Tian, Z. Zhang et al., “HunyuanVideo: A Systematic Framework For Large Video Generative Models,” arXiv:2412.03603, 2024. arXiv
- A. Polyak, A. Zohar, A. Brown et al., “Movie Gen: A Cast of Media Foundation Models,” arXiv:2410.13720, 2024. arXiv
- Y. HaCohen, N. Chiprut, B. Brazowski et al., “LTX-Video: Realtime Video Latent Diffusion,” arXiv:2501.00103, 2024. arXiv
- D. Kondratyuk, L. Yu, X. Gu et al., “VideoPoet: A Large Language Model for Zero-Shot Video Generation,” ICML, PMLR 235, 2024. PMLR · arXiv
- L. Yu, Y. Cheng, K. Sohn et al., “MAGVIT: Masked Generative Video Transformer,” CVPR, 2023. CVF
- Y. Guo, C. Yang, A. Rao et al., “AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning,” ICLR, 2024. arXiv
- Z. Zheng, X. Peng, T. Yang et al., “Open-Sora: Democratizing Efficient Video Production for All,” arXiv:2412.20404, 2024. arXiv
- G. Bertasius, H. Wang and L. Torresani, “Is Space-Time Attention All You Need for Video Understanding?,” ICML, PMLR 139, 2021. PMLR
- A. Arnab, M. Dehghani, G. Heigold, C. Sun, M. Lučić and C. Schmid, “ViViT: A Video Vision Transformer,” ICCV, 2021. CVF
- X. Ma, Y. Wang, X. Chen et al., “Latte: Latent Diffusion Transformer for Video Generation,” Transactions on Machine Learning Research, 2025. arXiv
- B. Lin, Y. Ge, X. Cheng et al., “Open-Sora Plan: Open-Source Large Video Generation Model,” arXiv:2412.00131, 2024. arXiv
- J. Ho, W. Chan, C. Saharia et al., “Imagen Video: High Definition Video Generation with Diffusion Models,” arXiv:2210.02303, 2022. arXiv
- O. Bar-Tal, H. Chefer, O. Tov et al., “Lumiere: A Space-Time Diffusion Model for Video Generation,” SIGGRAPH Asia 2024 Conference Papers, 2024. doi · arXiv
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” arXiv:2210.02747, 2022. arXiv
- W. Peebles and S. Xie, “Scalable Diffusion Models with Transformers,” ICCV, 2023. CVF
- S. Yin, C. Wu, H. Yang et al., “NUWA-XL: Diffusion over Diffusion for eXtremely Long Video Generation,” ACL, pp. 1309–1320, 2023. doi · arXiv
- H. Qiu, M. Xia, Y. Zhang et al., “FreeNoise: Tuning-Free Longer Video Diffusion via Noise Rescheduling,” ICLR, 2024. arXiv
- R. Villegas, M. Babaeizadeh, P.-J. Kindermans et al., “Phenaki: Variable Length Video Generation From Open Domain Textual Description,” arXiv:2210.02399, 2022. arXiv
- Z. Huang, Y. He, J. Yu et al., “VBench: Comprehensive Benchmark Suite for Video Generative Models,” CVPR, 2024. CVF
- T. Yin, Q. Zhang, R. Zhang et al., “From Slow Bidirectional to Fast Autoregressive Video Diffusion Models,” CVPR, 2025. CVF
- B. Chen, D. M. Monso, Y. Du, M. Simchowitz, R. Tedrake and V. Sitzmann, “Diffusion Forcing: Next-token Prediction Meets Full-Sequence Diffusion,” NeurIPS, 2024. proceedings · arXiv
- X. Huang, Z. Li, G. He, M. Zhou and E. Shechtman, “Self Forcing: Bridging the Train-Test Gap in Autoregressive Video Diffusion,” NeurIPS, 2025. arXiv
- T. Unterthiner, S. van Steenkiste, K. Kurach, R. Marinier, M. Michalski and S. Gelly, “Towards Accurate Generative Models of Video: A New Metric & Challenges,” arXiv:1812.01717, 2018. arXiv
- J. Carreira and A. Zisserman, “Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset,” CVPR, 2017. CVF
- W. Kay, J. Carreira, K. Simonyan et al., “The Kinetics Human Action Video Dataset,” arXiv:1705.06950, 2017. arXiv
- K. Soomro, A. R. Zamir and M. Shah, “UCF101: A Dataset of 101 Human Actions Classes From Videos in The Wild,” technical report CRCV-TR-12-01, arXiv:1212.0402, 2012. arXiv
- S. Ge, A. Mahapatra, G. Parmar, J.-Y. Zhu and J.-B. Huang, “On the Content Bias in Fréchet Video Distance,” CVPR, 2024. CVF
- L. Wang, B. Huang, Z. Zhao et al., “VideoMAE V2: Scaling Video Masked Autoencoders With Dual Masking,” CVPR, 2023. CVF
- Z. Huang, F. Zhang, X. Xu et al., “VBench++: Comprehensive and Versatile Benchmark Suite for Video Generative Models,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 48, no. 3, pp. 3268–3285, 2026. doi · arXiv
- Y. Liu, X. Cun, X. Liu et al., “EvalCrafter: Benchmarking and Evaluating Large Video Generation Models,” CVPR, 2024. CVF
- Z. Zheng, X. Peng, Y. Lou et al., “Open-Sora 2.0: Training a Commercial-Level Video Generation Model in $200k,” arXiv:2503.09642, 2025. arXiv
- M. Bain, A. Nagrani, G. Varol and A. Zisserman, “Frozen in Time: A Joint Video and Image Encoder for End-to-End Retrieval,” ICCV, 2021. CVF · arXiv
- T.-S. Chen, A. Siarohin, W. Menapace et al., “Panda-70M: Captioning 70M Videos with Multiple Cross-Modality Teachers,” CVPR, 2024. CVF
- A. Rössler, D. Cozzolino, L. Verdoliva, C. Riess, J. Thies and M. Nießner, “FaceForensics++: Learning to Detect Manipulated Facial Images,” ICCV, 2019. doi · arXiv
- P. Fernandez, H. Elsahar, I. Z. Yalniz and A. Mourachko, “Video Seal: Open and Efficient Video Watermarking,” arXiv:2412.09492, 2024. arXiv
- A. Melnik, M. Ljubljanac, C. Lu, Q. Yan, W. Ren and H. Ritter, “Video Diffusion Models: A Survey,” Transactions on Machine Learning Research, 2024. arXiv
- Z. Xing, Q. Feng, H. Chen et al., “A Survey on Video Diffusion Models,” arXiv:2310.10647, 2023. arXiv
- Y. Liu, K. Zhang, Y. Li et al., “Sora: A Review on Background, Technology, Limitations, and Opportunities of Large Vision Models,” arXiv:2402.17177, 2024. arXiv
- OpenAI, “What to know about the Sora discontinuation,” official service notice, 2026, accessed 5 November 2026. Notice.