YOLOX:無錨框 YOLO 與 SimOTA
選讀・DLCV 03A・以 YOLOv4 讀懂單階段偵測 的論文導讀(第 9/22 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
本頁內容
- YOLO v1:把偵測當成一次迴歸
- YOLOv2 與 YOLO9000:錨框、先驗與聯合訓練
- YOLOv3:三尺度與 Darknet-53
- SSD:多尺度預設框
- RetinaNet 與 focal loss
- FCOS:逐像素無錨框偵測
- CenterNet:把物件視為點
- YOLOR:顯式特徵與可學隱式表示
- YOLOX:無錨框 YOLO 與 SimOTA
- YOLOv6:重參數化工業偵測器
- YOLOv7:可訓練的免費技巧
- YOLOv9:可編程梯度資訊
- YOLOv10:雙指派的免 NMS 訓練
- YOLOv12:以注意力為核心的 YOLO
- YOLOv13:超圖關聯
- YOLO26:移除 DFL 的端到端 YOLO
- RT-DETR:即時 DETR
- RT-DETRv2:RT-DETR 的實用配方
- D-FINE:逐層精修框分布
- DEIM:密集一對一匹配
- RF-DETR:在 DINOv2 骨幹上搜尋架構
- DEIMv2:為即時 DETR 調適 DINOv3
電腦視覺深度學習
論文: Z. Ge等,“YOLOX: Exceeding YOLO series in 2021,” arXiv2021 [15]。對應: 頭、指派。
挑戰
2021已有無錨框、預測指派、端到端進展,v4/v5 [3]仍錨框。YOLOX刻意由v3-SPP開始,認為v4/v5對錨框流程已過度調校 [15]。
方法
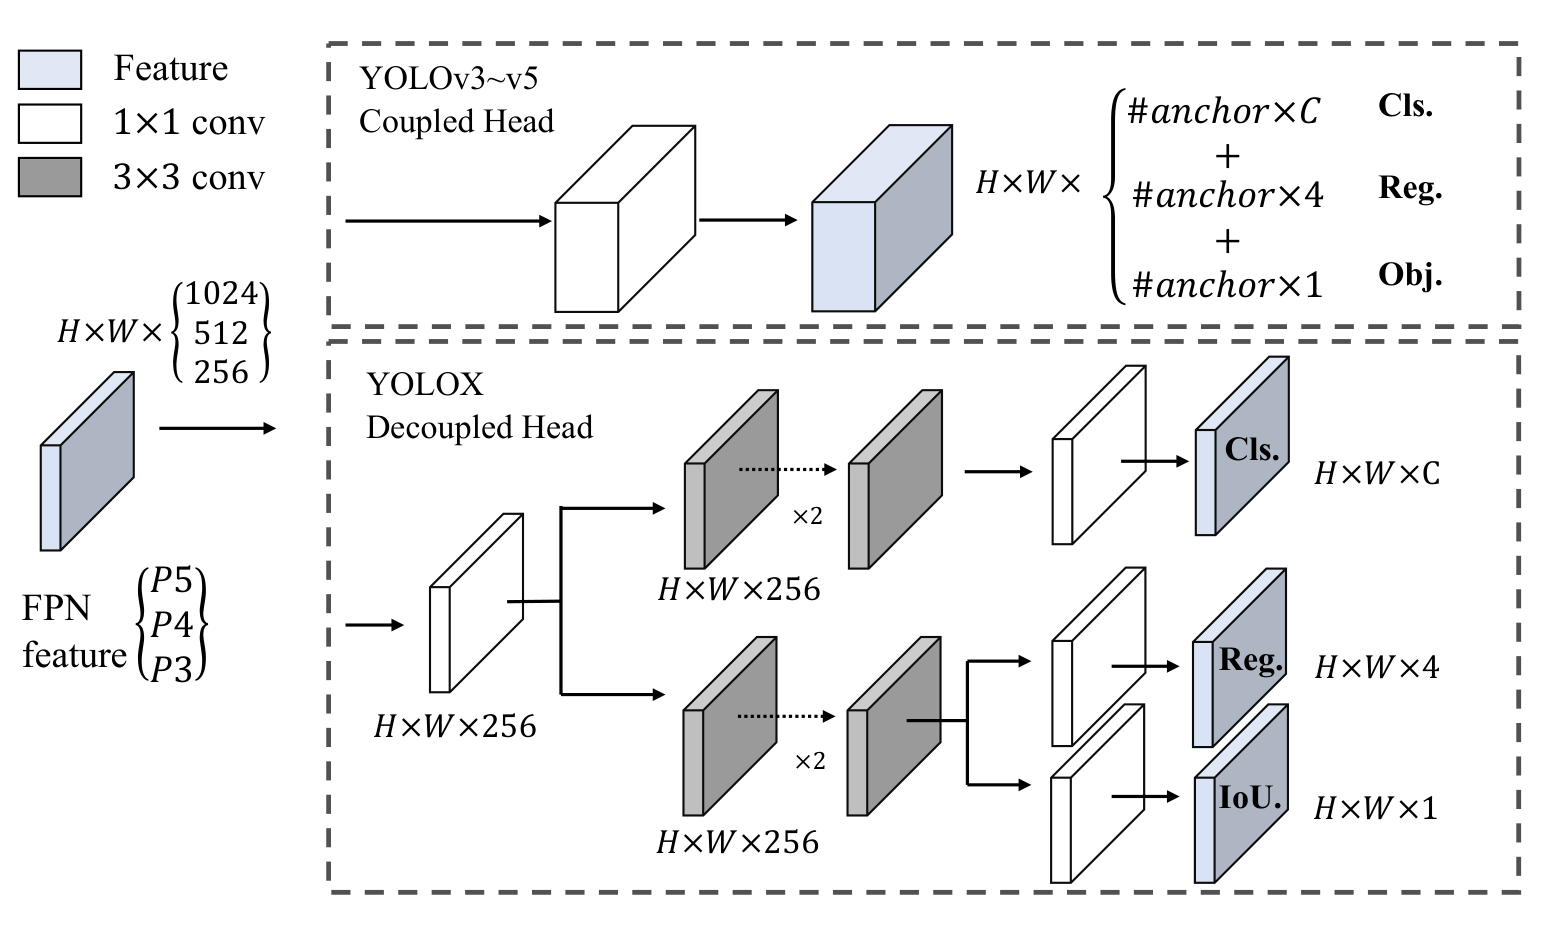
圖片來源:[15],arXiv:2107.08430v2,PDF 第 3 頁。原始 PDF。
強基準。 Darknet53-SPP、EMA、餘弦、IoU/品質支路、類別物件度BCE;300 epochs、暖5、SGD0.9、學習率、batch128、448–832;此階段僅翻轉、色彩、多尺度 [15]。
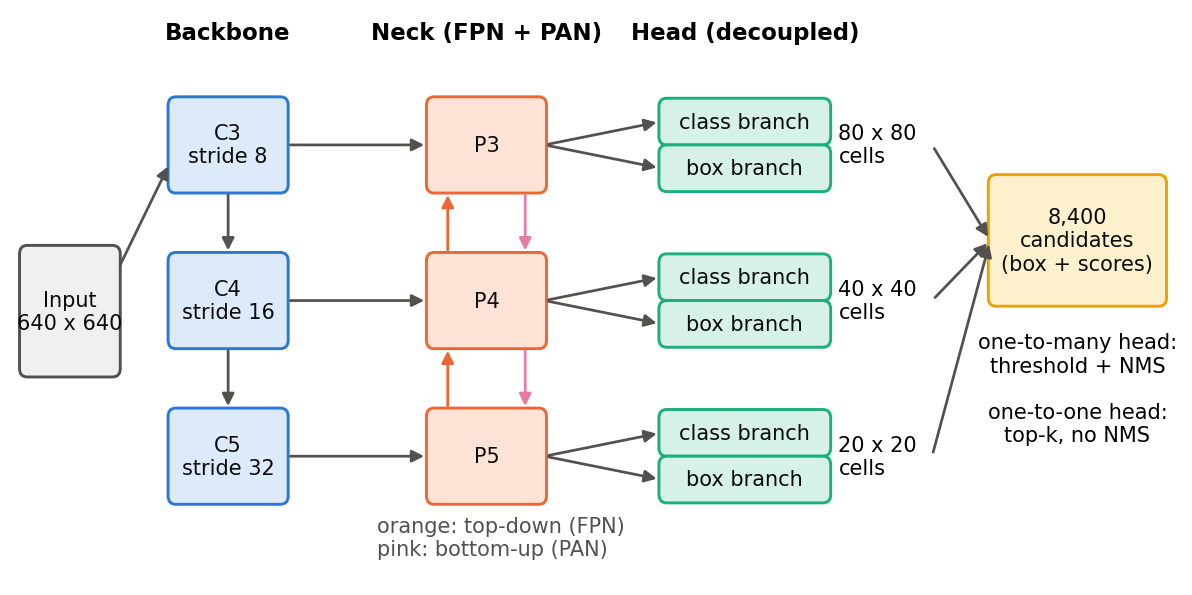
解耦頭。 每FPN層1×1降256,再分類、迴歸各兩個3×3,品質分支在迴歸側,降低兩任務特徵衝突 [15]。
強增強。 Mosaic、MixUp [46] 最後15 epochs關閉。此時ImageNet預訓練不再有益,後續從零訓 [15]。
無錨框。 每格由三降一,預測中心偏移與對數寬高;原初中心正樣本、尺度範圍類FCOS [15]。公開解碼 ;是格座標、步幅,為原始輸出,中心沒有sigmoid [74]。物件度與類別另算,範例乘兩分數過濾。
程式碼 · Python · 32 行
import numpy as np

def make_grid(img_size=640, strides=(8, 16, 32)):
    grids, all_strides = [], []
    for stride in strides:
        size = img_size // stride
        gy, gx = np.mgrid[:size, :size]
        grids.append(np.stack([gx.ravel(), gy.ravel()], axis=1))
        all_strides.append(np.full(size*size, stride))
    return np.concatenate(grids), np.concatenate(all_strides)

def decode(raw, grid, stride, threshold=0.25):
    # raw: center offsets, log(width/stride), log(height/stride), objectness and class logits.
    center = (raw[:, :2] + grid) * stride[:, None]
    size = np.exp(raw[:, 2:4]) * stride[:, None]
    boxes = np.concatenate([center-size/2, center+size/2], axis=1)
    probability = 1/(1+np.exp(-raw[:, 4:]))
    scores = probability[:, :1] * probability[:, 1:]
    classes, best = scores.argmax(1), scores.max(1)
    keep = best > threshold
    return boxes[keep], classes[keep], best[keep]

grid, stride = make_grid()
raw = np.zeros((len(grid), 5+3))
raw[:, 4:] = -6  # background objectness and class logits
index = np.flatnonzero((stride==16) & (grid[:, 0]==18) & (grid[:, 1]==12))[0]
raw[index, :4] = [0., 0.25, np.log(9.), np.log(5.5)]
raw[index, 4] = 4.  # objectness
raw[index, 5+1] = 4.  # class 1
boxes, classes, scores = decode(raw, grid, stride)
print("predictions per 640x640 image:", len(grid))
print("kept:", len(boxes), "| box:", boxes[0], "| class:", classes[0], "| score:", round(float(scores[0]), 3))
輸出
predictions per 640x640 image: 8400
kept: 1 | box: [216. 152. 360. 240.] | class: 1 | score: 0.964格、步幅16,此例解碼中心、寬144、高88。只是解碼示範,非訓練模型或基準;v4相同尺度會有三倍候選。
多正樣本。 單中心浪費鄰近好預測,改中心3×3為正,類似FCOS中心取樣 [15]。
SimOTA。 OTA [76] 用最優傳輸、Sinkhorn–Knopp,增約25%訓練時間。SimOTA保留損失感知、中心先驗、動態正數與全域觀點,以近似配對成本
為真值與預測的分類、框損失,平衡;中心區域內挑最低成本個,依物件動態估 [15]。
選配端到端。 加兩卷積、一對一與stop-gradient可免NMS,但較慢較不準,未納最終模型 [15]。
結果
V100、FP16、batch1,路線表不含後處理:test-dev YOLOX-L 50.0AP/69.0FPS,DarkNet53 47.4/90.1;v4-CSP 47.5/73、v5-L 48.2/73。Nano 0.91M、1.08GFLOPs、val25.3AP。單YOLOX-L贏CVPR2021自駕工作坊串流感知挑戰 [15]。
消融實驗
表2,DarkNet53、COCO val、640 [15]:
| 步驟 | AP | V100 FP16 batch1,無後處理 |
|---|---|---|
| YOLOv3基準 | 38.5 | 10.5ms |
| 解耦頭 | 39.6 | 11.6ms |
| 強增強 | 42.0 | 11.6ms |
| 無錨框 | 42.9 | 11.1ms |
| 多正樣本 | 45.0 | 11.1ms |
| SimOTA | 47.3 | 11.1ms |
| 選配免NMS | 46.5 | 13.5ms |
表1耦合頭改端到端 38.5→34.3AP,解耦 39.6→38.8,也較快收斂。表5弱化小模型增強,Nano 24.0→25.3;L用尺度MixUp 48.6→49.5 [15]。
結論
YOLOX以無錨框解耦、中心多正樣本、SimOTA、強增強,較v3基準約多9AP而網路延遲近似。
限制與問題
arXiv報告,最終仍NMS;SimOTA有額外成本,v6指出可能不穩 [16],時間又不含後處理。v6換TAL,v10改進免NMS。
參考文獻
- C.-Y. Wang, A. Bochkovskiy and H.-Y. M. Liao, “YOLOv7: Trainable bag-of-freebies sets new state-of-the-art for real-time object detectors,” in Proc. IEEE/CVF CVPR, pp. 7464–7475, 2023. doi
- C.-Y. Wang, I-H. Yeh and H.-Y. M. Liao, “YOLOv9: Learning what you want to learn using programmable gradient information,” in Proc. ECCV, 2024. doi
- G. Jocher, “Ultralytics YOLOv5,” software (first released 2020; v7.0 released 22 November 2022). release · documentation
- G. Jocher, A. Chaurasia and J. Qiu, “Ultralytics YOLOv8,” software, version 8.0.0, 2023 (no paper). docs · code
- G. Jocher and J. Qiu, “Ultralytics YOLO11,” software, version 11.0.0, 2024 (no paper). docs · code
- J. Lu, J. Jia, J. Yawl and C. Zhang, “YOLOv14: Adaptive real-time object detection for diverse imaging conditions,” arXiv:2608.04720, 2026 (withdrawn by the authors, 20 August 2026). arXiv
- J. Redmon, S. Divvala, R. Girshick and A. Farhadi, “You only look once: Unified, real-time object detection,” in Proc. IEEE CVPR, pp. 779–788, 2016. doi · arXiv
- J. Redmon and A. Farhadi, “YOLO9000: Better, faster, stronger,” in Proc. IEEE CVPR, pp. 6517–6525, 2017. doi · arXiv
- J. Redmon and A. Farhadi, “YOLOv3: An incremental improvement,” tech. report, arXiv:1804.02767, 2018. arXiv
- W. Liu, D. Anguelov, D. Erhan, C. Szegedy, S. Reed, C. Fu, A. C. Berg, “SSD: Single Shot MultiBox Detector,” Lecture Notes in Computer Science / Computer Vision – ECCV 2016, 2016. doi · manuscript
- T.-Y. Lin, P. Goyal, R. Girshick, K. He and P. Dollár, “Focal loss for dense object detection,” in Proc. IEEE ICCV, pp. 2999–3007, 2017. doi
- Z. Tian, C. Shen, H. Chen, T. He, “FCOS: Fully Convolutional One-Stage Object Detection,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- X. Zhou, D. Wang, P. Krähenbühl, “Objects as Points,” arXiv preprint, 2019. source
- C. Wang, I. Yeh, H. M. Liao, “You Only Learn One Representation: Unified Network for Multiple Tasks,” arXiv preprint, 2021. source
- Z. Ge, S. Liu, F. Wang, Z. Li and J. Sun, “YOLOX: Exceeding YOLO series in 2021,” arXiv:2107.08430, 2021. arXiv
- C. Li, L. Li, H. Jiang, K. Weng, Y. Geng et al., “YOLOv6: A single-stage object detection framework for industrial applications,” tech. report, arXiv:2209.02976, 2022. arXiv
- A. Wang, H. Chen, L. Liu, K. Chen, Z. Lin, J. Han and G. Ding, “YOLOv10: Real-time end-to-end object detection,” in Proc. NeurIPS, 2024. arXiv
- Y. Tian, Q. Ye and D. Doermann, “YOLOv12: Attention-centric real-time object detectors,” in Advances in Neural Information Processing Systems 38 (NeurIPS), 2025. proceedings · arXiv
- M. Lei, S. Li, Y. Wu, H. Hu, Y. Zhou et al., “YOLOv13: Real-time object detection with hypergraph-enhanced adaptive visual perception,” arXiv:2506.17733, 2025. arXiv
- G. Jocher, J. Qiu, M. Liu, S. Lyu, F. C. Akyon and M. E. Kalfaoglu, “Ultralytics YOLO26: Unified real-time end-to-end vision models,” arXiv:2606.03748, 2026 (software released January 2026). arXiv · docs
- Y. Zhao, W. Lv, S. Xu, J. Wei, G. Wang, Q. Dang, Y. Liu, J. Chen, “DETRs Beat YOLOs on Real-time Object Detection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source
- W. Lv, Y. Zhao, Q. Chang, K. Huang, G. Wang and Y. Liu, “RT-DETRv2: Improved baseline with bag-of-freebies for real-time detection transformer,” arXiv:2407.17140, 2024. arXiv
- Y. Peng, H. Li, P. Wu, Y. Zhang, X. Sun and F. Wu, “D-FINE: Redefine regression task in DETRs as fine-grained distribution refinement,” in Proc. ICLR, 2025. arXiv · code
- S. Huang, Z. Lu, X. Cun, Y. Yu, X. Zhou, X. Shen, “DEIM: DETR with Improved Matching for Fast Convergence,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2025. source
- I. Robinson, P. Robicheaux, M. Popov, D. Ramanan and N. Peri, “RF-DETR: Neural architecture search for real-time detection transformers,” in Proc. ICLR, 2026. arXiv
- S. Huang, Y. Hou, L. Liu, X. Yu and X. Shen, “Real-time object detection meets DINOv3,” arXiv:2509.20787, 2025 (revised 2026). arXiv
- A. Bochkovskiy, C.-Y. Wang and H.-Y. M. Liao, “YOLOv4: Optimal speed and accuracy of object detection,” arXiv:2004.10934, 2020. arXiv
- M. Tan, R. Pang, Q. V. Le, “EfficientDet: Scalable and Efficient Object Detection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- NVIDIA, “TensorRT documentation,” official documentation. link
- J. Deng, W. Dong, R. Socher, L. Li, Kai Li, Li Fei-Fei, “ImageNet: A large-scale hierarchical image database,” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 2009. source
- K. Simonyan, A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” arXiv preprint, 2014. source
- K. He, X. Zhang, S. Ren, J. Sun, “Deep Residual Learning for Image Recognition,” arXiv preprint, 2015. source
- T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature pyramid networks for object detection,” in Proc. IEEE CVPR, 2017. doi
- S. Liu, L. Qi, H. Qin, J. Shi and J. Jia, “Path aggregation network for instance segmentation,” in Proc. IEEE/CVF CVPR, pp. 8759–8768, 2018. doi
- K. He, X. Zhang, S. Ren, J. Sun, “Spatial Pyramid Pooling in Deep Convolutional Networks for Visual Recognition,” Lecture Notes in Computer Science / Computer Vision – ECCV 2014, 2014. doi · manuscript
- C.-Y. Wang, H.-Y. M. Liao, I-H. Yeh, Y.-H. Wu, P.-Y. Chen and J.-W. Hsieh, “CSPNet: A new backbone that can enhance learning capability of CNN,” CVPR Workshops, 2020. arXiv · doi
- A. Bochkovskiy and contributors, “Darknet: YOLOv4 configuration and detection layer,” official implementation, accessed 2 November 2026. configuration · assignment and decoding
- M. Tan, Q. V. Le, “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks,” ICML, 2019. source · proceedings
- G. Huang, Z. Liu, L. Van Der Maaten, K. Q. Weinberger, “Densely Connected Convolutional Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- S. Xie, R. Girshick, P. Dollar, Z. Tu, K. He, “Aggregated Residual Transformations for Deep Neural Networks,” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2017. doi · manuscript
- D. Misra, “Mish: A Self Regularized Non-Monotonic Activation Function,” BMVC, 2020. source
- P. Ramachandran, B. Zoph, Q. V. Le, “Searching for Activation Functions,” arXiv preprint, 2017. source
- J. Yu, Y. Jiang, Z. Wang, Z. Cao, T. Huang, “UnitBox: An Advanced Object Detection Network,” ACM Multimedia, 2016. source
- H. Rezatofighi, N. Tsoi, J. Gwak, A. Sadeghian, I. Reid, S. Savarese, “Generalized Intersection over Union: A Metric and A Loss for Bounding Box Regression,” arXiv preprint, 2019. source
- Z. Zheng, P. Wang, W. Liu, J. Li, R. Ye and D. Ren, “Distance-IoU loss: Faster and better learning for bounding box regression,” in Proc. AAAI, pp. 12993–13000, 2020. doi
- H. Zhang, M. Cisse, Y. N. Dauphin and D. Lopez-Paz, “mixup: Beyond empirical risk minimization,” in Proc. ICLR, 2018. arXiv
- S. Yun, D. Han, S. Chun, S. J. Oh, Y. Yoo, J. Choe, “CutMix: Regularization Strategy to Train Strong Classifiers With Localizable Features,” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 2019. doi · manuscript
- Nitish Srivastava, Geoffrey Hinton, Alex Krizhevsky, Ilya Sutskever, Ruslan Salakhutdinov, “Dropout: A Simple Way to Prevent Neural Networks from Overfitting,” Journal of Machine Learning Research, 2014. source
- G. Ghiasi, T. Lin, Q. V. Le, “DropBlock: A regularization method for convolutional networks,” NeurIPS, 2018. source · proceedings
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens, Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- S. Ioffe and C. Szegedy, “Batch normalization: Accelerating deep network training by reducing internal covariate shift,” in Proc. ICML, PMLR vol. 37, pp. 448–456, 2015. link
- Z. Yao, Y. Cao, S. Zheng, G. Huang, S. Lin, “Cross-Iteration Batch Normalization,” 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2021. doi · manuscript
- S. Woo, J. Park, J. Lee, I. S. Kweon, “CBAM: Convolutional Block Attention Module,” Lecture Notes in Computer Science / Computer Vision – ECCV 2018, 2018. doi · manuscript
- I. Loshchilov, F. Hutter, “SGDR: Stochastic Gradient Descent with Warm Restarts,” ICLR, 2017. source
- T.-Y. Lin, M. Maire, S. Belongie, J. Hays, P. Perona, D. Ramanan, P. Dollár and C. L. Zitnick, “Microsoft COCO: Common objects in context,” in Proc. ECCV, pp. 740–755, 2014. doi
- COCO Consortium, “COCO detection evaluation,” official evaluation description. link
- ONNX, “Open Neural Network Exchange,” official project page. link
- B. Jacob, S. Kligys, B. Chen, M. Zhu, M. Tang, A. Howard, H. Adam and D. Kalenichenko, “Quantization and training of neural networks for efficient integer-arithmetic-only inference,” in Proc. IEEE/CVF CVPR, pp. 2704–2713, 2018. doi
- N. Carion, F. Massa, G. Synnaeve, N. Usunier, A. Kirillov and S. Zagoruyko, “End-to-end object detection with transformers,” in Proc. ECCV, 2020. doi
- H. W. Kuhn, “The Hungarian method for the assignment problem,” Naval Research Logistics Quarterly, vol. 2, pp. 83–97, 1955. doi
- J. Terven, D.-M. Córdova-Esparza and J.-A. Romero-González, “A comprehensive review of YOLO architectures in computer vision: From YOLOv1 to YOLOv8 and YOLO-NAS,” Machine Learning and Knowledge Extraction, vol. 5, no. 4, pp. 1680–1716, 2023. doi · arXiv
- N. Jegham, C. Y. Koh, M. Abdelatti and A. Hendawi, “YOLO evolution: A comprehensive benchmark and architectural review of YOLOv12, YOLO11, and their previous versions,” arXiv:2411.00201, 2024 (revised 2025). arXiv
- R. Sapkota and M. Karkee, “Ultralytics YOLO evolution: An overview of YOLO27, YOLO26, YOLO11, YOLOv8, and YOLOv5 object detectors for computer vision and pattern recognition,” arXiv:2510.09653, 2025 (revised 2026). arXiv
- T. Shehzadi, K. A. Hashmi, M. Liwicki, D. Stricker and M. Z. Afzal, “Object detection with transformers: A review,” Sensors, vol. 25, no. 19, 2025. doi
- Ultralytics, “YOLO27 (coming soon),” official documentation page, accessed 2 November 2026. docs
- M. Oquab, T. Darcet, T. Moutakanni, H. Vo, M. Szafraniec et al., “DINOv2: Learning robust visual features without supervision,” arXiv:2304.07193, 2023. arXiv
- O. Siméoni, H. V. Vo, M. Seitzer, F. Baldassarre, M. Oquab et al., “DINOv3,” arXiv:2508.10104, 2025. arXiv
- X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets great again,” in Proc. IEEE/CVF CVPR, pp. 13728–13737, 2021. doi
- R. Girshick, “Fast R-CNN,” 2015 IEEE International Conference on Computer Vision (ICCV), 2015. doi · manuscript
- S. Ren, K. He, R. Girshick, J. Sun, “Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks,” arXiv preprint, 2015. source
- M. Everingham, L. Van Gool, C. K. I. Williams, J. Winn, A. Zisserman, “The Pascal Visual Object Classes (VOC) Challenge,” International Journal of Computer Vision, 2009. source
- A. Shrivastava, A. Gupta, R. Girshick, “Training Region-Based Object Detectors with Online Hard Example Mining,” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. doi · manuscript
- H. Zhang, Y. Wang, F. Dayoub and N. Sünderhauf, “VarifocalNet: An IoU-aware dense object detector,” in Proc. IEEE/CVF CVPR, pp. 8510–8519, 2021. doi
- YOLOX contributors, “YOLOX detection head,” official implementation, accessed 2 November 2026. code
- K. Duan, S. Bai, L. Xie, H. Qi, Q. Huang, Q. Tian, “CenterNet: Keypoint Triplets for Object Detection,” arXiv preprint, 2019. source
- Z. Ge, S. Liu, Z. Li, O. Yoshie and J. Sun, “OTA: Optimal transport assignment for object detection,” in Proc. IEEE/CVF CVPR, pp. 303–312, 2021. doi
- C. Li, L. Li, Y. Geng, et al., “YOLOv6 v3.0: A Full-Scale Reloading,” arXiv preprint, 2023. source
- C. Feng, Y. Zhong, Y. Gao, M. R. Scott, W. Huang, “TOOD: Task-Aligned One-Stage Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- Z. Gevorgyan, “SIoU Loss: More Powerful Learning for Bounding Box Regression,” arXiv preprint, 2022. source
- X. Li, W. Wang, L. Wu, S. Chen, X. Hu, J. Li, J. Tang and J. Yang, “Generalized focal loss: Learning qualified and distributed bounding boxes for dense object detection,” in Advances in Neural Information Processing Systems 33 (NeurIPS), 2020. proceedings
- X. Ding, H. Chen, X. Zhang, K. Huang, J. Han, G. Ding, “Re-parameterizing Your Optimizers rather than Architectures,” ICLR, 2023. source
- S. Zhang, C. Chi, Y. Yao, Z. Lei, S. Z. Li, “Bridging the Gap Between Anchor-Based and Anchor-Free Detection via Adaptive Training Sample Selection,” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2020. doi · manuscript
- C. Wang, H. M. Liao, I. Yeh, “Designing Network Design Strategies Through Gradient Path Analysis,” arXiv preprint, 2022. source
- T. Dao, D. Fu, S. Ermon, A. Rudra, C. Ré, “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness,” Advances in Neural Information Processing Systems 35, 2022. doi · manuscript
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- K. Jordan, “Muon: An optimizer for hidden layers in neural networks,” technical blog, 2024. source
- S. Shao, Z. Li, T. Zhang, C. Peng, G. Yu, X. Zhang, J. Li, J. Sun, “Objects365: A Large-Scale, High-Quality Dataset for Object Detection,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source