Latent Consistency Models:受引導潛在流的端點(2023)
選讀・DLCV 12B・單步生成 的論文導讀(第 4/7 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
LCM [10] 將一致性蒸餾移到預訓練潛在擴散系統,並把無分類器引導納入學生。它改學已引導流的端點,不只是減少原去雜訊器的步數。
一般引導分別評估有條件與無條件分支;若只壓縮未引導動態,仍留有額外成本,因此學生直接以引導強度為條件。
方法
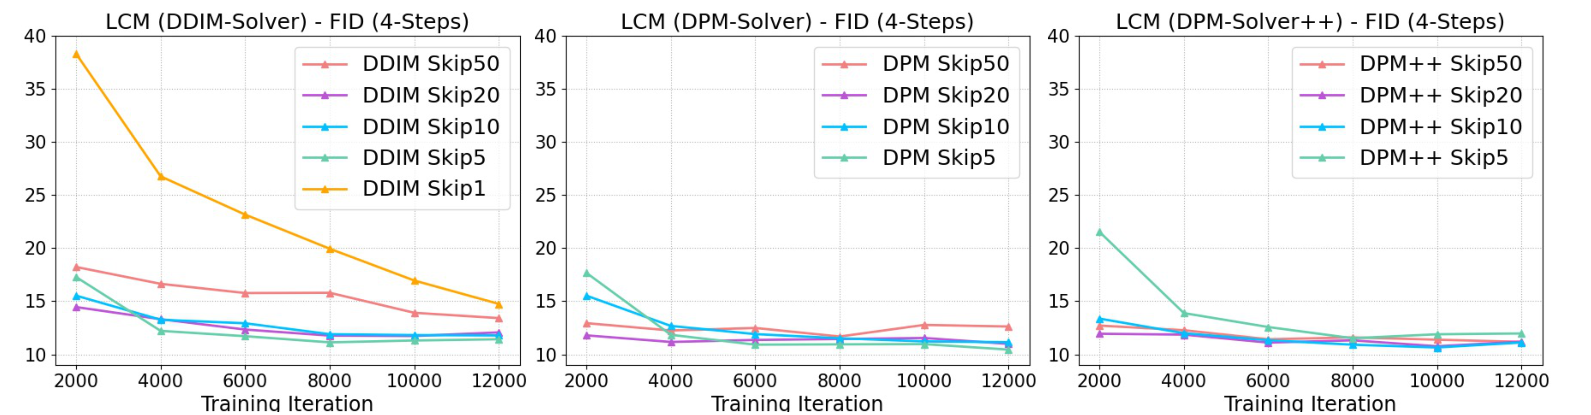
圖片來源: [10], arXiv:2310.04378v1, PDF 第 8 頁. 原始 PDF.
潛在表示。 固定編解碼器 [11] 將影像映射至潛在空間。模型輸入 、預測同形狀的乾淨潛在向量,再解碼一次。它減少空間計算,卻繼承壓縮限制。
端點參數化。 對預測 epsilon 的教師,一致性函數形式為:
是吵的潛在向量, 是提示, 是時間, 是前向係數;跳接/輸出係數滿足乾淨邊界。換成速度教師須正確轉換,不能直接替換預測意義。
引導條件。 原文教師組合為 。學生新增 嵌入,學習依提示與強度索引的一族端點映射,不是同一個未引導目標。
一致性配對。 教師求解器走向較乾淨時間;線上端點預測符合停止梯度、移動平均目標的預測。潛在距離避免每組配對都解碼並跑大型感知網路;部署不執行教師求解器。
跨步區間。 配對時間相隔可調網格索引數,避免太近的點無法提供大步學習訊號。此 skip 數字是訓練配對間隔,不是學生推論次數。
取樣。 一次端點預測可直接解碼;少步則在較低雜訊重新加雜訊並預測。排程與邊界係數屬訓練好的管線,一般擴散 scheduler 不必然適用。
結果
表 1 的 512 × 512、LAION-Aesthetic-6+ 規則 [31]、引導 8:一步/兩步/四步/八步 FID 為 35.36/13.31/11.10/11.84,CLIP 分數依原尺度為 24.14/27.83/28.69/28.84。四步 FID 明顯優於一步,八步沒有繼續改善。
表 2 的 768 × 768 FID 為 34.22/16.32/13.53/14.97。模型、解析度與子集不同,不能與 512 列或 COCO FID 直接比較。
消融實驗
求解器/skip 研究比較 DDIM、DPM-Solver、DPM-Solver++ [5]、[6] 及不同間隔;適當跨步改善收斂。選定 DDIM 設定相隔 20 個網格索引,不代表推論 20 步。
引導掃描呈現符合度與品質的取捨,沒有普遍最佳值。不同步數結果也非單調改善;只有曲線而無精確表列增益時,不補造數值。
結論
一致性蒸餾可運作於受引導潛在流,藉引導條件與跨步教師配對,讓學習目標符合少步用途。
限制與問題
學生繼承潛在壓縮、教師品質及訓練引導範圍;一步在原實驗仍弱於多步。教師目標與相容取樣器依然必要。後續轉接器和部署系統須各自驗證,跨論文分數差不是一致性目標的獨立測試。
參考文獻
- Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon, B. Poole, “Score-Based Generative Modeling through Stochastic Differential Equations,” ICLR, 2021. paper
- Y. Lipman, M. Havasi, P. Holderrieth, et al., “Flow Matching Guide and Code,” arXiv tutorial, 2024. paper
- T. Karras, M. Aittala, T. Aila, S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. source
- X. Fan, Z. Wu, H. Wu, L. Cao, “A Survey on Pre-Trained Diffusion Model Distillations,” arXiv preprint, version 2, 2025. paper
- J. Song, C. Meng, S. Ermon, “Denoising Diffusion Implicit Models,” ICLR, 2021. paper
- C. Lu, Y. Zhou, F. Bao, J. Chen, C. Li, J. Zhu, “DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps,” NeurIPS, 2022. paper
- T. Salimans, J. Ho, “Progressive Distillation for Fast Sampling of Diffusion Models,” ICLR, 2022. paper
- Y. Song, P. Dhariwal, M. Chen, I. Sutskever, “Consistency Models,” ICML, 2023. paper
- Y. Song, P. Dhariwal, “Improved Techniques for Training Consistency Models,” ICLR, 2024. paper
- S. Luo, Y. Tan, L. Huang, J. Li, H. Zhao, “Latent Consistency Models: Synthesizing High-Resolution Images with Few-Step Inference,” arXiv preprint, 2023. paper
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. source
- X. Liu, C. Gong, Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” ICLR, 2023. paper
- X. Liu, X. Zhang, J. Ma, J. Peng, Q. Liu, “InstaFlow: One Step is Enough for High-Quality Diffusion-Based Text-to-Image Generation,” ICLR, 2024. paper
- A. Sauer, D. Lorenz, A. Blattmann, R. Rombach, “Adversarial Diffusion Distillation,” ECCV, 2024. paper
- A. Sauer, F. Boesel, T. Dockhorn, A. Blattmann, P. Esser, R. Rombach, “Fast High-Resolution Image Synthesis with Latent Adversarial Diffusion Distillation,” SIGGRAPH Asia Conference Papers, 2024. paper · published version
- T. Yin, M. Gharbi, R. Zhang, E. Shechtman, F. Durand, W. T. Freeman, T. Park, “One-step Diffusion with Distribution Matching Distillation,” CVPR, 2024. paper
- T. H. Nguyen, A. Tran, “SwiftBrush: One-Step Text-to-Image Diffusion Model with Variational Score Distillation,” CVPR, 2024. paper
- M. Zhou, H. Zheng, Z. Wang, M. Yin, H. Huang, “Score identity Distillation: Exponentially Fast Distillation of Pretrained Diffusion Models for One-Step Generation,” ICML, 2024. paper
- T. Yin, M. Gharbi, T. Park, R. Zhang, E. Shechtman, F. Durand, W. T. Freeman, “Improved Distribution Matching Distillation for Fast Image Synthesis,” NeurIPS, 2024. paper
- K. Frans, D. Hafner, S. Levine, P. Abbeel, “One Step Diffusion via Shortcut Models,” ICLR, 2025. paper
- Z. Geng, M. Deng, X. Bai, J. Z. Kolter, K. He, “Mean Flows for One-step Generative Modeling,” NeurIPS, 2025. paper
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. source
- A. Radford, J. W. Kim, C. Hallacy, et al., “Learning Transferable Visual Models From Natural Language Supervision,” ICML, 2021. paper
- D. Ghosh, H. Hajishirzi, L. Schmidt, “GenEval: An Object-Focused Framework for Evaluating Text-to-Image Alignment,” NeurIPS Datasets and Benchmarks, 2023. paper
- A. Krizhevsky, V. Nair and G. Hinton, “CIFAR-10 and CIFAR-100 datasets,” official dataset page; companion technical report: A. Krizhevsky, “Learning Multiple Layers of Features from Tiny Images,” 2009. dataset and report
- J. Deng, W. Dong, R. Socher, L. Li, Kai Li, Li Fei-Fei, “ImageNet: A large-scale hierarchical image database,” CVPR, 2009. doi
- T. Lin, M. Maire, S. Belongie, et al., “Microsoft COCO: Common Objects in Context,” ECCV, 2014. paper
- L. Yang, Z. Zhang, Y. Song, et al., “Diffusion Models: A Comprehensive Survey of Methods and Applications,” ACM Computing Surveys, 2023. paper
- Z. Yu, J. Yuan, H. Yang, et al., “DMAD: Distribution Matching as Adversarial Distillation for Fast Visual Generation,” arXiv preprint, 2026. paper
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- C. Schuhmann, R. Beaumont, R. Vencu, et al., “LAION-5B: An open large-scale dataset for training next generation image-text models,” NeurIPS Datasets and Benchmarks, 2022. paper