Radosavovic 等人:Designing Network Design Spaces(RegNet,CVPR 2020)
選讀・DLCV 01B・網路的積木與組合:分類與影像復原網路 的論文導讀(第 2/4 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
Radosavovic 等人 [16] 想設計的是整個容易描述、又較可能有效的網路家族。只搜尋一個冠軍,無法知道鄰近設計是否可靠;因此 RegNet 分析抽樣架構的分布,不把單一最佳模型當成全部論據。
方法
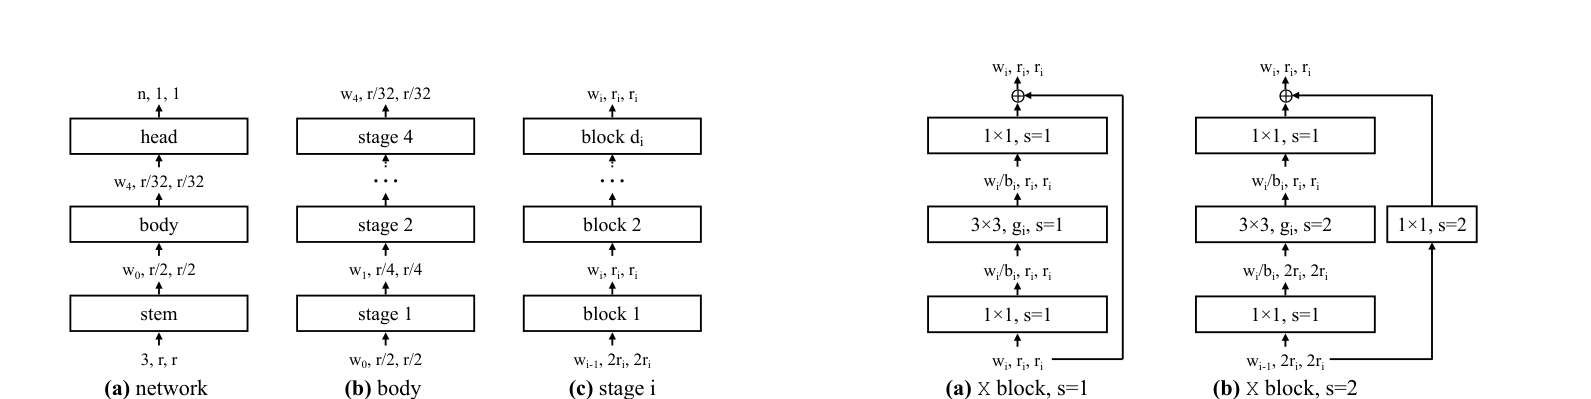
圖片來源: [16], Published paper PDF, PDF 第 4 頁. 原始 PDF.
先定義空間,再搜尋。 AnyNet 包含起始層、重複殘差階段與分類頭,以階段深度、寬度、瓶頸比例及群組寬度描述選擇。論文在相近複雜度/訓練條件下抽樣,檢查錯誤分布。經驗累積分布函數回答「有多少比例的模型低於某個錯誤門檻」,而非只列最佳樣本。
移除證據不支持的自由度。 後續空間共用瓶頸/群組設定,並偏好隨深度增加的階段寬度。核心規律是逐區塊線性增加,再量化成重複的階段寬度,可簡化寫成:
是區塊編號, 為深度, 為起始寬度, 為線性增量, 為量化倍率, 為最終通道數。相鄰且同寬的區塊形成階段;有效群組卷積還要檢查寬度相容性,單靠此式不保證剛好四階段。
RegNetX 使用殘差群組卷積區塊,RegNetY 再加 squeeze-and-excitation。它們是由設計空間生成的具體家族,不是宣稱量化本身會從影像學得最佳架構。
結果
論文跨預算比較 ImageNet 錯誤率、複雜度與實測 GPU 推論時間,顯示精簡結構化空間可產生有競爭力的模型。FLOPs 好看不保證延遲低;寬度、深度、啟用值大小與裝置執行方式都影響時間。
消融實驗
從 AnyNet 逐步限制到 RegNet 時,比較的是抽樣分布。分布往低錯誤移動,比只找到一個幸運冠軍更能支持空間有用,但不表示每個樣本都改善。逐階段寬度分析支持量化線性形式,瓶頸與群組研究則檢查哪些自由度可共用或限制。
閱讀時須連同抽樣、訓練預算一起看。限制空間會改變可抽樣模型集合,這是設計空間研究,不是固定模型只替換一層的實驗。
結論
RegNet 提供精簡、可理解的網路家族生成方式,將架構設計連接到分布證據,並區分模型複雜度與實測速度。
限制與問題
規律建立於特定分類資料、區塊與訓練流程,不能當作修復或所有密集工作通用定律。搜尋、驗證空間仍耗計算,較強訓練配方也可能改變排名。部署時應實測自己的解析度、批次與裝置,不能直接繼承其他設定的延遲數字。
參考文獻
-
K. He, X. Zhang, S. Ren and J. Sun, “Deep Residual Learning for Image Recognition,” in Proc. IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2016. CVF · arXiv
-
Z. Liu, H. Mao, C.-Y. Wu, C. Feichtenhofer, T. Darrell and S. Xie, “A ConvNet for the 2020s,” in Proc. IEEE/CVF CVPR, 2022. CVF · arXiv
-
A. Dosovitskiy, L. Beyer, A. Kolesnikov, D. Weissenborn, X. Zhai, T. Unterthiner, M. Dehghani, M. Minderer et al., “An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale,” in International Conference on Learning Representations (ICLR), 2021. arXiv
-
J. Liang, J. Cao, G. Sun, K. Zhang, L. Van Gool and R. Timofte, “SwinIR: Image Restoration Using Swin Transformer,” in Proc. IEEE/CVF International Conference on Computer Vision Workshops (ICCVW), 2021. CVF · arXiv
-
T.-Y. Lin, P. Dollár, R. Girshick, K. He, B. Hariharan and S. Belongie, “Feature Pyramid Networks for Object Detection,” in Proc. IEEE CVPR, 2017. CVF · arXiv
-
Z. Liu, Y. Lin, Y. Cao, H. Hu, Y. Wei, Z. Zhang, S. Lin and B. Guo, “Swin Transformer: Hierarchical Vision Transformer Using Shifted Windows,” in Proc. IEEE/CVF International Conference on Computer Vision (ICCV), 2021. CVF · arXiv
-
O. Russakovsky, J. Deng, H. Su, J. Krause, S. Satheesh, S. Ma, Z. Huang, A. Karpathy et al., “ImageNet Large Scale Visual Recognition Challenge,” International Journal of Computer Vision, vol. 115, no. 3, pp. 211–252, 2015. doi
-
W. Yu, M. Luo, P. Zhou, C. Si, Y. Zhou, X. Wang, J. Feng and S. Yan, “MetaFormer Is Actually What You Need for Vision,” in Proc. IEEE/CVF CVPR, 2022. CVF · arXiv
-
A. G. Howard, M. Zhu, B. Chen, D. Kalenichenko, W. Wang, T. Weyand, M. Andreetto and H. Adam, “MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications,” arXiv:1704.04861, 2017. arXiv
-
M. Sandler, A. Howard, M. Zhu, A. Zhmoginov and L.-C. Chen, “MobileNetV2: Inverted Residuals and Linear Bottlenecks,” in Proc. IEEE/CVF CVPR, 2018. CVF · arXiv
-
K. He, X. Zhang, S. Ren and J. Sun, “Identity Mappings in Deep Residual Networks,” in Proc. European Conference on Computer Vision (ECCV), LNCS, Springer, 2016. doi · arXiv
-
B. Lim, S. Son, H. Kim, S. Nah and K. M. Lee, “Enhanced Deep Residual Networks for Single Image Super-Resolution,” in Proc. IEEE CVPR Workshops (CVPRW), 2017. CVF · arXiv
-
H. Touvron, M. Cord, A. Sablayrolles, G. Synnaeve and H. Jégou, “Going Deeper With Image Transformers,” in Proc. IEEE/CVF ICCV, 2021. CVF
-
L. Chen, X. Chu, X. Zhang and J. Sun, NAFNet official implementation,
basicsr/models/archs/NAFNet_arch.py, GitHub (megvii-research/NAFNet), accessed 2026. code -
Y. Zhang, K. Li, K. Li, L. Wang, B. Zhong and Y. Fu, “Image Super-Resolution Using Very Deep Residual Channel Attention Networks,” in Proc. ECCV, 2018. CVF · arXiv
-
I. Radosavovic, R. P. Kosaraju, R. Girshick, K. He and P. Dollár, “Designing Network Design Spaces,” in Proc. IEEE/CVF CVPR, 2020. CVF · arXiv
-
J. Hu, L. Shen and G. Sun, “Squeeze-and-Excitation Networks,” in Proc. IEEE/CVF CVPR, 2018. CVF · arXiv
-
S. Woo, J. Park, J.-Y. Lee and I. S. Kweon, “CBAM: Convolutional Block Attention Module,” in Proc. ECCV, 2018. CVF · arXiv
-
L. Chen, X. Chu, X. Zhang and J. Sun, “Simple Baselines for Image Restoration,” in Proc. ECCV, LNCS, Springer, 2022. doi · arXiv
-
M.-H. Guo, T.-X. Xu, J.-J. Liu, Z.-N. Liu, P.-T. Jiang, T.-J. Mu, S.-H. Zhang, R. R. Martin, M.-M. Cheng and S.-M. Hu, “Attention Mechanisms in Computer Vision: A Survey,” Computational Visual Media, vol. 8, no. 3, pp. 331–368, 2022. doi · arXiv
-
S. W. Zamir, A. Arora, S. Khan, M. Hayat, F. S. Khan and M.-H. Yang, “Restormer: Efficient Transformer for High-Resolution Image Restoration,” in Proc. IEEE/CVF CVPR, 2022. CVF · arXiv
-
X. Chen, Z. Li, Y. Pu, Y. Liu, J. Zhou, Y. Qiao and C. Dong, “A Comparative Study of Image Restoration Networks for General Backbone Network Design,” in Proc. ECCV 2024, LNCS, Springer, 2025. doi · arXiv
-
S. Ioffe and C. Szegedy, “Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift,” in Proc. International Conference on Machine Learning (ICML), PMLR 37, 2015. PMLR
-
J. L. Ba, J. R. Kiros and G. E. Hinton, “Layer Normalization,” arXiv:1607.06450, 2016. arXiv
-
D. Ulyanov, A. Vedaldi and V. Lempitsky, “Instance Normalization: The Missing Ingredient for Fast Stylization,” arXiv:1607.08022, 2016. arXiv
-
Y. Wu and K. He, “Group Normalization,” in Proc. ECCV, 2018. CVF · arXiv
-
C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017. CVF
-
X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018. CVF · arXiv
-
K. Zhang, W. Zuo, Y. Chen, D. Meng and L. Zhang, “Beyond a Gaussian Denoiser: Residual Learning of Deep CNN for Image Denoising,” IEEE Transactions on Image Processing, vol. 26, no. 7, pp. 3142–3155, 2017. doi · arXiv
-
Q. Huynh-Thu and M. Ghanbari, “Scope of Validity of PSNR in Image/Video Quality Assessment,” Electronics Letters, vol. 44, no. 13, pp. 800–801, 2008. doi
-
A. Abdelhamed, S. Lin and M. S. Brown, “A High-Quality Denoising Dataset for Smartphone Cameras,” in Proc. IEEE/CVF CVPR, 2018. CVF
-
S. Nah, T. H. Kim and K. M. Lee, “Deep Multi-Scale Convolutional Neural Network for Dynamic Scene Deblurring,” in Proc. IEEE CVPR, 2017. CVF
-
N. Shazeer, “GLU Variants Improve Transformer,” arXiv:2002.05202, 2020. arXiv
-
Y. N. Dauphin, A. Fan, M. Auli and D. Grangier, “Language Modeling with Gated Convolutional Networks,” in Proc. ICML, PMLR 70, 2017. PMLR
-
D. Hendrycks and K. Gimpel, “Gaussian Error Linear Units (GELUs),” arXiv:1606.08415, 2016. arXiv
-
W. Shi, J. Caballero, F. Huszár, J. Totz, A. P. Aitken, R. Bishop, D. Rueckert and Z. Wang, “Real-Time Single Image and Video Super-Resolution Using an Efficient Sub-Pixel Convolutional Neural Network,” in Proc. IEEE CVPR, 2016. CVF · arXiv
-
A. Odena, V. Dumoulin and C. Olah, “Deconvolution and Checkerboard Artifacts,” Distill, vol. 1, no. 10, 2016. Distill · doi
-
A. Aitken, C. Ledig, L. Theis, J. Caballero, Z. Wang and W. Shi, “Checkerboard Artifact Free Sub-Pixel Convolution: A Note on Sub-Pixel Convolution, Resize Convolution and Convolution Resize,” arXiv:1707.02937, 2017. arXiv
-
O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” in Proc. Medical Image Computing and Computer-Assisted Intervention (MICCAI), LNCS, Springer, pp. 234–241, 2015. doi · arXiv
-
G. Huang, Z. Liu, L. van der Maaten and K. Q. Weinberger, “Densely Connected Convolutional Networks,” in Proc. IEEE CVPR, 2017. CVF
-
L.-C. Chen, G. Papandreou, I. Kokkinos, K. Murphy and A. L. Yuille, “DeepLab: Semantic Image Segmentation with Deep Convolutional Nets, Atrous Convolution, and Fully Connected CRFs,” IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 40, no. 4, pp. 834–848, 2018. doi · arXiv
-
W. Luo, Y. Li, R. Urtasun and R. Zemel, “Understanding the Effective Receptive Field in Deep Convolutional Neural Networks,” in Advances in Neural Information Processing Systems (NeurIPS), 2016. NeurIPS · arXiv
-
J. Kim, J. K. Lee and K. M. Lee, “Accurate Image Super-Resolution Using Very Deep Convolutional Networks,” in Proc. IEEE CVPR, 2016. CVF · arXiv
-
H. Guo, J. Li, T. Dai, Z. Ouyang, X. Ren and S.-T. Xia, “MambaIR: A Simple Baseline for Image Restoration with State-Space Model,” in Proc. ECCV 2024, LNCS, Springer, 2025. doi · arXiv
-
ITU-T, “Recommendation T.81: Information technology – Digital compression and coding of continuous-tone still images – Requirements and guidelines” (the JPEG standard), 1992. ITU
-
T. Elsken, J. H. Metzen and F. Hutter, “Neural Architecture Search: A Survey,” Journal of Machine Learning Research, vol. 20, 2019. JMLR · arXiv
-
A. Khan, A. Sohail, U. Zahoora and A. S. Qureshi, “A Survey of the Recent Architectures of Deep Convolutional Neural Networks,” Artificial Intelligence Review, vol. 53, no. 8, pp. 5455–5516, 2020. doi · arXiv
-
S. Khan, M. Naseer, M. Hayat, S. W. Zamir, F. S. Khan and M. Shah, “Transformers in Vision: A Survey,” ACM Computing Surveys, vol. 54, no. 10s, 2022. doi · arXiv
-
S. Woo, S. Debnath, R. Hu, X. Chen, Z. Liu, I. S. Kweon and S. Xie, “ConvNeXt V2: Co-Designing and Scaling ConvNets With Masked Autoencoders,” in Proc. IEEE/CVF CVPR, 2023. CVF · arXiv
-
M. Goldblum, H. Souri, R. Ni, M. Shu, V. Prabhu, G. Somepalli, P. Chattopadhyay, M. Ibrahim et al., “Battle of the Backbones: A Large-Scale Comparison of Pretrained Models across Computer Vision Tasks,” in Advances in Neural Information Processing Systems (NeurIPS), 2023. arXiv
-
X. Chen, X. Wang, J. Zhou, Y. Qiao and C. Dong, “Activating More Pixels in Image Super-Resolution Transformer,” in Proc. IEEE/CVF CVPR, 2023. CVF · arXiv
-
H. Guo, Y. Guo, Y. Zha, Y. Zhang, W. Li, T. Dai, S.-T. Xia and Y. Li, “MambaIRv2: Attentive State Space Restoration,” in Proc. IEEE/CVF CVPR, 2025. CVF · arXiv
-
A. Araujo, W. Norris and J. Sim, “Computing Receptive Fields of Convolutional Neural Networks,” Distill, vol. 4, no. 11, 2019. Distill · doi
-
X. Ding, X. Zhang, N. Ma, J. Han, G. Ding and J. Sun, “RepVGG: Making VGG-style ConvNets Great Again,” in Proc. IEEE/CVF CVPR, pp. 13733–13742, 2021. CVF paper
-
S. Zagoruyko and N. Komodakis, “DiracNets: Training Very Deep Neural Networks Without Skip-Connections,” arXiv:1706.00388, 2017. arXiv
-
X. Ding, Y. Guo, G. Ding and J. Han, “ACNet: Strengthening the Kernel Skeletons for Powerful CNN via Asymmetric Convolution Blocks,” in Proc. IEEE/CVF ICCV, 2019. CVF
-
H. Zhao, J. Shi, X. Qi, X. Wang and J. Jia, “Pyramid Scene Parsing Network,” in Proc. IEEE CVPR, 2017. CVF
-
M. Cordts, M. Omran, S. Ramos, T. Rehfeld, M. Enzweiler, R. Benenson, U. Franke, S. Roth and B. Schiele, “The Cityscapes Dataset for Semantic Urban Scene Understanding,” in Proc. IEEE CVPR, 2016. CVF
-
E. D. Cubuk, B. Zoph, D. Mane, V. Vasudevan and Q. V. Le, “AutoAugment: Learning Augmentation Strategies From Data,” in Proc. IEEE/CVF CVPR, 2019. CVF
-
H. Zhang, M. Cisse, Y. N. Dauphin and D. Lopez-Paz, “mixup: Beyond Empirical Risk Minimization,” in Proc. ICLR, 2018. arXiv