SeeSR:退化感知的語意提示(CVPR 2024)
選讀・DLCV 09A.1・盲與真實世界影像超解析度 的論文導讀(第 10/11 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
本頁內容
- SRMD:一個網路處理多種已知退化(CVPR 2018)
- IKC:反覆修正模糊核(CVPR 2019)
- KernelGAN:以單圖 GAN 估計核(NeurIPS 2019)
- DAN:展開交替最佳化(NeurIPS 2020)
- DASR:對比退化表示(CVPR 2021)
- BSRGAN:實用的退化模型(ICCV 2021)
- Real-ESRGAN:純合成高階退化(ICCVW 2021)
- StableSR:以時間感知編碼器控制凍結先驗(IJCV 2024)
- DiffBIR:先移除退化,再生成細節(ECCV 2024)
- SeeSR:退化感知的語意提示(CVPR 2024)
- SUPIR:擴大先驗、資料與文字控制(CVPR 2024)
電腦視覺深度學習
挑戰
同一模糊物件可有多種解釋;錯標籤會讓先驗清楚畫出錯物件。SeeSR [29] 把語意條件也視為退化估計問題,乾淨照片標註器不自動適合 LR。
結構約束位置,硬標籤提供概念,軟特徵保留標籤清單漏掉的資訊;另改起點減少純雜訊在平坦區生成不必要紋理。
方法
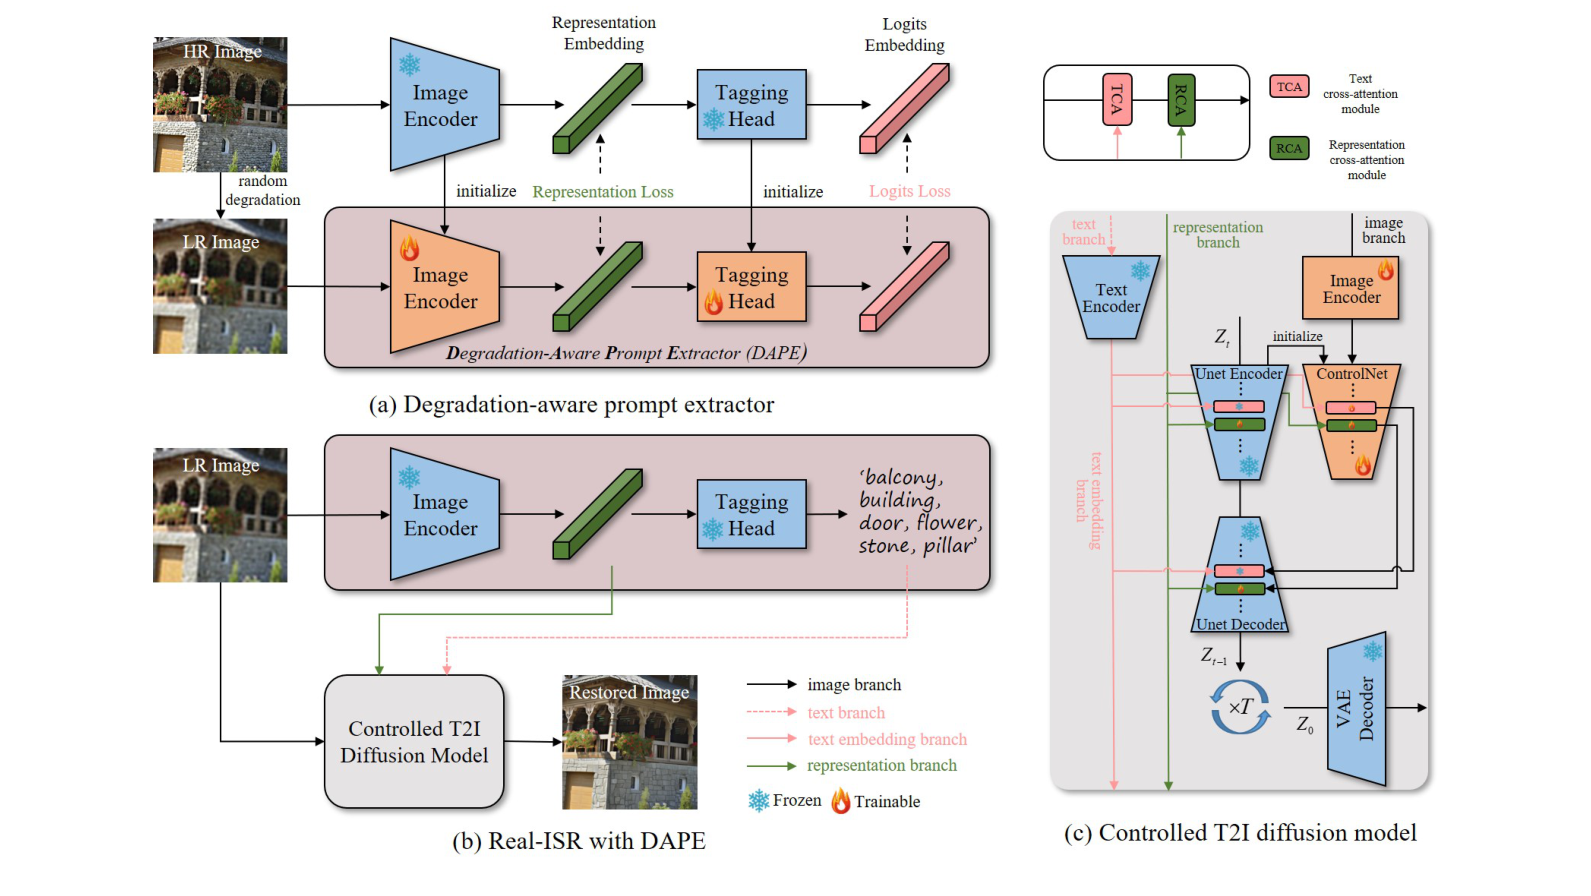
圖片來源: [29], arXiv:2311.16518v2, PDF 第 5 頁. 原始 PDF.
DAPE。 預訓練標註模型 [78] 形成凍結乾淨教師及可調退化分支;配對 HR 、LR 對齊表示和標籤 logits:
為表示, 是閾值前分數, 平衡,配對向量同維。低秩調適 [79] 降低成本;乾淨教師固定,退化分支學抗損傷語意,依賴訓練配對。
硬/軟提示。 閾值標籤作文字,未閾值表示作軟條件。閾值有召回/精確取捨,軟表示補資訊,但兩者都不確定不可辨識物件。
影像與表示控制。 ControlNet 式 [42] 提供影像特徵;文字 cross-attention 後再加表示 cross-attention,query 來自去雜訊特徵,key/value 來自軟語意。骨幹凍結,新增編碼器、控制及注意力以雜訊預測訓練。
LR 起點嵌入。 是放大 LR 的自動編碼, 是末端訊號係數,從下式開始:
狀態形狀符合模型,以 LR 訊號取代全雜訊起點,尤其適合原排程仍殘留末端訊號時。這是推論策略,不是新似然,也不保證消除虛構。
結果
×4 合成、實拍與真實低品質圖的研究中,對真值混淆率 38.6%,真實圖最佳選擇率 57.1%。兩者問題與候選不同,不是同一種準確率。
補充時間:V100 32 GB、128→512,SeeSR 50 步/7.24 秒,StableSR 200/18.70,Real-ESRGAN 0.09 秒。不是手機預測,步數也沒涵蓋提示與編碼器工作。
消融實驗
補充表 1 加 LR 起點:DRealSR PSNR 26.55→27.90,LPIPS 0.3952→0.3299,CLIPIQA 0.7248→0.6708。DIV2K PSNR 20.58→21.04,FID 卻 32.53→32.79;不是所有指標都改善。
表 3 的 DIV2K FID:無 DAPE/表示注意力 37.35;直接用乾淨標註器 46.34;硬提示 38.92;軟提示 38.77;完整 32.79。軟提示 LPIPS 略好卻有語意錯誤,互補是整體語意與多指標主張。標註準確度另有實驗,不能只憑 SR 好看推論。
結論
語意估計也須為退化訓練;結構、標籤與連續表示比直接套乾淨標籤提供更可靠引導。
限制與問題
強退化仍會誤標,先驗可能放大錯誤,小字小臉仍難。標註器增加記憶體與時間;LR 嵌入不使細節變成事實。單步後繼方法若保留擷取器,計時仍須包含它。
參考文獻
- N. Efrat, D. Glasner, A. Apartsin, B. Nadler and A. Levin, “Accurate Blur Models vs. Image Priors in Single Image Super-Resolution,” in Proc. IEEE ICCV, 2013, pp. 2832–2839. doi · CVF
- K. Zhang, W. Zuo and L. Zhang, “Learning a Single Convolutional Super-Resolution Network for Multiple Degradations,” CVPR, 2018. paper
- A. Liu, Y. Liu, J. Gu, Y. Qiao, C. Dong, “Blind Image Super-Resolution: A Survey and Beyond,” IEEE TPAMI (early access), 2022. source
- Honggang Chen, Xiaohai He, Linbo Qing, Yuanyuan Wu, Chao Ren, Ray E. Sheriff, Ce Zhu, “Real-world single image super-resolution: A brief review,” Information Fusion, 2022. source
- B. B. Moser, A. S. Shanbhag, F. Raue, S. Frolov, S. Palacio and A. Dengel, “Diffusion Models, Image Super-Resolution, and Everything: A Survey,” IEEE Transactions on Neural Networks and Learning Systems, vol. 36, no. 7, pp. 11793–11813, 2025. doi · arXiv
- Y. Xu, S. R. Tseng, Y. Tseng, H. Kuo, Y. Tsai, “Unified Dynamic Convolutional Network for Super-Resolution with Variational Degradations,” CVPR, 2020. source
- K. Zhang, L. Van Gool, R. Timofte, “Deep Unfolding Network for Image Super-Resolution,” CVPR, 2020. source
- J. Gu, H. Lu, W. Zuo and C. Dong, “Blind Super-Resolution With Iterative Kernel Correction,” CVPR, 2019. paper
- Z. Luo, Y. Huang, S. Li, L. Wang and T. Tan, “Unfolding the Alternating Optimization for Blind Super Resolution,” NeurIPS, 2020. paper
- Z. Luo, H. Huang, L. Yu, Y. Li, H. Fan and S. Liu, “Deep Constrained Least Squares for Blind Image Super-Resolution,” CVPR, 2022. paper
- T. Michaeli, M. Irani, “Nonparametric Blind Super-resolution,” Proceedings of the IEEE International Conference on Computer Vision, 2013. source
- S. Bell-Kligler, A. Shocher and M. Irani, “Blind Super-Resolution Kernel Estimation using an Internal-GAN,” NeurIPS, 2019. paper
- A. Shocher, N. Cohen and M. Irani, “‘Zero-Shot’ Super-Resolution Using Deep Internal Learning,” in Proc. IEEE/CVF CVPR, 2018, pp. 3118–3126. doi · arXiv
- L. Wang, Y. Wang, X. Dong, Q. Xu, J. Yang, W. An and Y. Guo, “Unsupervised Degradation Representation Learning for Blind Super-Resolution,” CVPR, 2021. paper
- B. Xia, Y. Zhang, Y. Wang, Y. Tian, W. Yang, R. Timofte and L. Van Gool, “Knowledge Distillation Based Degradation Estimation for Blind Super-Resolution,” ICLR, 2023. paper
- K. Zhang, J. Liang, L. Van Gool, R. Timofte, “Designing a Practical Degradation Model for Deep Blind Image Super-Resolution,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- X. Wang, L. Xie, C. Dong, Y. Shan, “Real-ESRGAN: Training Real-World Blind Super-Resolution With Pure Synthetic Data,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2021. source
- J. Liang, H. Zeng, L. Zhang, “Efficient and Degradation-Adaptive Network for Real-World Image Super-Resolution,” ECCV, 2022. source
- J. Cai, H. Zeng, H. Yong, Z. Cao, L. Zhang, “Toward Real-World Single Image Super-Resolution: A New Benchmark and a New Model,” Proceedings of the IEEE/CVF International Conference on Computer Vision, 2019. source
- P. Wei, Z. Xie, H. Lu, Z. Zhan, Q. Ye, W. Zuo, L. Lin, “Component Divide-and-Conquer for Real-World Image Super-Resolution,” ECCV, 2020. source
- C. Chen, Z. Xiong, X. Tian, Z. Zha, F. Wu, “Camera Lens Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2019. source
- Y. Yuan, S. Liu, J. Zhang, Y. Zhang, C. Dong, L. Lin, “Unsupervised Image Super-Resolution using Cycle-in-Cycle Generative Adversarial Networks,” CVPR Workshops, 2018. source
- A. Bulat, J. Yang, G. Tzimiropoulos, “To learn image super-resolution, use a GAN to learn how to do image degradation first,” ECCV, 2018. source
- M. Fritsche, S. Gu, R. Timofte, “Frequency Separation for Real-World Super-Resolution,” ICCV Workshops, 2019. source
- X. Ji, Y. Cao, Y. Tai, C. Wang, J. Li, F. Huang, “Real-World Super-Resolution via Kernel Estimation and Noise Injection,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2020. source
- J. Wang, Z. Yue, S. Zhou, K. C. K. Chan, C. C. Loy, “Exploiting Diffusion Prior for Real-World Image Super-Resolution,” IJCV, 2024. source
- X. Lin, J. He, Z. Chen, et al., “DiffBIR: Towards Blind Image Restoration with Generative Diffusion Prior,” ECCV, 2024. source
- T. Yang, R. Wu, P. Ren, X. Xie, L. Zhang, “Pixel-Aware Stable Diffusion for Realistic Image Super-resolution and Personalized Stylization,” ECCV, 2024. source
- R. Wu, T. Yang, L. Sun, Z. Zhang, S. Li, L. Zhang, “SeeSR: Towards Semantics-Aware Real-World Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024. source · supplementary experiments
- F. Yu, J. Gu, Z. Li, et al., “Scaling Up to Excellence: Practicing Model Scaling for Photo-Realistic Image Restoration In the Wild,” CVPR, 2024. source
- Z. Yue, J. Wang, C. C. Loy, “ResShift: Efficient Diffusion Model for Image Super-resolution by Residual Shifting,” NeurIPS, 2023. source
- X. Wang, K. Yu, C. Dong, C. C. Loy, “Recovering Realistic Texture in Image Super-Resolution by Deep Spatial Feature Transform,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, 2018. source
- K. He, H. Fan, Y. Wu, S. Xie, R. Girshick, “Momentum Contrast for Unsupervised Visual Representation Learning,” CVPR, 2020. source
- X. Wang, K. Yu, S. Wu, J. Gu, Y. Liu, C. Dong, Y. Qiao and C. C. Loy, “ESRGAN: Enhanced Super-Resolution Generative Adversarial Networks,” in Proc. ECCV Workshops, 2018 (Lecture Notes in Computer Science, 2019), pp. 63–79. doi · arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” in Proc. MICCAI, 2015, pp. 234–241. doi · arXiv
- T. Miyato, T. Kataoka, M. Koyama, Y. Yoshida, “Spectral Normalization for Generative Adversarial Networks,” ICLR, 2018. source
- J. Liang, H. Zeng, L. Zhang, “Details or Artifacts: A Locally Discriminative Learning Approach to Realistic Image Super-Resolution,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2022. source
- A. Ignatov, N. Kobyshev, R. Timofte, K. Vanhoey, L. Van Gool, “DSLR-Quality Photos on Mobile Devices with Deep Convolutional Networks,” ICCV, 2017. source
- A. Lugmayr, M. Danelljan, R. Timofte, “Unsupervised Learning for Real-World Super-Resolution,” arXiv preprint, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “NTIRE 2020 Challenge on Real-World Image Super-Resolution: Methods and Results,” CVPR Workshops, 2020. source
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser, B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. source
- L. Zhang, A. Rao, M. Agrawala, “Adding Conditional Control to Text-to-Image Diffusion Models,” ICCV, 2023. source
- Y. Ai, X. Zhou, H. Huang, X. Han, Z. Chen, Q. You, H. Yang, “DreamClear: High-Capacity Real-World Image Restoration with Privacy-Safe Dataset Curation,” NeurIPS, 2024. source
- Z. Duan, J. Zhang, X. Jin, et al., “DiT4SR: Taming Diffusion Transformer for Real-World Image Super-Resolution,” ICCV, 2025. source
- R. Wu, L. Sun, Z. Ma, L. Zhang, “One-Step Effective Diffusion Network for Real-World Image Super-Resolution,” NeurIPS, 2024. source
- Y. Wang, W. Yang, X. Chen, et al., “SinSR: Diffusion-Based Image Super-Resolution in a Single Step,” CVPR, 2024. source
- E. Agustsson and R. Timofte, “NTIRE 2017 Challenge on Single Image Super-Resolution: Dataset and Study,” in Proc. IEEE CVPR Workshops, 2017, pp. 1122–1131. doi · CVF
- Z. Wang, A. C. Bovik, H. R. Sheikh and E. P. Simoncelli, “Image Quality Assessment: From Error Visibility to Structural Similarity,” IEEE Transactions on Image Processing, vol. 13, no. 4, pp. 600–612, 2004. doi
- R. Zhang, P. Isola, A. A. Efros, E. Shechtman and O. Wang, “The Unreasonable Effectiveness of Deep Features as a Perceptual Metric,” in Proc. IEEE/CVF CVPR, 2018, pp. 586–595. doi · arXiv
- K. Ding, K. Ma, S. Wang, E. P. Simoncelli, “Image Quality Assessment: Unifying Structure and Texture Similarity,” IEEE TPAMI, 2022. source
- A. Mittal, R. Soundararajan and A. C. Bovik, “Making a “Completely Blind” Image Quality Analyzer,” IEEE Signal Processing Letters, vol. 20, no. 3, pp. 209–212, 2013. doi
- J. Ke, Q. Wang, Y. Wang, P. Milanfar, F. Yang, “MUSIQ: Multi-scale Image Quality Transformer,” ICCV, 2021. source
- S. Yang, T. Wu, S. Shi, S. Lao, Y. Gong, M. Cao, J. Wang, Y. Yang, “MANIQA: Multi-dimension Attention Network for No-Reference Image Quality Assessment,” CVPR Workshops, 2022. source
- J. Wang, K. C. K. Chan, C. C. Loy, “Exploring CLIP for Assessing the Look and Feel of Images,” AAAI, 2023. source
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler, S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. source
- R. Timofte, S. Gu, J. Wu, L. Van Gool, “NTIRE 2018 Challenge on Single Image Super-Resolution: Methods and Results,” Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition Workshops, 2018. source
- J. Cai, S. Gu, R. Timofte, L. Zhang, “NTIRE 2019 Challenge on Real Image Super-Resolution: Methods and Results,” Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops, 2019. source
- A. Lugmayr, M. Danelljan, R. Timofte, et al., “AIM 2019 Challenge on Real-World Image Super-Resolution: Methods and Results,” ICCV Workshops, 2019. source
- P. Wei, H. Lu, R. Timofte, et al., “AIM 2020 Challenge on Real Image Super-Resolution: Methods and Results,” ECCV Workshops, 2020. source
- Z. Chen, K. Liu, J. Gong, J. Wang, L. Sun, Z. Wu, R. Timofte, Y. Zhang et al., “NTIRE 2025 Challenge on Image Super-Resolution (×4): Methods and Results,” in Proc. IEEE/CVF CVPR Workshops, 2025, pp. 1525–1535. doi · arXiv
- Le Zhang, Ao Li, Qibin Hou, Ce Zhu, Yonina C. Eldar, “Deep-Learning-Empowered Super Resolution: A Comprehensive Survey and Future Prospects,” Proceedings of the IEEE, 2025. source
- W. Ren, R. Goyal, Z. Hu, T. T. Aumentado-Armstrong, I. Mohomed and A. Levinshtein, “Hallucination Score: Towards Mitigating Hallucinations in Generative Image Super-Resolution,” arXiv:2507.14367, 2025. arXiv
- Real-ESRGAN contributors, “Real-ESRGAN model and ×4-plus training configuration,” official source, accessed 2026-11-02. model · configuration
- D. P. Kingma, J. Ba, “Adam: A Method for Stochastic Optimization,” ICLR, 2015. source
- M. Bevilacqua, A. Roumy, C. Guillemot and M.-L. Alberi Morel, “Low-Complexity Single-Image Super-Resolution based on Nonnegative Neighbor Embedding,” in Proc. BMVC, 2012, pp. 135.1–135.10. doi
- R. Zeyde, M. Elad and M. Protter, “On Single Image Scale-Up Using Sparse-Representations,” in Curves and Surfaces, Lecture Notes in Computer Science, Springer, 2012, pp. 711–730. doi
- D. Martin, C. Fowlkes, D. Tal and J. Malik, “A Database of Human Segmented Natural Images and Its Application to Evaluating Segmentation Algorithms and Measuring Ecological Statistics,” in Proc. IEEE ICCV, 2001, vol. 2, pp. 416–423. doi
- J.-B. Huang, A. Singh and N. Ahuja, “Single Image Super-Resolution from Transformed Self-Exemplars,” in Proc. IEEE CVPR, 2015, pp. 5197–5206. doi · CVF
- J. Kim, J. K. Lee and K. M. Lee, “Accurate Image Super-Resolution Using Very Deep Convolutional Networks,” in Proc. IEEE CVPR, 2016, pp. 1646–1654. doi · arXiv
- C. Ledig, L. Theis, F. Huszár, J. Caballero, A. Cunningham, A. Acosta, A. Aitken, A. Tejani, J. Totz, Z. Wang and W. Shi, “Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network,” in Proc. IEEE CVPR, 2017, pp. 105–114. doi · arXiv
- R. Timofte, E. Agustsson, L. Van Gool, M.-H. Yang, L. Zhang et al., “NTIRE 2017 Challenge on Single Image Super-Resolution: Methods and Results,” in Proc. IEEE CVPR Workshops, 2017, pp. 1110–1121. doi · CVF
- Y. Matsui, K. Ito, Y. Aramaki, A. Fujimoto, T. Ogawa, T. Yamasaki and K. Aizawa, “Sketch-Based Manga Retrieval Using Manga109 Dataset,” Multimedia Tools and Applications, vol. 76, no. 20, pp. 21811–21838, 2017. doi
- KernelGAN contributors, “Adversarial losses and kernel constraints,” official source, accessed 2026-11-02. loss definitions · alternating updates
- X. Mao, Q. Li, H. Xie, R. Y. K. Lau, Z. Wang, S. P. Smolley, “Least Squares Generative Adversarial Networks,” ICCV, 2017. source
- DASR contributors, “MoCo logits and contrastive cross-entropy implementation,” official DASR source, commit
51524af8021c94a502ee002e135867a1b75dc7d0, accessed 2026-11-02. encoder · loss - Y. Zhang, K. Li, K. Li, L. Wang, B. Zhong and Y. Fu, “Image Super-Resolution Using Very Deep Residual Channel Attention Networks,” in Proc. ECCV, 2018, pp. 294–310. doi · arXiv
- K. Simonyan and A. Zisserman, “Very Deep Convolutional Networks for Large-Scale Image Recognition,” in Proc. ICLR, 2015. arXiv
- Y. Zhang, X. Huang, J. Ma, et al., “Recognize Anything: A Strong Image Tagging Model,” CVPR Workshops, 2024. source
- E. J. Hu, Y. Shen, P. Wallis, Z. Allen-Zhu, Y. Li, S. Wang, L. Wang, W. Chen, “LoRA: Low-Rank Adaptation of Large Language Models,” ICLR, 2022. source
- D. Podell, Z. English, K. Lacey, A. Blattmann, T. Dockhorn, J. Müller, J. Penna, R. Rombach, “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. source
- H. Liu, C. Li, Q. Wu, Y. J. Lee, “Visual Instruction Tuning,” NeurIPS, 2023. source
- T. Karras, M. Aittala, T. Aila, S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. source