DDPM — noise prediction and the quality–likelihood tradeoff
Optional · paper guide 1 of 6 for ML 08 · Diffusion Models and Flow Matching. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
On this page
- DDPM — noise prediction and the quality–likelihood tradeoff
- Flow Matching — regress a velocity, then integrate it
- MeanFlow — average velocity over an interval
- Improved MeanFlow — prediction inputs and flexible guidance
- JiT — clean-image prediction in pixel space
- Pixel MeanFlow — one-step pixels through a denoised field
Machine Learning
Question and thesis
Can a model generate realistic images by learning to reverse a gradual corruption process? Ho, Jain and Abbeel connect diffusion training with denoising and show that a simplified noise-prediction objective produces strong samples [3]. Read Gaussian noise, conditional probability and the variational-bound idea first. The paper’s sample-quality result must be separated from its likelihood-bound result.
Method and figure
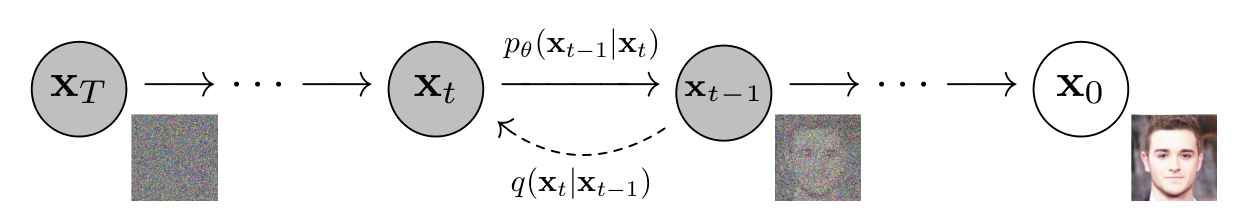
Figure 2 distinguishes the fixed forward chain from the learned reverse chain. Training can sample a noisy state directly:
Here is a data sample, is a uniformly sampled training step, is standard Gaussian noise, and is the learned noise predictor. The schedule defines and , where is forward noise variance at step . averages squared prediction error over these draws.
Generation starts from Gaussian noise and repeatedly uses the predicted noise to form reverse transitions. Predicting noise is a parameterization of those transitions; it is not a claim that one forward network call reconstructs every clean image exactly.
Evidence
Table 1 makes a useful controlled reading exercise on unconditional CIFAR-10. The fixed-variance model trained with the full variational bound reports FID 13.51 and a negative-log-likelihood bound of at most 3.70 bits/dim. The simplified objective reports FID 3.17 and a bound of at most 3.75 bits/dim. Thus better reported sample quality accompanies a worse reported likelihood bound. The bound is not an exact negative log likelihood, and these two measurements answer different questions.
Design analysis
Changing the weighting across noise levels changes which errors receive training emphasis. Table 2 further compares parameterizations and variance choices; unstable configurations matter as evidence, not merely the best row. This supports studying the objective and reverse-process design together. It does not establish that the same ranking holds under every schedule, dataset or sampling budget.
Reading checkpoint
At a late forward step, identify which term in the noisy-state equation carries the data signal. Then explain why a lower noise-prediction training loss, a lower FID and a tighter likelihood bound need not improve in lockstep. State the evaluation protocol before comparing scores from different papers.
Limits and next step
The original reverse chain requires many sequential evaluations. This paper is not yet a latent text-to-image system, and later guidance or fast-sampling features should not be attributed to it. Continue to flow matching: compare stochastic reverse transitions with learning a continuous velocity field, paying attention to both training cost and numerical sampling cost.
Continue reading: Flow Matching — regress a velocity, then integrate it
References
- L. Yang, Z. Zhang, Y. Song, S. Hong, R. Xu, Y. Zhao, W. Zhang, B. Cui and M.-H. Yang, “Diffusion Models: A Comprehensive Survey of Methods and Applications,” ACM Computing Surveys, 2023. arXiv
- Y. Lipman, M. Havasi, P. Holderrieth, N. Shaul, M. Le, B. Karrer, R. T. Q. Chen, D. Lopez-Paz, H. Ben-Hamu and I. Gat, “Flow Matching Guide and Code,” arXiv:2412.06264, 2024. arXiv
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. arXiv
- Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon and B. Poole, “Score-Based Generative Modeling through Stochastic Differential Equations,” ICLR, 2021. arXiv
- J. Song, C. Meng and S. Ermon, “Denoising Diffusion Implicit Models,” ICLR, 2021. arXiv
- J. Ho and T. Salimans, “Classifier-Free Diffusion Guidance,” NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications; arXiv:2207.12598, 2022. arXiv
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. arXiv
- W. Peebles and S. Xie, “Scalable Diffusion Models with Transformers,” ICCV, 2023. arXiv
- P. Esser, S. Kulal, A. Blattmann et al., “Scaling Rectified Flow Transformers for High-Resolution Image Synthesis,” ICML, PMLR 235, 2024. PMLR
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” ICLR, 2023. arXiv
- Y. Song, P. Dhariwal, M. Chen and I. Sutskever, “Consistency Models,” ICML, 2023. arXiv
- Z. Geng, M. Deng, X. Bai, J. Z. Kolter and K. He, “Mean Flows for One-step Generative Modeling,” NeurIPS, 2025. arXiv
- S. J. D. Prince, Understanding Deep Learning, MIT Press, 2023. book site
- J. Sohl-Dickstein, E. Weiss, N. Maheswaranathan and S. Ganguli, “Deep Unsupervised Learning using Nonequilibrium Thermodynamics,” ICML, PMLR 37, 2015. PMLR
- P. Vincent, “A Connection Between Score Matching and Denoising Autoencoders,” Neural Computation, vol. 23, no. 7, pp. 1661–1674, 2011. doi
- Y. Song and S. Ermon, “Generative Modeling by Estimating Gradients of the Data Distribution,” NeurIPS, 2019. arXiv
- P. Dhariwal and A. Nichol, “Diffusion Models Beat GANs on Image Synthesis,” NeurIPS, 2021. NeurIPS
- A. Q. Nichol and P. Dhariwal, “Improved Denoising Diffusion Probabilistic Models,” ICML, PMLR 139, 2021. PMLR
- T. Karras, M. Aittala, T. Aila and S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. arXiv
- C. Lu, Y. Zhou, F. Bao, J. Chen, C. Li and J. Zhu, “DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps,” NeurIPS, 2022. arXiv
- T. Salimans and J. Ho, “Progressive Distillation for Fast Sampling of Diffusion Models,” ICLR, 2022. arXiv
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler and S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS (NIPS), 2017. arXiv
- T. Kynkäänniemi, T. Karras, S. Laine, J. Lehtinen and T. Aila, “Improved Precision and Recall Metric for Assessing Generative Models,” NeurIPS, 2019. arXiv
- G. Stein, J. C. Cresswell, R. Hosseinzadeh et al., “Exposing Flaws of Generative Model Evaluation Metrics and Their Unfair Treatment of Diffusion Models,” NeurIPS, 2023. arXiv
- S. Jayasumana, S. Ramalingam, A. Veit, D. Glasner, A. Chakrabarti and S. Kumar, “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. CVF
- F.-A. Croitoru, V. Hondru, R. T. Ionescu and M. Shah, “Diffusion Models in Vision: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023. doi
- H. Cao, C. Tan, Z. Gao, Y. Xu, G. Chen, P.-A. Heng and S. Z. Li, “A Survey on Generative Diffusion Models,” IEEE Transactions on Knowledge and Data Engineering, vol. 36, no. 7, pp. 2814–2830, 2024. doi
- C.-H. Lai, Y. Song, D. Kim, Y. Mitsufuji and S. Ermon, “The Principles of Diffusion Models,” monograph, arXiv:2510.21890, 2025. arXiv
- H. Shen, J. Zhang, B. Xiong et al., “Efficient Diffusion Models: A Survey,” Transactions on Machine Learning Research, 2025. arXiv
- A. Melnik, M. Ljubljanac, C. Lu, Q. Yan, W. Ren and H. Ritter, “Video Diffusion Models: A Survey,” Transactions on Machine Learning Research, 2024. arXiv
- C. Lu and Y. Song, “Simplifying, Stabilizing and Scaling Continuous-Time Consistency Models,” ICLR, 2025. arXiv
- A. Sauer, D. Lorenz, A. Blattmann and R. Rombach, “Adversarial Diffusion Distillation,” ECCV, 2024. arXiv
- M. S. Albergo and E. Vanden-Eijnden, “Building Normalizing Flows with Stochastic Interpolants,” ICLR, 2023. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A Large-Scale Hierarchical Image Database,” CVPR, 2009, pp. 248–255. doi
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens and Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” CVPR, 2016, pp. 2818–2826. arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” MICCAI, LNCS 9351, pp. 234–241, 2015. arXiv
- A. Radford, J. W. Kim, C. Hallacy et al., “Learning Transferable Visual Models From Natural Language Supervision,” ICML, 2021. arXiv
- M. Oquab, T. Darcet, T. Moutakanni et al., “DINOv2: Learning Robust Visual Features without Supervision,” Transactions on Machine Learning Research, 2024. arXiv
- B. Efron, “Tweedie’s Formula and Selection Bias,” Journal of the American Statistical Association, vol. 106, no. 496, pp. 1602–1614, 2011. doi
- A. Dosovitskiy, L. Beyer, A. Kolesnikov et al., “An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale,” ICLR, 2021. arXiv
- T. Li and K. He, “Back to Basics: Let Denoising Generative Models Denoise,” CVPR, 2026 (preprint 2025). paper, publication record, official JiT code.
- B. Zheng, N. Ma, S. Tong and S. Xie, “Diffusion Transformers with Representation Autoencoders,” ICLR, 2026 (preprint 2025). proceedings, manuscript.
- S. Tong, B. Zheng, Z. Wang, B. Tang, N. Ma, E. Brown, J. Yang, R. Fergus, Y. LeCun and S. Xie, “Scaling Text-to-Image Diffusion Transformers with Representation Autoencoders,” CVPR Findings Track, 2026. manuscript, author publication record.
- D. Podell, Z. English, K. Lacey, A. Blattmann, T. Dockhorn, J. Müller, J. Penna and R. Rombach, “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. proceedings, official model card.
- Black Forest Labs, “FLUX.1 [dev],” official pretrained-model card, 2024. model card.
- W. Kong, Q. Tian, Z. Zhang et al., “HunyuanVideo: A Systematic Framework For Large Video Generative Models,” technical report, arXiv:2412.03603, 2024. report, official release.
- Team Wan, A. Wang, B. Ai, B. Wen et al., “Wan: Open and Advanced Large-Scale Video Generative Models,” technical report, arXiv:2503.20314, 2025. report, official Wan2.1 release.
- Z. Geng, Y. Lu, Z. Wu, E. Shechtman, J. Z. Kolter and K. He, “Improved Mean Flows: On the Challenges of Fastforward Generative Models,” CVPR, pp. 30467–30476, 2026. CVF
- Y. Lu, S. Lu, Q. Sun, H. Zhao, Z. Jiang, X. Wang, T. Li, Z. Geng and K. He, “One-step Latent-free Image Generation with Pixel Mean Flows,” ICML, PMLR 306, pp. 81265–81277, 2026. PMLR