DDPM:雜訊預測與品質、概似之間的取捨
選讀・ML 08・擴散模型與流匹配 的論文導讀(第 1/6 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
問題與論點
模型能否學會逆轉逐步破壞流程,藉此生成逼真影像?Ho、Jain 與 Abbeel 將擴散訓練連到去雜訊,並顯示簡化雜訊預測目標能產生良好樣本 [3]。先讀高斯雜訊、條件機率與變分下界。論文的樣本品質結果,必須與概似界限結果分開。
方法與圖解
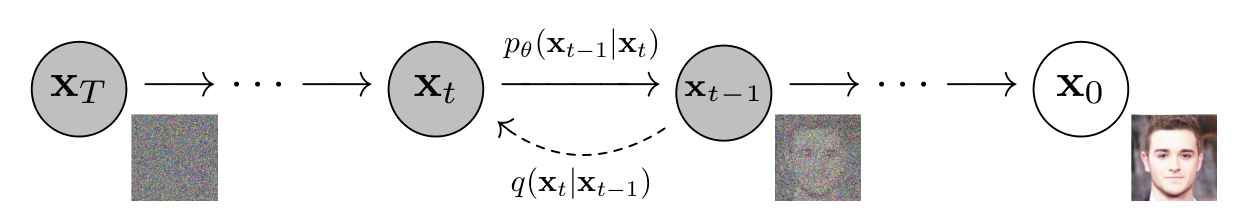
圖 2 區分固定前向鏈與可學習反向鏈。訓練可直接抽出帶雜訊狀態:
其中 為資料樣本, 為均勻抽取的訓練步, 為標準高斯雜訊, 為可學習雜訊預測器。排程定義 、,其中 為第 步前向雜訊變異數。 對這些抽樣的平方預測誤差取平均。
生成從高斯雜訊開始,反覆用預測雜訊形成反向轉移。預測雜訊是轉移的參數化方式,不代表一次網路前向就能精確重建每張乾淨影像。
證據
表 1 的無條件 CIFAR-10 結果適合練習控制條件閱讀。固定變異數、以完整變分界限訓練的模型,FID 為 13.51,負對數概似上界為 3.70 bits/dim;簡化目標則是 FID 3.17、上界 3.75 bits/dim。因此,報告的樣本品質改善,伴隨較差的概似上界。界限並非精確負對數概似,兩種量測回答不同問題。
設計分析
改變各雜訊程度的權重,會改變訓練強調哪些錯誤。表 2 進一步比較參數化及變異數選項;不穩定設定也是證據,不能只讀最佳一列。這支持一起研究目標與反向流程設計,卻不保證所有排程、資料集或取樣預算下的排序相同。
閱讀檢查點
在較晚的前向步驟,指出帶雜訊狀態式的哪一項仍攜帶資料訊號。再解釋為何更低的雜訊預測訓練損失、更低 FID 與更緊概似界限,不必同步改善。跨論文比分數以前,先說清楚評估協定。
限制與下一步
原始反向鏈需要多次循序計算。這篇還不是潛在文字生成影像系統,不能把後來的引導或快速取樣功能歸給它。接著讀 flow matching,比較隨機反向轉移與連續速度場學習,同時注意訓練成本及數值取樣成本。
接著閱讀: Flow Matching:先迴歸速度,再積分生成
參考文獻
- L. Yang, Z. Zhang, Y. Song, S. Hong, R. Xu, Y. Zhao, W. Zhang, B. Cui and M.-H. Yang, “Diffusion Models: A Comprehensive Survey of Methods and Applications,” ACM Computing Surveys, 2023. arXiv
- Y. Lipman, M. Havasi, P. Holderrieth, N. Shaul, M. Le, B. Karrer, R. T. Q. Chen, D. Lopez-Paz, H. Ben-Hamu and I. Gat, “Flow Matching Guide and Code,” arXiv:2412.06264, 2024. arXiv
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. arXiv
- Y. Song, J. Sohl-Dickstein, D. P. Kingma, A. Kumar, S. Ermon and B. Poole, “Score-Based Generative Modeling through Stochastic Differential Equations,” ICLR, 2021. arXiv
- J. Song, C. Meng and S. Ermon, “Denoising Diffusion Implicit Models,” ICLR, 2021. arXiv
- J. Ho and T. Salimans, “Classifier-Free Diffusion Guidance,” NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications; arXiv:2207.12598, 2022. arXiv
- R. Rombach, A. Blattmann, D. Lorenz, P. Esser and B. Ommer, “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. arXiv
- W. Peebles and S. Xie, “Scalable Diffusion Models with Transformers,” ICCV, 2023. arXiv
- P. Esser, S. Kulal, A. Blattmann et al., “Scaling Rectified Flow Transformers for High-Resolution Image Synthesis,” ICML, PMLR 235, 2024. PMLR
- Y. Lipman, R. T. Q. Chen, H. Ben-Hamu, M. Nickel and M. Le, “Flow Matching for Generative Modeling,” ICLR, 2023. arXiv
- X. Liu, C. Gong and Q. Liu, “Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow,” ICLR, 2023. arXiv
- Y. Song, P. Dhariwal, M. Chen and I. Sutskever, “Consistency Models,” ICML, 2023. arXiv
- Z. Geng, M. Deng, X. Bai, J. Z. Kolter and K. He, “Mean Flows for One-step Generative Modeling,” NeurIPS, 2025. arXiv
- S. J. D. Prince, Understanding Deep Learning, MIT Press, 2023. book site
- J. Sohl-Dickstein, E. Weiss, N. Maheswaranathan and S. Ganguli, “Deep Unsupervised Learning using Nonequilibrium Thermodynamics,” ICML, PMLR 37, 2015. PMLR
- P. Vincent, “A Connection Between Score Matching and Denoising Autoencoders,” Neural Computation, vol. 23, no. 7, pp. 1661–1674, 2011. doi
- Y. Song and S. Ermon, “Generative Modeling by Estimating Gradients of the Data Distribution,” NeurIPS, 2019. arXiv
- P. Dhariwal and A. Nichol, “Diffusion Models Beat GANs on Image Synthesis,” NeurIPS, 2021. NeurIPS
- A. Q. Nichol and P. Dhariwal, “Improved Denoising Diffusion Probabilistic Models,” ICML, PMLR 139, 2021. PMLR
- T. Karras, M. Aittala, T. Aila and S. Laine, “Elucidating the Design Space of Diffusion-Based Generative Models,” NeurIPS, 2022. arXiv
- C. Lu, Y. Zhou, F. Bao, J. Chen, C. Li and J. Zhu, “DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps,” NeurIPS, 2022. arXiv
- T. Salimans and J. Ho, “Progressive Distillation for Fast Sampling of Diffusion Models,” ICLR, 2022. arXiv
- M. Heusel, H. Ramsauer, T. Unterthiner, B. Nessler and S. Hochreiter, “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS (NIPS), 2017. arXiv
- T. Kynkäänniemi, T. Karras, S. Laine, J. Lehtinen and T. Aila, “Improved Precision and Recall Metric for Assessing Generative Models,” NeurIPS, 2019. arXiv
- G. Stein, J. C. Cresswell, R. Hosseinzadeh et al., “Exposing Flaws of Generative Model Evaluation Metrics and Their Unfair Treatment of Diffusion Models,” NeurIPS, 2023. arXiv
- S. Jayasumana, S. Ramalingam, A. Veit, D. Glasner, A. Chakrabarti and S. Kumar, “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. CVF
- F.-A. Croitoru, V. Hondru, R. T. Ionescu and M. Shah, “Diffusion Models in Vision: A Survey,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2023. doi
- H. Cao, C. Tan, Z. Gao, Y. Xu, G. Chen, P.-A. Heng and S. Z. Li, “A Survey on Generative Diffusion Models,” IEEE Transactions on Knowledge and Data Engineering, vol. 36, no. 7, pp. 2814–2830, 2024. doi
- C.-H. Lai, Y. Song, D. Kim, Y. Mitsufuji and S. Ermon, “The Principles of Diffusion Models,” monograph, arXiv:2510.21890, 2025. arXiv
- H. Shen, J. Zhang, B. Xiong et al., “Efficient Diffusion Models: A Survey,” Transactions on Machine Learning Research, 2025. arXiv
- A. Melnik, M. Ljubljanac, C. Lu, Q. Yan, W. Ren and H. Ritter, “Video Diffusion Models: A Survey,” Transactions on Machine Learning Research, 2024. arXiv
- C. Lu and Y. Song, “Simplifying, Stabilizing and Scaling Continuous-Time Consistency Models,” ICLR, 2025. arXiv
- A. Sauer, D. Lorenz, A. Blattmann and R. Rombach, “Adversarial Diffusion Distillation,” ECCV, 2024. arXiv
- M. S. Albergo and E. Vanden-Eijnden, “Building Normalizing Flows with Stochastic Interpolants,” ICLR, 2023. arXiv
- J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li and L. Fei-Fei, “ImageNet: A Large-Scale Hierarchical Image Database,” CVPR, 2009, pp. 248–255. doi
- C. Szegedy, V. Vanhoucke, S. Ioffe, J. Shlens and Z. Wojna, “Rethinking the Inception Architecture for Computer Vision,” CVPR, 2016, pp. 2818–2826. arXiv
- O. Ronneberger, P. Fischer and T. Brox, “U-Net: Convolutional Networks for Biomedical Image Segmentation,” MICCAI, LNCS 9351, pp. 234–241, 2015. arXiv
- A. Radford, J. W. Kim, C. Hallacy et al., “Learning Transferable Visual Models From Natural Language Supervision,” ICML, 2021. arXiv
- M. Oquab, T. Darcet, T. Moutakanni et al., “DINOv2: Learning Robust Visual Features without Supervision,” Transactions on Machine Learning Research, 2024. arXiv
- B. Efron, “Tweedie’s Formula and Selection Bias,” Journal of the American Statistical Association, vol. 106, no. 496, pp. 1602–1614, 2011. doi
- A. Dosovitskiy, L. Beyer, A. Kolesnikov et al., “An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale,” ICLR, 2021. arXiv
- T. Li and K. He, “Back to Basics: Let Denoising Generative Models Denoise,” CVPR, 2026 (preprint 2025). paper, publication record, official JiT code.
- B. Zheng, N. Ma, S. Tong and S. Xie, “Diffusion Transformers with Representation Autoencoders,” ICLR, 2026 (preprint 2025). proceedings, manuscript.
- S. Tong, B. Zheng, Z. Wang, B. Tang, N. Ma, E. Brown, J. Yang, R. Fergus, Y. LeCun and S. Xie, “Scaling Text-to-Image Diffusion Transformers with Representation Autoencoders,” CVPR Findings Track, 2026. manuscript, author publication record.
- D. Podell, Z. English, K. Lacey, A. Blattmann, T. Dockhorn, J. Müller, J. Penna and R. Rombach, “SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis,” ICLR, 2024. proceedings, official model card.
- Black Forest Labs, “FLUX.1 [dev],” official pretrained-model card, 2024. model card.
- W. Kong, Q. Tian, Z. Zhang et al., “HunyuanVideo: A Systematic Framework For Large Video Generative Models,” technical report, arXiv:2412.03603, 2024. report, official release.
- Team Wan, A. Wang, B. Ai, B. Wen et al., “Wan: Open and Advanced Large-Scale Video Generative Models,” technical report, arXiv:2503.20314, 2025. report, official Wan2.1 release.
- Z. Geng, Y. Lu, Z. Wu, E. Shechtman, J. Z. Kolter and K. He, “Improved Mean Flows: On the Challenges of Fastforward Generative Models,” CVPR, pp. 30467–30476, 2026. CVF
- Y. Lu, S. Lu, Q. Sun, H. Zhao, Z. Jiang, X. Wang, T. Li, Z. Geng and K. He, “One-step Latent-free Image Generation with Pixel Mean Flows,” ICML, PMLR 306, pp. 81265–81277, 2026. PMLR