GAN — a distribution game and its idealized guarantee
Optional · paper guide 2 of 2 for ML 07 · Generative Models: Autoencoders, VAEs, GANs and Flows. Citation numbers refer to the reference list at the bottom of this page.
Navigate: this page and this track: Navigate: this page and this track
Question and thesis
Can a generator learn by competing with a classifier instead of specifying a tractable observation likelihood? Goodfellow et al. introduce a game in which a discriminator separates real from generated samples and a generator tries to defeat it [11]. Read binary cross-entropy and probability densities first. The paper combines an idealized distribution argument with finite neural-network experiments; these must be evaluated separately.
Method and figure
The original objective is
Here is a real observation drawn from data distribution , is noise from prior , maps noise to a synthetic observation, and predicts the probability that an input is real. is the adversarial objective. Alternating updates train the two networks. The paper also recommends maximizing for the generator early in training to avoid weak gradients from the saturating form.
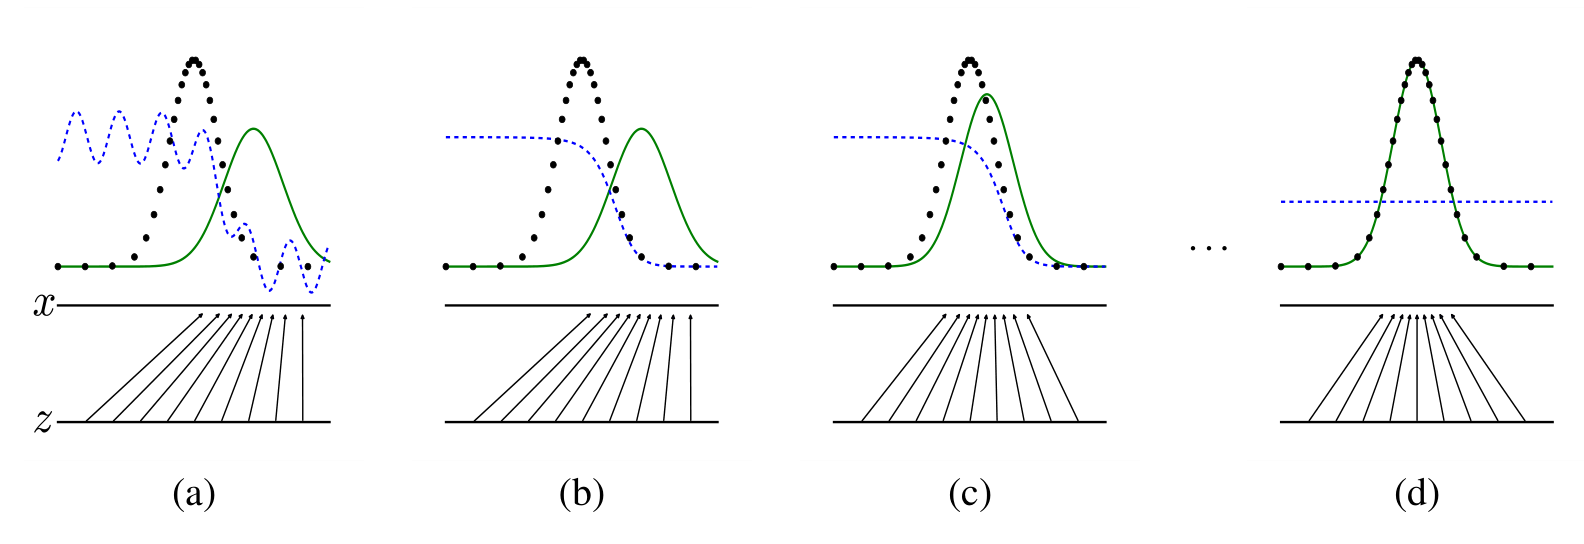
Figure 1 follows schematic densities and the decision function. With an optimal discriminator, , where is the generator’s induced density. Under the ideal assumptions, matching distributions is the global solution. The figure is not evidence that every practical optimizer reaches it.
Evidence
The experiments show generated samples and quantitative comparisons using a Parzen-window density estimate fitted to generated samples. Table 1 therefore reports a surrogate evaluation, not the exact likelihood of the implicit generator. Kernel bandwidth and estimation behavior affect that comparison. Figure 2 includes nearest training examples as a useful visual check, but a few nearest neighbors cannot establish that an entire model never memorizes.
Design analysis
The discriminator learns a task-specific signal instead of using a fixed reconstruction distance. That is useful, but also means the generator’s objective changes as its opponent changes. The theoretical optimum assumes sufficient distributional flexibility and appropriate discriminator optimization. It does not prove convergence of finite networks trained by alternating minibatch updates. Keep the optimum’s existence separate from an algorithm’s ability to find it.
Reading checkpoint
If real and generated densities agree everywhere they have support, compute the optimal discriminator output. Explain why an observed discriminator accuracy near chance alone is insufficient to demonstrate this ideal state: a weak or poorly trained discriminator can also fail to distinguish inputs.
Limits and next step
Training imbalance and missing modes can coexist with visually plausible samples. Inspect coverage as well as sample quality, and avoid comparing surrogate density scores as if they were exact log likelihoods. Next read DDPM in ML 08: contrast a learned adversarial signal with an explicit noise-prediction objective and a multi-step sampling procedure.
Continue reading: DDPM — noise prediction and the quality–likelihood tradeoff
References
- C. M. Bishop and H. Bishop, Deep Learning: Foundations and Concepts, Springer, 2024. Book
- S. J. D. Prince, Understanding Deep Learning, MIT Press, 2023. Book and notebooks
- S. Bond-Taylor, A. Leach, Y. Long and C. G. Willcocks, “Deep Generative Modelling: A Comparative Review of VAEs, GANs, Normalizing Flows, Energy-Based and Autoregressive Models,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022. Paper
- G. Papamakarios et al., “Normalizing Flows for Probabilistic Modeling and Inference,” JMLR, 2021. Review
- L. Theis, A. van den Oord and M. Bethge, “A note on the evaluation of generative models,” ICLR, 2016. Paper
- D. P. Kingma and M. Welling, “Auto-Encoding Variational Bayes,” ICLR, 2014. Paper
- S. R. Bowman et al., “Generating Sentences from a Continuous Space,” CoNLL, 2016. Paper
- I. Higgins et al., “β-VAE: Learning Basic Visual Concepts with a Constrained Variational Framework,” ICLR, 2017. Paper
- D. P. Kingma and M. Welling, “An Introduction to Variational Autoencoders,” Foundations and Trends in Machine Learning, 2019. Review
- A. Vahdat and J. Kautz, “NVAE: A Deep Hierarchical Variational Autoencoder,” NeurIPS, 2020. Paper
- I. Goodfellow et al., “Generative Adversarial Nets,” NeurIPS, 2014. Paper
- T. Salimans et al., “Improved Techniques for Training GANs,” NeurIPS, 2016. Paper
- M. Arjovsky, S. Chintala and L. Bottou, “Wasserstein GAN,” ICML, 2017. Paper
- I. Gulrajani et al., “Improved Training of Wasserstein GANs,” NeurIPS, 2017. Paper
- T. Miyato et al., “Spectral Normalization for Generative Adversarial Networks,” ICLR, 2018. Paper
- L. Mescheder, A. Geiger and S. Nowozin, “Which Training Methods for GANs do actually Converge?” ICML, 2018. Paper
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” CVPR, 2019. Paper
- L. Dinh, J. Sohl-Dickstein and S. Bengio, “Density estimation using Real NVP,” ICLR, 2017. Paper
- D. P. Kingma and P. Dhariwal, “Glow: Generative Flow with Invertible 1x1 Convolutions,” NeurIPS, 2018. Paper
- D. J. Rezende and S. Mohamed, “Variational Inference with Normalizing Flows,” ICML, 2015. Paper
- R. T. Q. Chen, Y. Rubanova, J. Bettencourt and D. Duvenaud, “Neural Ordinary Differential Equations,” NeurIPS, 2018. Paper
- Y. Lipman et al., “Flow Matching for Generative Modeling,” ICLR, 2023. Paper
- I. Goodfellow, Y. Bengio and A. Courville, Deep Learning, MIT Press, 2016, ch. 18–20. Book
- Y. Song and D. P. Kingma, “How to Train Your Energy-Based Models,” arXiv, 2021. Paper
- A. van den Oord, N. Kalchbrenner and K. Kavukcuoglu, “Pixel Recurrent Neural Networks,” ICML, 2016. Paper
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. Paper
- L. Yang et al., “Diffusion Models: A Comprehensive Survey of Methods and Applications,” ACM Computing Surveys, 2023. Survey
- E. Nalisnick et al., “Do Deep Generative Models Know What They Don’t Know?” ICLR, 2019. Paper
- M. Heusel et al., “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. Paper
- M. S. M. Sajjadi, O. Bachem, M. Lucic, O. Bousquet and S. Gelly, “Assessing Generative Models via Precision and Recall,” NeurIPS, 2018. Paper
- T. Kynkäänniemi, T. Karras, S. Laine, J. Lehtinen and T. Aila, “Improved Precision and Recall Metric for Assessing Generative Models,” NeurIPS, 2019. Paper
- G. Stein et al., “Exposing flaws of generative model evaluation metrics and their unfair treatment of diffusion models,” NeurIPS, 2023. Paper
- S. Jayasumana et al., “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. Paper
- A. van den Oord, O. Vinyals and K. Kavukcuoglu, “Neural Discrete Representation Learning,” NeurIPS, 2017. Paper
- R. Rombach et al., “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. Paper
- M. Kang et al., “Scaling up GANs for Text-to-Image Synthesis,” CVPR, 2023. Paper
- Y. Huang, A. Gokaslan, V. Kuleshov and J. Tompkin, “The GAN is dead; long live the GAN! A Modern GAN Baseline,” NeurIPS, 2024. Paper