GAN:分布賽局與理想條件下的保證
選讀・ML 07・生成模型:自編碼器、VAE、GAN 與正規化流 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
問題與論點
生成器能否透過與分類器競爭學習,而不必指定可計算的觀測概似?Goodfellow 等人提出賽局:判別器區分真實與生成樣本,生成器則試著讓它判錯 [11]。先讀二元交叉熵與機率密度。論文同時包含理想化分布論證及有限神經網路實驗,兩者應分開評估。
方法與圖解
原始目標為
其中 為資料分布 的真實觀測, 為先驗 的雜訊, 將雜訊映成合成觀測, 預測輸入為真的機率, 為對抗目標。兩網路交替更新。論文也建議在早期讓生成器最大化 ,避免飽和形式提供過弱梯度。
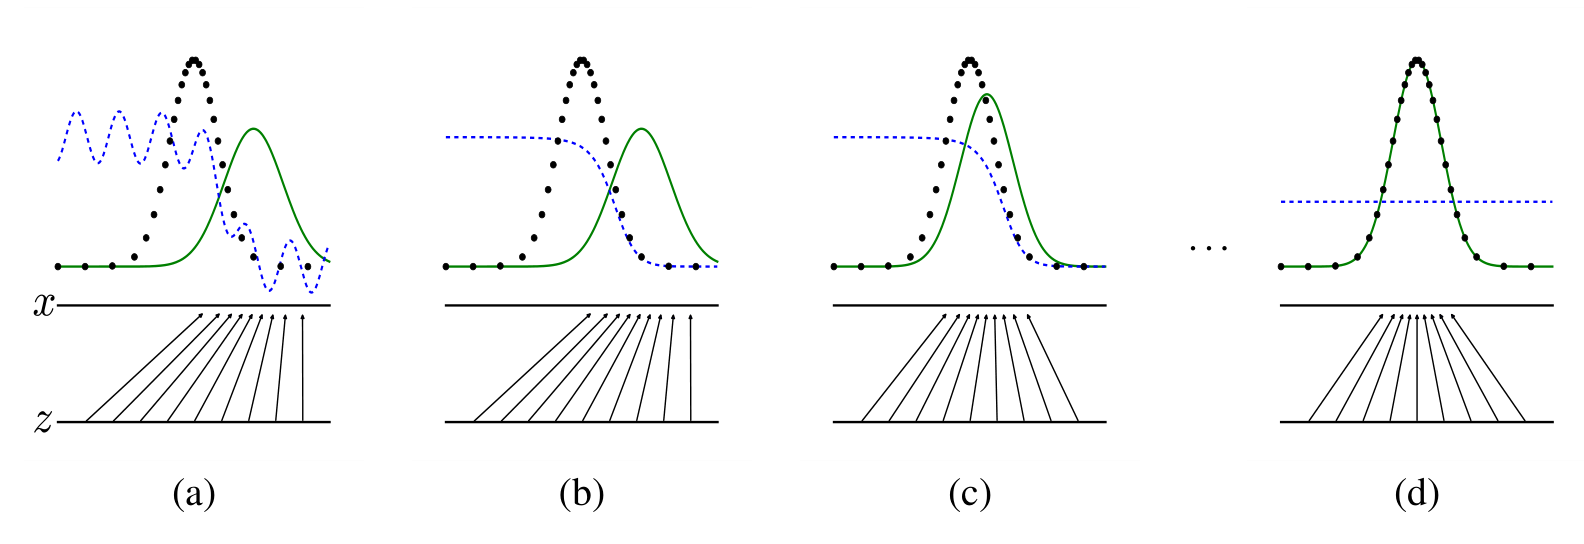
圖 1 追蹤示意密度與決策函數。最優判別器為 ,其中 為生成器誘發的密度。理想假設下,分布匹配是全域解;原圖並非每種實際最佳化器都會到達該解的證據。
證據
實驗展示生成樣本,並以生成樣本擬合 Parzen-window 密度估計做量化比較。因此表 1 是替代評估,不是隱式生成器的精確概似。核頻寬與估計器行為都會影響結果。圖 2 附最近訓練範例作為視覺檢查,但少數最近鄰無法證明整個模型從不記憶資料。
設計分析
判別器學習任務相關訊號,而非使用固定重建距離;這也表示對手改變時,生成器的目標跟著改變。理論最優解假設充分的分布彈性與適當的判別器最佳化,並未證明有限網路採交替小批次更新必然收斂。最優解存在,與演算法能找到它,是不同問題。
閱讀檢查點
若真實與生成密度在支撐集上處處相等,最優判別器輸出多少?再解釋為何觀察到判別準確度接近隨機,還不足以證明這個理想狀態:能力不足或訓練不佳的判別器也可能分不出輸入。
限制與下一步
看似合理的樣本仍可能伴隨訓練失衡或模式遺漏。除了樣本品質,也要檢查涵蓋範圍;不可把替代密度分數當成精確對數概似比較。接著讀 ML 08 的 DDPM,對照可學習對抗訊號與明確雜訊預測目標,以及多步取樣程序。
接著閱讀: DDPM:雜訊預測與品質、概似之間的取捨
參考文獻
- C. M. Bishop and H. Bishop, Deep Learning: Foundations and Concepts, Springer, 2024. Book
- S. J. D. Prince, Understanding Deep Learning, MIT Press, 2023. Book and notebooks
- S. Bond-Taylor, A. Leach, Y. Long and C. G. Willcocks, “Deep Generative Modelling: A Comparative Review of VAEs, GANs, Normalizing Flows, Energy-Based and Autoregressive Models,” IEEE Transactions on Pattern Analysis and Machine Intelligence, 2022. Paper
- G. Papamakarios et al., “Normalizing Flows for Probabilistic Modeling and Inference,” JMLR, 2021. Review
- L. Theis, A. van den Oord and M. Bethge, “A note on the evaluation of generative models,” ICLR, 2016. Paper
- D. P. Kingma and M. Welling, “Auto-Encoding Variational Bayes,” ICLR, 2014. Paper
- S. R. Bowman et al., “Generating Sentences from a Continuous Space,” CoNLL, 2016. Paper
- I. Higgins et al., “β-VAE: Learning Basic Visual Concepts with a Constrained Variational Framework,” ICLR, 2017. Paper
- D. P. Kingma and M. Welling, “An Introduction to Variational Autoencoders,” Foundations and Trends in Machine Learning, 2019. Review
- A. Vahdat and J. Kautz, “NVAE: A Deep Hierarchical Variational Autoencoder,” NeurIPS, 2020. Paper
- I. Goodfellow et al., “Generative Adversarial Nets,” NeurIPS, 2014. Paper
- T. Salimans et al., “Improved Techniques for Training GANs,” NeurIPS, 2016. Paper
- M. Arjovsky, S. Chintala and L. Bottou, “Wasserstein GAN,” ICML, 2017. Paper
- I. Gulrajani et al., “Improved Training of Wasserstein GANs,” NeurIPS, 2017. Paper
- T. Miyato et al., “Spectral Normalization for Generative Adversarial Networks,” ICLR, 2018. Paper
- L. Mescheder, A. Geiger and S. Nowozin, “Which Training Methods for GANs do actually Converge?” ICML, 2018. Paper
- T. Karras, S. Laine and T. Aila, “A Style-Based Generator Architecture for Generative Adversarial Networks,” CVPR, 2019. Paper
- L. Dinh, J. Sohl-Dickstein and S. Bengio, “Density estimation using Real NVP,” ICLR, 2017. Paper
- D. P. Kingma and P. Dhariwal, “Glow: Generative Flow with Invertible 1x1 Convolutions,” NeurIPS, 2018. Paper
- D. J. Rezende and S. Mohamed, “Variational Inference with Normalizing Flows,” ICML, 2015. Paper
- R. T. Q. Chen, Y. Rubanova, J. Bettencourt and D. Duvenaud, “Neural Ordinary Differential Equations,” NeurIPS, 2018. Paper
- Y. Lipman et al., “Flow Matching for Generative Modeling,” ICLR, 2023. Paper
- I. Goodfellow, Y. Bengio and A. Courville, Deep Learning, MIT Press, 2016, ch. 18–20. Book
- Y. Song and D. P. Kingma, “How to Train Your Energy-Based Models,” arXiv, 2021. Paper
- A. van den Oord, N. Kalchbrenner and K. Kavukcuoglu, “Pixel Recurrent Neural Networks,” ICML, 2016. Paper
- J. Ho, A. Jain and P. Abbeel, “Denoising Diffusion Probabilistic Models,” NeurIPS, 2020. Paper
- L. Yang et al., “Diffusion Models: A Comprehensive Survey of Methods and Applications,” ACM Computing Surveys, 2023. Survey
- E. Nalisnick et al., “Do Deep Generative Models Know What They Don’t Know?” ICLR, 2019. Paper
- M. Heusel et al., “GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium,” NeurIPS, 2017. Paper
- M. S. M. Sajjadi, O. Bachem, M. Lucic, O. Bousquet and S. Gelly, “Assessing Generative Models via Precision and Recall,” NeurIPS, 2018. Paper
- T. Kynkäänniemi, T. Karras, S. Laine, J. Lehtinen and T. Aila, “Improved Precision and Recall Metric for Assessing Generative Models,” NeurIPS, 2019. Paper
- G. Stein et al., “Exposing flaws of generative model evaluation metrics and their unfair treatment of diffusion models,” NeurIPS, 2023. Paper
- S. Jayasumana et al., “Rethinking FID: Towards a Better Evaluation Metric for Image Generation,” CVPR, 2024. Paper
- A. van den Oord, O. Vinyals and K. Kavukcuoglu, “Neural Discrete Representation Learning,” NeurIPS, 2017. Paper
- R. Rombach et al., “High-Resolution Image Synthesis with Latent Diffusion Models,” CVPR, 2022. Paper
- M. Kang et al., “Scaling up GANs for Text-to-Image Synthesis,” CVPR, 2023. Paper
- Y. Huang, A. Gokaslan, V. Kuleshov and J. Tompkin, “The GAN is dead; long live the GAN! A Modern GAN Baseline,” NeurIPS, 2024. Paper