GloVe — Global Vectors for Word Representation
選讀・NLP 04・詞彙語意與詞嵌入 的論文導讀(第 2/2 篇)。引用編號對應本頁底部的參考文獻。
導覽:本頁與本系列: 導覽:本頁與本系列
挑戰
預測式嵌入從局部視窗學習,計數方法則明確整理語料統計。Pennington、Socher 與 Manning 探討如何把全域共現資訊保留在可訓練的低維表示中 [10]。論點是共現機率的比值能揭露有用區別,進而提出對數計數的加權擬合。先讀本章的共現矩陣及 word2vec 導讀。
方法
先根據選定的上下文視窗建立詞—上下文共現矩陣。出發點是比較某個探測詞出現在兩個目標詞周圍的頻率:機率比值可以區分具有辨識力的探測詞,以及與兩者關聯相似的詞。GloVe 將這個想法轉成可實作的迴歸目標:
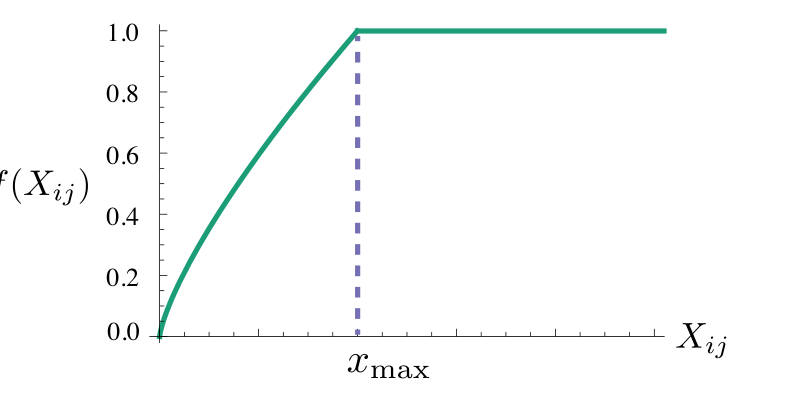
是目標詞 與上下文詞 的共現計數。向量 分別表示兩種角色; 是學得的純量偏差。 是訓練損失, 是信心權重, 是飽和門檻, 是指數。論文使用 、。只有非零項參與,因此避開零的對數未定義問題。
內積加上偏差擬合的是對數計數,不是正規化條件機率。原始計數很大也不會讓權重無限增加。圖 1 中,超過門檻後權重維持一,但迴歸目標仍隨計數改變。訓練把全語料統計與精簡向量的反覆更新結合起來,最終表示不必保留一個稠密的詞對詞矩陣。
結果
表 2 中,使用 60 億 token、300 維向量的 GloVe,總類比準確率為 71.7%;表內相同 60 億 token 設定的 Skip-gram 為 69.1%。GloVe 使用 420 億 token 時為 75.0%,但同時改變了語料與資料量。這支持該大型訓練設定的結果,不能單獨歸因於目標函數。類比準確率也不同於句子分類或理解能力。
消融與設計證據
圖 2 在相同 60 億 token 語料上改變向量維度與上下文視窗,幫助區分表示容量、上下文定義與增加資料的效果。論文也探討訓練進度與語料差異。重現時應記錄視窗是否對稱、距離如何影響共現計數,以及最佳化走訪資料的次數;這些都會改變矩陣或擬合結果。
結論
GloVe 明確連結觀察到的統計量與學到的幾何表示。可以問:某項計數加倍後,訓練項會如何改變?對數目標會變,門檻以下的權重也會變。接著讀 NLP 05,了解序列模型如何在詞輸入上加入依上下文變化的狀態。
問題與限制
單一向量仍混合不同詞義,缺少或罕見的詞也缺乏證據。建立、儲存稀疏共現計數本身有成本。語料偏差與視窗設計都會塑造向量幾何。較低迴歸損失不代表所有語言任務都更好;比較嵌入時仍須做下游評估,並讓資料與詞彙表可比。
參考文獻
- M. Hagiwara, Real-World Natural Language Processing: Practical Applications with Deep Learning, Manning, 2021; Chapters 3–4. publisher
- S. McRoy, Principles of Natural Language Processing, open textbook, 2021; Chapter 6, “Benchmark Tasks for Language Modelling.” chapter
- Y. Bengio, R. Ducharme, P. Vincent and C. Jauvin, “A neural probabilistic language model,” Journal of Machine Learning Research 3, 2003. paper
- G. A. Miller, “WordNet: a lexical database for English,” Communications of the ACM 38(11), 1995. paper
- Z. S. Harris, “Distributional structure,” Word 10(2–3), 1954. paper
- P. D. Turney and P. Pantel, “From frequency to meaning: vector space models of semantics,” Journal of Artificial Intelligence Research 37, 2010. survey
- T. Mikolov, K. Chen, G. Corrado and J. Dean, “Efficient estimation of word representations in vector space,” ICLR Workshop, 2013. paper
- T. Mikolov, I. Sutskever, K. Chen, G. Corrado and J. Dean, “Distributed representations of words and phrases and their compositionality,” Advances in Neural Information Processing Systems 26, 2013. paper
- O. Levy and Y. Goldberg, “Neural word embedding as implicit matrix factorization,” Advances in Neural Information Processing Systems 27, 2014. paper
- J. Pennington, R. Socher and C. D. Manning, “GloVe: global vectors for word representation,” EMNLP, 2014. paper
- P. Bojanowski, E. Grave, A. Joulin and T. Mikolov, “Enriching word vectors with subword information,” Transactions of the Association for Computational Linguistics 5, 2017. paper
- L. Finkelstein, E. Gabrilovich, Y. Matias, E. Rivlin, Z. Solan, G. Wolfman and E. Ruppin, “Placing search in context: the concept revisited,” ACM Transactions on Information Systems 20(1), 2002. paper
- F. Hill, R. Reichart and A. Korhonen, “SimLex-999: evaluating semantic models with (genuine) similarity estimation,” Computational Linguistics 41(4), 2015. paper
- T. Mikolov, W.-t. Yih and G. Zweig, “Linguistic regularities in continuous space word representations,” NAACL-HLT, 2013. paper
- T. Linzen, “Issues in evaluating semantic spaces using word analogies,” Workshop on Evaluating Vector-Space Representations for NLP (RepEval), 2016. paper
- T. Schnabel, I. Labutov, D. Mimno and T. Joachims, “Evaluation methods for unsupervised word embeddings,” EMNLP, 2015. paper
- T. Bolukbasi, K.-W. Chang, J. Zou, V. Saligrama and A. Kalai, “Man is to computer programmer as woman is to homemaker? Debiasing word embeddings,” Advances in Neural Information Processing Systems 29, 2016. paper
- A. Caliskan, J. J. Bryson and A. Narayanan, “Semantics derived automatically from language corpora contain human-like biases,” Science 356(6334), 2017. paper
- H. Gonen and Y. Goldberg, “Lipstick on a pig: debiasing methods cover up systematic gender biases in word embeddings but do not remove them,” NAACL-HLT, 2019. paper
- N. Reimers and I. Gurevych, “Sentence-BERT: sentence embeddings using Siamese BERT-networks,” EMNLP-IJCNLP, 2019. paper
- T. Gao, X. Yao and D. Chen, “SimCSE: simple contrastive learning of sentence embeddings,” EMNLP, 2021. paper
- M. E. Peters, M. Neumann, M. Iyyer, M. Gardner, C. Clark, K. Lee and L. Zettlemoyer, “Deep contextualized word representations,” NAACL-HLT, 2018. paper
- J. Devlin, M.-W. Chang, K. Lee and K. Toutanova, “BERT: pre-training of deep bidirectional transformers for language understanding,” NAACL-HLT, 2019. paper
- M. Apidianaki, “From word types to tokens and back: a survey of approaches to word meaning representation and interpretation,” Computational Linguistics 49(2), 2023. survey
- N. Muennighoff, N. Tazi, L. Magne and N. Reimers, “MTEB: massive text embedding benchmark,” EACL, 2023. paper