Images as Arrays
Navigate: this page and this track: Navigate: this page and this track
On this page
- What you’ll learn1 min
- The big picture1 min
- An image is a sampled, quantized signal2 min
- Shape, dtype and memory1 min
- Indexing, slicing and views2 min
- Color images and channel order2 min
- Data types and the wraparound trap2 min
- Sampling and quantization on a real image2 min
- A short checklist before you process an image1 min
- Modern view2 min
- Key takeaways1 min
- Exercises2 min
- References
Foundations
Explore this chapter 2 interactive experiments
Add the same number to every pixel of a real photo and compare 8-bit wraparound with saturating and floating-point arithmetic.
What you’ll learn
- How a grayscale or color image becomes a NumPy array, and what
shape,dtypeandstridestell you about it. - Why an image is a sampled and quantized version of a continuous scene, and what is lost when you keep fewer pixels or fewer gray levels.
- The coordinate convention (row first, then column), and how slicing, flipping, masking and flattening work, including the difference between a view and a copy.
- The three pitfalls that bite everyone: BGR versus RGB channel order,
uint8wraparound, and writing through a view by accident. - How the same array view of an image carries over to deep-learning tensors, image patches and neural image representations.
The big picture
Every method in this site, from a 3×3 blur to a vision Transformer, starts from the same object: a grid of numbers. If you can read, slice and transform that grid with confidence, the rest of the curriculum is a matter of choosing which numbers to combine and how.
Why it matters: almost every beginner bug in image code is really a bug about the array, not about the algorithm. Colors look blue because the channels were swapped. Bright areas turn black because 8-bit values wrapped around. An edit changes the original because a crop was a view, not a copy. This page names those traps once, with code you can run, so you can recognize them later.
An image is a sampled, quantized signal
Plain version. The real world has no pixels. A camera measures how much light reaches each tiny spot of its sensor, and writes the measurement down as a whole number. Two decisions turn a continuous scene into a digital image: where to measure (how many spots) and how finely to write each measurement (how many possible values).
Precise version. Let a monochrome scene be a continuous brightness function. Sampling evaluates it on a regular grid of rows and columns. Quantization rounds each sample to one of integer levels, where is the number of bits per pixel. The result is a function on a finite grid,
where is the row index (counted from the top), is the column index (counted from the left), is the pixel value, and for the common 8-bit case, so values run from 0 (black) to 255 (white). A color image adds a channel index and becomes with for the three color channels. This is the standard treatment of image formation and digitization in textbooks such as Gonzalez and Woods [1, Ch. 2] and Torralba, Isola and Freeman [2].
Written as an array, the grid has a shape (H, W) for grayscale or (H, W, 3) for color. The number of values stored is for channels, and the memory needed is that count times the bytes per value.
Shape, dtype and memory
Plain version. An array knows three things about itself: how many numbers it holds along each axis (shape), what kind of number each is (dtype), and how those numbers are laid out in memory (strides).
scikit-image ships a few small test photographs [6], [7], which keeps every example here runnable without downloading anything. The code below loads one grayscale and one color image and prints their basic properties.
Code · Python · 10 lines
import numpy as np
from skimage import data

gray = data.camera()          # grayscale test photo bundled with scikit-image
rgb = data.astronaut()        # color test photo, also bundled

for name, a in [("gray", gray), ("rgb", rgb)]:
    print(name, a.shape, a.dtype, a.ndim, a.size, a.nbytes)
print(gray.min(), gray.max())
print(gray.strides, rgb.strides)
Output:
Code · 4 lines
gray (512, 512) uint8 2 262144 262144
rgb (512, 512, 3) uint8 3 786432 786432
0 255
(512, 1) (1536, 3, 1)
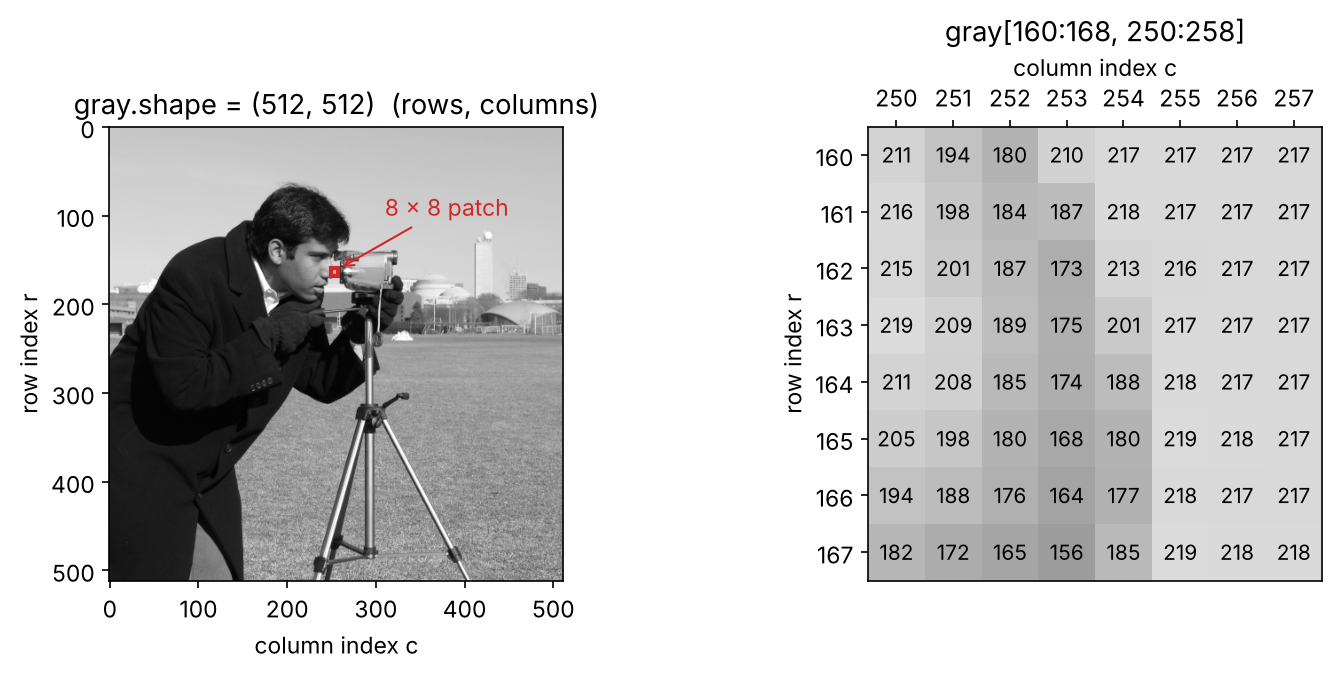
Reading the output: the grayscale image has 512 rows and 512 columns, so size is 512 × 512 = 262,144 values, and since each uint8 takes one byte, nbytes is the same number. The color image has three times as many values. The pixel range is the full 0 to 255.
strides is the number of bytes to jump to move one step along each axis. For gray, moving one column costs 1 byte and moving one row costs 512 bytes, which means NumPy stores the image row by row (C order). In rgb, the three channel values of one pixel sit next to each other in memory. This explains why scanning along a row is fast and why reshaping an image into a long vector keeps rows together, as the next section shows. The NumPy paper [3] and documentation [4] describe the array model in full.
Indexing, slicing and views
Plain version. Because an image is just an array, you pick out pixels, rectangles and whole rows with the same square-bracket syntax you use for any NumPy array. The surprise is that a rectangle taken this way is a window onto the same memory, not a separate copy.
Precise version. For an array a, the expression a[r, c] returns one pixel, a[r0:r1, c0:c1] returns the sub-block of rows and columns (the end index is excluded), and a step such as a[::2, ::2] keeps every second row and column. Basic slices are views: array objects sharing the original memory. Integer indexing that selects every axis, such as gray[r, c], returns a scalar value instead; rgb[r, c] leaves the channel axis and returns a view. Boolean or integer-array indexing returns a copy when reading, but direct indexed assignment such as a[mask] = 0 still writes into a. Calling .copy() explicitly separates a slice from its source [13].
Code · Python · 16 lines
r, c = 100, 200
print(gray[r, c])             # row first, then column
print(rgb[r, c])              # three numbers: R, G, B
patch = gray[100:108, 200:208]            # rows 100..107, columns 200..207
print(patch.shape, np.shares_memory(patch, gray))

work = gray.copy()
work[100:108, 200:208] = 0                # writing through a slice edits `work`
print(work[100:108, 200:208].max(), gray[100:108, 200:208].max())

H, W = gray.shape
vec = gray.reshape(-1)                    # flatten: row-major order
print(vec.shape, vec[r * W + c] == gray[r, c], np.shares_memory(vec, gray))
print(np.array_equal(gray[::-1], np.flipud(gray)), gray[:, ::-1].shape)
mask = gray > 200
print(mask.dtype, mask.sum())
Output:
Code · 7 lines
54
[81 57 17]
(8, 8) True
0 109
(262144,) True True
True (512, 512)
bool 55112
What each line shows:
gray[100, 200]is 54 andrgb[100, 200]is[81 57 17]: a color pixel is a short vector, one number per channel.- The 8 × 8 patch shares memory with
gray, so it is a view. Becauseworkis a copy ofgray, zeroing a patch ofworkleavesgrayuntouched (its patch still has maximum 109). If you had written to the view ofgrayitself, the original photo would have changed. - Flattening gives a vector of numbers in which pixel sits at position . This flattened form is the input vector that classical classifiers and the first layer of a fully connected network see (see ML 01A and ML 01).
- Flipping the image upside down is
gray[::-1], a view with a negative row step; no loop is needed. The comparison withnp.flipudisTrue. - A comparison such as
gray > 200yields a boolean array of the same shape, here with 55,112Trueentries. Boolean masks are how you select, count or edit pixels that satisfy a condition.
Color images and channel order
Plain version. A color image stores three numbers per pixel, one for how red, one for how green and one for how blue. The trouble is that two common conventions order these three numbers differently, and nothing in the array tells you which one you have.
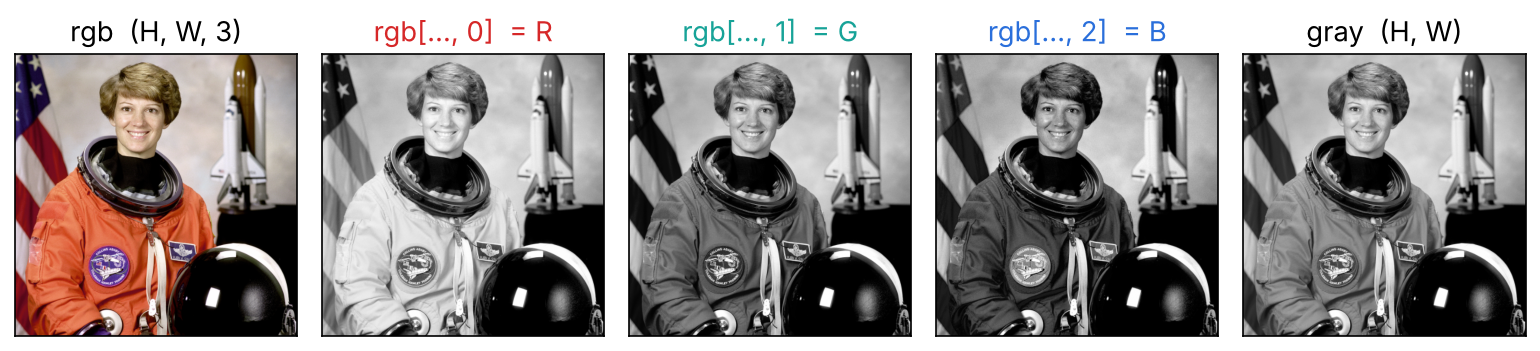
Precise version. Most Python imaging code (NumPy arrays from scikit-image [6], Matplotlib, Pillow) uses the order red, green, blue (RGB). OpenCV’s imread returns BGR: blue is channel 0 and red is channel 2. Mixing the two does not raise an error; it silently swaps red and blue, so skin looks blue and the sky looks orange. To make the effect visible without a file on disk, the code below writes the color test image to a temporary PNG, reads it back with OpenCV and compares.
Code · Python · 18 lines
import pathlib, tempfile
import cv2
from skimage import io

with tempfile.TemporaryDirectory() as d:
    path = pathlib.Path(d) / "astronaut.png"
    io.imsave(path, rgb)                   # a PNG written in R, G, B order
    bgr = cv2.imread(str(path))            # OpenCV hands the channels back as B, G, R
print(rgb[100, 200], bgr[100, 200])
print(np.array_equal(bgr[..., ::-1], rgb))
print(np.array_equal(cv2.cvtColor(bgr, cv2.COLOR_BGR2RGB), rgb))

weights = np.array([0.299, 0.587, 0.114])
manual = rgb @ weights                     # weighted sum of R, G, B -> float64 (H, W)
cv_gray = cv2.cvtColor(rgb, cv2.COLOR_RGB2GRAY)
print(cv_gray.dtype, np.abs(manual - cv_gray).max())
from skimage.color import rgb2gray
print(np.abs(rgb2gray(rgb) * 255 - cv_gray).max())
Output:
Code · 5 lines
[81 57 17] [17 57 81]
True
True
uint8 0.5010000000000332
15.529299999999992
The same pixel reads [81 57 17] as RGB and [17 57 81] as BGR. Reversing the last axis, bgr[..., ::-1], is a free way to flip the order, and cv2.cvtColor with COLOR_BGR2RGB does the same thing explicitly. Both restore the original exactly.
To turn color into gray, the standard approach is a weighted sum of the channels, because the eye is more sensitive to green than to blue. The weights come from the luma definition in the ITU-R BT.601 television standard [8, Sec. 2.5.1], and the check above shows OpenCV’s gray conversion agrees with that weighted sum to within 0.501 gray level, which is just rounding to integers. Different libraries use different weights: scikit-image’s rgb2gray differs from OpenCV’s result by up to about 15.5 gray levels on this image. So never assume that “gray” means the same numbers across libraries. Compare against the documentation of the function you call.
Data types and the wraparound trap
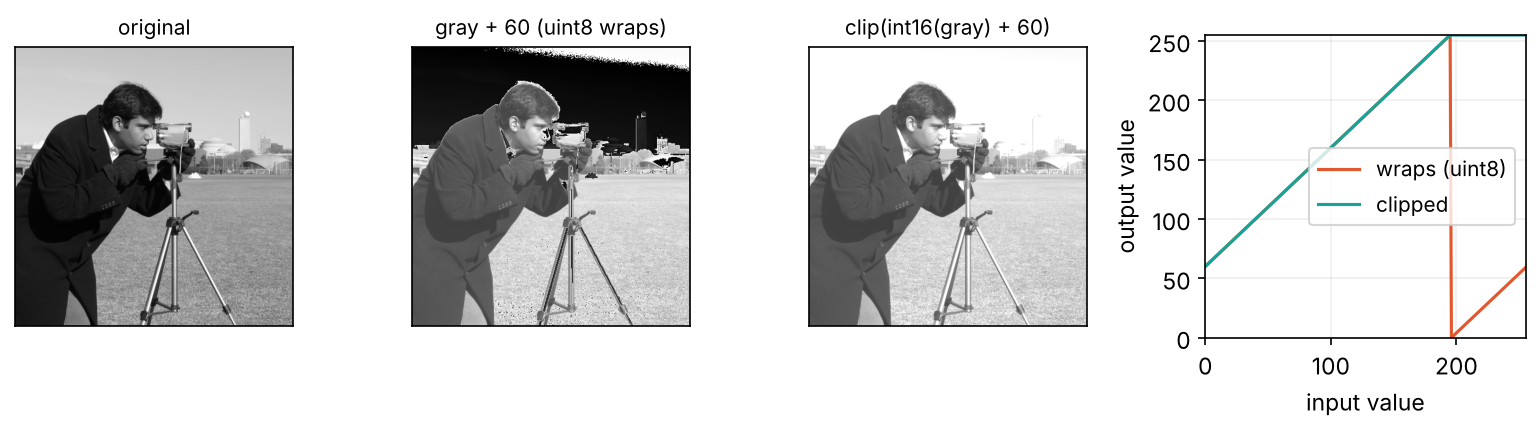
Plain version. The most common storage type for images is the 8-bit unsigned integer, which can only hold 0 to 255. If a calculation goes past 255 it does not stop at 255: it silently starts again from 0. A pixel that was almost white can become almost black.
Precise version. For an unsigned integer type uint8, arithmetic is performed modulo . So and . Because values are not saturated, brightening or subtracting images in uint8 is unsafe. NumPy 2 also refuses to combine an array with a Python integer that does not fit the array’s type: it raises an error instead of quietly widening, following NEP 50 [5]. The safe recipe has three steps: convert to a wider type (int16, float32), compute, then clip back to the valid range and convert back to uint8.
Code · Python · 18 lines
from skimage.util import img_as_float

a = np.array([250], dtype=np.uint8)
print(a + 10, a - 251, a.astype(np.int16) + 10)
try:
    a + 300
except OverflowError as e:
    print("OverflowError:", e)

wrapped = gray + np.uint8(60)
clipped = np.clip(gray.astype(np.int16) + 60, 0, 255).astype(np.uint8)
print((gray >= 196).sum(), (wrapped < gray).sum(), clipped.max())

x = gray.astype(np.float32) / 255.0
print(x.dtype, x.min(), x.max(), np.allclose(x, img_as_float(gray)))
y = np.clip(1.2 * x, 0, 1)
out = np.round(y * 255).astype(np.uint8)
print(out.dtype, out.max())
Output:
Code · 5 lines
[4] [255] [260]
OverflowError: Python integer 300 out of bounds for uint8
72087 72087 255
float32 0.0 1.0 True
uint8 255
Reading it: in uint8, 250 + 10 gives 4 and 250 - 251 gives 255, while in int16 the sum is a correct 260. Adding 60 to every pixel wraps exactly the pixels whose value is at least (since ): there are 72,087 of them, and the same 72,087 pixels come out darker than they went in. The clipped version keeps all of them at the maximum 255 instead. The last block shows the usual float workflow: divide by 255 to work in , compute, clip, multiply back and round. skimage.util.img_as_float performs the same rescaling for uint8 images.
Sampling and quantization on a real image
Plain version. Two independent knobs control how much of the scene survives: the number of pixels (spatial resolution) and the number of gray levels (brightness resolution). Turning down the first makes the picture blocky; turning down the second makes smooth shading break into flat bands.
Precise version. Keeping every -th row and column, gray[::s, ::s], reduces an image to about samples. Done without smoothing first, this can create aliasing: fine detail that the coarser grid cannot represent shows up as false patterns instead of disappearing (the formal treatment is in IP 02 and the frequency-domain chapters). Reducing the bit depth from 8 to keeps only distinct values. The helper below rounds each pixel to the center of its bin, so with 4 bits there are 16 allowed gray levels.
Code · Python · 21 lines
def quantize(img, bits):
    step = 256 // 2 ** bits
    return (img // step) * step + step // 2    # replace each bin by its center

for bits in (8, 4, 2, 1):
    print(bits, len(np.unique(quantize(gray, bits))))

small = gray[::4, ::4]                          # keep every 4th row and column
print(gray.shape, "->", small.shape, small.nbytes, gray.nbytes)

def invert_loop(img):
    out = np.empty_like(img)
    for r in range(img.shape[0]):
        for c in range(img.shape[1]):
            out[r, c] = 255 - img[r, c]
    return out

print(np.array_equal(invert_loop(gray), 255 - gray))
chw = np.transpose(rgb, (2, 0, 1))
print(rgb.shape, "->", chw.shape, np.shares_memory(chw, rgb))
print(np.mean(rgb, axis=(0, 1)))
Output:
Code · 8 lines
8 256
4 16
2 4
1 2
(512, 512) -> (128, 128) 16384 262144
True
(512, 512, 3) -> (3, 512, 512) True
[141.56249237 105.75944519  96.47507477]
The number of distinct values falls as . Keeping every 4th row and column shrinks the image from 262,144 bytes to 16,384, one sixteenth of the memory. The nested loop and the single expression 255 - gray give identical results (True), but the array expression runs as one compiled operation rather than a quarter of a million Python steps: write image code as array expressions whenever you can, and keep explicit loops for checking. Transposing to channels-first, (3, 512, 512), is another view, which is the layout most deep-learning libraries expect. The last line, a mean over both spatial axes, gives one average per color channel.
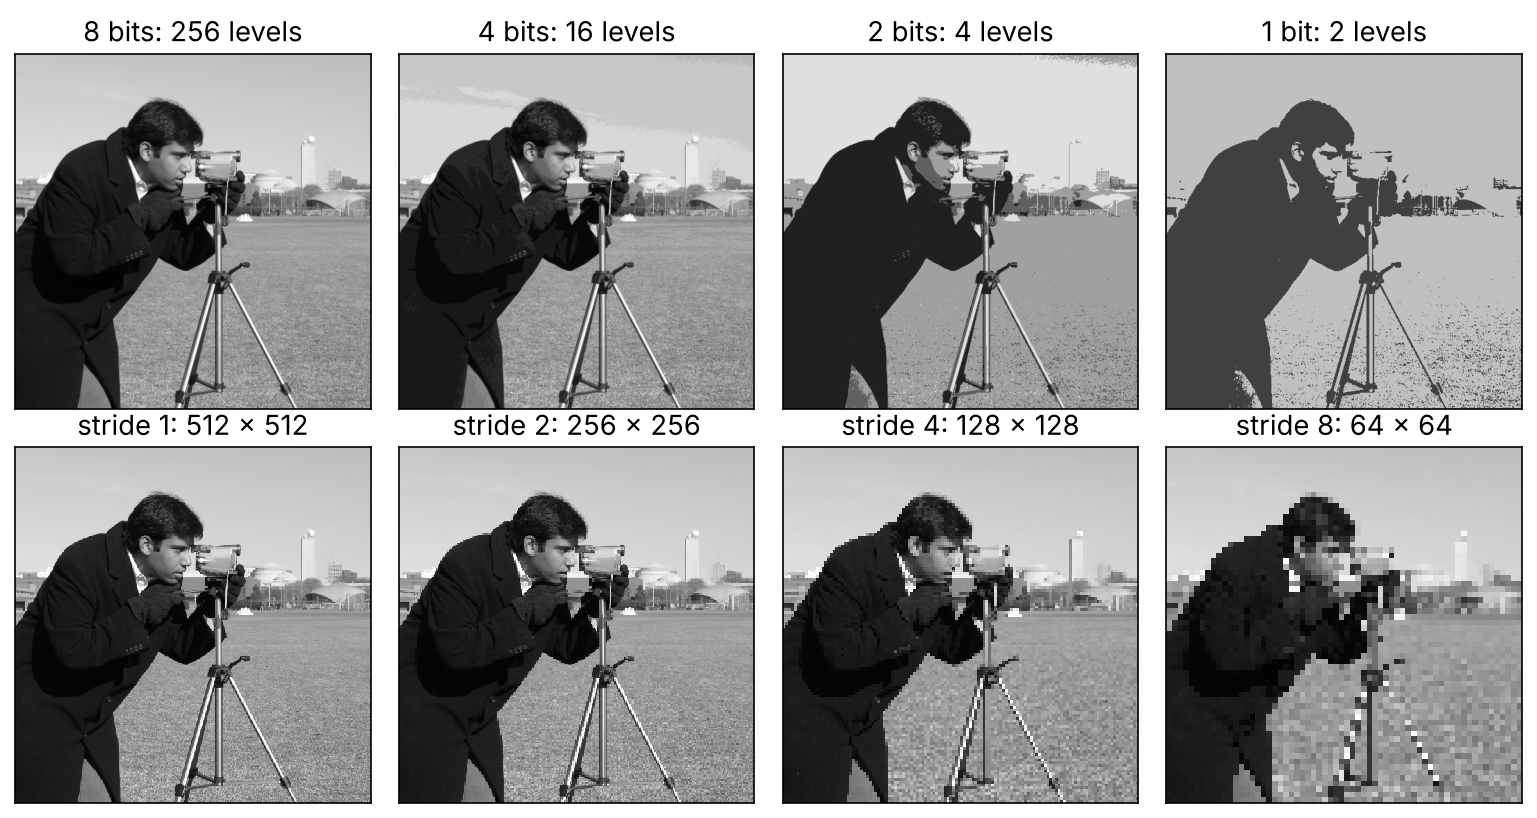
Eight bits per channel is usually enough to show an image, but not always enough to process one: stretching the contrast of a dark, banded image only magnifies the bands. That is why image formats and sensors with more bits per channel exist, and why processing pipelines convert to floating point for the arithmetic. The lab above moves both knobs on a photo and on a test pattern that exposes aliasing.
A short checklist before you process an image
| Check | Why | One line |
|---|---|---|
Print shape and dtype | Confirms grayscale versus color and the value range | print(a.shape, a.dtype, a.min(), a.max()) |
| Know the channel order | RGB and BGR look similar until the colors are wrong | rgb = bgr[..., ::-1] |
| Choose the working dtype | uint8 wraps; float32 in is safe for filtering | x = a.astype(np.float32) / 255 |
| Copy before editing | Slices are views and edits write through | b = a.copy() |
| Clip before converting back | Out-of-range floats become garbage in uint8 | np.clip(y, 0, 1) |
Remember [row, column] | Pairs from graphics APIs are (x, y) | a[y, x] |
Modern view
Nothing in this chapter is obsolete, because deep-learning frameworks treat an image as a tensor and tensors behave like NumPy arrays. What changes is the layout, the normalization and, in recent research, the idea of what an image is.
Tensors and layout. A training batch adds a leading axis, giving (N, H, W, C) or the channels-first (N, C, H, W) that many libraries expect, as in the np.transpose view above. The pixel values are usually converted to float32 and normalized, for example by dividing by 255 and standardizing each channel. All the pitfalls above carry over unchanged: a model trained on RGB input and fed BGR will silently degrade, and a preprocessing step that wraps in uint8 can poison a whole dataset without raising an error. The convolution and Transformer chapters build directly on this view: ML 03 and ML 05.
Images as sequences of patches. The Vision Transformer of Dosovitskiy et al. [10] (ICLR 2021) cuts an image into a grid of fixed-size patches, flattens each patch into a vector with the reshaping used in this chapter, and feeds the sequence to a standard Transformer. The paper reports that such a model, with large-scale pre-training, can match or exceed convolutional networks on image classification benchmarks while needing less training compute. The key point for this chapter is that the array operations (slicing into blocks, reshaping, transposing) are the model’s front end.
Images as functions. A second modern idea replaces the grid with a learned function. Sitzmann et al. [11] (NeurIPS 2020) propose sinusoidal representation networks, small networks with periodic activations that take coordinates as input and return the pixel value, and show that they can represent images, audio, video and their derivatives in detail. Essakine et al. [12] (TMLR 2025) survey this implicit neural representation field: they propose a taxonomy over four groups of methods (activation functions, position encoding, combined strategies and network-structure optimization), compare them experimentally, and conclude with open problems such as more expressive activation functions, better position encodings and scalability to high-dimensional data. The array is still how such models are trained and evaluated, since the network is fitted to sampled pixels; but resolution becomes a property of how you query the function, not of the stored table.
What is still open and what is not. Questions that remain unsettled include how to store high-dynamic-range and wide-gamut color consistently across tools, and how learned representations should be compared with plain arrays at the same storage cost. Questions that are settled, and worth drilling until they are automatic, are the ones in this chapter: shape, dtype, channel order, views versus copies, and the habit of choosing the arithmetic type before computing.
Key takeaways
- A digital image is a sampled, quantized signal stored as an array of shape
(H, W)or(H, W, C); means row , column . shape,dtypeandstridesdescribe the array. A 8-bit grayscale image holds 262,144 bytes; the color version holds three times as many.- Slicing returns views that share memory with the original. Use
.copy()before editing, and use array expressions rather than pixel loops. - Libraries disagree on channel order (OpenCV uses BGR, most others RGB) and on the weights used for gray conversion; check, do not assume.
uint8arithmetic wraps modulo 256. Convert toint16orfloat32, compute, clip, and only then convert back.- Spatial resolution and gray-level resolution are separate choices, and reducing either loses information in a different way: blockiness and aliasing versus banding.
- Deep-learning tensors, image patches and implicit neural representations are all built on the same array view of an image.
Exercises
- Channel means. Load
data.astronaut()and compute the mean of each color channel withrgb.mean(axis=(0, 1)). Which channel is largest? Then write the result for the BGR version of the same image and explain which index now holds the largest value.
Hint
For this image the means are about 141.6, 105.8 and 96.5 for R, G and B, so red is largest. In the BGR array the same numbers appear in reversed order, so the largest value is at index 2 instead of index 0.
- Flip with slicing. Using only slicing (no
np.flipand no loops), produce the upside-down, left-right mirrored and 180°-rotated versions ofgray. Check each againstnp.flipud,np.fliplrandnp.rot90(gray, 2).
Hint
Use a step of on the axis you want to reverse: gray[::-1], gray[:, ::-1], and gray[::-1, ::-1]. All three are views, so copy them if you plan to edit.
- Find the wrap. For the brightening by 60 in this page, which input gray values wrap around, and what output value does an input of 200 produce? Write a one-line check that counts the wrapped pixels without computing the wrapped image.
Hint
Inputs of or more wrap, because . An input of 200 gives . The count is (gray >= 196).sum().
- Safe difference. Two
uint8frames and should be compared with the absolute difference . Show with a pair of pixel values thatA - Bfails, and write a safe version in NumPy.
Hint
With and in uint8, A - B equals , not . A safe version is np.abs(A.astype(np.int16) - B.astype(np.int16)).astype(np.uint8).
- Design a bit-depth budget. A grayscale image is stored with 8 bits, then quantized to bits. Predict the number of distinct values and the memory needed if each pixel is packed to exactly bits, for and at . Why does the picture in Figure 4 show bands at 4 bits but not at 8?
Hint
There are values: 16 and 4. Packed storage is bytes, which is 131,072 bytes at 4 bits and 65,536 bytes at 2 bits. Bands appear where a smooth gradient crosses a boundary between two bins: at 8 bits the steps are 1 gray level, below what the eye can distinguish on most displays, while at 4 bits they are 16 levels apart.
References
-
R. C. Gonzalez and R. E. Woods, Digital Image Processing, 4th ed., Pearson, 2018 (Chapter 2, image sensing, sampling and quantization). publisher page
-
A. Torralba, P. Isola and W. T. Freeman, Foundations of Computer Vision, MIT Press, 2024 (open-access edition). book site
-
C. R. Harris et al., “Array programming with NumPy,” Nature, vol. 585, pp. 357–362, 2020. doi
-
NumPy developers, “Data types,” NumPy user guide, current documentation. docs
-
NumPy developers, “NEP 50: Promotion rules for Python scalars,” NumPy Enhancement Proposals. NEP 50
-
S. van der Walt et al., “scikit-image: image processing in Python,” PeerJ, vol. 2, e453, 2014. doi
-
scikit-image developers, “skimage.data: test images and example data,” scikit-image documentation. docs
-
ITU-R, “Recommendation BT.601-7: Studio encoding parameters of digital television for standard 4:3 and wide-screen 16:9 aspect ratios,” 2011. ITU page
-
Matplotlib developers, “matplotlib.pyplot.imshow,” Matplotlib documentation. docs
-
A. Dosovitskiy et al., “An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale,” International Conference on Learning Representations (ICLR), 2021. arXiv:2010.11929
-
V. Sitzmann, J. N. P. Martel, A. W. Bergman, D. B. Lindell and G. Wetzstein, “Implicit Neural Representations with Periodic Activation Functions,” Advances in Neural Information Processing Systems (NeurIPS), vol. 33, 2020. proceedings
-
A. Essakine et al., “Where Do We Stand with Implicit Neural Representations? A Technical and Performance Survey,” Transactions on Machine Learning Research (TMLR), 2025. arXiv:2411.03688
-
NumPy developers, “Indexing on ndarrays,” NumPy user guide, accessed 2026-11-05. documentation
Check your understanding
This tutorial has 5 exercises. Can you solve them without opening the hints?
Go to the exercises ↑This is the last tutorial in Foundations. Back to the learning map →